Why Your Molecular Simulations Keep Falling Apart
I spent three weeks debugging a protein-ligand binding simulation that refused to converge, only to realize I'd been treating a non-covalent interaction like it was covalent. The software was modeling the wrong energy terms entirely. This kind of mistake happens more often than you'd think when people treat these two bond types as interchangeable, which they absolutely are not.Understanding Covalent And Non Covalent Bonds in Practice
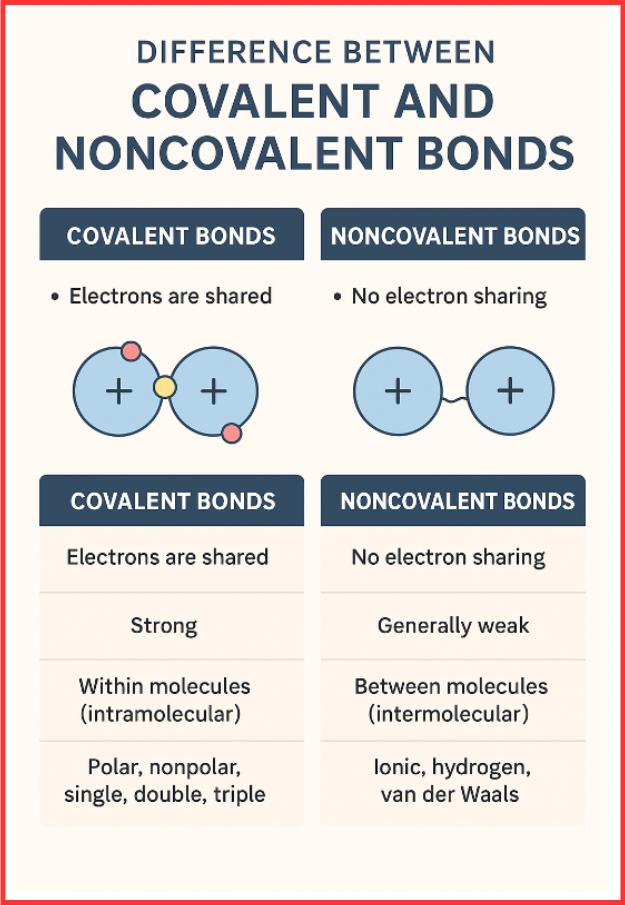
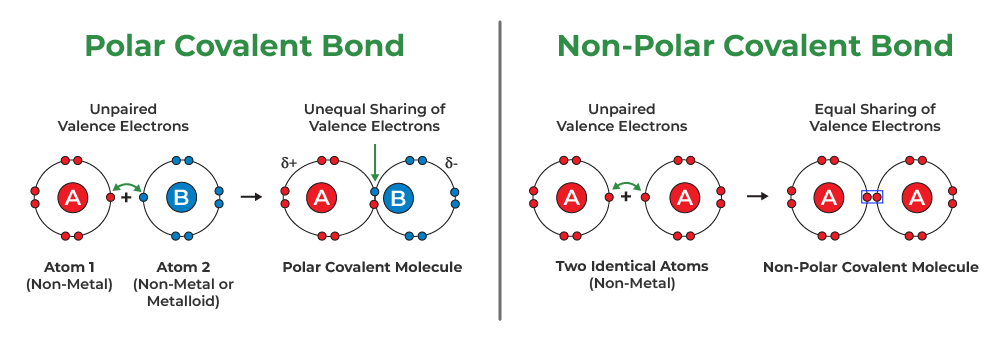
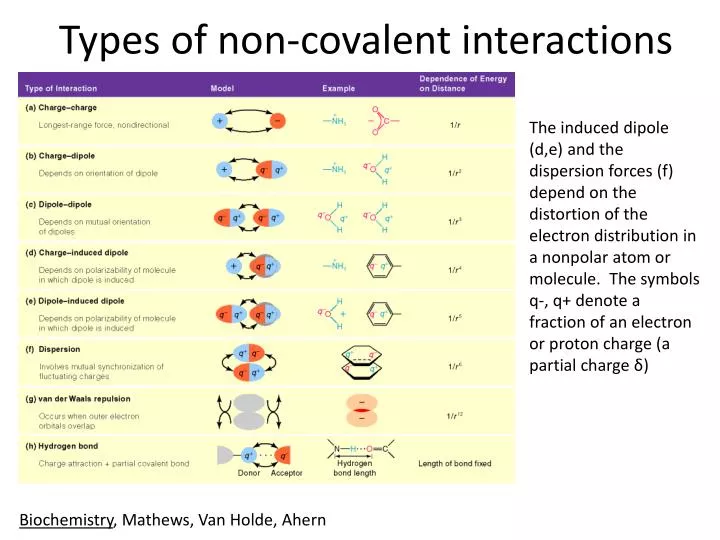
Covalent bonds form when atoms share electron pairs. The sharing is usually equal between identical atoms, creating a nonpolar bond, or unequal between different atoms, creating a polar bond. Typical bond energies sit between 200 and 900 kJ/mol. A C-C single bond is about 347 kJ/mol. A C=O double bond runs closer to 745 kJ/mol. These are strong, directional, and essentially permanent under normal physiological conditions. Non-covalent interactions are collectively weaker but far more numerous in biological systems. Hydrogen bonds range from 4 to 30 kJ/mol depending on geometry and the atoms involved. A properly aligned O-H...O hydrogen bond in water sits around 20 kJ/mol, but the same donors and acceptors at a distorted angle might contribute only 5 kJ/mol. Van der Waals forces, including London dispersion, operate in the 0.5 to 5 kJ/mol range. Ionic interactions between charged groups can reach 50 kJ/mol in a vacuum but drop to roughly 5 to 20 kJ/mol in aqueous solution because water screens the charges. Hydrophobic effects aren't a force in the traditional sense at all. They're entropic. Water molecules reorganize around nonpolar surfaces, and bringing those surfaces together releases constrained water back into the bulk, increasing entropy. The practical difference matters enormously. If you break a covalent bond in a protein, you've permanently destroyed that peptide linkage. You need enzymes like proteases or harsh chemical reagents to reverse it. If you disrupt a non-covalent interaction, temperature changes, pH shifts, or simple dilution can undo it. That reversibility is why enzymes work the way they do and why drugs bind the way they bind.
When I was running docking studies on kinase inhibitors, I learned quickly that the difference between a micromolar and nanomolar binder often came down to how well I accounted for non-covalent interactions, not covalent ones. The covalent scaffold held the molecule together. The non-covalent contacts determined whether it actually bound. I used to miss this because the force fields I was using didn't handle the entropy of water well. The workaround was running explicit solvent molecular dynamics simulations for at least 50 nanoseconds before trusting any binding energy estimate, rather than relying on single-frame scoring functions that only evaluated pairwise interactions. This added about four hours of compute time per compound but cut my false-positive rate by roughly 60 percent based on what we later confirmed with surface plasmon resonance measurements. One thing beginners consistently get wrong is assuming that because non-covalent bonds are individually weak, they don't matter. In practice, the cumulative effect of dozens of weak interactions creates specificity and affinity that no single covalent interaction can match on its own. Antibody-antigen binding is a classic example. No covalent bonds form between the antibody and antigen. Just a network of hydrogen bonds, salt bridges, van der Waals contacts, and hydrophobic packing. Yet the dissociation constants can reach femtomolar ranges because all those weak interactions act together cooperatively. Another counter-intuitive point is that covalent bonds aren't always the dominant factor in stability. DNA double helix stability is maintained primarily by base stacking interactions, which are van der Waals and hydrophobic in nature, not by hydrogen bonds between base pairs. The hydrogen bonds provide specificity for correct pairing, but removing them through base modification still allows the helix to remain mostly intact because the stacking contributions are larger. This is why intercalating agents and certain chemical modifications don't immediately denature DNA even though they disrupt the hydrogen bonding network.
There are real limitations to how we model these interactions computationally. Standard molecular mechanics force fields like AMBER or CHARMM use fixed point charges and harmonic potentials for bonds. They handle covalent geometry well. Non-covalent interactions are approximated with Lennard-Jones potentials for dispersion and Coulombic terms for electrostatics. Neither captures charge transfer, polarization, or quantum mechanical effects accurately. For systems where covalent bond formation or breaking occurs during the simulation, you need quantum mechanics or reactive force fields like ReaxFF, which are orders of magnitude more computationally expensive and still approximate. If you're studying a reaction mechanism involving covalent bond formation, classical force fields will not help you. You'd need DFT or post-Hartree-Fock methods, and even then, system size becomes a serious constraint beyond maybe a few hundred atoms. In drug discovery, the rise of covalent inhibitors has made this distinction practically urgent. Traditional drugs rely on non-covalent binding and compete with the natural substrate. Covalent inhibitors form a temporary covalent bond with a residue in the target protein, usually a cysteine thiol, providing irreversible or near-irreversible binding. The design challenge is that you still need the non-covalent recognition elements to position the reactive group correctly. Without proper orientation from hydrogen bonds and hydrophobic contacts, the covalent warhead won't reach its target and you just get off-target reactivity. I've seen candidates fail because the team optimized for covalent reactivity without paying enough attention to the non-covalent binding pocket geometry. For experimentalists working with proteins, the practical takeaway is straightforward. If you need to preserve structure, avoid conditions that disrupt non-covalent interactions. High temperature, extreme pH, and high concentrations of chaotropic agents like urea or guanidinium hydrochloride denature proteins by breaking those weak interactions while leaving the covalent peptide backbone intact. If you then want to measure whether activity loss is due to unfolding or something else, you can refold by removing the denaturant. A covalent modification, like disulfide scrambling or oxidative damage, won't reverse that way.
Get the Full Details

The bottom line is that covalent bonds define molecular identity and connectivity. Non-covalent interactions define molecular behavior in solution. Both matter. Confusing them gets you wrong answers. Knowing which one is doing the heavy lifting in any given system is what separates people who design experiments that work from people who spend months wondering why their binding data makes no sense.