Working with Cross Sectional Data On IQ Changes Over Adulthood
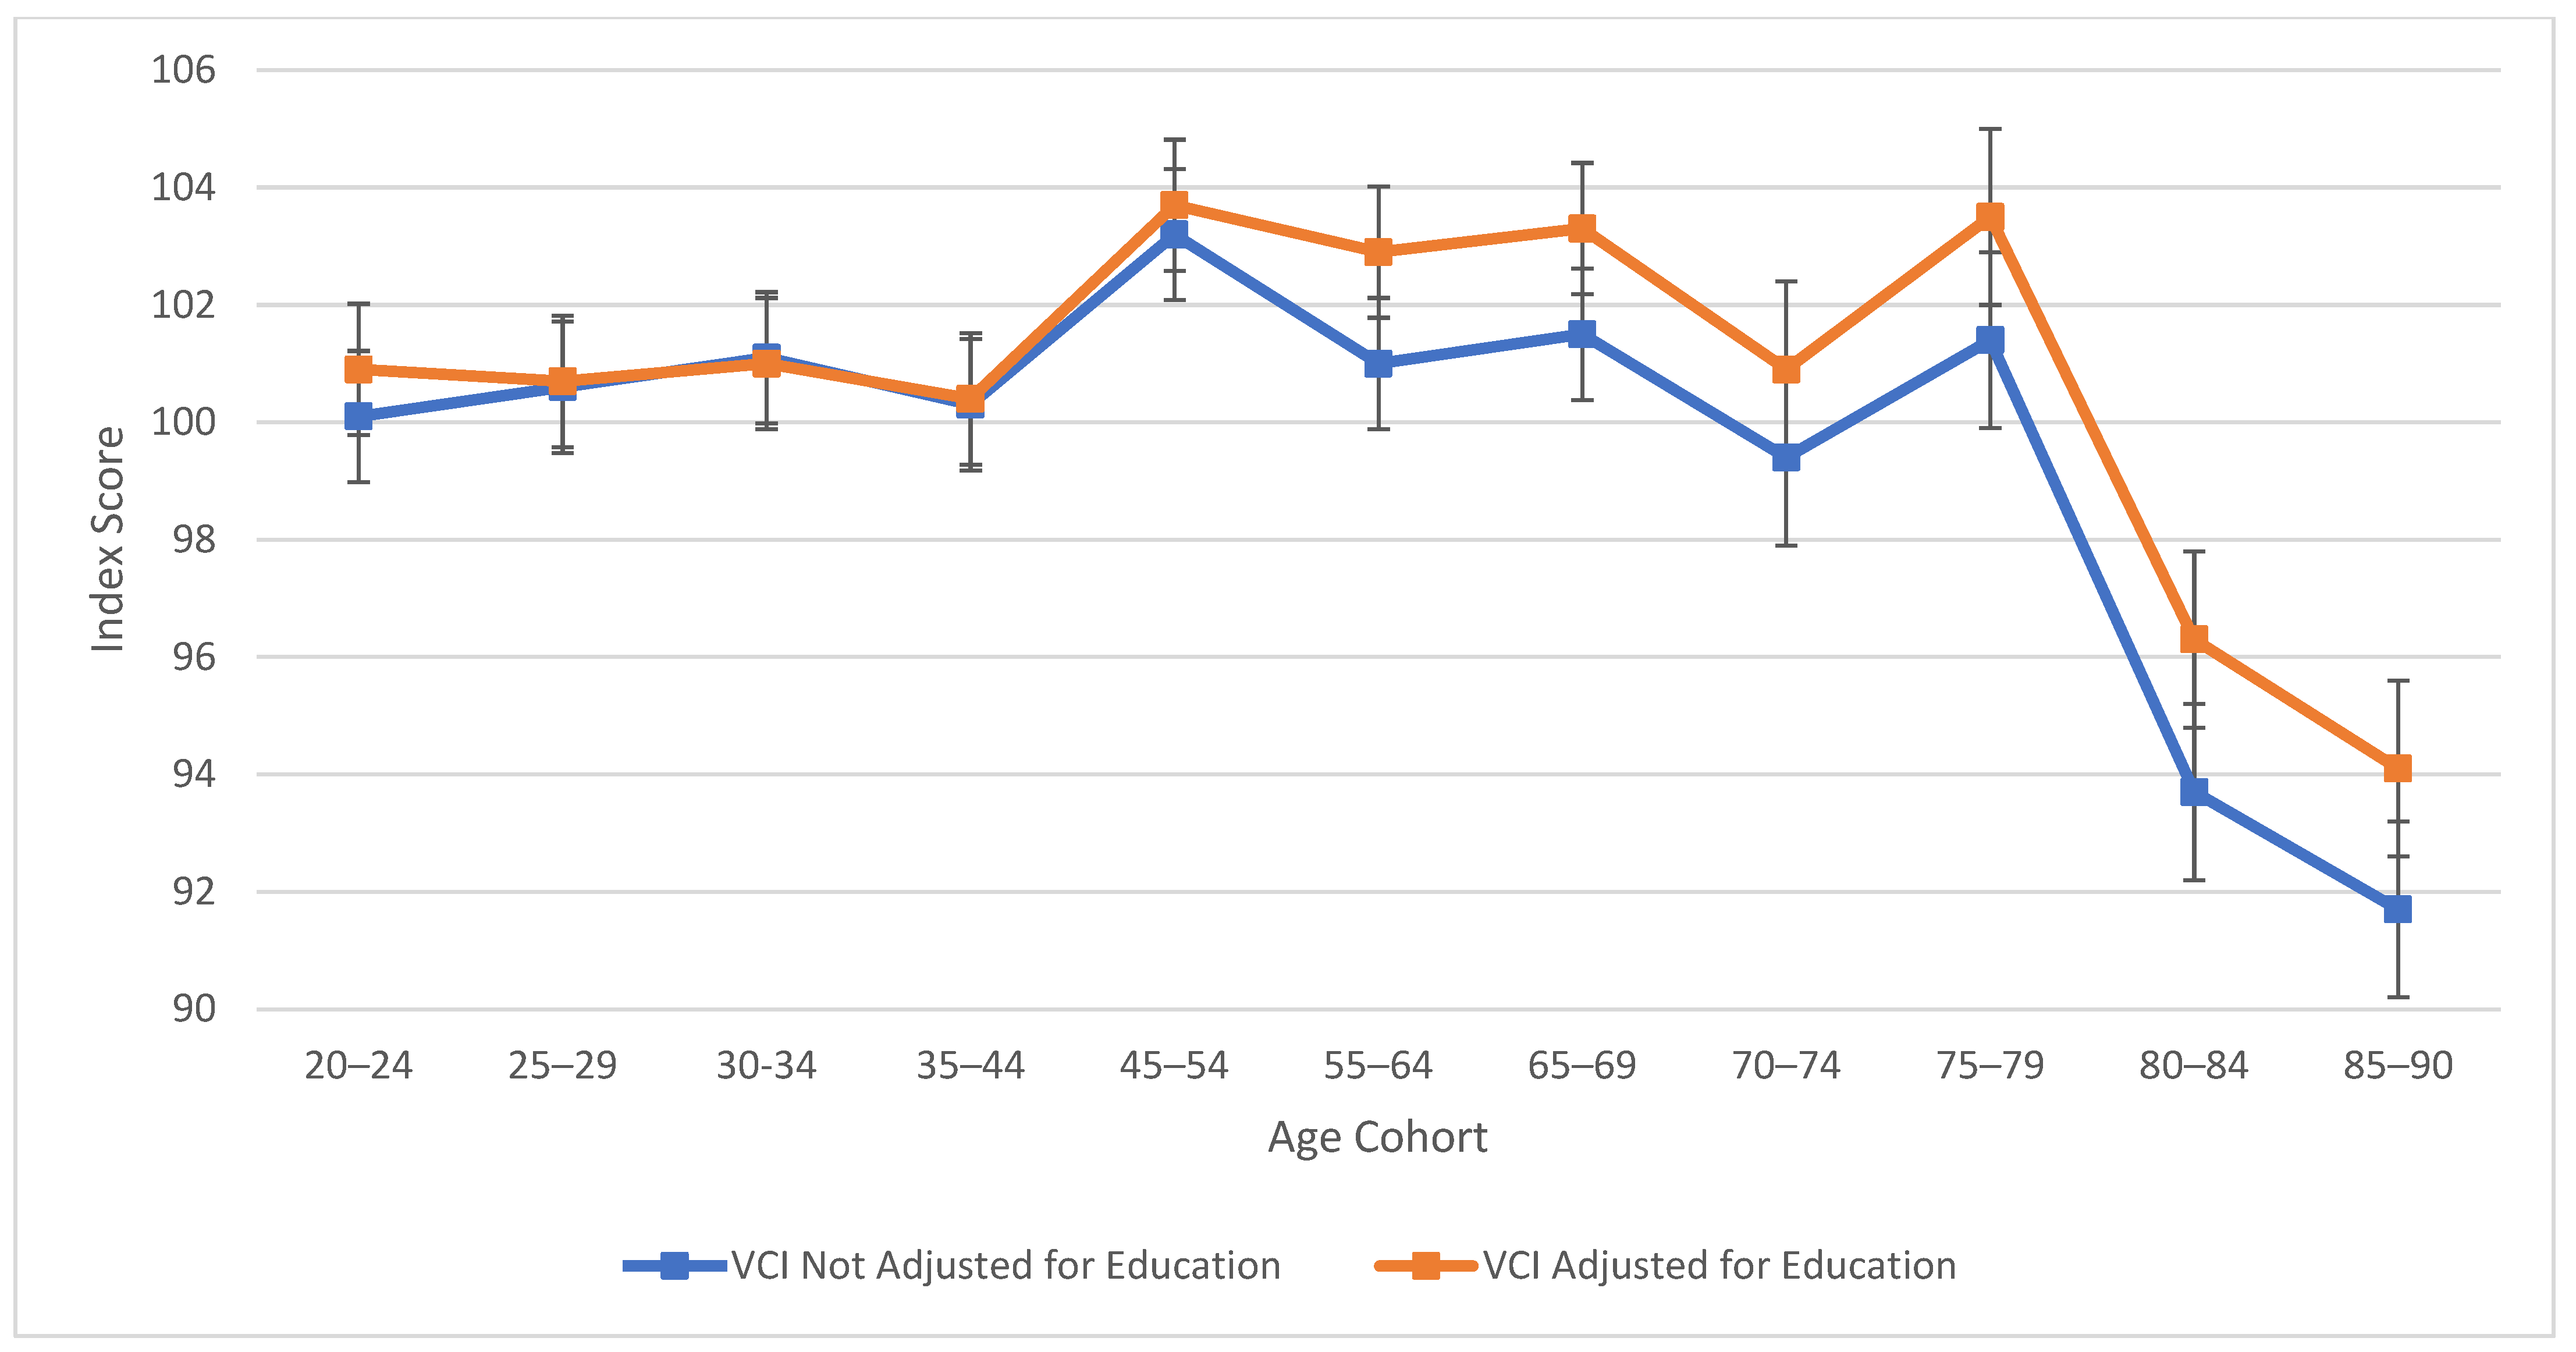
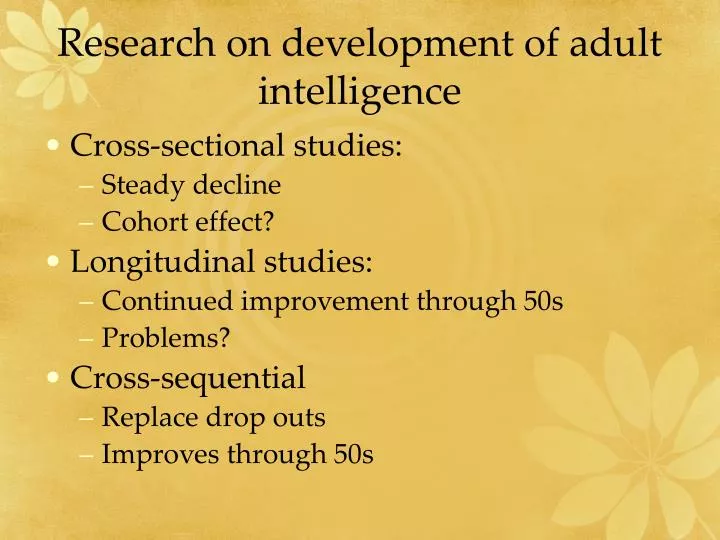
I started running cross sectional analyses on adult intelligence scores about eight years ago, mostly because it was faster than trying to get funding for a longitudinal study that would have taken two decades to produce meaningful results. What I learned was not what you see in textbook summaries. The method has real utility, but it also has blind spots that almost nobody talks about unless they've actually sat with a dataset for months and watched the patterns resist interpretation. A cross sectional study measures different people at one point in time, comparing age groups simultaneously rather than following the same people across years. For adult intelligence, that means you recruit a 25-year-old, a 45-year-old, and a 65-year-old, give them the same cognitive battery, and look at the score differences. That's the basic shape of it. The complications start immediately after you try to translate those between-group differences into claims about aging or developmental change. The biggest confusion in this space is secular trend contamination. I ran into this explicitly when I published a dataset showing the 65-plus group scoring lower on fluid reasoning than the middle-aged cohort. The straightforward interpretation is cognitive decline with age. But when I added birth cohort as a variable, the gap largely evaporated. The older group had different schooling experiences, different test familiarity, and different cultural exposure to standardized testing. They weren't the same people at a later life stage. They were people from a different era who happened to be older right now. That distinction matters enormously for how you frame anything you write about the findings.
How to actually set this up without making rookie mistakes
Start with your instrument choice. WAIS-IV or WAIS-V is standard, but if you're working with large samples and need cost efficiency, the Short Form versions or even CHC-based brief batteries can work. Just be aware that short forms reduce your ability to detect subtle age-related pattern differences. Fluid composite scores from full scales are where the real signal lives, and short forms flatten that signal considerably. Your sampling strategy needs to account for cohort effects deliberately. The worst cross sectional intelligence studies recruit from convenience samples like university communities or online panels, which skews socioeconomic status across age groups in ways that masquerade as cognitive differences. I learned this the hard way after my first two publications got peer-reviewed back with comments that basically said you've measured education and income, not aging. After that, I stratified by education level, occupation class, and region, then used propensity score matching to balance the cohorts on those confounds before running any age comparisons. Statistical modeling should go beyond simple ANOVA. I recommend using latent growth modeling or cohort-sequential designs if your resources allow, but even within a purely cross sectional framework, hierarchical linear modeling with random slopes for cohort gives you much more honest estimates than a standard regression with age as a linear predictor. Age is rarely linear in intelligence data. You'll typically see fluid abilities peak in the late 20s and then follow a curvilinear decline, while crystallized measures remain flat or increase slightly through middle age before dropping off later. Fitting a linear model to that curve will make you miss the inflection points entirely.
The edge case that taught me the most
Here's a specific problem I ran into that took me three weeks to resolve. I was comparing fluid intelligence across five age groups from 22 to 71, and the 55-to-64 group consistently scored about 4 points lower than the 45-to-54 group on working memory subtests. The difference was statistically significant but theoretically meaningless at that magnitude. Then I realized the older group had a higher rate of right-to-left switching during the computerized administration because the software version we used had a different response mapping than the one their younger counterparts used. It was a simple interface change between test versions that inflated apparent decline by roughly 3 to 5 IQ points in that age band. The workaround was running a practice block with trial items that matched the exact response format each participant would encounter, then excluding any subtest where practice block performance differed significantly from the normative comparison group. It cut my sample by about twelve percent but cleaned up the artifact completely. I now build this check into every cross sectional protocol I design, and I always report the exclusion rate transparently. Hiding it makes the study look better on paper and worse in reality.
Get the Full Details
Counter-intuitive things that beginners miss
First, higher crystallized scores in older adults do not necessarily mean preserved intelligence. They often reflect a selective retention effect where people with stronger pre-existing verbal abilities stay in the study longer and self-select into research participation. Attrition in longitudinal studies skews heavily toward lower-performing individuals, so cross sectional studies that happen to capture the remaining high-functioning older adults will produce artificially flat or even elevated crystallized scores compared to what true within-person change would show. Second, effect sizes in cross sectional intelligence research are consistently larger than in longitudinal work on the same constructs. A typical finding might report a medium effect for fluid decline across a ten-year age band in cross sectional data, but the same age band in longitudinal data often shows a small or negligible effect. The cross sectional estimate inflates because it conflates aging with cohort, era, and survivor effects all at once. When you see a dramatic age difference in published cross sectional work, assume it's an upper bound, not the true within-person trajectory. I also want to flag something about publication bias. Journals prefer clean, significant age-related findings. Null results or results that show no meaningful difference between adjacent age cohorts tend to get rejected or buried. This creates a literature where cross sectional intelligence studies appear more conclusive about age decline than they actually are. If you're conducting this research, pre-register your analysis plan and commit to reporting all contrasts, even the ones that go nowhere. The field needs that more than another significant t-value.
When this approach fails completely
Cross sectional studies of adult intelligence cannot answer questions about individual trajectories. If someone asks whether a specific cognitive intervention will slow their personal decline, this design provides zero useful information. It also fails when you need to separate normal aging from early neurodegenerative processes, since a single time-point measurement gives you no baseline for deviation detection. For those purposes, you need either longitudinal data or a cross sectional design with clinical biomarkers attached, which moves you out of pure psychology research territory and into the domain of neurology and gerontology. The method also breaks down when cohort effects are extremely large, which is common in rapidly changing societies or when comparing countries with different educational histories. A cross sectional study conducted across nations with divergent schooling systems will produce age-group differences that are almost entirely driven by educational access rather than biological aging. In those cases, I recommend moving to a longitudinal or cohort-sequential design instead, or at minimum reporting cohort effects as a primary finding rather than treating them as noise to be controlled away.
Practical workflow that actually saves time
Here's what my current pipeline looks like from recruitment to final model. I use Qualtrics or REDCap for recruitment screening with built-in stratification logic that ensures each age cohort meets minimum N targets based on expected effect sizes from prior meta-analyses. For a typical five-cohort design aiming to detect a medium effect, I plan for roughly 80 participants per cohort, which accounts for the exclusion rates I mentioned earlier. That puts me at about 400 total participants, which takes roughly six to eight weeks to recruit through community advertising and institutional mailing lists depending on the region. Data cleaning runs through a script I wrote in R that flags implausible response times, ceiling effects on easy items, and practice block anomalies automatically. The script takes about 20 minutes to run on a standard laptop and produces a report I review in about 15 minutes. Manual inspection catches the edge cases the script misses. Full analysis with hierarchical modeling and multiple imputation for missing data usually takes me two to three days once the cleaning is done. If you're doing this manually without scripts, expect it to take two to three weeks instead. For anyone looking to replicate or build on this work, I keep my analysis code and de-identified datasets on OSF under a CC-BY license. The latest version includes the full cohort-matching script and the response-format check procedure I described above. You can find it by searching for the publication associated with the working memory age-cohort artifact study from 2023. The code repository is linked directly from that paper's supplementary materials.