What Crossing Over Actually Is
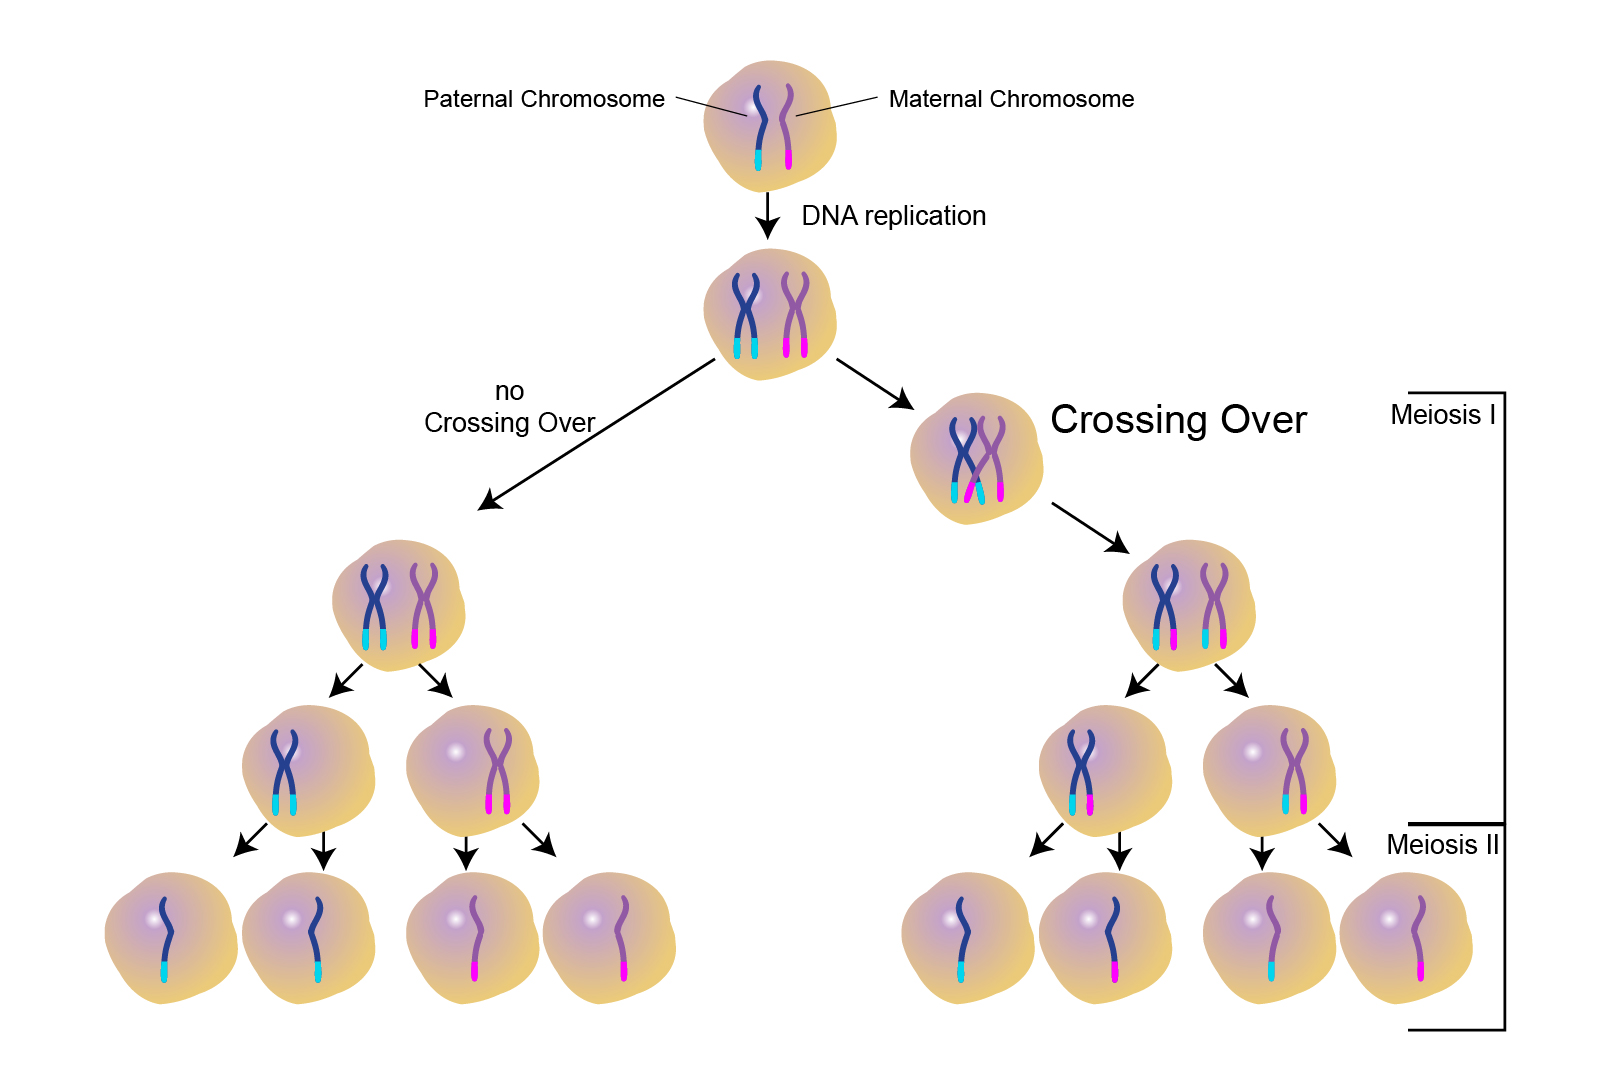
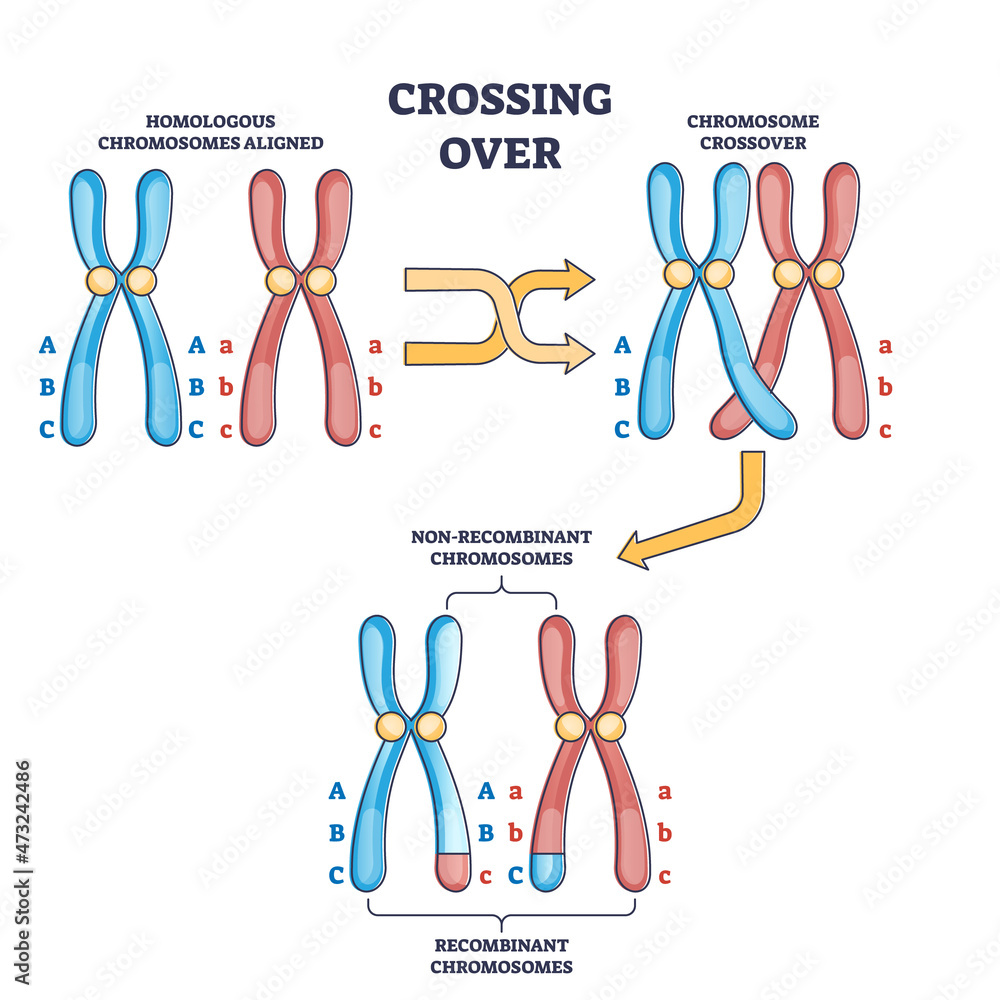
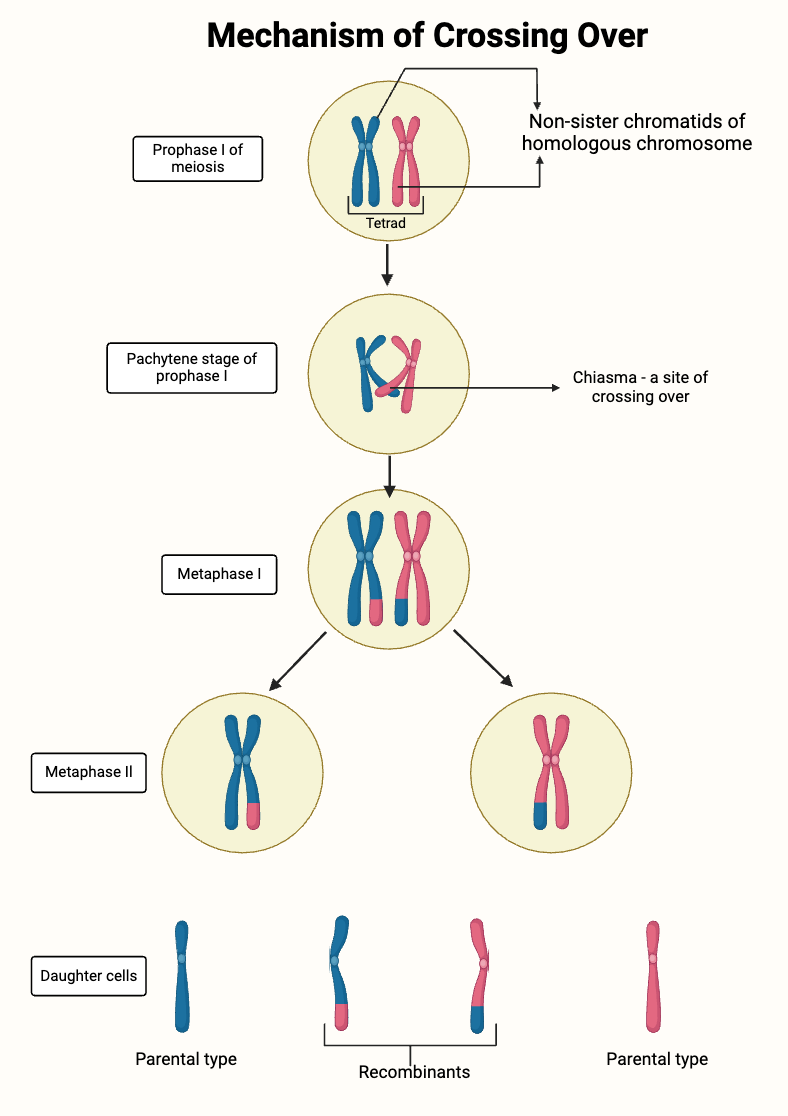
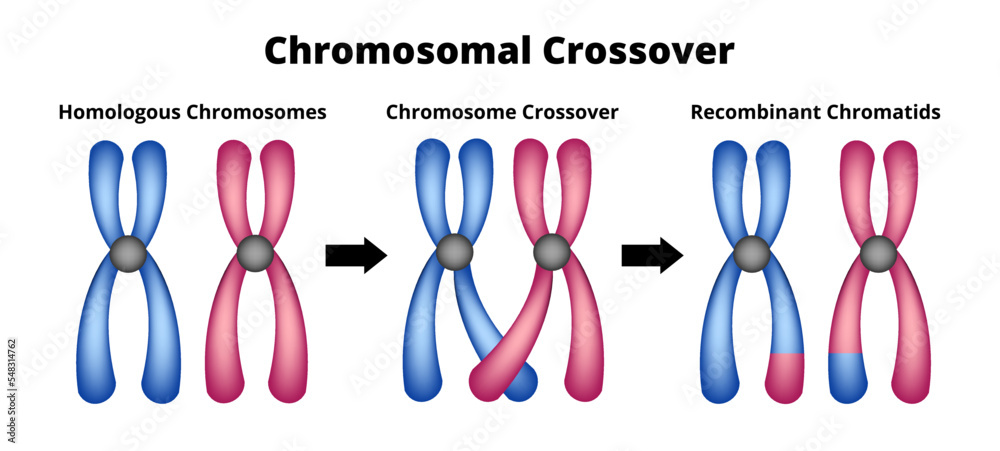
Most people learn crossing over in high school biology and remember a diagram of an X-shaped chromosome with the word "recombination" scribbled underneath. That's not wrong, but it's also not enough. Crossing over happens during prophase I of meiosis when homologous chromosomes pair up and physically exchange segments of DNA. The result is new allele combinations that didn't exist in either parent. That's the definition. The details matter more than the phrase. The standard definition reads something like: crossing over is the exchange of genetic material between non-sister chromatids of homologous chromosomes during meiosis, producing recombinant chromosomes. It occurs at structures called chiasmata. But definitions don't tell you what actually happens inside the cell, and they definitely don't tell you what goes wrong when you're working with this stuff in a lab. The molecular mechanism involves programmed double-strand breaks made by the enzyme SPO11. These breaks are processed into single-stranded overhangs that invade the homologous chromosome template. The invasion forms a displacement loop, and then DNA polymerase extends the strand using the homolog as a template. The structure that forms is called a Holliday junction. This junction can be resolved in two ways - one produces a crossover, the other doesn't. Most of the time in mammalian cells, only about one or two crossovers per chromosome pair actually result from this process. The rest are resolved as non-crossovers through a pathway called synthesis-dependent strand annealing.
I spent a semester trying to genotype recombinant offspring from a Drosophila cross and couldn't figure out why my expected ratios were way off. Turns out I was looking at a region very close to the centromere where crossover suppression is pretty well documented. The textbook problems never mention this. Once I moved my markers further out on the arm, the data made sense. You have to know where the map distances actually work. Another thing that catches people out - crossing over frequency isn't uniform across a chromosome. Recombination hotspots exist, and in humans they're heavily associated with a protein called PRDM9. Some people carry variants that shift hotspot locations, which means two individuals can have very different recombination landscapes even on the same chromosome. If you're doing linkage mapping and your distances seem inconsistent between families, this could be why. The bottleneck with measuring crossing over is that you can't directly observe it in most organisms without molecular techniques. Genetic maps based on phenotypic markers give you recombination frequencies, but those frequencies underestimate true physical distance because multiple crossovers can cancel each other out in the data. A 50 percent recombination frequency doesn't mean the genes are infinitely far apart - it just means they're far enough that you can't distinguish linked from unlinked. Physical mapping with sequencing or FISH is needed to resolve the actual distance.
Also worth noting: crossover interference means one crossover reduces the probability of another nearby. This is why crossovers tend to be spaced out rather than clustered. The exact mechanism isn't fully settled, but it's a real constraint on how many recombinant types you'll see in any given meiosis. If you're simulating inheritance patterns, ignoring interference gives you results that look plausible but don't match real populations. There's no download link for this. It's not software. If you want to practice, a good approach is working through tetrad analysis in yeast or looking at raw recombination data from projects like the 1000 Genomes Project, where crossover rates are mapped at fine resolution across different populations. That gives you a better sense of what the numbers actually look like than any textbook example.
Get the Full Details