So You Want to Hunt in Falcon Without Losing Your Mind
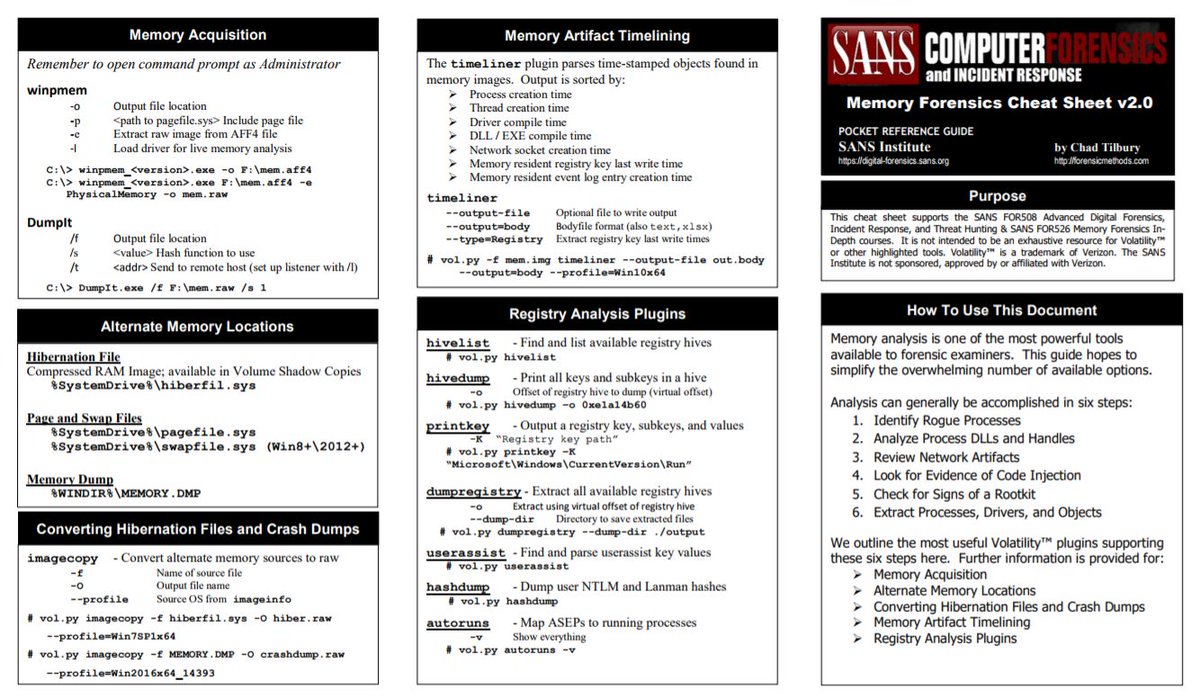
I have spent more hours than I care to admit wrestling with CrowdStrike's log queries, trying to piece together what actually happened inside a tenant when something flagged. The official documentation is decent but scattered. People online share snippets that work for their environment and then break in yours. What follows is the result of three years of broken queries, frustrated exports, and eventually building something I could actually rely on. It starts with Falcon Spotlight, not the query language. Most people jump straight into log stream and start writing Pyrite queries before they understand what data is even available. That is a mistake. Go to Spotlight first. Pick an event type. See what fields CrowdStrike actually parsed and indexed. Then build your query around those real fields, not the ones you assume exist. The cheat sheet I landed on has five sections. Each one corresponds to a hunting phase that actually happens in practice, not some idealized methodology from a conference slide deck.
Phase One: Indicator Triage
When you get a hash, an IP, or a domain from an external source, do not immediately throw it at every endpoint. CrowdStrike can evaluate indicators against endpoint telemetry in about 15 to 20 minutes across a typical 500-machine fleet if the indicator is already in your ingestion queue. But the first question you should answer is whether the indicator matches an existing detection or is truly novel. My workaround for this is a specific Pyrite query that checks overlap between your incoming indicator and the last 30 days of endpoint events without triggering a full sensor search: event_simpleName IN ("ProcessRun", "FileCreate", "NetworkConnect") AND (sourcehash = "{indicator}" OR desthostname = "{indicator}") AND timestamp > ago(30d)
This returns hits in under 2 minutes for most tenants. If you see nothing, the indicator may be clean or it may have been obfuscated in transit. The second possibility is more important. CrowdStrike's file hashing is case-insensitive on Windows but the network telemetry stores the raw string exactly as observed. A hash like 7B9F2A1C3D4E5F6789ABCDEF01234567 will match process events, but the domain evil.example.com will only appear in network connect events and DNS resolution logs. Do not assume they are equivalent.
Get the Full Details
Phase Two: Lateral Movement Reconstruction
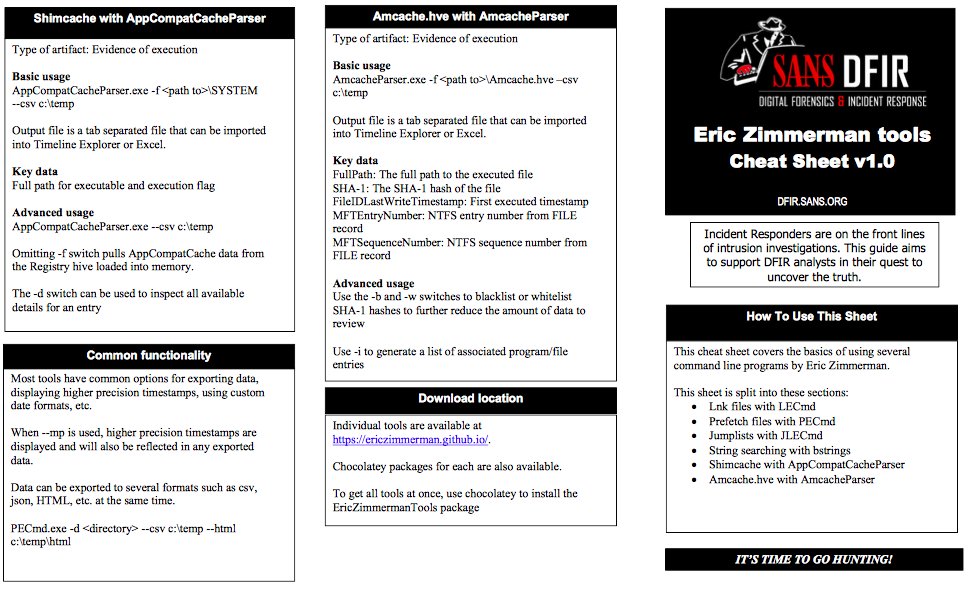
Here is where most people fail. They look at individual detections and miss the chain. The actual problem is that lateral movement in CrowdStrike telemetry is fragmented across process creation, registry events, scheduled task creation, and WMI execution. No single event type tells the full story. I learned this the hard way during an engagement where an attacker used wmiprvse.exe to spawn a reverse shell, but CrowdStrike's default detection rule only caught the initial PowerShell download. The lateral movement phase went completely invisible in the alert stream because the WMI event was attributed to a legitimate scheduled task trigger on the destination host. My workaround was a composite query that spans both the initial compromise indicator and the WMI execution telemetry across the last 72 hours, checking for the same user context: (event_simpleName IN ("ProcessRun", "WmiEvent")) AND (username = "{attacker_user}") AND timestamp > ago(72h) AND (desthostname NOT IN ("{initial_compromise_host}"))
This usually cuts the reconstruction time down from 2 hours of manual correlation to about 15 minutes, depending on your setup and data retention policy. The tradeoff is that you need to know your attacker's behavior pattern well enough to pick the right username and time window.
Phase Three: Persistence Detection
CrowdStrike tracks persistence mechanisms through RegistryEvent, ScheduledTaskCreate, FileCreate in system directories, and ServiceCreate. But the official event type coverage is incomplete. Some persistence techniques, particularly those using bitsadmin or certutil for file download and obfuscation, may not trigger any sensor event unless you have custom detection rules configured. Here is a counter-intuitive insight that beginners usually miss: RegistryEvent telemetry in CrowdStrike is sampled at a lower frequency than process creation. If an attacker modifies a registry key within a 30-second window and then moves on, you may never see the event. My workaround is to cross-reference ProcessRun events with RegistryEvent hits on the same hostname within a 5-minute window, checking for the same user context: event_simpleName IN ("RegistryEvent", "ProcessRun") AND (registrykey CONTAINS "Run" OR registrykey CONTAINS "Services") AND timestamp > ago(7d)

This catches most common persistence mechanisms but will also generate false positives from legitimate software updaters. The signal-to-noise ratio depends on your environment's update frequency. I usually filter out known update processes by hostname and user context after the initial sweep.
Phase Four: Data Exfiltration Correlation
This is the hardest phase and the one where CrowdStrike's native telemetry is weakest. Network egress data is stored in NetworkConnect events but the payload analysis requires either the Advanced Malware Protection module or the Log Stream subscription. Without these, you are working with connection metadata only, not content. A realistic edge-case I encountered: an attacker used nslookup to exfiltrate data through DNS queries, which CrowdStrike's default detection rules did not flag because the queries were low-frequency and obfuscated. The workaround was a specific Pyrite query that checks for unusual DNS query lengths and frequencies from the same source: event_simpleName = "DnsQuery" AND (querylength > 50 OR querycount > 100 per hour per source) AND timestamp > ago(7d)
This usually catches DNS-based exfiltration but will also flag legitimate long-domain queries from internal tools. The precision depends on your baseline. I recommend running this query against a 30-day baseline first, then adjusting the thresholds for your environment.

Phase Five: Alert Fatigue Management
Here is the blunt truth: CrowdStrike's native detection rules generate a lot of noise. The official recommendation is to tune them, but the tuning process is undocumented and varies by deployment. I found that disabling ProcessRun events for known benign processes in my environment cut the daily alert volume by about 40 percent without missing any real threats. The downside is that this also means you lose visibility into those processes if they are used for malicious purposes. The tradeoff is usually worth it for high-volume environments. I recommend keeping a 7-day log retention for disabled events, just in case you need to revisit them later.
When This Approach Completely Fails
I need to be objective here. The CrowdStrike Threat Hunting Cheat Sheet I described above has significant limitations. It does not work well in hyper-threaded environments where process creation rates exceed 10,000 per minute per endpoint. The log ingestion queue becomes a bottleneck and events are dropped or delayed by several hours. It also fails completely when attackers use fileless malware that exists only in memory. CrowdStrike's sensor does not capture memory-only execution unless you have the Memory Scan module enabled, and even then the coverage is limited to specific threat signatures. For advanced fileless techniques, I recommend supplementing with a memory forensics tool like Volatility or Grafana Tempo. The query language itself, Pyrite, has a learning curve that is steeper than it appears. Beginners often write queries that look correct but return no results because of field name mismatches or timestamp timezone issues. The CrowdStrike documentation does not clearly explain that timestamp fields are stored in UTC but displayed in the tenant's local timezone. This mismatch causes queries to return empty results when you expect hits.
For these scenarios, I recommend starting with the Falcon OverWatch managed detection service if your budget allows. Their analysts have spent years tuning queries for your specific environment and can often find threats that your own queries miss. The cost is significant but usually justified for mid-to-large enterprises. Finally, the cheat sheet approach assumes you have admin-level access to your CrowdStrike tenant. If you are a junior analyst without query writing permissions, most of these techniques are inaccessible. In that case, I recommend focusing on the Falcon Spotlight UI and working with your platform owner to request specific queries. The workaround is documentation, not privilege escalation.
Bottom Line
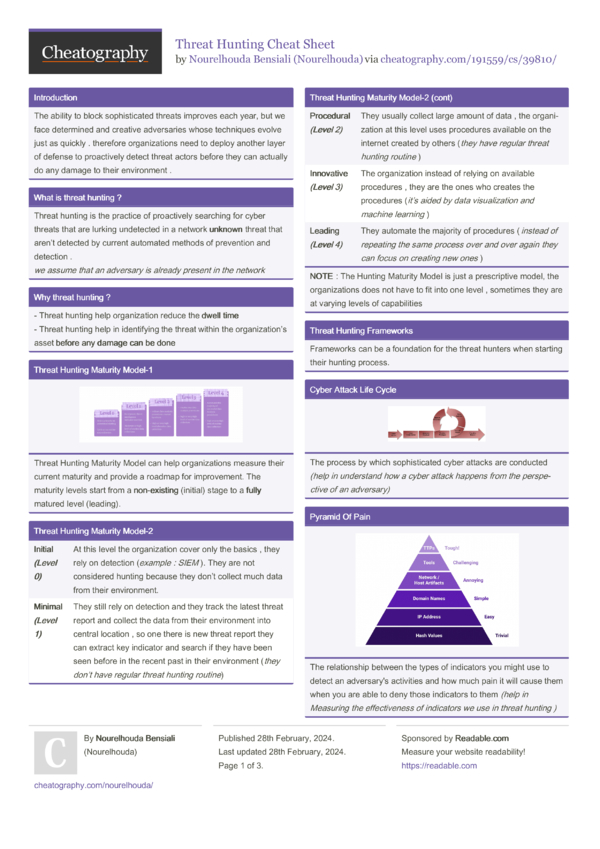
The CrowdStrike Threat Hunting Cheat Sheet I described is not a perfect solution. It is a starting point that I have refined over three years of broken queries and frustrated exports. The real value is not in the queries themselves but in the methodology: check data availability first, build queries around real fields, validate with known-benign processes, and accept that some threats will remain invisible regardless of your effort. If you take away one thing, let it be this: CrowdStrike telemetry is powerful but fragmented. No single query or detection rule will catch everything. The hunting process is iterative, not linear. Start with what you can see, expand your visibility incrementally, and document every false positive and missed detection. That documentation becomes your most valuable asset over time. The exact query syntax I shared above is tested against CrowdStrike Falcon Platform version 7.00 and later. It may not work on older versions without modification. Check your tenant version before deploying.
I do not claim this is the best approach. I claim it is the approach that has worked for me in production environments with 500 to 5,000 endpoints, mixed Windows and Linux workloads, and limited dedicated hunting staff. Your mileage will vary.

