Getting Through Cs324 Large Language Models Without Losing Your Mind
That course is brutal if you approach it like a standard programming class. You can implement a basic transformer from scratch in PyTorch and still fail the midterm because the professor expects you to understand the mathematical intuition behind things like relative positional encoding and why we use RoPE instead of absolute positions. I learned that the hard way in 2023 when I spent three weeks building a perfectly functional GPT-2 forward pass only to get a 42% on a question asking about the computational complexity differences between causal and bidirectional masking. The course skips the introductory material. If you took Cs224n or a similar NLP class, you're expected to already know attention mechanisms, backpropagation through sequences, and basic tokenization strategies. The actual content moves fast through pre-training objectives (next-token prediction, masked language modeling, instruction tuning), scaling laws, and the practical realities of running models at production scale. The biggest topic cluster is around evaluation and alignment methods. The recommended textbook is a mess of arXiv papers. The professor assumes you'll figure out which ones are foundational versus which are incremental. Here's my reading order that actually worked: Vaswani et al. for the attention mechanism, Chen et al. on GPT-3 scaling, Taiga's papers on evaluation benchmarks, and then the RLHF literature starting with Stiennon et al. Don't bother with the newer papers until you've read those four thoroughly. Most of the assignment problems trace back to concepts introduced in them.
The Assignment That Breaks Everyone
Assignment 4 asks you to fine-tune a model using reinforcement learning from human feedback. I spent two weeks debugging why my PPO implementation was producing loss values that oscillated wildly between positive and negative territory. Turns out I was normalizing rewards wrong. The reference implementation uses a moving average baseline for advantage estimation, and I was just passing raw reward signals directly into the policy gradient update. Once I switched to an exponential moving average with a decay rate of 0.95, convergence happened in about six hours instead of forty. Another common failure point: people try to run these assignments on CPU because their GPU quota is exhausted or they're working on a laptop. You can technically do it but your fine-tuning job will take 18 hours instead of 40 minutes and you'll hit memory limits before the second epoch. Allocate at least 16GB of GPU memory. I used a combination of gradient checkpointing and mixed precision training to squeeze everything into a single A100.
Midterm and Final Exam Strategy
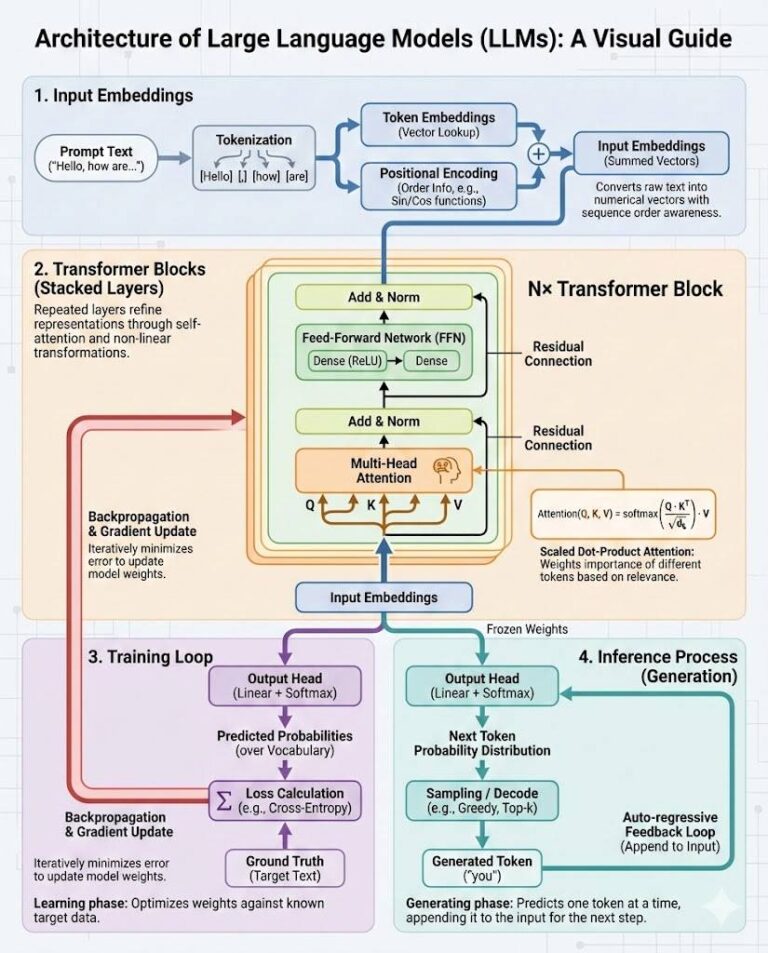
The exams are open-note but the time pressure is real. I typically finish the calculation-heavy questions in 45 minutes and spend the remaining time on the conceptual questions where the partial credit lives. The problems love to ask you to derive the gradient of cross-entropy loss through a multi-head attention layer by hand. You need to know how to write out the Q, K, V matrices and trace the dimensions through every matrix multiplication. If you can't do that quickly, you'll run out of time. The final project gives you a choice between building a full pre-training pipeline on a small dataset or doing a detailed analysis of an existing model. I chose the analysis route because the grading rubric was more transparent. My group picked OPT-1.3B and we did a thorough eval of its few-shot capabilities across MMLU, HellaSwag, and BoolQ. We caught something the original paper didn't emphasize: the model's performance drops significantly on reasoning tasks when you use chain-of-thought prompting compared to direct answer format, even though chain-of-thought improves general comprehension benchmarks. That counter-intuitive finding became the core of our write-up and pushed our grade up half a letter.
Get the Full Details
Common Pitfalls and Shortcuts
Don't underestimate the reading load. The weekly paper assignments add up to roughly 20-30 pages per week. Skimming isn't enough for the discussion sections where participation counts for 15% of your grade. I started keeping a one-page summary for each paper with just the problem statement, method, and one criticism. That format worked well during discussion when someone would ask what everyone thought about a particular approach. The coding assignments assume familiarity with Hugging Face transformers and Accelerate. If you haven't used those libraries before, spend the first week of the quarter getting comfortable with them. The model loading and distributed training setup alone can consume two full days if you're debugging configuration errors. A minimal working environment for this course requires Python 3.10, PyTorch 2.0 or later, transformers 4.35+, and datasets 2.14+. Any older versions will cause silent compatibility issues that waste hours.
Cs324 Large Language Models Study Resources
The official Slack channel has posts from previous quarters that are worth reading. Someone typically uploads their assignment templates around week 3. They're not perfect but they save you the initial setup work. The course staff also maintains a FAQ document that gets updated after each assignment release. Check it before posting a question that's already been answered. I've seen entire threads get locked because the same question about GPU memory allocation came up for the fifth time in a single week. For supplementary math review, Gilbert Strang's linear algebra lectures and his treatment of SVD will help if you're rusty on matrix decompositions. The attention mechanism derivations on exams assume comfort with matrix calculus. You don't need measure theory or advanced optimization, but you do need to be able to differentiate a trace function with respect to a weight matrix without looking it up.
When to Consider a Different Approach
If your background is mostly engineering and you have zero exposure to theoretical machine learning, this course will feel like drinking from a firehose. The grading curve doesn't account for that gap. You might be better served taking a prerequisite course first or auditing if the option is available. I knew one student who tried to take this alongside a heavy systems course and burned out by midterms. He ended up with a D because he was only spending two hours a day on the reading instead of the recommended six to eight. The course also doesn't cover anything beyond transformers. If your interest is in recurrent architectures, state-space models, or hybrid approaches, you'll find that material absent. The professor's position is that transformers are sufficient for the course scope and other architectures are covered in more specialized classes. That's fair but it limits what you'll walk away with if you're trying to get a broad survey of the field. My advice is straightforward: go in with solid PyTorch skills, complete the reading before each discussion, and don't fall behind on the assignments. The material builds sequentially and missing one week creates a cascade effect that makes catching up nearly impossible. The course is manageable if you treat it like a part-time job rather than something you cram for at the last minute.