Scoring CTOPP-2: What the manual actually says versus what happens in practice
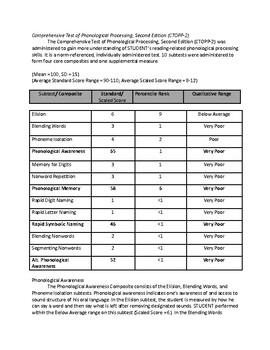
The CTOPP-2 is a phonological process assessment tool published by Pearson. It targets children's speech sound patterns, identifying whether a student is using developmental or atypical processes across a battery of subtests. The scoring manual walks you through raw score conversion, standard scores, percentiles, and confidence intervals. It's not complicated, but there are enough small traps that people who are new to it will make the same mistakes over and over again. Here is how I actually do it. You administer the subtests in the order recommended: Phonological Process Test, Real Word Identification and Production, Pseudoword Repetition, and the related optional tasks. Each subtest produces a raw score. You take that raw score and look it up on the corresponding conversion table in the manual. Those tables are age-normed in six-month bands from about 3 years through 17 years. You pull out the standard score, which sits on a scale with a mean of 100 and a standard deviation of 15. From there you get the percentile rank and the confidence interval around that standard score. One detail people routinely miss: the manual gives you scaled scores for the process indices too. Those are summed from specific item patterns within the Phonological Process Test. The scaling is already baked into the conversion tables, so you do not need to calculate anything by hand unless you are doing a clinical cross-check. If you are using the manual's tables correctly, the whole scoring run for a single child takes about 20 to 30 minutes. If you mess up the age band lookup, you could spend an hour double-checking your work.
The standard score interpretation follows the usual framework. Scores in the 85 to 115 range fall within the average band. Below 85 starts entering the low average to significantly below average territory. Above 115 moves into the high average range. The manual provides cutoff tables that map these ranges directly, and you should reference those rather than guessing from the standard score alone. Percentiles are useful for parent communication but they compress information unevenly at the extremes, so rely on standard scores and confidence intervals for clinical decisions.
A specific edge case I ran into and how I handled it
Last year I scored a referral for a five-year-old who had a standard score of 92 on the Phonological Process index but a remarkably uneven profile across the individual process categories. The composite looked solidly average, which could easily have led someone to clear the referral. But when I went back to the item-level data in the manual's response booklets, I noticed the child was omitting final consonants and clusters at a rate that pushed two separate process scores into the borderline range. The composite was averaging those out. I flagged the uneven profile and recommended targeted intervention anyway. The manual actually has a section on profile analysis in Chapter 4 that discusses this exact scenario, but it is easy to skim past that part if you are focused on getting the numbers out quickly. Another practical note: the manual does not always make clear how to handle inconsistent responding. I once had a child who performed fine on the first half of the Phonological Process Test but deteriorated significantly on the second half due to fatigue. The raw score reflected a mix of both states. I used the first half's data as a conservative estimate and noted the fatigue effect in the report. The manual's scoring guidelines do not prescribe this workaround explicitly, so you are working from clinical judgment here.
Get the Full Details

Common pitfalls and counter-intuitive details
Beginners often assume the CTOPP-2 norms are more granular than they actually are. The six-month age bands are real, but the manual's tables only print in whole-month increments for certain narrow ranges. If your child's age lands between two table entries, you interpolate. The manual tells you to round to the nearest available age entry rather than interpolate, which is a reasonable shortcut but can introduce small errors at the boundaries. I have seen standard scores shift by two points depending on how someone handles a borderline age match. Two points might seem negligible, but it can flip a borderline classification into average or vice versa. Another thing: the confidence intervals in the manual assume a certain reliability coefficient for each subtest. If a child has atypical responding patterns, like inconsistent error types across trials, the reliability estimate may not hold for that individual. The composite scores are still valid in a statistical sense, but the confidence interval around them becomes less useful. In those cases, I supplement the CTOPP-2 data with a separate articulation or phonology inventory to triangulate what is actually going on. The manual acknowledges this limitation briefly but does not push it hard enough for people who are relying on this tool as their primary assessment method.
Limitations that matter
The CTOPP-2 is not a complete speech sound assessment. It measures phonological processes, not articulatory placement or motor speech patterns. If a child's primary issue is apraxia or dysarthria, the CTOPP-2 will not capture it well and you could get a misleading composite score. I have seen cases where a child with a mild motor planning disorder scored in the average range on the phonological process index simply because their errors did not cluster into the measured process categories. The test is designed for phonological disorders, and it shows its blind spots clearly when applied outside that population. Another practical limitation: the administration time. The full battery takes roughly 45 to 60 minutes depending on the child's cooperation and attention span. For young children or children with co-occurring attention or behavioral concerns, you will likely need to split the battery across two sessions. The manual provides guidance on split administration, but scoring across sessions requires you to track which items were completed in which session and adjust the raw score accordingly. It is manageable, but it adds friction that some clinicians underestimate. If you need a broader or more detailed phonological assessment, tools like the FARSA or the Goldman-Fristoe Articulation Test can fill gaps. The CTOPP-2 works best as part of a battery rather than a standalone measure. That is true for most standardized speech-language assessments, but it is worth stating explicitly because the manual's marketing material tends to present it as a comprehensive solution.
Accessing the manual and scoring materials
The official CTOPP-2 Scoring Manual is available through Pearson's clinical resource portal. You can purchase it directly from their website or through authorized educational suppliers. Pearson also offers a digital scoring package that integrates with their online testing platform, which automates many of the raw-to-standard score conversions and generates profile reports automatically. The digital version cuts scoring time significantly, usually down to under ten minutes for a complete battery, assuming you have all the data entered correctly. The tradeoff is that you lose some of the visibility into item-level patterns unless you manually export the response data and review it yourself. If you are scoring manually with the paper manual, keep a highlighter and a separate sheet of paper for cross-referencing. The tables are dense and flipping between pages during scoring leads to errors. I set up a simple spreadsheet template that maps raw scores to standard scores based on the manual's tables. It takes about fifteen minutes to build and saves perhaps ten minutes per child afterward. The manual itself does not provide a scoring template, so you are building your own system from scratch.

Bottom line
The CTOPP-2 Scoring Manual is straightforward if you follow its procedures carefully. The main risks are age-band interpolation errors, overlooking uneven subtest profiles, and applying the tool outside its intended population. Use it alongside other measures, pay attention to item-level patterns when the composite looks deceptively average, and be honest about what the test cannot tell you. That is about all there is to it.