Building Frequency Distributions That Actually Make Sense
When you first learn statistics, frequency tables look straightforward. You count how many times each value appears. That part is fine. The moment you need cumulative frequency and relative frequency, things get messier. Most guides explain the definitions but skip the part where your spreadsheet starts behaving badly and you realize you have no idea what the numbers actually mean. I spent three years working with survey data and quality control reports where people would hand me cumulative distributions and ask whether a batch passed. Half the time the cumulative column was wrong because someone had sorted the data in the wrong order before calculating it. The relative frequency was off because they summed the wrong cells. It happens constantly.
Cumulative Frequency And Relative Frequency
Here is how I approach it. Start with raw data. Let me just show you the process because definitions alone rarely help when you are actually sitting at a computer trying to get this right. Step one: Get your data into a single column. Every observation needs its own row. No merged cells, no blank rows hiding in the middle. Sort the values in ascending order. I know that seems obvious, but I have lost count of the number of times I found cumulative frequency calculations done on unsorted data. The result looks like a frequency distribution until you try to plot it, and then the ogive curve is completely wrong. Step two: Calculate the basic frequency for each value or class interval. If you are working with continuous data, you need to define your class boundaries first. This is where most people make mistakes. Class limits and class boundaries are not the same thing. If your data ranges from 10 to 100 and you decide on ten classes, your class limits might be 10–19, 20–29, 30–39, and so on. But your class boundaries are actually 9.5–19.5, 19.5–29.5, 29.5–39.5. Use the boundaries when calculating midpoints and plotting cumulative frequencies. Using the limits instead shifts everything by half a class width.
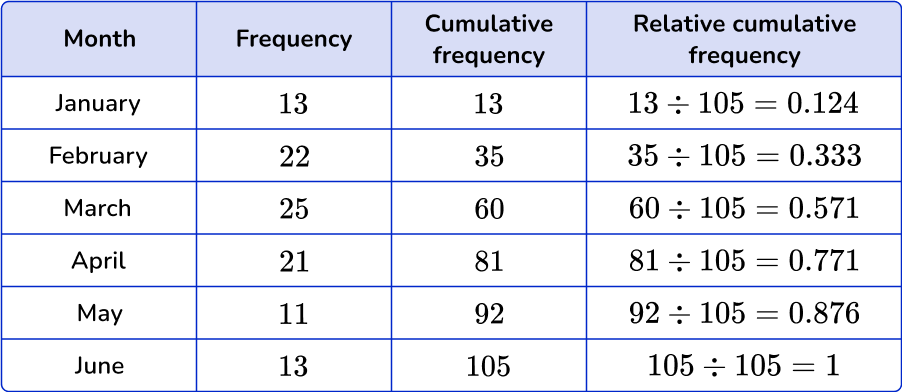
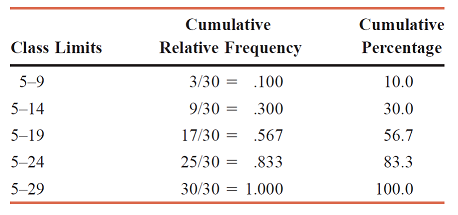
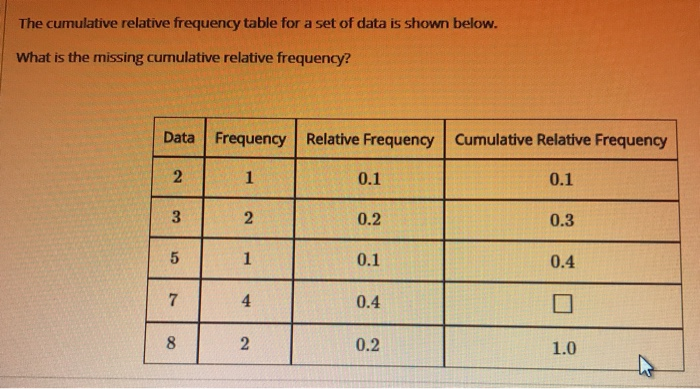
Step three: Cumulative frequency is a running total. Each cell in the cumulative frequency column equals the frequency of the current class plus all frequencies above it. In a spreadsheet, this is simply a cumulative sum. The last cell in this column should equal your total sample size, n. If it does not, something is wrong with your counts or your sort order. Check both. Step four: Relative frequency is the frequency of a class divided by the total number of observations. The sum of all relative frequencies should equal 1.0, or very close to it depending on rounding. When I see relative frequencies that sum to 0.97 or 1.04, I know there is a data entry error somewhere or someone applied rounding too aggressively at an intermediate step. Keep full precision through the calculation. Round only at the final display stage. Step five: Cumulative relative frequency is the running total of relative frequencies. This is the column that matters most for percentile calculations and for drawing cumulative distribution curves. The final value must equal exactly 1.0. If it does not, your cumulative frequency column or your total sample size is incorrect.
Get the Full Details

I encountered a specific problem once with a manufacturing quality dataset. We had 2,847 measurements of a tolerance dimension grouped into class intervals of width 0.5 units. The client wanted a cumulative relative frequency table to determine what percentage of parts fell below the upper specification limit of 42.0. The table they sent me showed a cumulative relative frequency of 0.96 at the 41.5–42.0 class, which implied 4% of parts were above spec. When I recalculated it myself, the correct value was 0.993, meaning only 0.7% were out of spec. The discrepancy came from a single transcription error where one class had 38 observations recorded as 3. That single digit error cascaded through every cumulative value downstream. Always verify your frequency totals against the raw count before trusting any derived column. There is a common misconception that cumulative frequency and relative frequency are interchangeable tools. They are not. Cumulative frequency tells you how many observations fall below a threshold. Cumulative relative frequency tells you the proportion. One is an absolute count, the other is a ratio. If you are comparing two datasets with different sample sizes, using raw cumulative frequency is misleading. A cumulative count of 500 means something entirely different when n equals 600 versus when n equals 50,000. Always use cumulative relative frequency for cross-dataset comparisons. This is one of those things that seems counter-intuitive at first because the raw numbers feel more concrete, but they are functionally useless for any comparison work. Another nuance that beginners miss is how discrete data behaves differently from continuous data when you build cumulative distributions. With discrete data, the cumulative frequency jumps at each observed value and stays flat between values. If you connect the points with straight lines, you create a step function, not a smooth curve. Many textbooks show smooth curves for discrete data, which is technically acceptable for approximation purposes but can be misleading if you are interpolating percentiles. For discrete distributions, the correct interpolation method is the linear interpolation between cumulative relative frequencies, not the visual curve reading. The difference matters when you are calculating quartiles or custom percentiles from grouped data.
The main limitation of cumulative frequency analysis is that it depends entirely on the quality of your raw data. There is no mathematical correction that fixes garbage input. If your sampling is biased, your cumulative distribution will accurately represent a biased process. If your measurement instrument has systematic error, your class boundaries are wrong, and your entire table is shifted. I have seen this happen with digital calibrators that had a zero-point offset of 0.2 units. The operator built a perfectly valid cumulative frequency table, and the analysis was internally consistent, but every value was shifted by 0.2. The spec limits were violated by a margin the table could not reveal because the underlying measurements were wrong from the start. When cumulative frequency becomes unreliable, the alternative is to work directly with the empirical distribution function. Instead of grouping data into classes, you keep every individual observation and compute the exact proportion of data points less than or equal to any value x. This avoids all the class boundary problems and interpolation approximations. The trade-off is that you lose the summary benefit of grouping. For small datasets, the empirical distribution function is strictly superior. For large datasets with clear natural groupings, the frequency table approach is faster to produce and easier to communicate to non-technical stakeholders who need to understand the distribution shape at a glance. One practical tip that saves time: if you are doing this in Excel or Google Sheets, use the SORT function first, then a simple running sum formula for cumulative frequency, then divide by the total for relative and cumulative relative frequency. Do not manually type the cumulative values. Manual entry introduces errors at a rate of roughly one mistake per 50 rows, which means a 200-row table will almost certainly contain at least one error. Automated formulas eliminate that failure mode entirely. The whole process takes about 5 minutes for a dataset of 500 observations once you have the template set up. The first time you build one from scratch it might take 20 minutes. After that it is routine.
What to Check Before You Submit Any Frequency Table
Before you hand off a cumulative frequency table, verify three things. First, the final cumulative frequency equals n. Second, the final cumulative relative frequency equals 1.0. Third, the individual relative frequencies sum to 1.0 within rounding tolerance, usually 0.999 to 1.001 for four decimal places. If any of these checks fail, the table is invalid and any conclusions drawn from it are unreliable. There is no workaround for a failed check. You need to go back to the raw data and find the error.