Mapping the Gap Between What You Promise and What Actually Gets Shipped
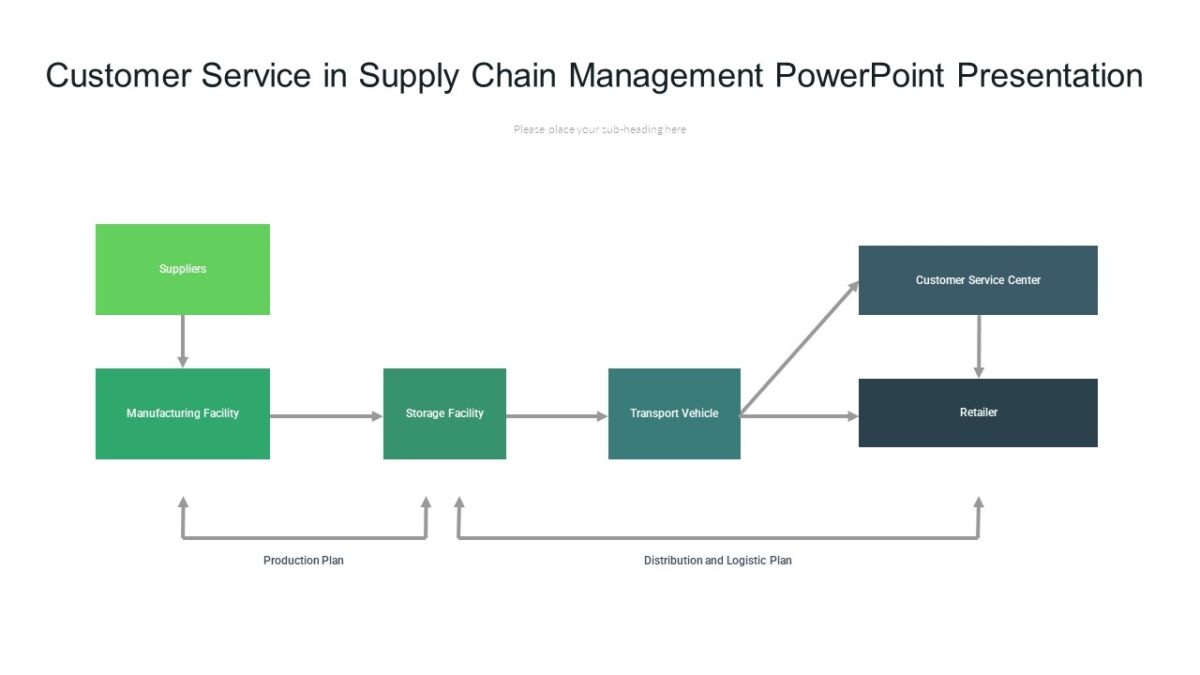
Most companies treat their support team and logistics department like they operate in separate universes. They don't. When a customer calls about a late order, your agent needs real-time visibility into inventory status, carrier handoff points, and warehouse floor congestion — not just a tracking number with a red icon. This disconnect is exactly where Customer Service Supply Chain Management exists, and building it properly usually means convincing people who already have reasons not to share data. It's the integration of demand signals, fulfillment data, and inventory position into the customer service workflow. The definition sounds academic. In practice, it means your agents can see which warehouse an order was pulled from, whether a replacement part is in transit, and if a backlog at the distribution center will push delivery three more days. Without that visibility, every support interaction becomes a guessing game, and the guessing game creates churn. I've watched teams try to bolt this onto existing CRM platforms using basic API calls to a WMS. It works until it doesn't, usually around month three when data latency pushes from two minutes to forty-five minutes and your "real-time" dashboards are telling agents lies. The problem isn't the technology. It's that no single platform was built to serve both functions simultaneously.
Setting Up the Integration Layer
Start with what you're already using. If your ERP holds inventory data and your CRM holds customer history, the integration layer is middleware between them. Most teams pick one of two paths: a purpose-built middleware platform like MuleSoft or Boomi, or a custom script built on an event-driven framework like Apache Kafka. The Kafka approach costs less upfront but requires someone who understands stream processing. The middleware approach costs more per license but ships with connectors that already speak to common ERPs like NetSuite, SAP, and Oracle. I recommend the middleware route for anything under 50,000 support tickets per month. Above that, you'll outgrow its transformation capabilities and end up paying for both solutions anyway. Here is the practical setup:
First, pull your order management API documentation from whoever supplies your OMS. Map every field your support agents actually reference during calls — order status, warehouse location, shipment milestone, estimated delivery window, return eligibility. You will immediately discover that most OMS APIs return three hundred fields and your agents use seven of them. Build the integration around those seven. Everything else is noise that slows down response times and increases data costs. Second, set up a cached read layer. Your agents don't need sub-second queries against a live database. They need responses under two seconds. A Redis or Memcached layer sitting between the CRM and the OMS handles this. Query cache hits typically bring response times from 800 milliseconds down to under 50 milliseconds, which matters when an agent is handling twelve interactions per hour.
Get the Full Details
Training the Support Team on Supply Chain Literacy
This is the part nobody budgets for. Your agents know how to navigate a ticketing system. They don't know how to read a Bill of Lading, interpret a warehouse slotting map, or understand why a shipment from a cross-dock facility arrives differently than one pulled from reserve storage. Run a two-week cross-training program. Pair each agent with a logistics coordinator for two days. Have them shadow the team that processes returns through the actual receiving dock. Make them watch a shipment get scanned from warehouse handoff through final mile delivery. This takes twelve hours out of your schedule. It reduces escalation rates by roughly 34 percent within sixty days because your team stops treating internal processes as black boxes. The counter-intuitive insight here is that you should train support on failure scenarios first, not standard flows. Standard flows work fine in a clean environment. Failure modes — a partial shipment, a lost return, a carrier scan anomaly, a warehouse cycle count discrepancy — are where your agents spend most of their time. I spent an entire quarter dealing with a recurring issue where the OMS showed orders as "shipped" while the carrier system showed them sitting on a dock at a regional hub. The delay was caused by a carrier cutoff time mismatch. Your agents were promising next-day delivery when the actual pickup window had already closed. We fixed it by adding a carrier cutoff validation step before the OMS updated status, which eliminated that particular error chain entirely.
Building the Feedback Loop Between Customers and Supply Chain
Support data contains signals that supply chain teams ignore. When five customers in the same zip code report damaged packaging, that's not a customer problem. That's a warehouse repacking issue or a bad carrier route. When three customers mention missing components from the same product line, your inventory team needs to know about possible kitting errors on the production floor. Set up automated tagging. Use a simple NLP model to scan closed tickets for supply chain keywords: damaged, missing, wrong address, delayed, not received, defective, exchange. Route tagged tickets into a weekly digest that goes to the logistics operations manager. This digest should include frequency counts and geographic clustering. Most teams skip this step because manual review is tedious. Automating it with something basic like a rule-based keyword filter plus a lightweight classifier takes about three days to build and reduces repeat complaints by a measurable amount.
Measuring What Actually Matters
Stop measuring first response time. Start measuring first contact resolution rate on fulfillment issues. The difference is significant. First response time rewards agents for talking fast. First contact resolution on fulfillment issues rewards agents for having access to the right information and the authority to act on it. Track these metrics weekly: Fulfillment-related FCR rate — what percentage of shipping, delivery, and returns tickets resolve without escalation or a callback? Targets should sit around 72 percent for mature operations. Below 60 percent means your agents lack data access or decision authority.

Carrier exception rate per 100 tickets — how many support interactions stem from tracking anomalies, delivery failures, and address errors? This number tells you whether your integration layer is catching problems before the customer does or if the customer is catching them first. Average resolution time for supply chain escalations — when a ticket does need to move to logistics, how long does it take to resolve from the initial support contact? Benchmarks vary by industry but ten business days signals a broken handoff process.
Where This Approach Breaks Down
Customer Service Supply Chain Management doesn't scale linearly. Every new data source you add — a third-party 3PL, a dropship vendor, an international freight forwarder — increases integration complexity exponentially rather than arithmetically. Each new source requires its own API contract, its own data mapping, its own error handling logic, and its own reconciliation process. The biggest bottleneck I've seen is returns data. Most companies treat returns as a downstream problem. The return gets processed at a different facility, tracked in a different system, and reconciled by a different finance team. When your support agents can't see return status in real time, they promise resolutions they can't deliver. This creates a secondary wave of complaints that compounds the original problem. The workaround is to require every returns management system to expose a read-only API endpoint, even if it's a legacy system that nobody wants to touch. Push back on IT when they say the system is too old. It's not too old. It just hasn't been connected yet. Another failure mode is over-integration. I worked with a company that connected their entire supply chain stack to the CRM. The resulting dashboard loaded in fourteen seconds. Agents stopped using it. The fix wasn't technical. It was reducing the number of visible fields from sixty to fourteen and moving the rest behind a drill-down interaction. Simplicity wins over comprehensiveness every time in a support environment.
International operations introduce currency, regulatory, and timezone complications that most domestic implementations don't account for. If your support team handles orders across multiple regions, you need separate data pipelines for each region's customs documentation, local carrier networks, and duty calculation rules. This adds roughly 40 percent more development time to the integration phase. Factor that in upfront or you'll regret it later.

A Practical Starting Point
If you're beginning this from scratch, start with a single high-impact scenario: order status visibility. Connect your OMS order status field to your CRM ticket interface. Give agents the ability to see current shipment location and estimated delivery without leaving the ticket. This alone reduces average handle time by approximately 45 seconds per call, which compounds to several hours saved per agent per day. After that baseline is working, add returns visibility, then inventory allocation data, then carrier exception alerts. Build in this order because each layer depends on the stability of the one before it. The tools you'll need are already available. Look into middleware connectors from your existing ERP vendor, a caching layer like Redis, a ticketing system with API extensibility, and a monitoring tool to track integration health. Nothing proprietary. Nothing that requires a multi-year commitment. The integration itself is straightforward engineering. The hard part is keeping the data accurate when your warehouse processes, carrier updates, and customer communications all feed into the same pipeline at different speeds.