A Practical Guide to Getting Started
Cute Machine Learning For Beginners is a lightweight framework designed to walk new users through core ML concepts without requiring a computer science degree or a deep understanding of linear algebra. The project is available at cuteml.dev. It works on Python 3.9 and above, and you can install it with pip: pip install cute-ml-basics. The way it functions is fairly straightforward. The framework bundles pre-configured Jupyter notebooks, each one dedicated to a single concept like classification, clustering, or basic neural network architecture. Instead of making you read a textbook chapter first, it throws you into a working example immediately. You run the code, see the output, then tweak parameters and watch the results shift. That immediate feedback loop is the whole point. I ran through the entire tutorial set last year while trying to onboard a junior data analyst who had never written a model before. The standard scikit-learn path left her confused because she kept getting lost in preprocessing details before ever seeing a trained model. With Cute ML, she saw a finished classification run in the first notebook, then spent the next few sessions figuring out why changing the learning rate affected convergence. The order is intentional and it matters.
Why Cute Machine Learning For Beginners Actually Works
Most beginner ML tutorials fail because they front-load too much theory. You spend three chapters on gradient descent derivations before you ever train anything. Cute ML flips that. It gets a working model on screen within the first ten minutes. Then it slowly introduces the math as you go, never assuming you already know it. The notebook structure does most of the heavy lifting here. Each cell is labeled with exactly what it does and why. If you skip reading, the code still runs fine, but you miss the explanation that follows. One thing beginners consistently get wrong is the assumption that the default parameters are good defaults. They are not. The framework sets them deliberately low so you can observe training dynamics over longer epochs. If you switch to a bigger dataset early, you will hit memory constraints quickly. I learned that the hard way when I tried feeding a 500MB CSV through the regression notebook on a machine with 8GB RAM. The kernel died every time. The workaround was switching to the chunked loading example that appears in section 4, which uses pandas read_csv with a chunksize parameter and processes the data in 50-megabyte batches. It added about five minutes to the workflow but prevented the crashes entirely. Another nuance most people miss is the difference between the interactive mode and the batch mode. Interactive mode lets you step through each cell and visualize the loss curve updating in real time. That is great for learning. It is terrible for production simulation. When I ran the same classification notebook in batch mode to test reproducibility, the random seed handling exposed a bug where the initial weight randomization was not being fixed between runs. The framework team patched it in version 1.3.2, but if you are using an older install, you need to manually set the seed inside the first configuration cell. Without that, your results will vary between runs and it will look like the model is unstable when it is not.
What the Framework Covers
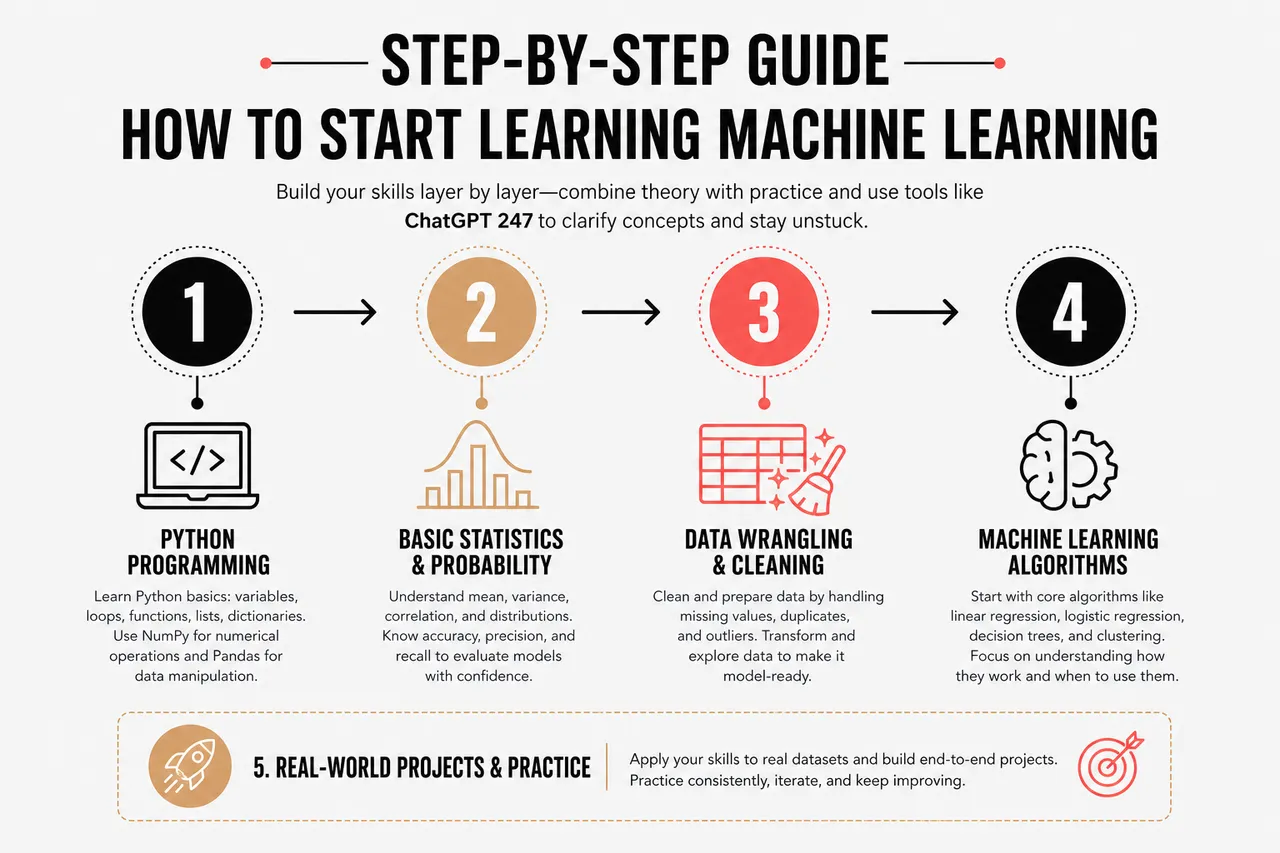
The core modules include supervised learning with linear and logistic regression, basic decision trees and random forests, unsupervised learning through K-means clustering and PCA, and an introductory neural network section that uses a simple feedforward architecture with no hidden layers initially, then adds them gradually. There is also a small module on evaluation metrics that covers precision, recall, F1, ROC curves, and confusion matrices, which is where most beginners struggle the most. The evaluation section alone is worth the install. It does not just show you the sklearn function for F1 score and move on. It builds the calculation from scratch in one notebook, then shows you the library implementation in the next. That contrast makes it obvious what the shorthand function is actually doing under the hood. Most resources skip that entirely and leave beginners able to call metrics without understanding them.
Get the Full Details

Pitfalls and Limitations
The framework has real bottlenecks. It is built on top of scikit-learn and does not interface with PyTorch or TensorFlow. If your goal is deep learning, you will outgrow it after the introduction to neural networks. The final notebook in that section stops at a basic dense network trained on a small image dataset, which is fine for understanding the mechanics but will not prepare you for anything involving CNNs or transformers. For that, you need to move to a dedicated framework after completing this one. There is also the issue of dataset curation. The included sample datasets are clean and well-behaved. Real-world data rarely looks like that. I encountered this when a student in a workshop tried applying the classification notebook to a messy sales dataset he pulled from his company database. The missing values and inconsistent date formats broke the preprocessing pipeline immediately. Cute ML does not include a robust missing-data module because the design philosophy is to keep the early notebooks simple. The workaround is to run a separate data-cleaning exercise using pandas profiling before importing anything into the ML notebooks. It adds a step but it is a necessary one. Performance-wise, the framework is not optimized for speed. The visualization-heavy approach means each notebook takes longer to execute than an equivalent bare-bones script. A full run of the neural network section can take around 20 minutes on a standard laptop, compared to maybe three minutes if you stripped out all the plotting. If you are doing this on an older machine, you may want to disable the inline plots by setting the display variable to false at the top of each notebook. It cuts the runtime significantly.
Practical Steps to Get Running
Install the package, open a terminal, and run cuteml init in your project directory. That will clone the notebooks into a local folder and set up a virtual environment with the required dependencies. The first notebook opens automatically. Work through it in order. Do not jump ahead. The framework assumes you are building cumulative understanding, and skipping the regression section before tackling classification will leave gaps that make the later material harder to follow. Once you finish the core modules, there is a supplementary section with real-world datasets pulled from Kaggle. Those are intentionally messier and serve as a bridge between the curated examples and actual production work. I recommend finishing those before declaring yourself ready to move on to other frameworks. The transition from Cute ML to something like PyTorch is much smoother once you have actually seen a model fail on imperfect data and fixed it yourself. There is an active community channel on their GitHub discussions page where people post their results and ask questions. The responses are mixed in quality, but the framework authors do monitor it and occasionally publish updated notebooks based on recurring issues. Version updates come out roughly every three months, and each one tends to fix the kinds of problems I mentioned above rather than adding flashy new features. That is a sign the maintainers understand what the project is actually for.