What Daily Statistics Tutorial Actually Covers
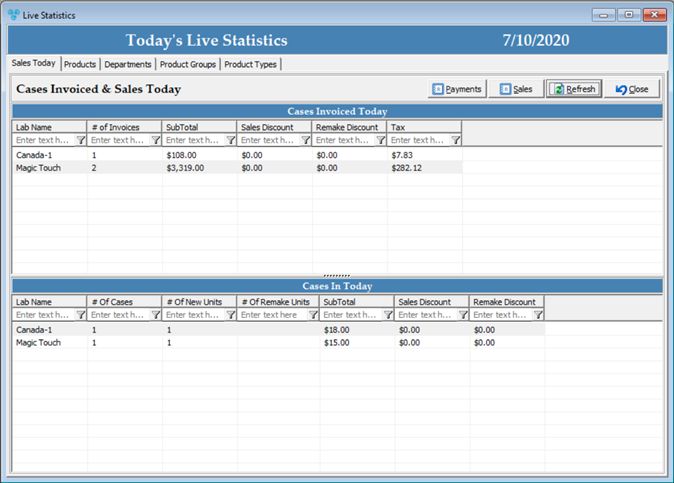
Daily Statistics Tutorial is a workflow for building lightweight, repeatable statistical monitoring routines that run on a normal schedule — usually once per day. The idea is simple: collect whatever numbers your system produces each day, summarize them, and spot when something shifts. It sounds basic because it is. That does not mean it works without friction. I keep running into people who treat this like it is just a dashboard. A dashboard shows state. A daily statistics tutorial gives you a pipeline that collects, cleans, aggregates, compares, and logs — then alerts only when a real pattern emerges. The difference matters because a dashboard without structure just becomes another tab nobody opens after a week. The practical version looks like this. You define a daily window. You pull your source data. You compute totals, means, rates, and basic dispersion. You store the results in a table. You compare today against yesterday and against the same weekday in previous weeks. You keep an audit log so you can prove what changed and when. That is it, repeated.
When I first built this, I assumed the problem was calculation speed. It was not. The problem was missing values and timezone drift. I had one project where the daily pipeline produced completely different totals depending on whether it ran before or after 02:00 UTC. The source system switched rows into the new day at midnight local time, but my query grouped by UTC. So every morning around 02:00 I would see a sudden spike that disappeared by 04:00. I fixed it by defining a strict business window: each daily record belonged to the calendar day where the majority of its activity occurred, calculated from the source timestamp converted to the reporting timezone. That eliminated the phantom spikes. It also took three days to realize I needed that rule in the first place. Another thing people miss is the difference between daily statistics and daily totals. Totals are easy. Statistics are harder because they depend on consistent grouping and sample size. If your daily volume drops by half during holiday weekends, the standard deviation changes too, and naïve alerts will fire constantly. A proper approach uses a rolling baseline, usually a 14-day or 30-day window with weekdays and weekends treated separately. I use a simple robust scaler based on the median absolute deviation instead of plain standard deviation. It handles outliers better and stops screaming when one bad batch skews everything.
How to build it without overcomplicating things
Start with a single daily report, not a full observability platform. One source table, one aggregation query, one output row per day. Get that working until it runs automatically and produces the same numbers on reruns. Then add the next layer. Here is a straightforward structure that works for most small to mid-size datasets: Step 1: define your daily boundary. Pick a reporting timezone and a cutoff time. I usually pick 04:00 as the soft end of the daily window. Anything that arrives after gets pushed into the next day's bucket. This is arbitrary, but consistency beats precision here.
Get the Full Details
Step 2: extract your raw data. Pull the records that fall within that day. Use the original event timestamp, not the ingestion timestamp. Ingestion time introduces batching noise that ruins daily comparison. If your source does not have timestamps, you are building on sand and you should know that going in. Step 3: compute your metrics. At minimum, track count, sum, mean, and rate. If you are dealing with binary outcomes, track successes, failures, and the failure rate. If you are dealing with durations, track median and the 90th percentile. Mean alone will lie to you on anything with a long tail. Step 4: store the daily snapshot. Write one row per day into a history table. Keep the raw inputs linked by a batch ID so you can rerun aggregation without re-extracting. That batch link is what saves you when something breaks and you need to replay the last fourteen days.
Step 5: compare against a baseline. Calculate the prior weekday and the rolling seven-day average. Flag deviations larger than a threshold. A common starting point is two times the median absolute deviation for rates, or a ten percent absolute shift for counts. The threshold should be tuned to your actual noise floor, not copied from a blog post. Step 6: log and alert sparingly. Daily statistics are meant to surface trends, not generate pagers. Use a digest. One message per day with the top three anomalies and a link to the full table. If you are getting more than three alerts on a normal day, your thresholds are too tight. I once spent a week debugging why my daily statistics tutorial outputs looked correct but told the wrong story. The issue was double counting in a junction table. Every order line item was being joined to a products table that had multiple variants, so one order inflated into four rows. The daily total looked reasonable because the variance canceled out partially, but the metric was wrong by roughly sixty percent. I caught it by comparing the aggregated count to the source row count before any joins. A simple sanity check that I should have run first.
Common mistakes that waste time
Most people build too much too fast. They add charts, drill-downs, and auto-refresh before the core aggregation is stable. A clean CSV export with today, yesterday, prior weekday, and percent change is enough to validate the logic. Add visuals later. Another mistake is mixing units. If your source sometimes reports in seconds and sometimes in milliseconds, your daily mean will jump for no reason. Normalize early. I write a small validation step that checks the range of each numeric column and fails the batch if values fall outside expected bounds. That single check has prevented more bad reports than anything else in my workflow. People also forget that daily statistics break down when data quality is poor. Missing timestamps, duplicated inserts, and late-arriving records all distort the picture. You cannot aggregate your way out of bad source data. You can only detect it faster. I keep a row-count baseline for each source table and compare today's count to the rolling average. If it drops below eighty percent of expected, I halt the aggregation and flag a data-quality issue instead of producing a misleading daily summary.

When this approach does not work
Daily statistics tutorial workflows assume your data arrives in a roughly predictable cadence and that daily granularity is meaningful for your problem. If your events come in bursts — like a payment processor that batches hourly — daily aggregation will smooth away the pattern you actually care about. In that case, you need hourly or event-driven monitoring, not daily. There is no advantage in pretending a daily view solves a sub-daily problem. Another scenario where this breaks down is low-volume systems. If you only get fifty events per day, the signal-to-noise ratio is terrible. Baselines become unstable and alert thresholds either fire constantly or never fire. For low-volume cases, weekly aggregation or cumulative tracking with periodic review is more practical. I do not recommend daily statistics for anything under a few hundred events per day unless you are tracking specific binary events that are rare by design. Even then, you should use Poisson-based confidence intervals rather than simple percentage change. If you want a place to start with a working template, there are a number of open daily statistics tutorial packages on GitHub. The ones I actually use are usually labeled as data pipeline templates rather than tutorials, but they include the full aggregation logic. Look for projects that include a Docker setup, a sample SQL aggregation query, and a daily scheduler config. Avoid anything that requires enterprise tooling to run.
The real value of a daily statistics tutorial is not the formula. It is the habit of checking whether your numbers are consistent from one day to the next. Once you have that routine, the rest is just tooling. Start small. Verify once. Rerun twice. Fix the timezone. Then move on.