Why Most People Get Data Analysis And Artificial Intelligence Wrong
I spent three months last year trying to build a churn prediction model for a mid-market SaaS company. The model itself was fine. It hit decent AUC scores. The problem was that by the time I got to production, nobody in the business understood why it flagged certain customers, and the dashboard that fed it data was running two days behind because the upstream ETL pipeline had quietly broken during a schema migration. The model wasn't the hard part. Getting it to matter in the real world was.
That is the thing nobody tells you about Data Analysis And Artificial Intelligence working together. People treat them as separate phases. They spend weeks or months training models, then get shocked when the analysis side collapses under messy, real-world data. Or they focus entirely on the analytics — cleaning, visualizing, reporting — and assume a well-labeled dataset will magically become useful once they switch on the AI layer. Neither assumption holds up.
What Data Analysis And Artificial Intelligence Actually Look Like Together
Data analysis is the discipline of turning raw information into something you can reason about. Cleaning, transforming, aggregating, visualizing, testing hypotheses — that is the bulk of it. Artificial intelligence, specifically machine learning, is the part where you let a statistical model make predictions or find patterns without being explicitly programmed for each one. When you combine them, the analysis feeds the model, and the model feeds back into the analysis as new signals to interpret.
The cycle is not linear. It loops. Your initial exploratory analysis shapes feature selection. The model's output reveals gaps in your data that your original analysis missed. You go back. You clean more. You retrain. You end up spending roughly 70 to 80 percent of your total project time on the data work, not the modeling work. That is a consistent ratio across pretty much every type of project I have run.
Start with the data audit before you touch anything else. I know that sounds obvious, but it is the step most people skip or rush. A data audit means understanding source reliability, recording field types and their actual ranges, checking for null patterns, and documenting how often the data refreshes. I keep a simple spreadsheet for this. Source name, table or API endpoint, refresh cadence, known issues, column descriptions, and the person or team responsible. When an ML pipeline fails at 11 PM on a Thursday, you do not want to be reverse-engineering where the data came from.
The Practical Workflow That Actually Works
Here is the sequence I use now, after abandoning the fancy end-to-end pipelines that fell apart under real conditions.
First, define the question. Not the model. The question. What decision are you trying to inform? Churn prediction is not a question. A question is whether we can identify at-risk accounts thirty days before renewal so the success team can intervene. That changes the entire approach. The target variable, the time window, the acceptable false positive rate, the downstream action — all of that comes from the question.
Second, pull the raw data directly from the source, not from some pre-cleaned CSV someone sent you three months ago. The version you were given may already have biases baked in. A senior analyst filtered out incomplete records. A product manager renamed fields. Your model will learn those choices as if they were objective truth.
Third, perform exploratory data analysis before any transformation. Look at distributions. Check correlations. Find outliers. Plot time series. This phase usually takes longer than people expect. For a typical dataset with a few dozen features, I spend anywhere from a day to a week here depending on complexity. The insight you get in this stage — say, a feature that looks predictive but is actually leaking future information — will save you from building a model that works in training and fails immediately in production.
Fourth, engineer features with domain logic, not just statistical correlation. Correlation does not equal causation, but in practice it gets you started. The trick is knowing when to trust it. If a feature correlates with your target but makes no intuitive sense, it is either a proxy for something real or a data artifact. Verify both possibilities before including it.
Fifth, train multiple baseline models before reaching for anything complex. A logistic regression, a random forest, a gradient boosting machine, maybe a simple neural network. Compare them on the same validation set. You will often find that the gradient boosting model is only 2 percent better than logistic regression, and that logistic regression is far easier to explain to stakeholders who need to act on the results.
Sixth, validate properly. Hold out a test set that the model has never seen. Use k-fold cross-validation if your dataset is small. Check for data leakage — the most common failure mode I see. I had a case where a timestamp column accidentally ended up in the feature set, and the model learned to predict based on time proximity rather than actual customer behavior. It scored nearly perfect on validation. It failed completely in production. That took me four days to trace.
Seventh, deploy as a pipeline, not a notebook. Jupyter notebooks are for exploration. Production models live in scripts, scheduled jobs, or orchestrated workflows. I use Airflow for orchestration now. It is not glamorous, but it handles retries, dependencies, and monitoring in a way that none of the fancy auto-ML platforms do reliably.
When Data Analysis And Artificial Intelligence Meet Their Limits
No system works everywhere. There are scenarios where throwing AI at a problem is actively worse than doing the analysis by hand.
Small datasets, under a few thousand rows with fewer than ten features, rarely justify a machine learning approach. A well-done statistical analysis or even a rules-based system will outperform a black-box model, and it will be interpretable. Rule-based systems are not sexy, but they are honest. If you can write the logic in ten lines of Python, do not train a neural network.
Low-quality data that cannot be fixed is another hard stop. If thirty percent of your records have missing critical fields and you cannot recover them, no amount of sophisticated modeling will compensate. The Garbage In, Garbage Out principle is not a cliché. It is a physical law of this work. I once inherited a dataset where the customer ID field was inconsistently formatted across three different source systems. Merging them took two weeks. The model itself took three days. I still recommend against touching projects like that unless you have the time.
Real-time inference requirements also expose the weakness of many ML approaches. Batch scoring every night works fine. But if your use case demands sub-second predictions on every user action, you need infrastructure that most teams do not have. The model becomes irrelevant if it cannot reach the user fast enough. In those cases, simpler heuristic systems or pre-computed lookups often serve better.
Tools I Actually Use Day to Day
Python is the default. Pandas for data manipulation, Scikit-learn for most traditional ML tasks, XGBoost or LightGBM for tabular data where you need the extra performance, and Matplotlib or Seaborn for quick visualization. For anything larger than a few hundred megabytes, I switch to Polars or DuckDB instead of Pandas. The speed difference is noticeable, sometimes dramatic.
For the orchestration piece, Airflow is my standard. Dagster is a reasonable alternative if you prefer a more modern interface, though it has a steeper initial learning curve. For lightweight scheduling, simple cron jobs or GitHub Actions work fine if your pipeline is not complex.
Cloud platforms offer managed ML services — SageMaker, Vertex AI, Azure ML — and they are not useless. They save you from infrastructure headaches if your team is small. But they introduce vendor lock-in, and the cost curve gets steep fast once you move past prototyping. I use them for short-lived projects and build custom pipelines for anything that needs to stay in production for more than six months.
For database work, PostgreSQL handles the majority of my needs. ClickHouse for analytical queries over large historical data. MongoDB when the schema is truly unstructured, which is rarer than people think.
If you want to download something and start, the Anaconda distribution of Python is the most straightforward entry point. It bundles NumPy, Pandas, Scikit-learn, Matplotlib, and Jupyter. A single installer covers most of what you need for the first few months of work.
The Mistakes That Will Waste Your Time
Ignoring class imbalance is probably the most common error I see. When you are predicting churn and only five percent of customers churn, a model that predicts everyone stays will claim ninety-five percent accuracy and be completely useless. Use techniques like SMOTE oversampling, class weight adjustment, or stratified cross-validation to handle this properly.
Overfitting to the training set is the second most common. If your model performs significantly better on training data than on validation data, you have overfitted. Regularization, feature reduction, and early stopping during training will help. So will accepting that your model may never be as accurate as you hope.
Not tracking experiments is the third. I used to rely on memory for hyperparameter choices and feature sets. That stopped working after project number four. Now I use MLflow or a simple spreadsheet to log every experiment with its parameters, metrics, and key observations. It sounds tedious, but it saves hours when you need to revisit a model six months later.
Feature engineering based on domain knowledge beats automated feature selection almost every time. Tools like Scikit-learn's SelectKBest or mutual information ranking can identify useful features, but they miss the interactions that a domain expert would spot immediately. I always combine automated selection with manual review, never the other way around.
Where the Field Is Heading and What to Watch
Auto-ML platforms continue to improve, but they solve a narrower slice of the problem than their marketing suggests. They handle model selection and hyperparameter tuning well. They do not handle data quality problems, business logic integration, or deployment. Treat them as acceleration tools for the middle of your pipeline, not replacements for the beginning and the end.
Large language models have changed the data analysis workflow in ways that are harder to quantify. They can generate SQL queries, write cleaning scripts, and produce initial exploratory summaries. The speed gain is real — tasks that used to take hours of writing and debugging code now take minutes of reviewing and correcting generated code. But the generated code is not reliable without human verification, and the tendency to produce plausible but incorrect results is a genuine risk. I use LLMs for boilerplate generation and as a second pair of eyes, never as an autonomous agent for production data.
The broader shift is toward embedded analytics. The models are moving from standalone dashboards into the products themselves. A recommendation engine is no longer a report you look at. It is a feature that runs inside the application your users interact with daily. That means the gap between development and production shrinks, and the expectation for reliability goes up accordingly.
If you are starting out, build one complete project from raw data to a simple deployed model. Do not cluster twelve partial tutorials together and call it experience. The gap between a tutorial that predicts a fictional sales figure and a system that actually influences business decisions is large, and crossing it requires dealing with the messy parts that tutorials conveniently skip. The messy parts are where the work actually lives.
Gallery Data Analysis And Artificial Intelligence
ARTIFICIAL-INTELLIGENCE (AI) And Data-Analysis || What Is ARTIFICIAL-INTELLIGENCE (AI) And Data ...
AI-driven data analysis integrating big data, business analytics, and artificial intelligence ...
Artificial Intelligence Data Analysis with Graphs and Charts for Decision Making Stock ...
Modern Data Analysis and Artificial Intelligence Visualization with Graphs, Charts, and Team ...
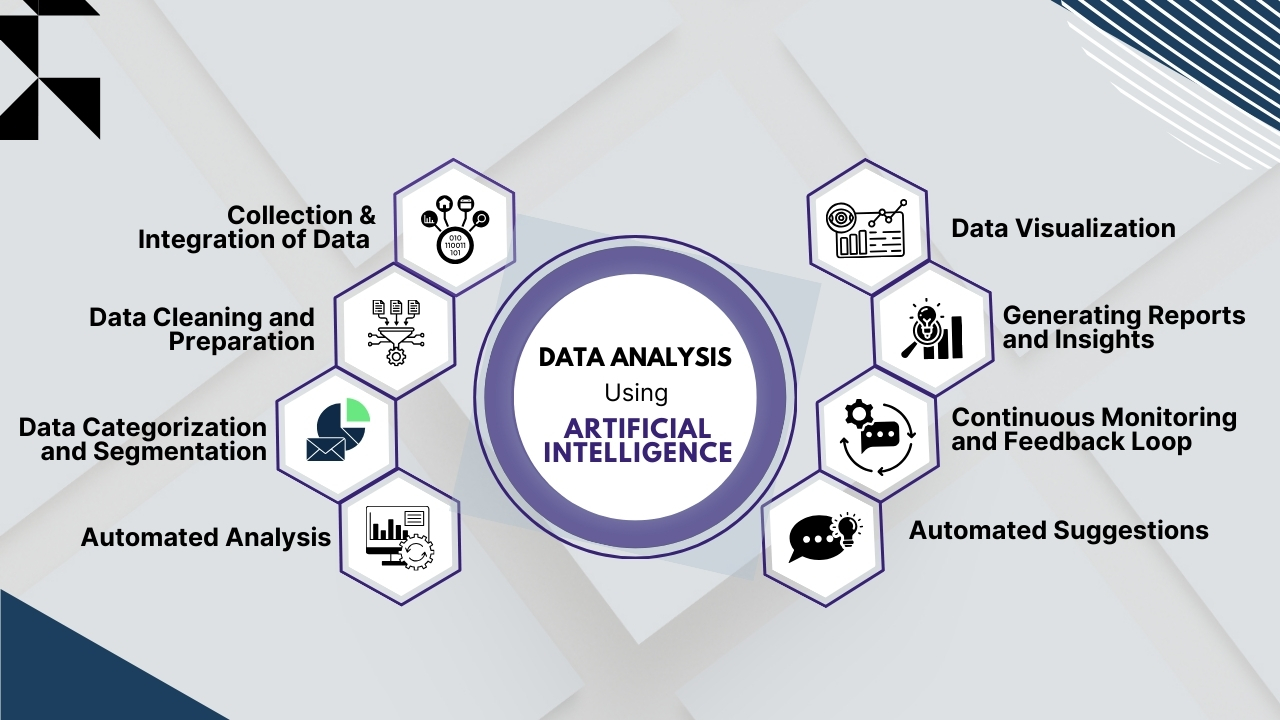
Automating Data Analysis using Artificial Intelligence