So you want to build a data model that doesn't fall apart when the numbers get weird
I spent three years doing this professionally before I stopped treating every project the same way. The first time I tried Data Analysis And Business Modeling on a manufacturing floor, I built a perfectly normalized star schema and handed it to a plant manager who had never seen a fact table in his life. He asked where the invoice numbers were. They weren't in the model. They were in a separate Excel file on his desktop labeled "actuals_final_v3." That's not a data problem. That's a communication problem. Here's what actually works, written out like I'm explaining it to someone who has to ship this next week.
Start with the question, not the tool
Most people open Power BI, dbt, or whatever they're using and immediately start pulling tables together. That's backwards. Sit down with whoever actually makes the decision and ask them to describe a scenario in plain language. "I need to know whether our margins are slipping on the east coast before the 10th of next month." Now you have a constraint, a geographic filter, a measure, and a time horizon. Build the model around that, not around every table your IT department says exists. The reason this matters: I've watched entire analytics projects die because the model was technically sound but the key metric didn't match what the CFO was actually tracking. The definitions diverged somewhere between engineering and finance, and nobody checked until the board meeting. Two weeks of rework. I learned to lock down metric definitions in writing before touching a single DAX formula or SQL query.
The modeling layer: keep it dumb, make it fast
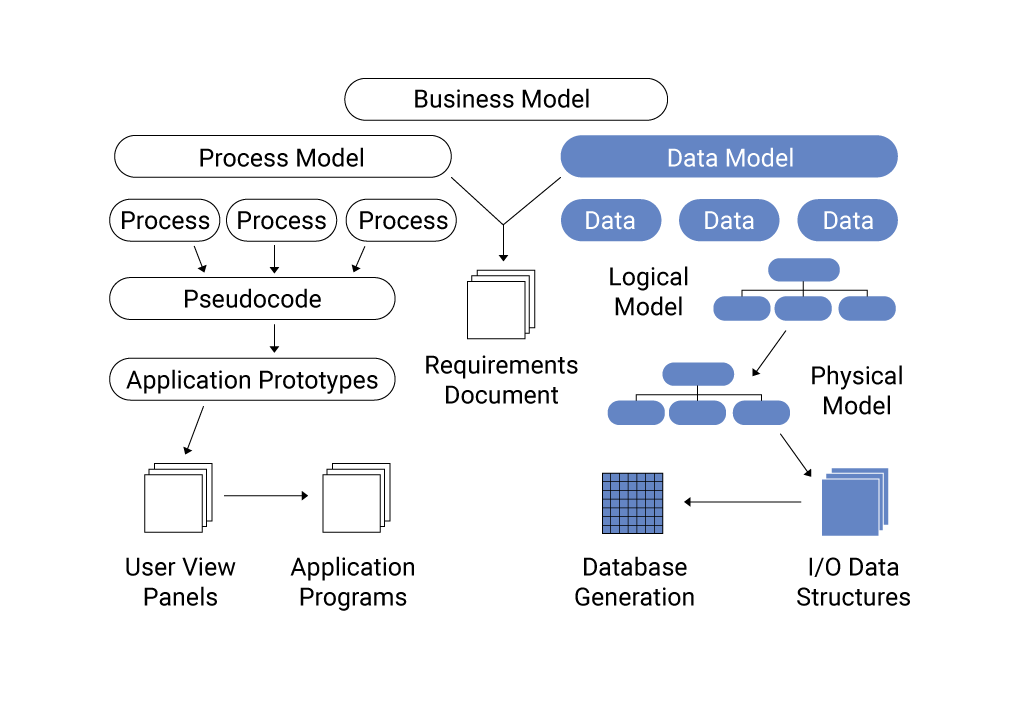
Your dimensional model should have facts and dimensions. That's it. Don't overthink the snowflake vs star debate — star is almost always better for business users because the relationships map to how people actually talk about data. "Sales by product category by region" is a single path through a star schema. Snowflaked dimensions force users to jump across multiple tables to get there, which translates to confusion and wrong answers. Here's a thing nobody mentions early enough: measure groups. Group your related KPIs together. Revenue, cost of goods, gross margin belong in one group because they share the same grain and the same time intelligence logic. Keep headcount and attrition in a separate group. Mixing grain levels inside a single measure group will bite you. I found this out the hard way on a retail project where average transaction value and store-level conversion rates shared a fact table but had different aggregation paths. The cross-filtering produced garbage numbers that looked plausible at first glance.
Get the Full Details

Data Analysis And Business Modeling actually means understanding grain
Grain is the level of detail your fact table lives at. Daily transaction grain. Monthly snapshot grain. Inventory-on-hand-at-midnight grain. Getting this wrong is the single most common mistake I see. A friend of mine built a forecasting model for a chain of gas stations and assumed daily grain. The underlying ERP only pushed batch updates twice a day, sometimes with a 4-hour lag. The model's dates didn't line up with reality. He ended up blending CSV exports from three different systems and writing a reconciliation script just to align the timestamps. Took him a week. Would have taken two days if he'd checked the source system's update cadence before committing to the grain. Always verify grain before you build. Ask the source team when data lands, how often, and whether there are corrections that happen retroactively. Most of the time they don't know. That's your red flag.
The tools: pick the one your team can actually maintain
Power BI for desktop analytics and quick dashboards. Tableau if your users live in dashboards and hate writing anything. dbt + a warehouse if you're doing this at scale with SQL-literate teams. SSAS tabular if you need enterprise semantic layers with row-level security baked in. There's no perfect choice. The right choice is the one your people will still be using in six months when the original developer leaves. I recommend Power BI for most small to mid-size organizations. The gap between building a prototype and shipping it is about 4 hours for a standard retail or operations dashboard. A comparable setup in custom SQL plus a frontend framework takes 2 to 3 days minimum. That's not an opinion. That's what I've priced into actual bids. For modeling logic, stop writing measures inside every report file. Create a shared semantic model. Publish it. Point everyone's reports at it. When finance changes a definition, you change it once, not twelve times across twelve .pbix files.
Common mistakes I still see in production models
Overcomplicating DAX. A 40-line calculated column usually means you're doing something the model structure should handle instead. If you find yourself writing complex FILTER and ALL combinations repeatedly, your dimension relationships are probably wrong. Fix the model, not the formula. Ignoring model size during design. I once loaded 800 million rows into a PBI dataset and wondered why refresh took six hours. The original requirement was for monthly trends, not transaction-level detail. Aggregating to monthly grain beforehand would have cut the dataset to under 2 million rows and the refresh to eight minutes. Always scope the data to the question, not to what the source system offers. Skipping documenation. Not code comments. Actual documentation: what each table represents, the business owner for each measure, the refresh schedule, known limitations. I kept a single markdown file in the same repo as the model. Six months later, when a new analyst picked up the project, they spent two days figuring out what "adjusted revenue" actually meant because nobody had written it down anywhere.

When this approach doesn't work
Dimensional modeling breaks down when your data doesn't fit neat hierarchies. Marketing attribution across channels, customer journey analysis with overlapping touchpoints, dynamic pricing where the "product" changes definition hourly. For those problems, graph models or even flat denormalized tables sometimes make more sense. Don't force a star schema where it doesn't belong. Also: this assumes your source data is at least somewhat clean. If your ERP is writing NULLs where there should be dates, or your CRM has duplicate customers that merge occasionally, no amount of good modeling will fix that. Data quality work comes first. You can't dimensional model your way out of bad source systems. The short version: figure out what question someone needs answered, find the grain that serves that question, build a star schema around it, document the definitions, and verify refresh times against your SLA before anyone calls it production-ready.