How Data Analysis Actually Works When You're Not Reading A Vendor Brochure
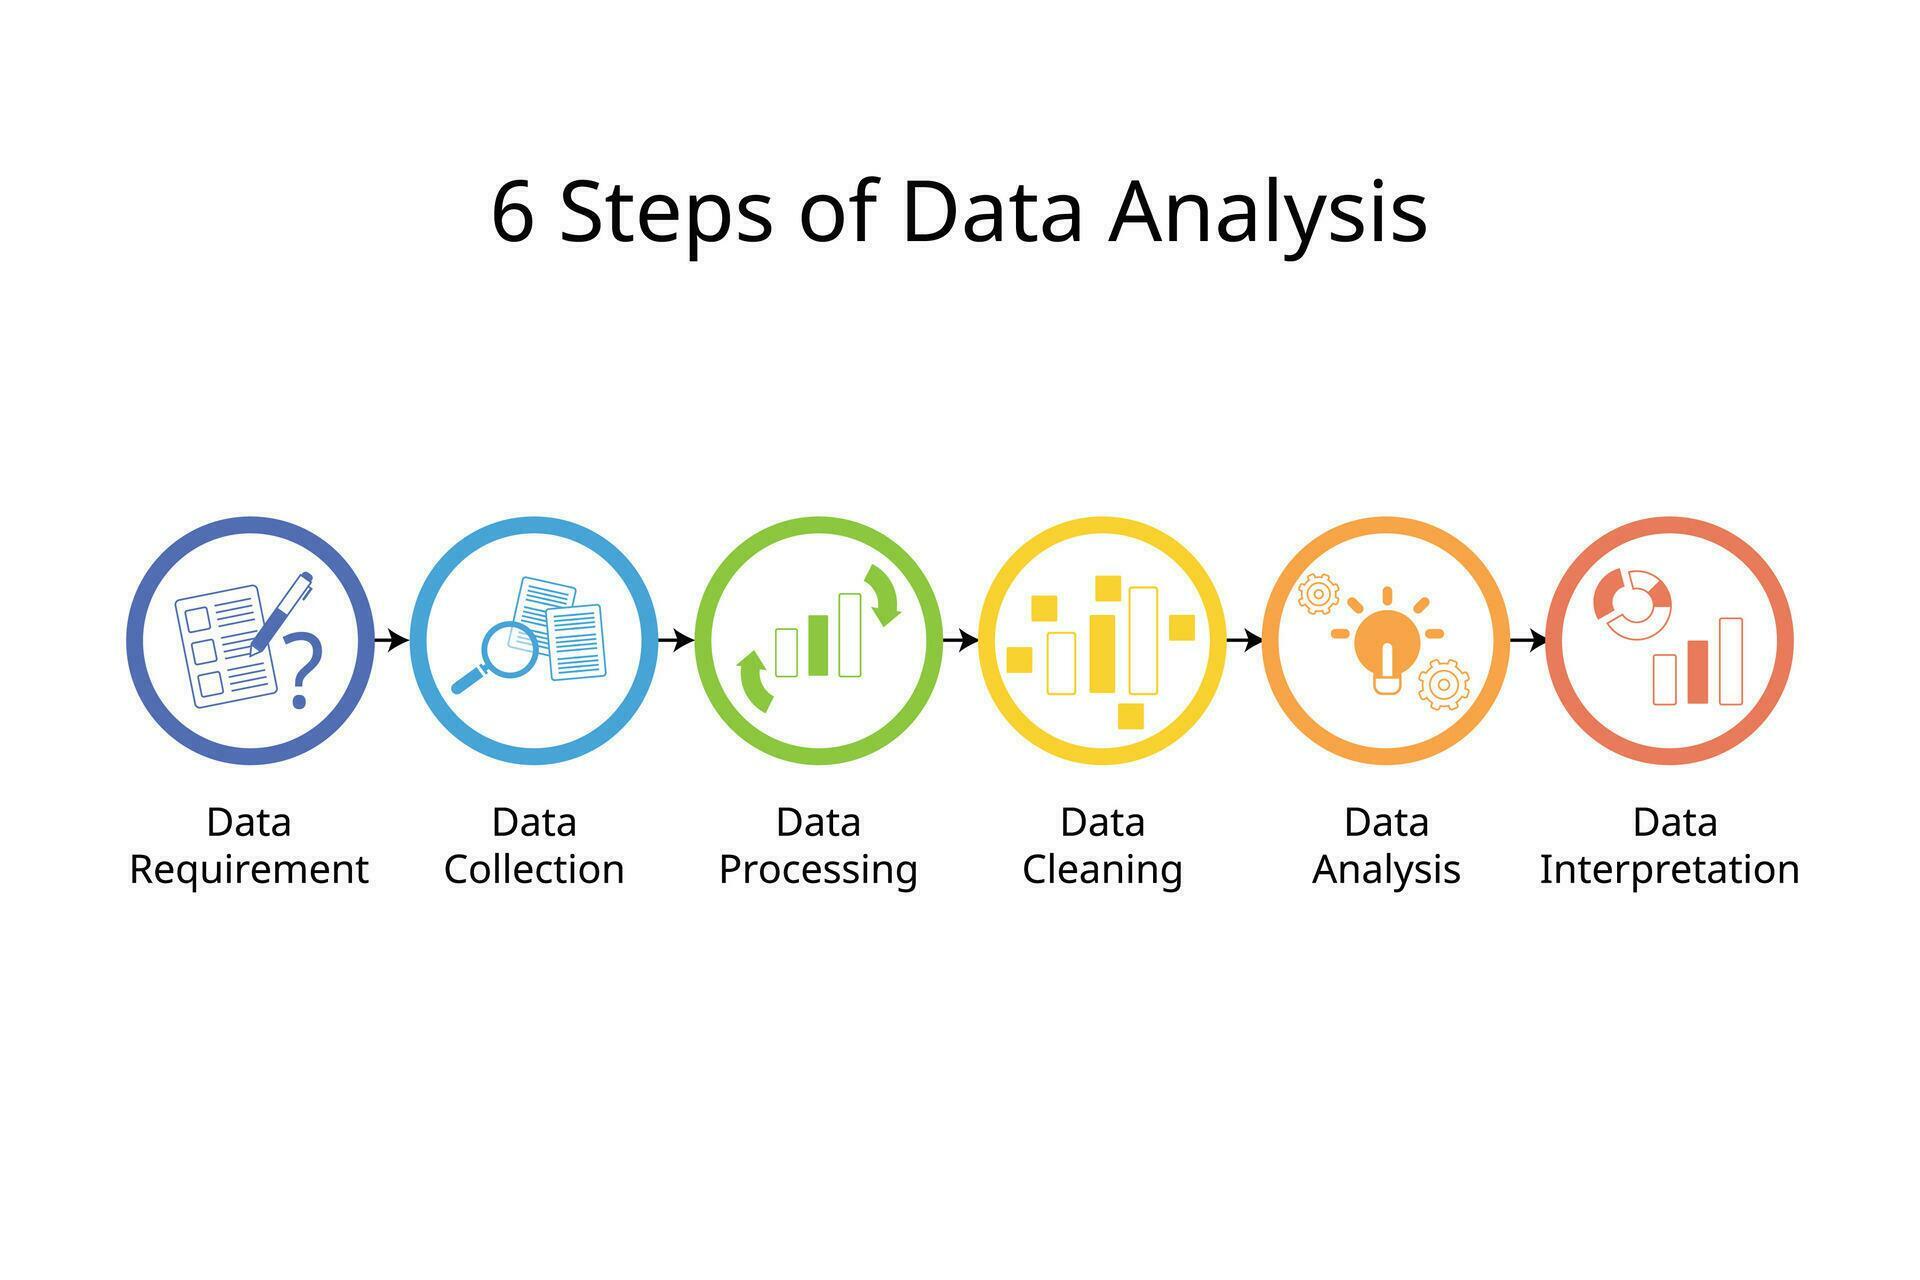
Most organizations treat data analysis and decision making solutions like software you install and it just works. I watched a mid-market supply chain team go from three days of manual pivot table work to something resembling automation in a single afternoon. The tooling wasn't fancy. It was mostly Python, a few well-structured SQL queries, and a clear understanding of what question they were actually trying to answer. The part nobody tells you about this process is that 80% of the effort happens before you touch a single line of code.The framework that actually holds up under pressure looks like this. You define the decision you need to make, then work backwards to figure out what data would change that decision if it were different. Everything else is noise. I had a client once who wanted a predictive maintenance dashboard for their manufacturing line. The first three weeks we spent cleaning sensor data, building ETL pipelines, training a random forest model. Then the operations manager asked a simple question: what threshold should trigger a shutdown? That was the actual decision. We replaced the entire dashboard with a single alert rule based on a basic temperature variance check. Took two days instead of six weeks.
Implementing Data Analysis And Decision Making Solutions In A Real Environment
Start with the data layer. Get your sources mapped and your schema documented. This sounds obvious but most teams skip it and spend months later trying to figure out where their numbers came from. I keep a simple markdown file with every column name, its source table, and the transformation applied. When your CFO asks where revenue recognition changed quarter over quarter, you should be able to trace it in under a minute.Next, pick your analysis tools based on what your team actually knows how to use, not what's trending on LinkedIn. A solid SQL database with dbt for transformations and a basic BI tool for visualization covers maybe 90% of use cases in most companies. The remaining 10% is where Python or R comes in for custom modeling. I've seen teams burn six figures on tools they never properly adopted because leadership wanted platform features that didn't solve their actual problems.
Build your metrics before you build your dashboards. Define lead time, conversion rate, churn, whatever matters to your business with exact mathematical definitions. "Customer satisfaction" means nothing until you specify whether it's CSAT score, net promoter score, or support ticket resolution time. Write these definitions down in a central metrics repository and enforce them. I inherited a project where three departments had four different calculations for "gross margin" and none of them matched. Took a month of reconciliation to figure out which one the executives were actually using in board presentations.
The Counter-Intuitive Part Nobody Talks About
More data does not equal better decisions. This is probably the single most important thing to understand about this space. I worked with a retail company that had terabytes of customer interaction data and made worse pricing decisions than their competitor with a fraction of the data. The difference was signal-to-noise ratio. Their model was picking up on spurious correlations like the day of the week intersecting with store location and discount level, while missing the actual drivers of purchase behavior.The workaround is Occam's razor applied to feature selection. Start with the simplest model that could plausibly explain the outcome. If a linear regression gives you 85% of the accuracy that a gradient boosting machine does, use the linear regression. It's interpretable, it's faster to retrain, and when it makes a wrong prediction you can actually explain why. In my experience, the stakeholders who need to trust the output are the ones who make the decisions, and they won't trust a black box they can't interrogate. Another thing that catches people off guard: correlation between your input features and your target variable isn't enough. You need causal understanding. I had a marketing attribution model that showed email campaigns drove 40% of conversions. The business poured money into email. Then we looked at the data more carefully and realized email was being sent primarily to high-intent customers who were going to convert anyway. The correlation was real. The causation wasn't. This cost them roughly eighty thousand dollars in misplaced budget before we caught it.
Common Pitfalls That Will Waste Your Time
Selection bias is the quiet killer. Your analysis only reflects the data you have, and your data only reflects the population that chose to generate it. If you're analyzing customer feedback, you're hearing from the people who felt strongly enough to leave feedback, which is systematically different from your average customer. I once built a sentiment analysis pipeline on support tickets and the model predicted overall satisfaction at 92%. The actual NPS was 31. The angry customers weren't filing tickets through the channel we were monitoring.Overfitting to historical patterns is the other big one. A model trained on two years of sales data will bake in seasonality, promotions, and market conditions from that period. When those conditions shift, the model keeps predicting based on the old pattern. I've seen this cause inventory managers to order twice what they needed during a demand spike because the model was anchoring to pre-spike baselines. The fix is regular model retraining schedules and out-of-sample validation, not just training accuracy. There's also the documentation problem. An analysis without clear assumptions is just an opinion with numbers. Every model, every transformation, every exclusion criterion should be logged. When your analysis is six months old and someone asks why a particular segment was excluded, you should have an answer. I keep every analysis in version-controlled notebooks with a README that states the question, the approach, the limitations, and the confidence level. It makes handoffs infinitely easier.
Get the Full Details

When These Solutions Don't Work
Let me be straight about the limitations. Data analysis and decision making solutions break down when the problem is fundamentally uncertain rather than probabilistic. If you're launching a product in a completely new market with no prior data, no historical analog, and no comparable competitors, fancy analytics won't save you. You need qualitative research, expert judgment, and experimental approaches like prototypes and MVPs. I've seen leaders misuse predictive models as decision substitutes in exactly these situations, treating uncertain futures as if they were statistically estimable. It doesn't work.Another scenario where this approach fails is when the decision requires value judgments that can't be quantified. Should we enter the Brazilian market? Can't be answered by data alone. You can inform it with market size estimates, regulatory risk scores, and competitive analysis, but the final call involves strategy, risk tolerance, and organizational capacity. No algorithm replaces that kind of deliberation. For organizations with very small datasets, the return on building full analytics infrastructure is questionable. If you're a twenty-person company making maybe fifty purchase decisions per month, a well-kept spreadsheet and a structured decision log will serve you better than a $50,000 analytics platform. I recommended exactly this to a B2B services firm last year. They were close to buying an enterprise solution their data volume couldn't justify. Saved them a painful migration and integration cycle.
Practical Steps To Get Started
Pick one decision your team makes regularly that currently relies on gut feel. Document how that decision is actually made today, including what information is considered and what is ignored. Then identify the data that exists around that decision and assess its quality. Is it complete? Is it timely? Is it accurate? Most organizations find their data quality is good enough for directional insight even if it's not production-grade. That's sufficient to start.
Build a minimal version of your analysis. One metric, one visualization, one clear recommendation format. Run it alongside your current decision process for a month without letting it influence the actual decision. Compare the model's implied recommendation against what you actually did. Where they diverged, investigate why. This gives you calibration data without any risk. Once you have that track record, expand gradually. Add a second metric, automate the report, bring in another stakeholder. The incremental approach prevents the common failure mode where teams build an elaborate system nobody uses because it was too big to deploy properly. My rule of thumb is that a solution should take no longer to implement than the time it saves in its first month of use. If that math doesn't work out, you've either overbuilt it or you're solving the wrong problem.