Stop Treating Data Cleaning Like It Is Optional
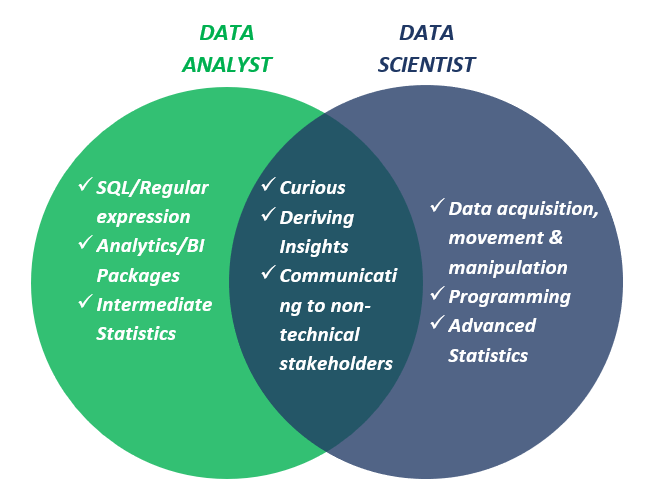
Most people waste weeks on modeling when they should spend three days on cleaning. I have seen entire Data Analysis Data Science projects collapse because someone loaded a messy CSV without checking column types. The model trained fine until you tried to deploy it. Then the prediction pipeline broke on the first real-world row. Here is how the work actually goes.
Setting Up the Workflow
Start with a clean environment. I use conda because it keeps dependencies separate and prevents the kind of version conflicts that make you pull your hair out. A typical setup for Data Analysis Data Science looks like this: pandas and numpy for manipulation, scikit-learn for modeling, and either matplotlib or plotly for visualization. If you are working with time series data, add statsmodels. For anything involving text, use nltk or spacy. Keep it simple until you hit a wall. I learned this the hard way on a project where I stacked five different data science libraries on top of each other. The project became unmaintainable within two weeks. The best setups use the minimum number of tools needed to solve the problem.
The Real Work: Cleaning and Validation
Raw data is almost never ready for analysis. Here is what I check first: Duplicate rows. They happen constantly when data gets merged from multiple sources. Use pandas drop_duplicates but always verify what is being dropped before you remove anything silently. Missing values. Do not just fill everything with the mean. That destroys variance and biases your models. I check the missingness pattern first using missingno or a simple isna().sum() across every column. Sometimes the gaps themselves carry information. In one project, missing transaction amounts correlated with fraudulent activity, which meant dropping those rows would have ruined the model entirely.
Get the Full Details

Wrong data types. Dates stored as strings. Categorical columns loaded as objects when they should be categories. This is more common than you think and it silently breaks aggregations and visualizations. Once I validated the data, I write the cleaning logic as a reusable function instead of pasting it into a notebook cell. Notebooks are fine for exploration but they become untestable messes if you never wrap your cleaning steps in functions.
Exploratory Analysis Before Any Modeling
Jumping straight into a random forest or gradient boosting is a mistake beginners make constantly. You need to understand distributions, correlations, and outliers before you fit anything. I run a full EDA pass using seaborn pairplots and correlation matrices. Then I look at the relationship between each feature and the target variable individually. Box plots for numerical features against categorical targets. Violin plots when you need to see density. These are not decorative. They reveal things that summary statistics hide. A feature might have a near-zero correlation with the target but still be highly predictive once combined with another feature. That only shows up in the visualizations or in a proper model later. Outliers need a decision, not automatic removal. In customer lifetime value prediction, the top 1 percent of spenders are real business entities. Removing them because they are statistical outliers destroys the signal you actually care about. In sensor data, outliers are often equipment failures and should be flagged and handled differently. Know your domain.
Feature Engineering That Actually Matters
This is where most tutorials fail. They show you to encode categorical variables and normalize features, then move on. That is table stakes. The difference between a mediocre model and a good one usually comes from features you construct yourself. Ratio features are underrated. Instead of feeding raw count and raw total into a model, create the ratio between them. Revenue per user. Clicks per session. These often carry more signal than the raw numbers. Interaction features matter too. Two weak predictors combined multiplicatively can create a strong one. Test this with a simple product term before reaching for deep learning. I remember a project where we were predicting equipment failure from vibration sensor data. The raw features gave us an AUC around 0.68. Nothing useful. We spent three days computing rolling statistical features: rolling mean, rolling standard deviation, and the ratio of high-frequency to low-frequency energy over a sliding window. The AUC jumped to 0.89. The model was still just a gradient boosting classifier. The features did the work.
Model Selection Is Less Important Than You Think
People obsess over choosing the right algorithm. With tabular data, a well-tuned light gradient boosting machine will beat most deep learning approaches. XGBoost, LightGBM, and CatBoost are the standard tools. CatBoost handles categorical features natively, which saves you from writing custom encoders. LightGBM is faster on large datasets. XGBoost is the most documented and easiest to find help for. Hyperparameter tuning matters, but grid search is usually overkill. I use randomized search or Optuna for hyperparameter optimization. Optuna prunes bad trials automatically and finds good configurations faster than a full grid. A typical Optuna run on a medium dataset takes 30 to 45 minutes on a single CPU. Grid search on the same space could take hours. Cross-validation is non-negotiable. Use StratifiedKFold for classification with imbalanced classes. Use TimeSeriesSplit if your data has any temporal component. Random k-fold on time series data gives you look-ahead bias, which means your validation scores will be artificially high and your production performance will disappoint.
Validation Pitfalls
The biggest mistake I see is training and validation coming from the same distribution without checking. If your training data covers January through October and your validation data covers November, you are testing temporal generalization, not random generalization. Make sure your split strategy matches your deployment scenario. Another common error is data leakage through feature selection before cross-validation. If you select features using the entire dataset and then run cross-validation, your model sees information from the validation fold during selection. Always wrap feature selection inside the cross-validation loop using sklearn Pipeline.
Deploying Is Where Things Get Ugly
A model that works in a Jupyter notebook is not a product. I have trained models that scored perfectly in validation and failed immediately in production because the preprocessing steps were not preserved exactly. The fix is always the same: serialize your entire preprocessing pipeline along with the model using joblib or pickle. Do not re-fit preprocessing on the production data. Fit it once, save it, apply it consistently. Monitoring matters more than most teams realize. Model performance degrades when the input data distribution shifts. This is called dataset shift and it happens constantly. Set up a simple monitoring pipeline that logs prediction distributions and compares them to the training baseline every week. If the drift is significant, retrain. If it is not, do not touch the model. I had a churn model that started losing accuracy gradually over six months. The feature distributions had not shifted noticeably. The issue was a change in the customer acquisition channel that introduced a new segment the model had never seen. Retraining on the last twelve months of data fixed it. Regular retraining schedules prevent these surprises from becoming emergencies.

When Data Analysis Data Science Methods Break Down
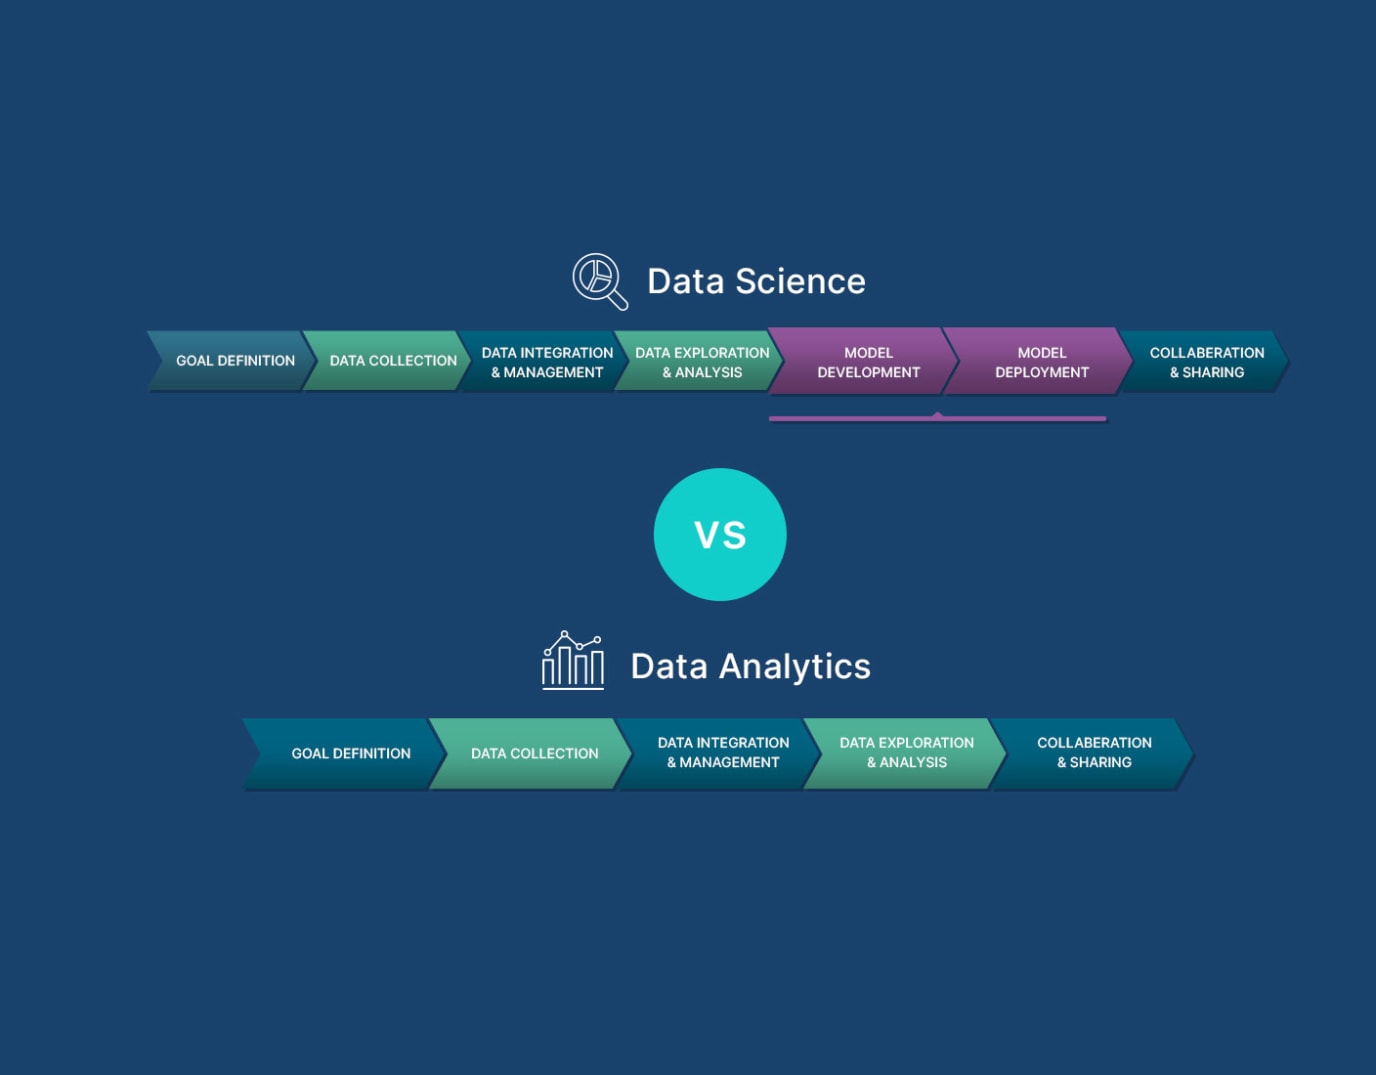
Gradient boosting models do not handle missing values well in production if the missingness pattern changes after training. Linear models assume linearity and can fail catastrophically on nonlinear relationships. Neural networks require large datasets and substantial compute. If you have fewer than ten thousand rows, stick to tree-based methods or regularized linear models. Sometimes the answer is not a better model but a better question. I have walked away from projects where the underlying business problem was ill-defined. No amount of feature engineering fixes a vague objective. Spend time understanding what metric actually matters to the business before you write a single line of code.
Practical Next Steps
Pick a dataset you can access easily. Kaggle has plenty of cleaned options if you need one. Build the cleaning pipeline first. Run exploratory analysis. Engineer a small set of features based on domain reasoning rather than copying someone else's approach. Train a baseline model. Iterate. Repeat. The workflow is straightforward. The difficulty is in the details. Missing value imputation strategies that seem harmless can introduce bias. Feature scaling matters more for some models than others. Cross-validation folds that are too small produce unstable estimates. These are the things that separate people who ship models from people who collect notebooks. Data Analysis Data Science is not about the latest technique or the most complex model. It is about building a reproducible pipeline from messy input to reliable output. Most of the work happens in the messy middle part.


