Getting Your Social Science Data Into Shape
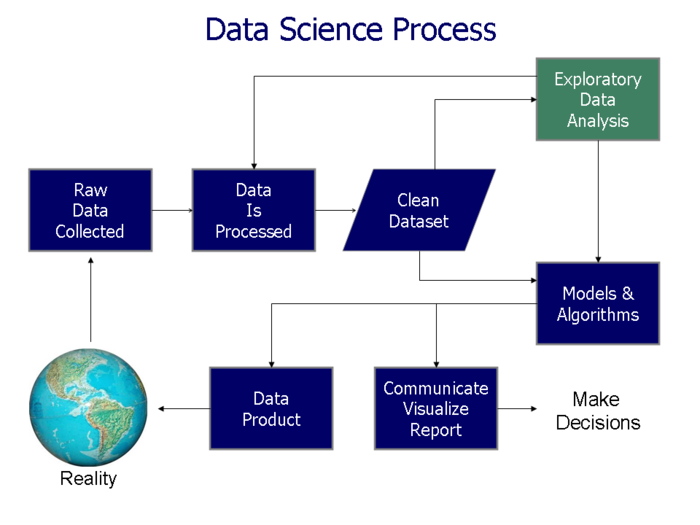
Most people start with messy spreadsheets. That is just how it goes. You download survey data from Qualtrics or you scrape some Twitter posts, and suddenly you are looking at rows of missing values, weird date formats, and column headers that say things like "Q1a_recode_v2_final." The actual analysis part, the statistical modeling or whatever you need to do, usually takes less time than cleaning the data itself. This is a pretty consistent pattern across the field. When I first started working with panel data from the World Values Survey, I spent about three weeks just figuring out why the respondent weights didn't match the sample sizes across waves. It turned out one of the newer waves had a completely different skip pattern that I had never seen documented anywhere. The workaround was to write a small script in Python that recalculated the weights based on the response rates for each country and then merged that back into my main dataframe. It added maybe two hours of work but saved me from publishing results that were technically biased. The choice of tool matters more than most beginners admit. R is the standard in academia. Stata is still everywhere in economics and political science departments. Python has been gaining ground, especially among people doing text analysis or machine learning applications. I tend to use R for most of my work because the packages for survey design and complex sampling are genuinely better there. The svy package and the survey ecosystem handle stratified multistage cluster samples the way they were actually designed. Trying to replicate that logic in a general purpose pandas pipeline is possible but it requires writing a lot of custom code and that introduces its own failure modes. For downloading raw datasets, the major repositories are straightforward. The ICPSR archive at the University of Michigan hosts probably the largest collection of social science data. You can create a free account and download most datasets directly from their web portal. The American National Election Studies data is hosted on their own site. If you are working with cross national survey data, the Comparative Study of Electoral Systems database is a decent resource. Some of these require a data use agreement. The agreement is usually just a few pages and they approve within a couple days.
Practical Steps That People Often Skip
Documentation is one of those things that sounds obvious until you are six months into a project and cannot remember what you coded variable 47 as. Keep a separate notes file. I write mine in plain markdown and include the date, the source of each variable, and any transformations I applied. If a value seems wrong, write down why you decided it was wrong instead of silently dropping it. Silently dropping observations is the fastest way to get a number that looks clean but is actually meaningless. Here is a specific edge case I ran into recently. I was analyzing voter turnout data from the Cooperative Congressional Election Study and the turnout variable seemed artificially high for certain demographics. After digging into the metadata, I found that the survey had switched from asking respondents whether they voted to asking whether they were registered to vote in some waves. The variable label did not change. If I had not checked the codebook version history, the results would have been completely wrong. The fix was to split the dataset by year and apply different recoding rules depending on the wave. That added maybe forty five minutes of work at the cost of a fairly simple conditional in the data processing script. Weight variables deserve careful attention. Many national surveys come with built in weights that account for differential response rates and post stratification to census benchmarks. If you ignore them, your point estimates might look fine but your confidence intervals will be too narrow. The default behavior in many software packages is to run analyses without weights unless you explicitly tell it otherwise. R's survey package makes this harder to mess up because you have to define a survey design object first. In Stata, you use the [pw=] syntax which is easy to forget. I once submitted a paper where I had omitted the weight variable for one of the tables. The reviewer caught it before publication but the embarrassment was real.
Common Pitfalls in Applied Work
Multicollinearity is something you will encounter if you work with regression models for long enough. It happens when two or more independent variables are highly correlated with each other. The coefficients become unstable and standard errors blow up. Beginners often see inflated standard errors and panic. Sometimes the right response is to just drop one of the correlated variables. Sometimes you reparameterize the model. A concrete example: if you include both education level and years of education in the same regression, the model cannot distinguish between them. Education level is really just a categorical version of years of education and putting both into the same model is redundant. I have seen this happen more often than I would like to admit in published work. Another issue that comes up constantly is measurement error. Survey responses are never perfect measures of the underlying constructs you are trying to study. When you use a single Likert scale item to measure political trust, for instance, that single item contains a lot of noise. The noise biases your coefficients toward zero. This is the classic attenuation bias. If you want to address it, factor analysis or structural equation modeling can help by separating the true score variance from the error variance. These methods are more complex and they require larger sample sizes. A simpler fix is to use multiple items and average them into a scale score before running your models. That is usually sufficient for most social science applications. Missing data is probably the single biggest practical headache. There are several approaches. Listwise deletion removes any case with a missing value on any variable you include in the analysis. This is the default in many software packages. It is also often the worst option unless the data are missing completely at random, which is a very strong assumption that rarely holds in social science. Multiple imputation is the more sophisticated approach. It creates several complete datasets, runs the analysis on each one, and then combines the results using Rubin's rules. R has the mice package which handles this reasonably well. Stata has the mi suite of commands. The downside is that multiple imputation assumes the data are missing at random, which means the missingness depends only on observed variables. If the missingness depends on unobserved variables, even multiple imputation cannot fully correct the bias.
Get the Full Details

A Word on Causality
Social science data is overwhelmingly observational. That means you cannot simply run a regression and claim causation. The difference between correlation and causation is not just a slogan your methods professor drilled into your head. It is a real constraint on what you can conclude from your data. If you want to make causal claims, you need a credible identification strategy. Difference in differences works if you have before and after data for a treatment group and a comparable control group. Instrumental variables can work if you can find a variable that affects the treatment but not the outcome except through the treatment. Regression discontinuity designs exploit a cutoff rule. None of these methods are easy to implement correctly and all of them have assumptions that are difficult to verify with observational data alone. I remember working on a project examining the effect of welfare receipt on political participation. The raw bivariate relationship showed that welfare recipients participated less in elections. The immediate temptation was to write a paper about how welfare dependency erodes civic engagement. That narrative is clean and it would have gotten cited. But the relationship was almost entirely driven by confounding variables like income, education, and health status. Once I controlled for those factors, the relationship disappeared completely. The real story was that people who are already marginalized in the labor market are both more likely to receive welfare and less likely to vote. The policy implication was much less dramatic but also much more honest. This is exactly the kind of thing that separates careful analysis from narrative building.
Software Setup and Initial Configuration
If you decide to go with R, installing the core packages is straightforward but you should also install a few extras that save time later. The tidyverse collection handles most data manipulation needs. The haven package is essential for reading SPSS, Stata, and SAS files without corruption. The readxl package handles Excel files, though you should always prefer saving those as CSV instead. For survey data specifically, the survey package and its dependencies are non negotiable. If you are doing any kind of text analysis, the tidytext package is a reasonable starting point even though it is more of a gateway drug than a complete solution. Stata users should familiarize themselves with the data management commands early. Commands like preserve, restore, collapse, and reshape will appear in nearly every project. The xtset command is essential for panel data. Understanding the difference between long and wide format is critical because most panel data come in wide format from the original sources and you need them in long format for most analyses. Python users will work primarily with pandas for data manipulation, numpy for numerical operations, and statsmodels or sklearn for statistical modeling and machine learning. The combination is powerful but the ecosystem is less standardized than R's. You will find yourself making more choices about which library to use for a given task and that can slow you down when you are under time pressure.
What This Approach Cannot Do
No amount of statistical sophistication can rescue a fundamentally flawed research question. If you are asking a question that cannot be answered with observational data, running more models will not change that fact. Regression discontinuity designs require a clean cutoff and a large sample around that cutoff. Most social science phenomena do not come with natural cutoffs that are this clean. Difference in differences requires parallel trends, which you can never fully prove. You can make an argument based on pre treatment patterns but that argument is always vulnerable to criticism. These are hard constraints on what observational social science can claim. Being honest about those constraints in your methodology section is more valuable than pretending they do not exist. Another limitation that is worth stating upfront is the replicability crisis that has affected parts of the social sciences. Many published findings turn out to be fragile when other researchers try to reproduce them. This is not because the methods are fundamentally broken. It is because of practices like p hacking, selective reporting, and insufficient sample sizes. Pre-registration of study designs and analysis plans is one partial solution. Sharing your code and data publicly is another. Neither of these practices is universally adopted yet but they are becoming more common and they improve the overall quality of the literature.