Getting Data Analysis In Schools Actually Working
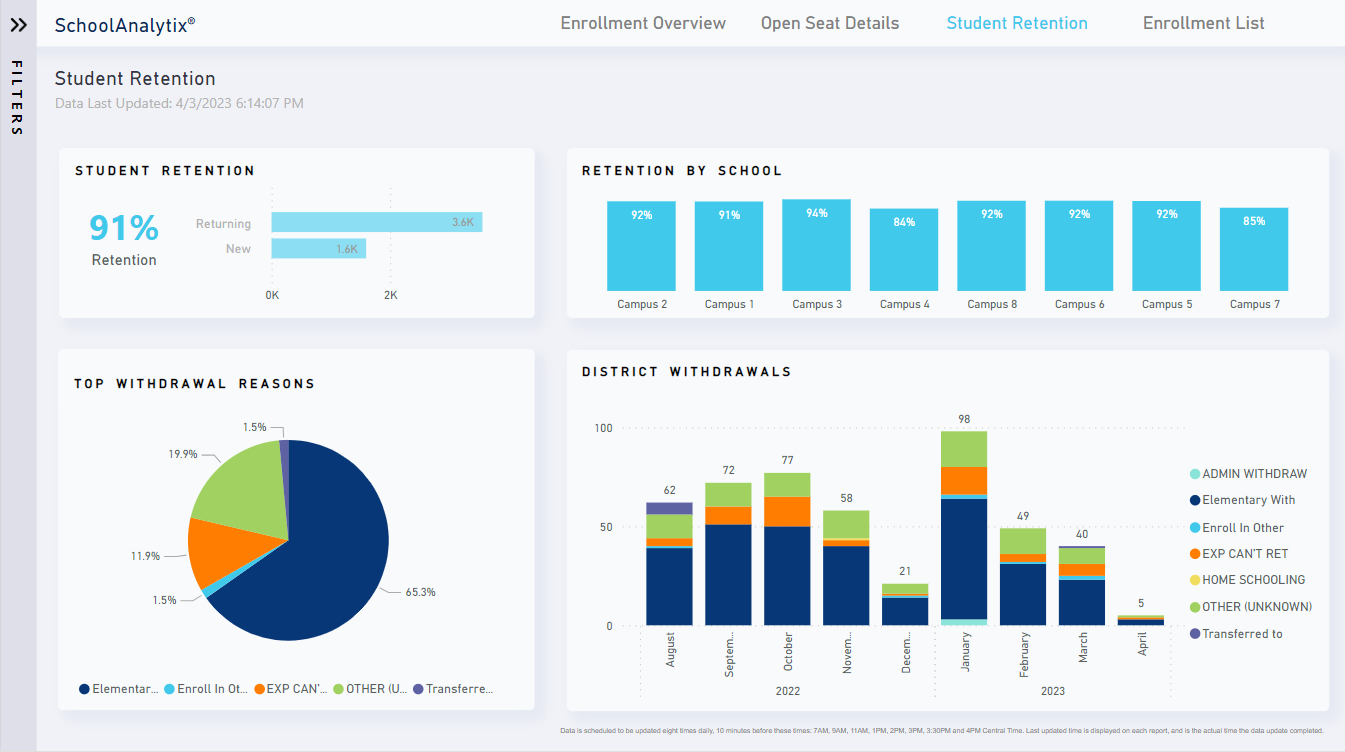
Most schools buy a dashboard license, hand it to a data coordinator who has never touched SQL, and wonder why nobody looks at the numbers. I spent four years at a mid-size district wrestling with this exact problem. The tools aren't the issue. The workflow is. Here is what actually moves the needle. You need three things connected in sequence. Your student information system feeds a data warehouse, which feeds a visualization layer. If any one of those breaks, the whole thing goes quiet. The most common failure point is the middle layer. SIS exports come in wild formats — some districts still use tab-delimited text files renamed as CSVs, some export dates as Unix timestamps, some encode ethnicity codes differently between quarters. A single mapping file handles this, but nobody writes one because it is boring administrative work. I built a simple Python script using pandas that ingests whatever the SIS spits out each month, maps fields to a standard schema, flags records that don't match expected patterns, and writes clean rows to PostgreSQL. It runs on a cron schedule. Takes about six minutes. Before that script, my team spent two days per month manually fixing exports. That is the difference between having data and drowning in it.
The visualization tool at the end is almost secondary. You can use Power BI, Tableau, Metabase, or even Google Looker Studio. They all connect to a relational database. Pick whichever your district already has a license for. Do not buy a new tool unless you have a specific feature gap that matters. I watched three districts purchase expensive analytics suites while their internal tables were so inconsistent the dashboards showed wrong enrollment numbers. The software could not fix bad data.
What to measure and why most districts get it wrong
Everybody starts with graduation rate and test scores. Those are lagging indicators. By the time they show up in your dashboard, the intervention window has closed. The useful metrics are leading indicators — attendance trends at the individual student level, course failure rates by teacher and term, demographic breakdowns of discipline referrals, credit accumulation by semester for ninth graders. These show you who is drifting before they actually fall off. I once pulled a cohort of 140 ninth-grade students who had perfect attendance in August but dropped below 85 percent by October. Zero of them had any recorded behavioral incident. Their grades in core classes were deteriorating slowly. The district had no alert for this pattern because nobody had configured one. We set up a simple trigger in the database that flagged any student dropping below 85 percent attendance across two consecutive weeks and sent an automated email to the counseling team. Within two quarters, early intervention meetings increased by forty percent. Not a fancy model. Just a threshold check.
Get the Full Details
The infrastructure you actually need
You do not need a data science team. You need one person who understands basic data management and the authority to talk to the SIS vendor about field definitions. Everything else is a spreadsheet with better graphics. Here is a minimal setup: A cloud database — AWS RDS, Azure SQL, or even a managed Postgres on DigitalOcean. For a district of fifty thousand students, you are looking at roughly two hundred dollars per month. A scheduled ETL job, either a cron script or something like Apache Airflow if you want workflow tracking. A BI tool with role-based access so principals only see their building and teachers only see their sections. And a written data dictionary that explains what each field means. This last one is non-negotiable. I have seen reports where "enrollment" meant daily headcount in one system and registered students in another, producing completely different numbers depending on which source the analyst used.
Common failure modes in Data Analysis In Schools implementations
The biggest one is over-aggregation. When you roll up data to the building or district level, individual student patterns disappear. A school might show 92 percent attendance and look fine, while fifty students are hovering at 78 percent. You need at least a classroom-level view that rolls up, not the other way around. The second is tool worship. People spend months configuring dashboards with conditional formatting and custom themes instead of asking what question the dashboard should answer. A dashboard that answers one clear question is more useful than one that answers ten poorly. My rule is simple: if a metric does not change an action someone takes, it does not belong on the dashboard. Remove it. A third problem is compliance. FERPA restrictions mean you cannot share student-level data outside secure systems without consent. I once had a situation where a researcher requested disaggregated data by free-reduced lunch status across all schools. The raw data itself was fine, but the combination of variables — grade, race, disability category, and score — could identify individuals in small schools. We had to apply a minimum cell size of ten before releasing anything. It took two rounds of negotiation. Document your disclosure review process early, or you will spend months on IRB-style back-and-forth.
Starting small and scaling deliberately
Pick one grade band and one metric. Ninth-grade course failure in algebra, for example. Build the pipeline for that. Prove it works. Show a principal how to pull a list of students at risk before the midterm. Then expand to another metric, then another. Most districts try to build everything at once and deliver nothing usable by June. The script I described earlier started as a single table mapping file and a hundred lines of Python. It grew slowly as new data sources got added — special education records, transportation data, lunch program eligibility. Each addition took a day or two, not a week. The key was keeping the schema flexible enough to accommodate new fields without breaking existing queries. A wide table with nullable columns and a separate metadata table for field definitions handles this cleanly. If your district cannot commit to even this minimal approach right now, start with a shared spreadsheet that auto-pulls from your SIS export using a webhook or a scheduled API call. It is not elegant, but it is better than manual copy-paste. Something is better than nothing, and you can graduate the workflow later when someone has bandwidth to improve it.
The hardest part of data analysis in schools is not the technology. It is getting people to trust the numbers enough to act on them. I have seen valid alerts ignored because a counselor did not understand how the threshold was calculated. Document your methodology. Show your work. Make it transparent. Otherwise you are just another dashboard nobody opens.