Getting Past the Interface
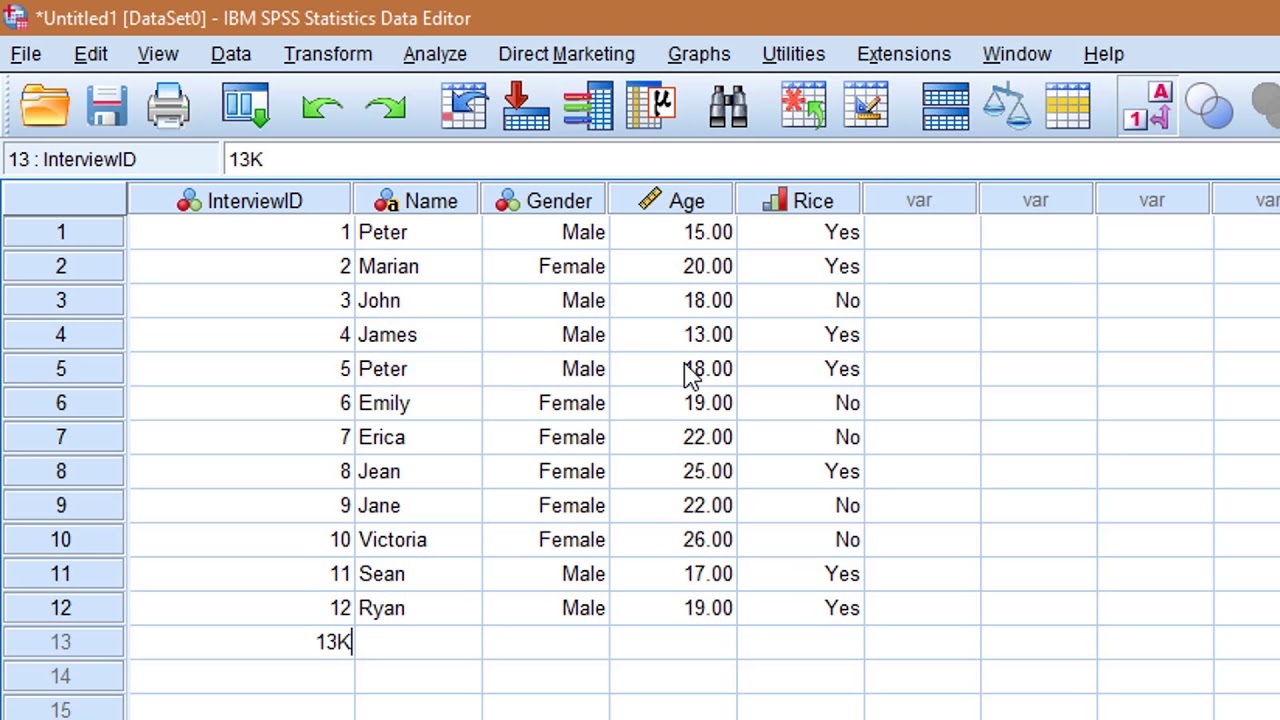
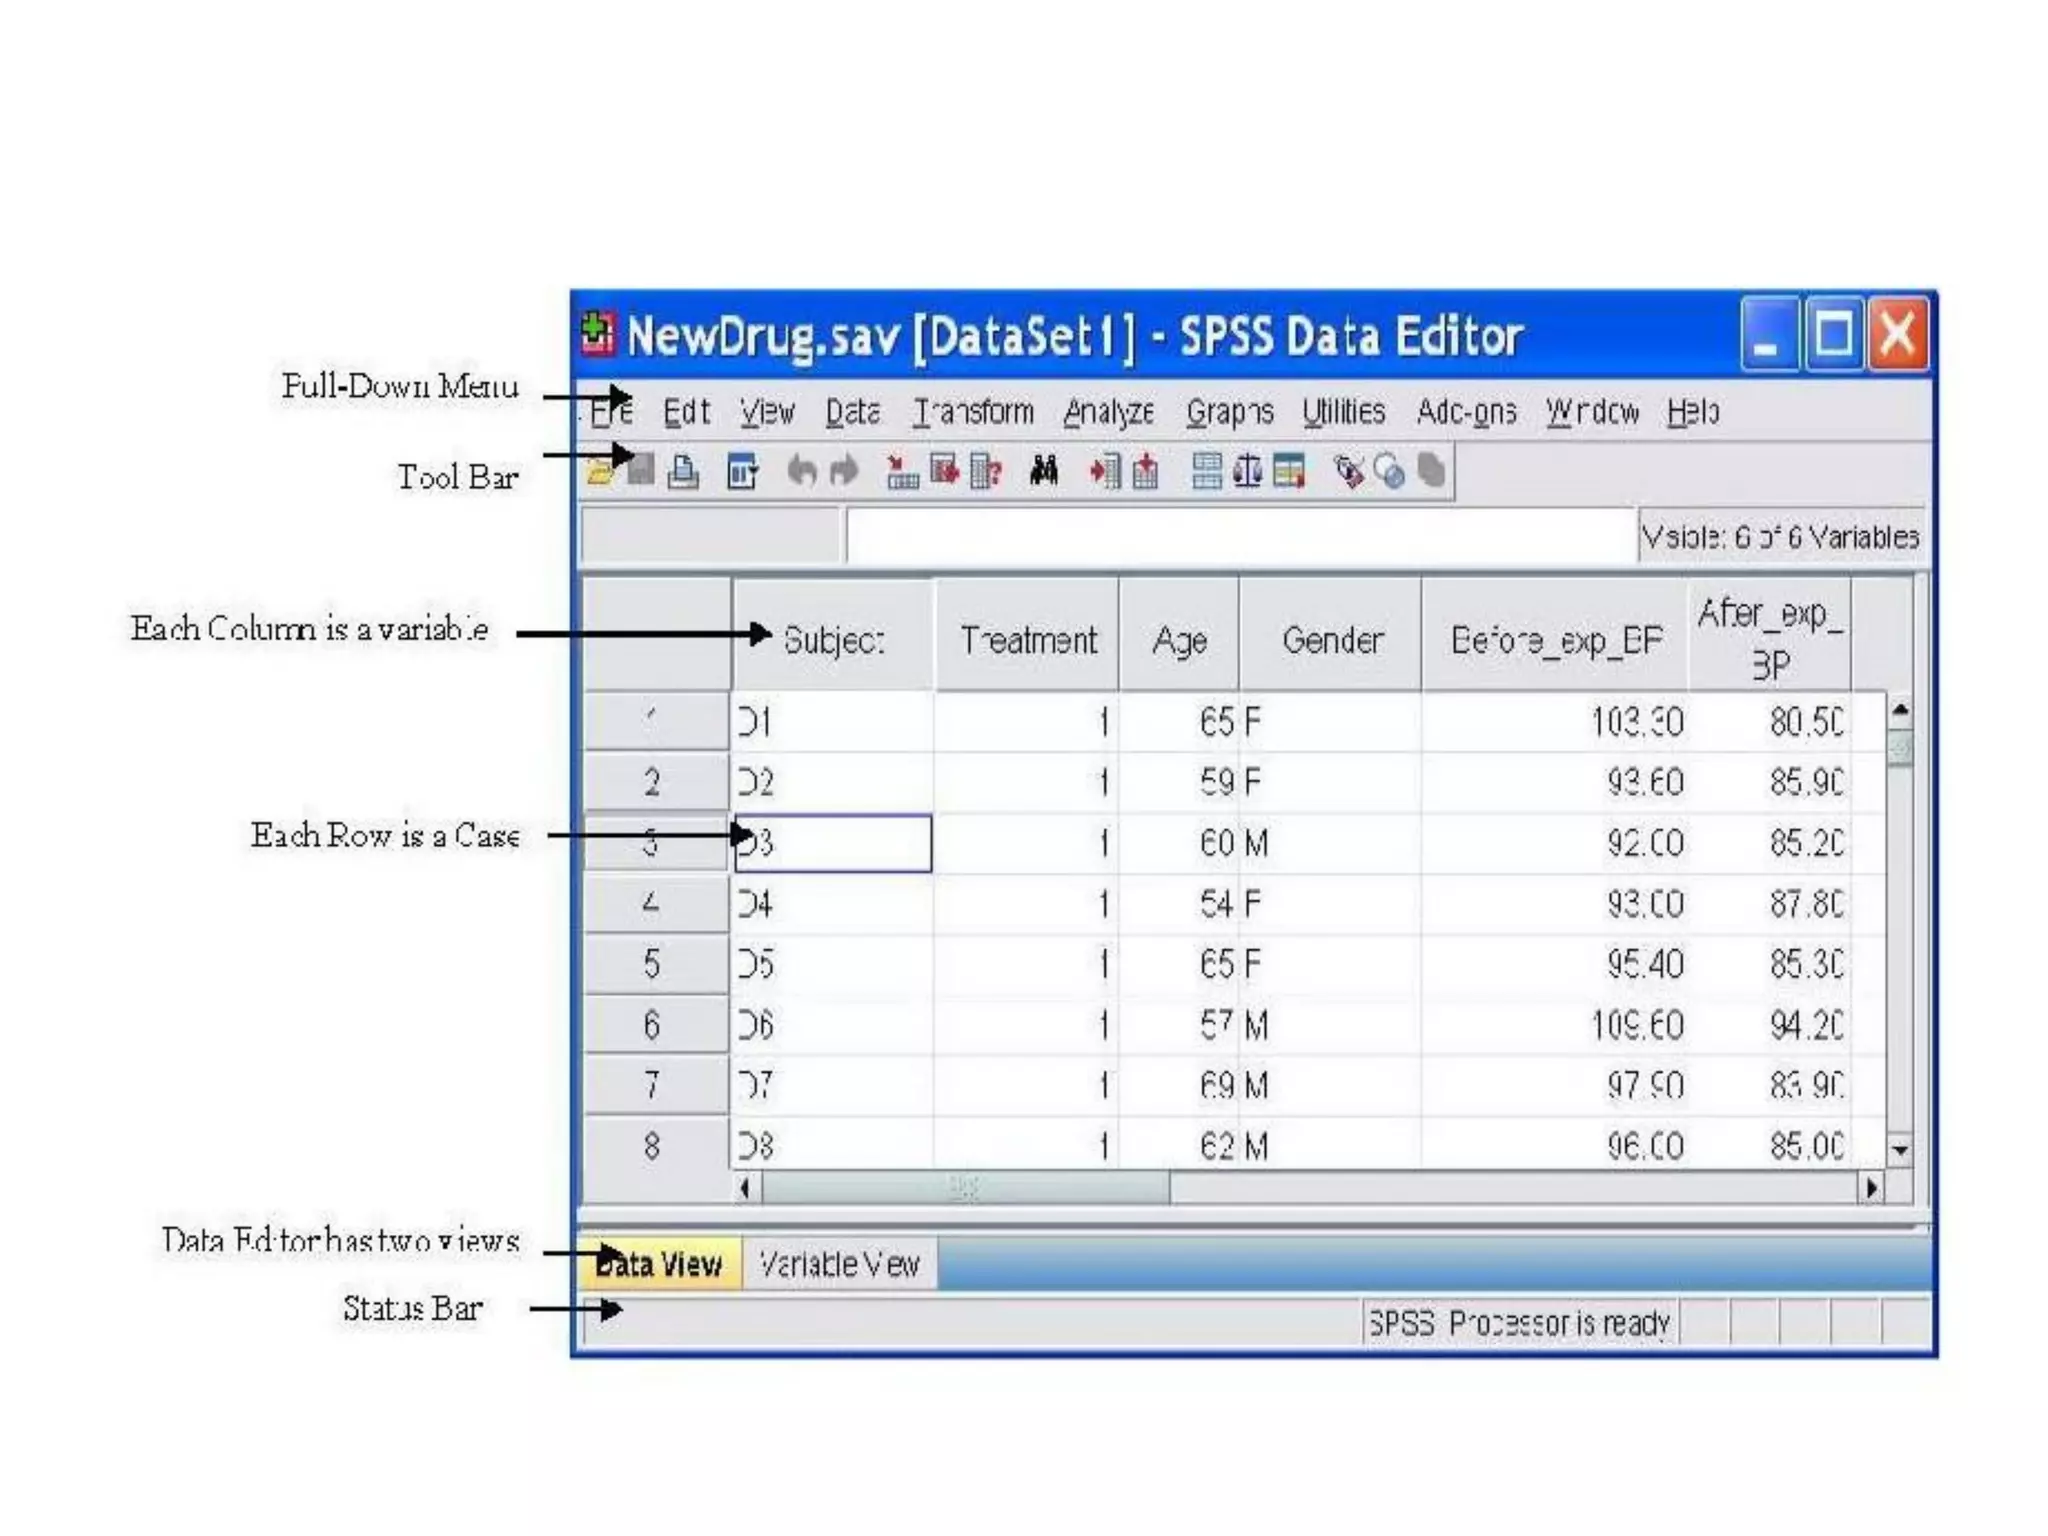
SPSS stands out because it forces you to think about your data structure before you run anything. The Variable View tab exists for a reason, and most people skip it entirely. I spent two weeks troubleshooting a logistic regression that produced nonsensical coefficients, only to realize the dependent variable was coded as string instead of numeric. SPSS never complained. It just treated the data wrong from the start. Every analysis begins with Variable View. This is where you define whether a variable is nominal, ordinal, or scale. Set it wrong, and your frequency tables will look like garbage while SPSS silently proceeds. The scroll-to-the-right-and-set-measurement-level step takes roughly 30 seconds per variable, but it saves about two hours later when you are trying to figure out why a chi-square test won't run.
Data Analysis In Spss With Examples
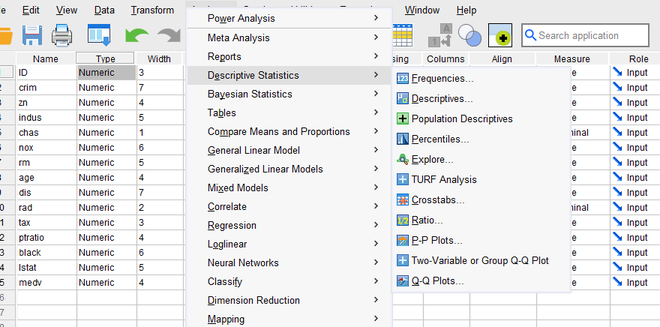
The most common entry point is the Data folder type, which loads comma-separated or Excel files directly. When I imported a 50,000-row clinical trial dataset last year, the auto-detection labeled three numeric variables as strings because some cells contained blank fields that SPSS interpreted differently. The fix was running the syntax RECODE old_var INTO new_var after setting the correct measurement level. Without that recode step, any descriptive statistics command returned missing value errors across the board. From the menu bar, Analyze gives you everything. Descriptive Statistics has Frequencies, which works for categorical variables and gives you counts and percentages in one click. Cross-tabulations sit under the same submenu, and that is where most people hit their first real wall with SPSS. Here is a specific edge case: cross-tabs treat missing values differently than you expect. If you have 200 respondents and 30 are missing data on one question, SPSS excludes those 30 from that particular table, not from your entire dataset. I lost a day tracking down an inconsistency once because I assumed the sample size was consistent across all outputs. It was not. The numbers changed depending on where missing values appeared. This is normal behavior, but it trips people up constantly.
Running the Actual Analysis
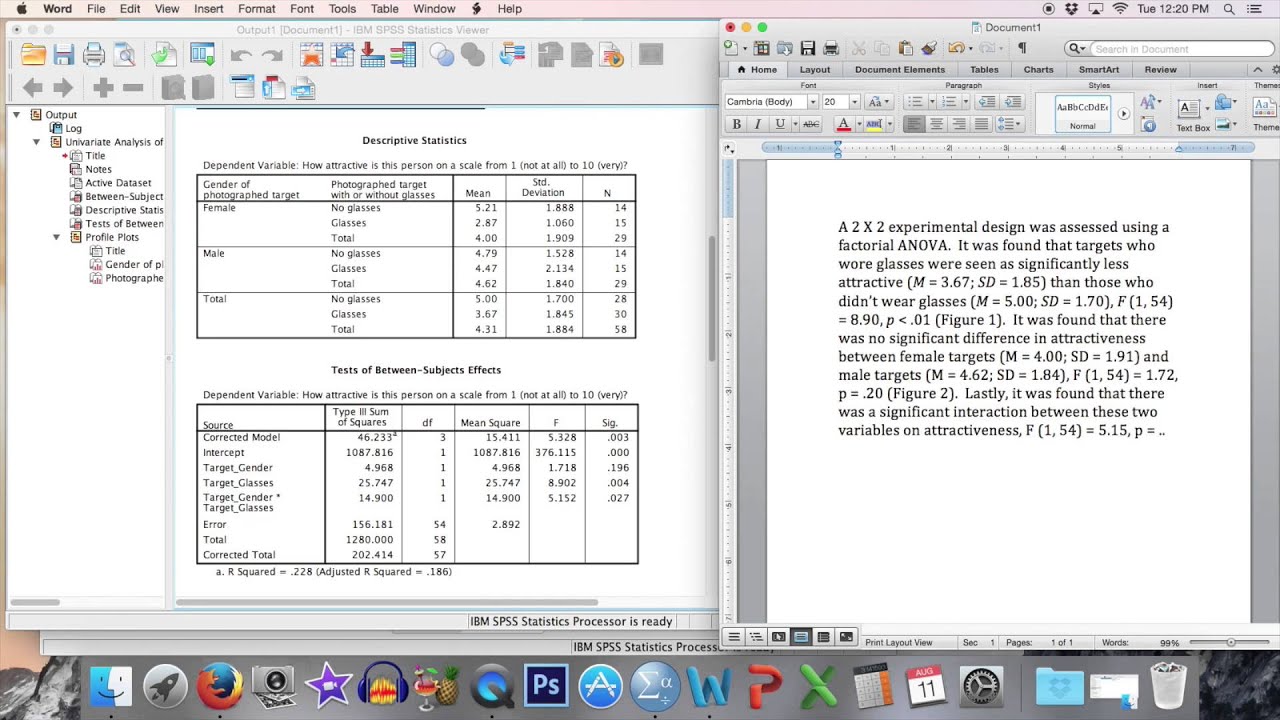
For a basic independent t-test, go to Analyze, Compare Means, Independent-Samples T Test. You select your grouping variable and your test variable, then define the groups by their actual codes. If your gender variable uses 1 and 2, you enter 1 and 2 in the Group 1 and Group 2 boxes. Enter text labels by mistake and SPSS returns a message saying no cases satisfy the condition, which looks like a broken program but is really just a coding mismatch. ANOVA follows the same pattern. One-way ANOVA under Compare Means gives you the F-statistic and post hoc options. The post hoc tests are where people usually go wrong. Scheffe is conservative. Tukey is standard. LSD is essentially doing multiple t-tests without correction, which inflates Type I error, and I see junior analysts default to it because the p-values look nicer. They should not. Regression lives under Regression, Linear. You put your dependent variable in the DV box and your predictors in the Independent(s) box. The default method is Enter, which forces all variables into the model at once. Forward and backward stepwise exist but introduce their own problems, especially with small samples. A rule of thumb that actually matters: you need roughly ten cases per predictor variable for stable estimates. Eight hundred cases with eighty predictors is asking for overfitting regardless of what the software shows you.
Get the Full Details
Weighted Data and Survey Analysis
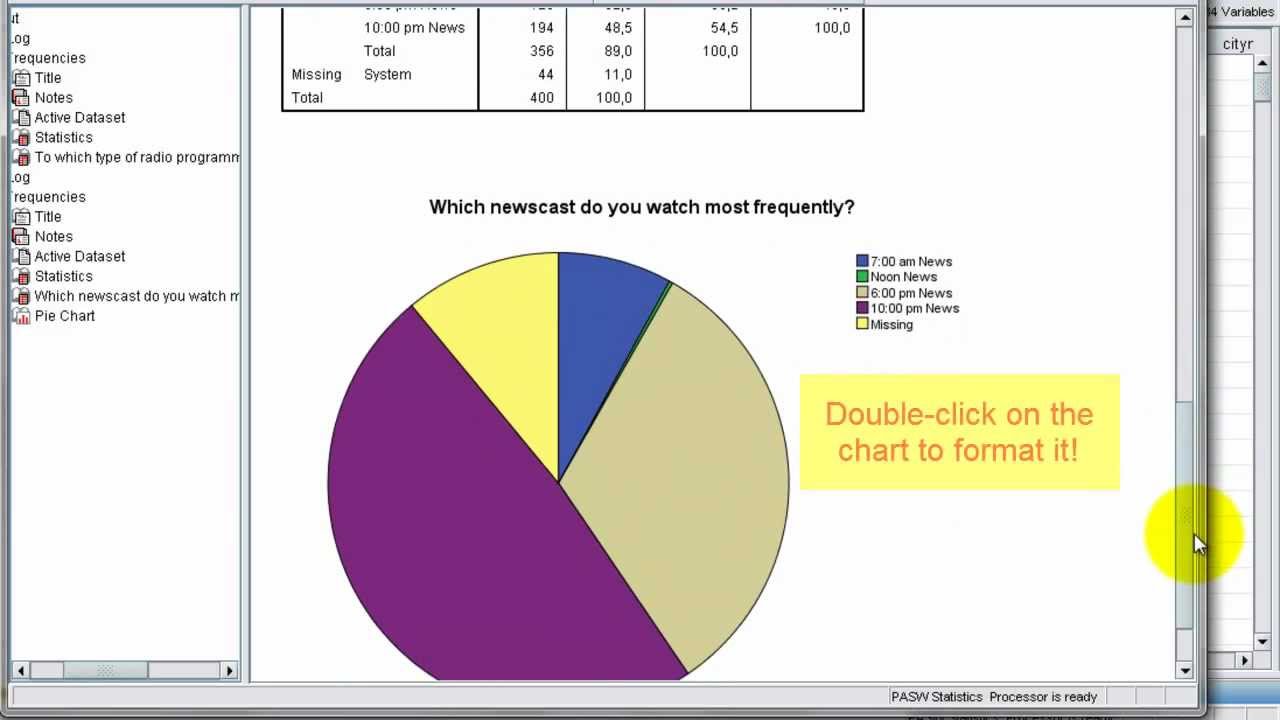
If you are working with survey data that has been probability-weighted, you must activate the weight before running any analysis. Data, Weight Cases, then select the weight variable. Forget this step, and your totals are wrong and there is no warning. I once ran a national election poll analysis without weighting and got percentages that implied three candidates had equal support when the raw data showed one candidate at fourteen percent. The weight variable was sitting in the dataset the entire time. Complex samples under the Analyze menu handle stratified and clustered designs. Standard SPSS procedures assume simple random sampling, and using them on cluster-sampled data produces standard errors that are too small. This means your confidence intervals are narrower than they should be, and your p-values are artificially significant. If your study design involves clusters or strata, use the Complex Samples module. The license cost is real, but a false positive result costs more in retractions.
Missing Data Handling
SPSS offers several ways to deal with missing data, and the defaults are not always what you want. The default behavior for most procedures is listwise deletion, meaning any case missing even one variable gets removed from the entire analysis. Pairwise deletion is available in some procedures like correlation, where SPSS uses all available data for each pair of variables separately. In practice, listwise deletion on a dataset with fifteen percent missingness across variables can drop your sample by forty to fifty percent depending on the pattern of missingness. A more practical approach for routine work is to check the Missing Values option under Analyze, Descriptive Statistics, Frequencies, before committing to any major analysis. This tells you how many cases are actually being excluded. If the number is high, you should consider multiple imputation through the Transform menu rather than deleting data wholesale. The Built-In Multiple Imputation feature creates five to ten complete datasets, runs your analysis on each, and pools the results using Rubin's rules. It is not perfect, but it is better than losing half your data.
Syntax and Automation
The Paste button next to every dialog box writes SPSS syntax. Most people never look at it, which is a mistake. Syntax is reproducible, editable, and it runs faster for repetitive tasks. If you find yourself clicking through the same procedure ten times with minor variations, write the syntax once and loop it. The syntax editor opens automatically when you paste a procedure, and you can save it as a .sps file for later reuse. One practical tip: always include the /MISSING and /FORMAT commands in your syntax blocks. /MISSING handles how missing values are treated during computation, and /FORMAT controls the display precision of your output. Small details, but they prevent hours of confusion when your output table shows eight decimal places for a mean that should be rounded to two.
Where SPSS Falls Short
SPSS struggles with anything beyond standard classical statistics. Machine learning algorithms are limited to basic decision trees and neural networks that rarely match what Python or R offer. Large datasets above roughly two million rows cause noticeable slowdowns in both processing and output rendering. The interface itself has not changed meaningfully in fifteen years, which makes navigation frustrating when you are already stressed about a deadline. For panel data analysis, SPSS requires extensive syntax manipulation that Stata handles more naturally. If your project involves time series forecasting, spatial analysis, or structural equation modeling beyond the basic AMOS add-on, you are better off in R or Python. SPSS is strongest for cross-sectional survey analysis, basic to intermediate inferential statistics, and environments where reproducibility through documented syntax matters more than algorithmic sophistication.
A Few Things I Wish I Knew Earlier
The Aggregation command under Transform is underutilized. It lets you collapse data by grouping variables and computing summary statistics, which is faster than running a pivot table after a crosstab. I used it to merge five thousand respondent-level records into five hundred neighborhood-level summaries in about forty seconds. Doing the same through manual recoding and grouping would have taken closer to twenty minutes of clicking. Output templates in SPSS are more useful than people give them credit for. You can set default font sizes, table styles, and label formats once, and every new analysis inherits them. This matters mostly for report consistency, but when you are producing dozens of tables for a journal submission, not having to adjust every single table manually is a real time saver. The template file lives in your SPSS install folder, and modifying it affects all future sessions. Finally, always save your work in .spv format for output and .sav for data, but keep a backup copy in .por or portable format. SPSS files corrupt occasionally, usually when the program crashes mid-save. Portable files survive that scenario, and the only trade-off is slightly longer load times on reimport. The trade-off is worth it.
Bottom Line on Workflow
A typical analysis pipeline in SPSS looks like this: import data, verify Variable View settings, run preliminary frequencies to check for coding errors, activate weights if needed, choose the appropriate procedure, review the output for unexpected missing value handling, and save both the data and output files with timestamps. This sequence takes about ten to fifteen minutes to set up for a standard analysis and reduces the chance of having to redo everything because a variable was mislabeled or a weight was not applied. The software does exactly what you tell it to do, and it rarely tells you when you have asked it to do something questionable. That silence is the main reason to develop good habits early rather than correcting mistakes after you have already submitted results.