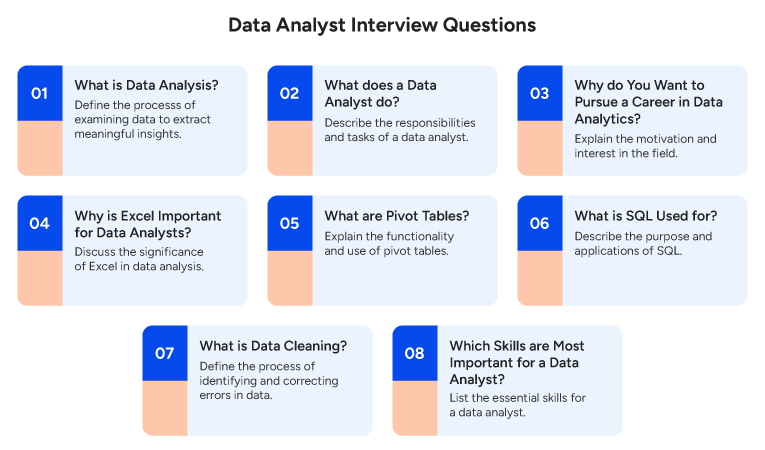
Preparing for data analysis interviews is less about memorizing answers and more about understanding what interviewers are actually probing for.
The questions themselves are often predictable. The trap is in how candidates respond to them. Most people give textbook answers that sound correct but reveal nothing about their actual problem-solving process. I've sat on both sides of these interviews, and the difference between a hire and a rejection usually comes down to whether the candidate can walk through their thinking out loud while handling follow-up questions that deliberately complicate the scenario. Let me break down what actually gets asked and how to approach each type, not by reciting perfect answers but by showing the kind of reasoning that separates competent analysts from people who just read a blog post before the interview. Statistical and probability questions come up early and often. You will get something like "what is the central limit theorem" or "explain p-value to a non-technical stakeholder." The first type tests whether you can articulate a concept without fumbling. The second type tests whether you can actually communicate, which is a daily job requirement that candidates routinely underestimate.
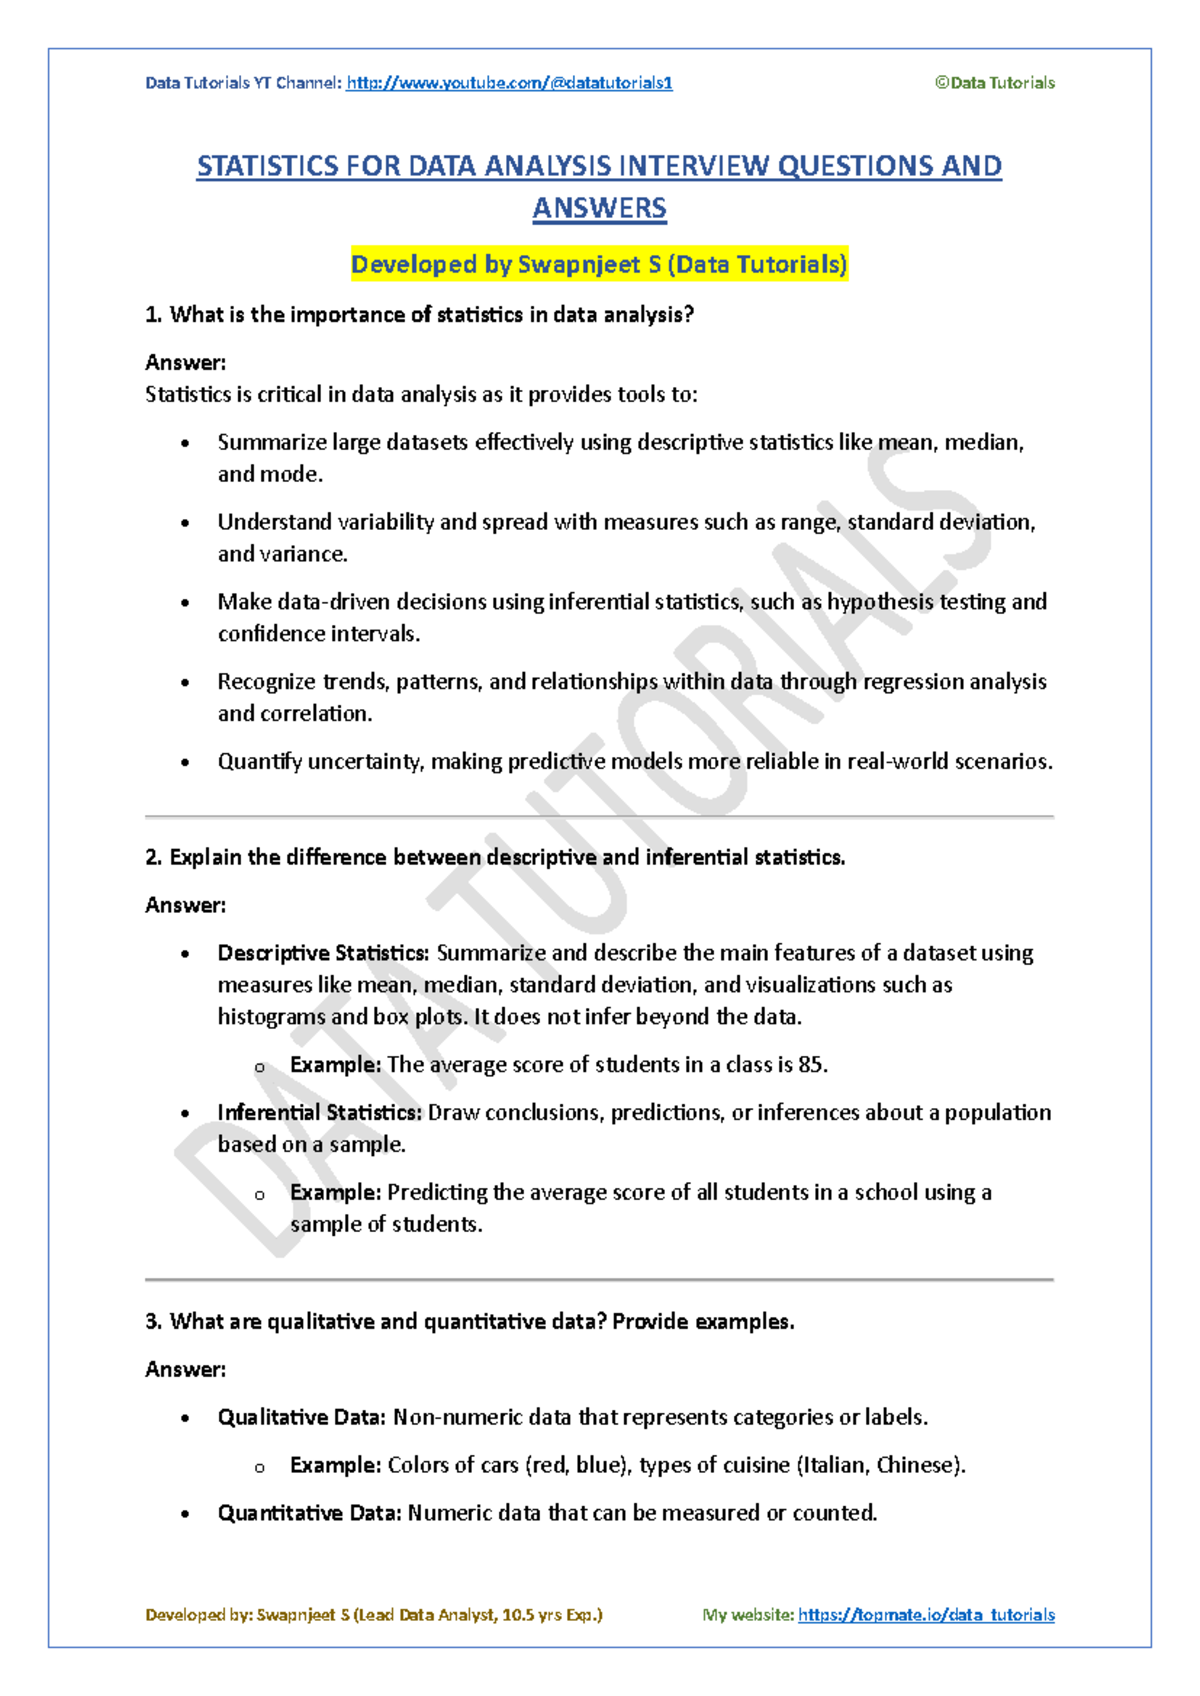
I remember a candidate once defining p-value as "the probability that the null hypothesis is true." That sounds fine on paper until you realize that is technically incorrect. A p-value measures the probability of observing results at least as extreme as what you got, assuming the null hypothesis is true. The candidate kept going with the wrong definition because they had memorized a simplified version from somewhere. When I pressed them on the distinction, they had no path forward. They failed the interview. For SQL questions, the pattern is consistent. You will get table schemas and asked to write queries. The basic ones test joins, aggregations, and filtering. The harder ones involve window functions, recursive CTEs, or handling edge cases like duplicate records. Most candidates can write a straightforward SELECT with a GROUP BY. Fewer can explain why they would use ROW_NUMBER versus RANK, or when a self-join makes more sense than a subquery. One edge case that catches people off guard: handling NULL values in joins. A standard inner join drops rows where either side is NULL. If someone asks you to count transactions per user and some users have NULL transaction IDs, an inner join silently excludes those users. A left join preserves them, but now you need to decide whether NULL transaction IDs mean "no transaction" or "missing data." The right answer depends on the business context, not just the SQL syntax. During an interview, pausing to ask that question before writing code is worth more than writing a perfect query for the wrong scenario.
Python and coding questions typically involve manipulating datasets using pandas or numpy. You might get asked to clean a messy dataset, handle missing values, merge multiple sources, and produce a summary statistic. The code itself is usually not the hardest part. The hardest part is knowing which operations to chain together efficiently and being able to explain trade-offs in your approach. For example, merging two large DataFrames with pandas can work fine with a simple merge, but if you are dealing with millions of rows, it can consume significant memory. In practice, I have seen analysts load data in chunks, use categorical dtypes to reduce memory footprint, or switch to polars or duckdb when performance becomes a bottleneck. Mentioning these considerations during an interview shows you have actually worked with data at scale, not just with clean tutorial datasets. Case study questions are where most candidates struggle because they do not have a fixed right answer. You will be given a business problem, like "revenue dropped 15 percent month over month. How would you investigate?" The expected response is not a single conclusion but a structured approach to diagnosing the problem.
Get the Full Details
A solid framework starts with clarifying the metric. Is revenue measured gross or net? Are we talking about a specific product, region, or customer segment? Then you break the problem into dimensions: traffic changes, conversion rate changes, average order value changes, seasonal effects, competitive moves, or internal changes like pricing or product availability. You prioritize which levers to examine first based on impact and data availability. After that, you formulate hypotheses and outline how you would test each one. I once gave a candidate a case where they immediately jumped to checking Google Analytics and pulling traffic numbers. I asked what they would do if the data was not available. They froze. The point of these questions is to demonstrate adaptability, not to follow a memorized script. In real projects, data is often incomplete, access is restricted, or the metrics are defined poorly. Showing you can think through those constraints matters more than reciting the ideal analysis plan. Product sense and business intuition questions are increasingly common. You might be asked to define success metrics for a new feature, estimate market size, or explain how you would measure the impact of a policy change. These questions do not test technical skill. They test whether you understand that analysis serves a business purpose.
A counter-intuitive point many beginners miss: sometimes the best analysis is the one you do not run. If a question lacks enough signal to produce a reliable answer, stating that clearly is more valuable than forcing a conclusion from weak data. I have seen analysts confidently present findings from underpowered experiments because they felt pressure to deliver an answer. Interviewers can usually tell when someone is overconfident in weak evidence, and it damages credibility more than admitting uncertainty would. Another thing worth noting about data analysis interviews: follow-up questions are deliberate. When an interviewer pushes back on your answer, they are not trying to humiliate you. They are simulating the kind of scrutiny you will face from stakeholders. Your reaction to pushback matters more than your initial answer. Defensiveness is a red flag. Engaging with the critique and adjusting your reasoning in real time demonstrates the exact skill they are hiring for. For practical preparation, working through real datasets matters more than reading answer lists. Use platforms like LeetCode for SQL, StrataScratch for mixed questions, and Kaggle for end-to-end projects. Write out your approach to case studies before the interview so you can articulate it smoothly. Practice explaining technical concepts to someone who does not understand statistics. Record yourself if you have to, because your delivery will feel different than you expect.
There is no shortcut that replaces doing the work. The candidates who perform best are the ones who have actually built analyses from scratch, encountered broken data, had to make decisions with incomplete information, and dealt with stakeholders who did not understand what the numbers meant. Interviews are rarely about knowing everything. They are about demonstrating that you know how to think through problems when you do not have all the answers.