The Reality of Working Through Data Analysis Steps
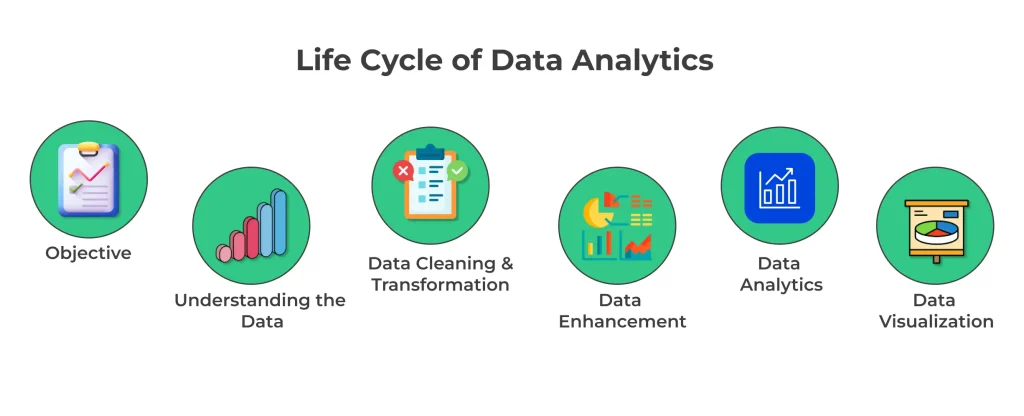
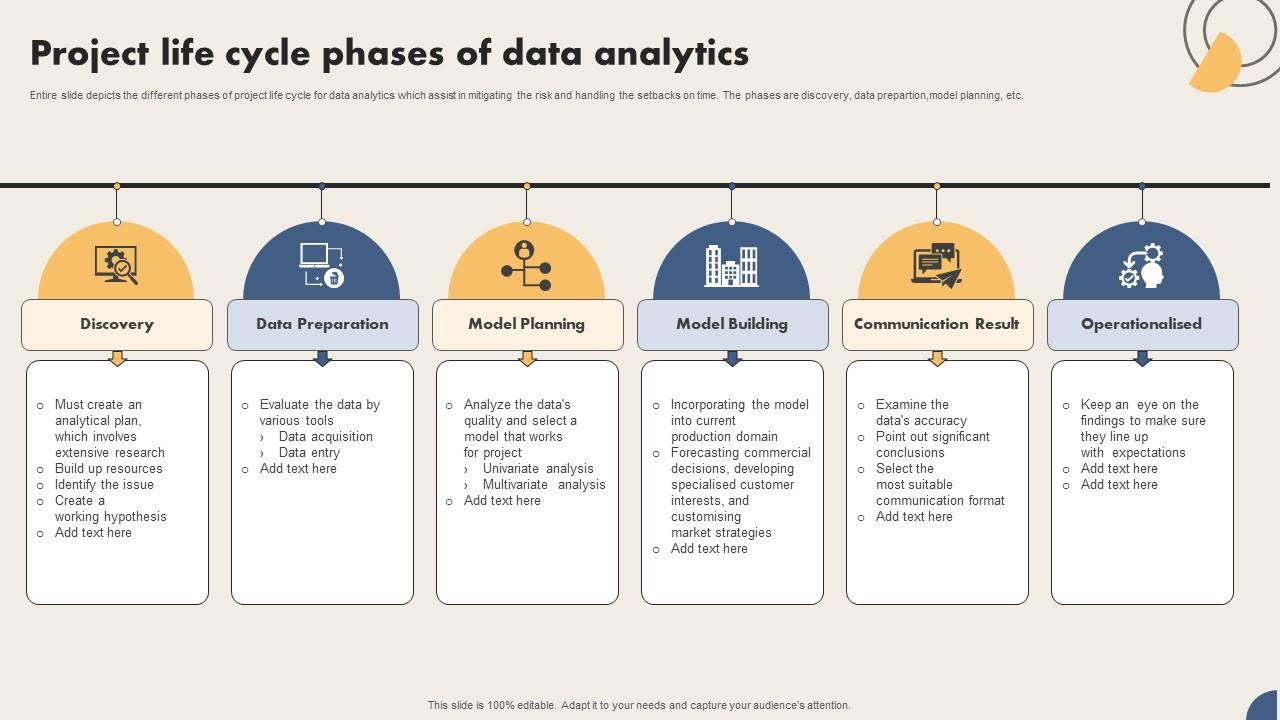
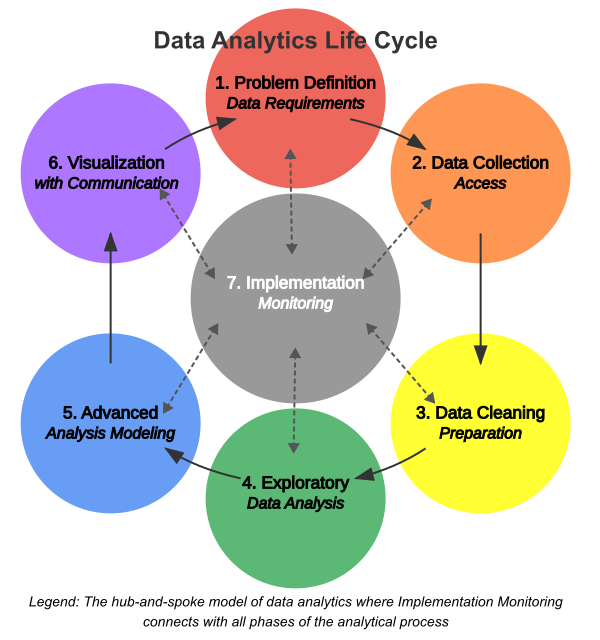
I've watched too many people treat the Data Analysis Life Cycle like a rigid checklist, which makes the whole thing miserable and slow. Here's what actually happens when you sit down to do this work properly. The cycle starts with problem framing, and this is where most projects quietly fail before they really begin. You need to nail down exactly what decision this analysis will inform. I worked on a project once where the stakeholder wanted "customer churn predictions." We spent three weeks building models only to discover they didn't actually have a clear action they'd take based on the output. The fix was going back to the original question and asking them what they would do differently if the model was 90% accurate versus 95% accurate. They couldn't answer that. It turned out they just wanted a dashboard. That changed the entire scope from a machine learning pipeline to a simple descriptive analysis that we completed in four days instead of twelve. Data collection follows, and the assumption that data just exists is one of the most common mistakes I see. Real data is scattered across three systems, two of which require manual extraction. I've pulled data from SQL databases, crawled internal APIs that had no documentation, and manually transcribed PDF reports when nothing else was available. A practical tip: before you write a single query, spend an afternoon mapping every possible data source. This usually saves two to three days of dead-end work later.
Data Cleaning Is Where Time Actually Goes
Most of the effort here sits in the cleaning phase. Raw data rarely behaves the way you expect. Duplicate records, inconsistent date formats, missing values encoded as zeros, and columns that change their data type between extracts are standard occurrences, not edge cases. I recently spent four days dealing with a dataset where the customer ID column had leading zeros removed by whoever exported it. That made duplicate customer records look like unique entries, and it inflated the analysis by roughly eighteen percent. There was no clean way to restore the zeros, so I had to join against a separate reference table that still had the properly formatted IDs. This kind of problem doesn't show up in any tutorial. When you handle missing values, don't default to mean imputation across the board. If a column has thirty percent missing entries and the missingness correlates with another variable, filling gaps with the mean introduces systematic bias. I've seen this skew results enough to flip a positive finding negative. The better approach depends on why the data is missing in the first place. If it's missing completely at random, deletion or mean imputation is fine. If it's missing for a reason related to the outcome, you need to model that relationship or flag those rows separately.
Exploration and Modeling Decisions
Exploratory analysis comes next, and people often treat it as a preliminary step they should rush through. Spending adequate time here directly reduces time spent debugging downstream. A proper EDA involves checking distributions, identifying outliers, testing correlations between features, and visualizing relationships before any modeling begins. The pattern recognition you develop here guides every subsequent decision. When you move into modeling or deeper analysis, keep in mind that the most statistically significant model is not necessarily the most useful one. I've built models with high accuracy scores that were worthless in production because the features weren't available at decision time. A churn prediction model requiring transaction data from the next billing cycle is circular. You have to think about temporal leakage during the feature engineering stage, not after the model is built. Feature selection is another area where beginners consistently overcomplicate things. Using a forward selection approach with cross-validation on your training set typically gives you a stable feature set without the noise that comes from throwing every available column into a model. I've found that starting with twenty well-chosen features and validating them through repeated holdout testing beats using two hundred features and hoping regularization handles it.
Get the Full Details
Validation and Communication
Validation is where you confirm your analysis actually answers the original question. Split your data appropriately. Training data for building the model, a validation set for tuning parameters, and a test set that you never touch until the final evaluation. Using the same data for training and testing inflates your performance metrics by fifteen to thirty percent depending on your dataset size, which makes your results look dramatically better than they actually are in practice. Communication is the part that people who focus only on the technical side neglect. The analysis itself doesn't matter if the people who need to act on it can't understand it. I've seen perfectly sound analysis rejected because the executive summary led with methodology instead of the actual recommendation. Start with the answer you want them to hear, then show the supporting evidence. A chart with a clear title and a one-sentence interpretation is more useful than a gallery of seventeen graphs with no narrative.
Where This Process Breaks Down
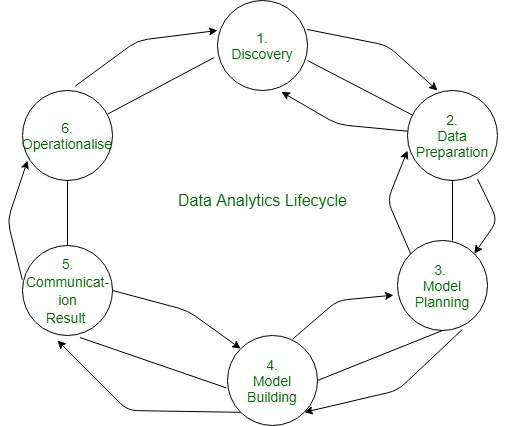
The Data Analysis Life Cycle assumes you have enough data to work with, enough time to iterate, and stakeholders who will actually use the results. None of those assumptions hold in a lot of real organizations. When you're working with a single year of data and the business operates on seasonal cycles, your model will capture noise as signal. When stakeholders treat analysis as a box to check rather than a decision support tool, they won't engage with the findings meaningfully regardless of how rigorous the process was. For small datasets where statistical power is limited, the framework still works but you need to adjust expectations. Confidence intervals will be wide. Predictions will be unreliable. In those situations, descriptive analysis and clear documentation of limitations provide more value than attempting complex predictive modeling. There's also the scenario where data simply doesn't exist for the question you need to answer. No amount of process discipline fixes that. You either collect the data first or you accept that the question can't be answered with what's available. The cycle repeats because nothing is ever finished. New data arrives, business conditions shift, and the original question often changes as you learn more. Treating this as linear instead of iterative is a recipe for building something that answers a question nobody cares about anymore.