What People Actually Put in These Things
A data analysis portfolio is just a collection of projects that prove you can handle real data without breaking things. The common format is a GitHub repo with a README, cleaned datasets, and a Jupyter notebook or Python script showing your work. Some people host dashboards on Streamlit or Tableau Public instead. Both work, but they solve different problems for different audiences. I spent about four years reviewing portfolios for hiring teams and then eventually managing a small analytics team. Most submissions are fine. A solid portion is either unfinished work disguised as polished or copy-pasted tutorials with zero personal context. You do not need fancy visualizations. You need evidence that you can take a messy question, wrestle it into something usable, and explain what the numbers actually mean.
Where to Find Data Analysis Portfolio Examples
If you are looking at existing work before building your own, Kaggle Datasets, GitHub Explore, and the datasets section on StrataScratch are reasonable starting points. Don't just browse the top results, though. The trending projects there are usually someone's homework or a competition entry with an oversimplified approach. Better to dig into repositories with actual issue trackers and pull request history, since that shows iterative, collaborative work rather than a single polished export. I keep a folder of about twelve projects I reference when I tell people what good looks like. They tend to share a few traits: the dataset has missing values and inconsistent formatting, the notebook walks through the decisions made during cleaning, and the final section explains what the analysis would not tell you, which is usually the most useful part.
How to Build Something That Actually Works
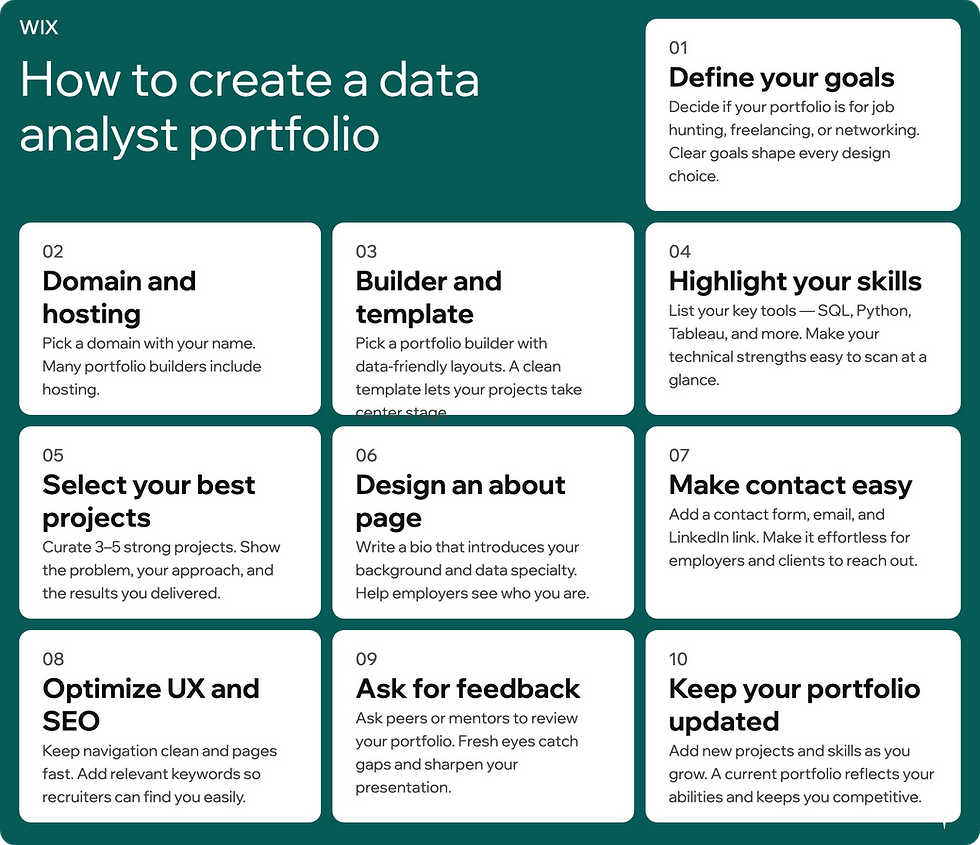
Start with a project where the data is imperfect. A clean CSV from a tutorial does not prove anything. Pick something that requires merging multiple sources, handling timestamps, and dealing with at least one ambiguous field. Then document everything, including the parts you are unsure about. Here is the basic structure I see repeated in projects that get noticed: First, state the question clearly. Not the business problem, but the specific analytical question. "What drives churn in month two?" is better than "Let's explore churn." Second, describe the raw data in two or three sentences: size, source, known issues. Third, show the cleaning pipeline. This is where most people skip ahead, which is a mistake. Fourth, run the analysis. Fifth, interpret the results with caveats. Sixth, link to the code.
Get the Full Details
The cleaning section matters more than the analysis section. Recruiters and hiring managers spend more time looking at how you handled messy data than on whether you used the right statistical test. I once saw a candidate who spent two full paragraphs on outlier removal and another two on date parsing. They ended up with a simple correlation, but the notebook was still hired because the methodology was transparent and defensible. When I built my own portfolio projects, I focused on tools I actually use. Python with pandas and SQL for cleaning, either seaborn or plotly for visualization, and a straightforward README. R or a full-stack deployment is fine if that is what you work with daily. Don't include five different languages just to check boxes. It looks like you are padding the list. One thing that catches people off guard is the README. It should not be a novel. Three paragraphs max: what the project is, what the data looked like before cleaning, and what the key finding was. If you include a screenshot of a dashboard, make sure it is accurate. A blurry Tableau image with axis labels cut off adds zero value and makes you look careless.
I recently reviewed a portfolio where the candidate had a project on retail sales forecasting using a public Walmart dataset. The model was solid, but the README didn't mention that they had excluded three regions due to incomplete data. When I asked about it in the screening call, they admitted they hadn't realized that omission mattered. Projects like that don't fail the portfolio review, but they do raise a yellow flag. Always note what you left out and why. For hosting, GitHub is still the default. Tableau Public works if you are focusing on visualization-heavy work. There are a few people who host on personal domains, but unless you have done something unusual with the project, it just looks like you are trying too hard. A clean URL and a descriptive repo name are enough.
Common Mistakes That Make Portfolios Look Amateur
I see the same errors across hundreds of submissions. Here are the ones that actually cost people interviews. Inconsistent file naming is a minor thing that adds up fast. "final_v2_revised_clean.csv" says you didn't version control your workflow. Use a simple system like project_name_data_raw, project_name_data_clean, project_name_notebook.ipynb. It takes thirty seconds and signals organization. Over-analyzing is another big one. Running twenty models on a small dataset and presenting them all looks like you don't know which one matters. Pick one or two approaches, justify them, and move on. Depth beats breadth every time in these reviews.
Then there's the lack of a narrative. A portfolio is not a dump of completed tasks. It is a story about how you think. The README is where that story lives. If I open a repo and can't tell within thirty seconds what you did and why, I close it. That is honest, and it happens more often than you might think. A specific edge case I ran into myself involved a project where the timestamps were in two different formats across files: some were ISO 8601 strings, others were Unix epoch seconds, and a few were just dates without times. I spent about an hour writing a parsing function that handled all three, validated against a small manually labeled sample, and logged the mismatches so I could flag them later. I included that function and a short note about why the mixed formats existed in the README. That kind of detail is what separates a portfolio from a tutorial walkthrough.
What Employers Actually Look For
Most hiring managers and technical leads scan portfolios in about ninety seconds. They are not reading every line of code. They are checking three things: Can this person handle real data? Can they explain their process? Do they seem curious enough to investigate further? The first check is usually the data quality section. If your cleaning is thorough and your assumptions are stated, you pass that gate. The second check is the interpretation. I don't need a thesis, but I do need to see that you understand causation versus correlation and that you can phrase limitations honestly. The third check is harder to gauge from a static portfolio. It shows up when your project raises a follow-up question that makes me want to dig deeper into your GitHub profile or contact you directly. SQL skills matter a lot more than people admit. A project that includes a well-structured SQL query for data extraction, even if the main analysis is in Python, stands out. Most beginners skip SQL entirely and rely on pandas alone. That isn't wrong, but it limits how you demonstrate your range. A single well-commented SQL query in the repo goes a long way.
Visualization quality is another mixed signal. Pretty charts are nice, but they are not the point. Clarity is. A poorly designed but accurate chart is better than a gorgeous one that misrepresents the data. I have seen people use 3D pie charts and stacked bar graphs that obscure the actual distribution. Don't do that. Stick to simple bar charts, line plots, and scatter plots unless the data genuinely demands something more complex.

How to Improve What You Already Have
If your current portfolio feels thin, the fastest fix is to revisit your oldest projects and add what is missing. A README with limitations, a data quality section, and a clear question usually turns an average project into a credible one. Don't rebuild everything from scratch. Add context to what exists. If you need new projects, pick a domain you have some familiarity with. Healthcare, finance, e-commerce, logistics, or marketing are all reasonable. The industry doesn't matter as much as the quality of the analysis. A mediocre healthcare project is still mediocre. A strong retail project can be just as compelling. One more thing about scope. A single well-executed project is worth more than three half-finished ones. I would rather see a complete, thoughtful analysis of a moderately difficult dataset than three repos that trail off mid-analysis because you lost interest. Finishing matters.
And if you want to stay current with how other people structure theirs, search for Data Analysis Portfolio Examples and filter by recent updates. The conversation around what counts as a strong portfolio shifts every year or two, and the older examples tend to show practices that are no longer recommended.


