
What the role actually looks like day to day
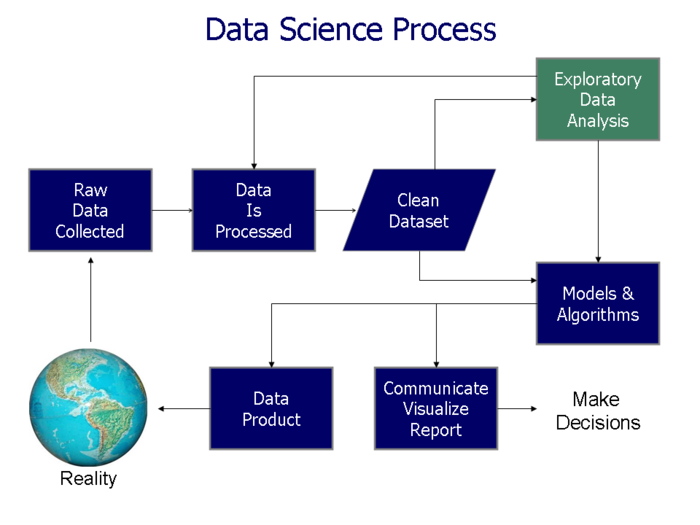
A Data Analysis Product Manager sits between the people asking for numbers and the people who actually build the pipelines to deliver them. Most job postings make it sound like a straightforward bridge role. It isn't. The friction comes from everyone assuming the other side already understands their constraints. Engineers think you're going to ask for impossible dashboards. Business stakeholders think you're going to hand them a magic box that turns raw logs into quarterly strategy. You're not either of those things. You're the person who translates business ambiguity into something a data team can ship, and then figures out why the shipped thing isn't being used. The core loop is pretty mechanical once you stop overthinking it. You take a business question, figure out what data would actually answer it, decide whether that data exists or needs to be built, and then track whether the output is changing behavior. That's it. The complexity shows up in the edges. Most of your time ends up spent on three things: scoping requests so they don't blow up your team's sprint, defining success metrics that aren't vanity numbers, and explaining to leadership why "just one more column" adds two weeks to delivery. The scoping part is where most people fail early. A request like "we need to understand churn drivers" is not a project. It's a conversation starter. You need to push back until someone says "I need to know X by Thursday so I can do Y." That's when you have something to work with.
On the metric side, the trap is optimizing for accuracy over actionability. A model that predicts churn with 94% accuracy but can't be explained to a sales manager is worse than a simple rule-based dashboard at 72% accuracy that someone actually uses. I've seen entire product cycles wasted on this. The fix is to define the decision first, then work backward to the data required. What decision does this metric enable? If you can't answer that in one sentence, you don't have a metric, you have a statistic.
Tools and infrastructure you actually need
There's no single tool called "Data Analysis Product Manager." It's a role that sits on top of a stack. Here's the practical version of what that stack looks like and where people commonly mess it up. For querying and prototyping, SQL is non-negotiable. You don't need to be an optimization engineer, but you should be able to write a join without panicking. If you can't read your own warehouse queries, you're going to become entirely dependent on engineers for every sanity check, and that relationship degrades fast. dbt is the standard for transforming raw tables into something usable. Learn the materialized vs. view distinction and when to use each. It matters more for your sprint planning than people realize. Dashboards live in Tableau, Looker, or Metabase depending on your org. The mistake here is letting dashboard tools drive the data model. They shouldn't. The data model is the product. Dashboards are the packaging. I once spent six weeks debugging a dashboard that showed revenue dropping 40% quarter over quarter. The data was fine. The dashboard was filtering out refunds that had been automatically processed in the new ERP system. Six weeks. It took me one afternoon to write a raw SQL query that bypassed the dashboard layer and confirmed the actual numbers were correct. Always verify at the source before trusting a visual. Especially when leadership is watching.
Get the Full Details

For pipeline orchestration, Airflow or Prefect are the common choices. You don't need to be the one writing the DAGs, but you need to understand what a downstream dependency failure looks like and how to communicate it when it breaks a stakeholder's Monday morning report. That's a different skill from fixing it. Version control for your analytics code is Git. If your team doesn't have PR reviews on SQL transformations, you're operating on borrowed time. I've seen a GROUP BY change get merged without review that silently dropped three segments from a reporting table. No alerts fired. No one noticed for eleven days. That's the cost of skipping version control discipline.
How to scope a data analysis project without derailing it
The framework I use is blunt and it's not elegant. Before any work starts, I require three things in writing: the decision the analysis will inform, the consequence of being wrong, and the deadline. Not the date the report is due. The date the decision needs to happen. These are often different. If someone says "we need a churn analysis," I push until I get this: the product lead needs to decide whether to extend the free trial from 14 days to 21 days by the end of Q2. The consequence of being wrong is either losing $200K in projected retention or spending engineering time on a trial extension that won't move the needle. The deadline for the analysis is two weeks before Q2 ends to allow for a pilot. Now I have a bounded problem. Everything else is noise. Then I map the data. What tables contain the signals? How fresh do they need to be? Can I get an answer from existing pipelines, or does this require a new extraction? If it requires new extraction, the timeline doubles. That's a hard rule I learned the hard way. A request that looked like a three-day query turned into a three-week project because the event schema had changed six months prior and nobody had updated the documentation.
Here's the counter-intuitive part that nobody teaches: the best data analysis projects are often the ones that get scoped down, not up. A narrowly defined question answered well beats a broad question answered adequately. "Did the pricing page change increase conversion for mobile users in the 18-24 demographic?" is a better project than "understand our conversion funnel." The narrow version can be answered in a week. The broad version becomes a portfolio piece that nobody reads. One more thing about scope. Stakeholders will always add "and while you're at it" requests. This is not a negotiation. It's a boundary enforcement exercise. Every added request either moves the original decision forward or it's a separate project. There is no third option. I keep a public backlog and track every request. When someone asks for something extra, I don't say no. I say "that's item forty-seven on the backlog. Do you want to reorder the queue, or shall we schedule it for next quarter?" Making it visible and structured removes the emotional component. It also means you have a paper trail when someone claims you "never got around to it."
Measuring whether your analysis product is actually working
This is the part most roles skip. You ship a dashboard or a report or a model. Then what? If you're not tracking adoption, you're just making art. The metrics that matter aren't about the data quality. They're about whether the output changed a decision. I track three things: how often the asset is opened or queried, whether the people using it are the right people, and whether any documented decision references it. The first two come from dashboard analytics or query logs. The third requires actual conversation. I set up a monthly check-in with the top three stakeholders for each major asset and ask one question: "Did this change what you did last month?" Not "did you like it." "Did it change your behavior." If the answer is no for two consecutive months, the asset gets sunset or radically redesigned. Sentiment doesn't pay for infrastructure. There's a specific edge case here that catches people. Sometimes the right answer is that your analysis product should never be used directly. If you've built a good predictive model for demand forecasting, the operations team shouldn't be looking at its outputs daily. They should be using the automated reorder recommendations that the model feeds into. The model's success metric is the reduction in stockouts, not how many people click on it. Don't confuse usage with impact. A model that runs silently and prevents $500K in lost inventory is more valuable than a dashboard that gets 200 weekly views and changes nothing.
Common failure modes and how to avoid them
The biggest failure mode is building something technically correct that answers a question nobody cares about. This happens when you prioritize data completeness over decision relevance. I once built a comprehensive customer segmentation model. It was statistically sound. The engagement was zero. The problem wasn't the model. The marketing team had already moved to a different framework and the segments didn't map to anything in their campaign tool. Two months of work. I should have spent two weeks talking to the team that would actually use it instead of diving into the data immediately. Another failure mode is the false precision problem. Reporting a number to four decimal places when the underlying data has a 15% margin of error creates a false sense of confidence. I've seen leadership make hiring decisions based on attribution models that were essentially fancy guesses dressed up in percentages. The fix is to attach confidence intervals or at least directional language. "Likely higher" is more honest and more useful than "12.7% increase" when your sample size is three hundred and your data source is self-reported. Data lineage breakdown is a third one. It sounds boring until a regulatory audit asks where a specific number came from and nobody can trace it past the second transformation layer. This is preventable with dbt's documentation generation or a simple metadata table that logs source-to-target mappings. Do this before you need it. I learned this after a compliance question stalled a product launch for three weeks because we couldn't prove where our revenue attribution numbers originated. The workaround was manually reconstructing the lineage from git history and Slack messages. It took four people ten hours. A proper metadata system takes two hours to set up once.
When to build versus when to use off-the-shelf
This is where the role gets genuinely difficult. You'll be asked to build custom analytics solutions for problems that already have commercial answers. The temptation is to prove your value by building things. It's a trap. Every custom pipeline you maintain is a tax on your team's capacity that compounds over time. The rule I use is simple: if a tool like Hex, Mode, or even a well-structured Looker block can solve it in under two days, don't build custom. The exception is when your data architecture is unique enough that off-the-shelf tools can't access it, or when the analysis requires proprietary logic that can't be expressed in standard BI platforms. Even then, start with the tool and build only what the tool can't do. Don't reverse that order because it feels more impressive. There's also the internal tool problem. You'll build a dashboard or a script that solves one team's problem. Six months later, three other teams are asking if they can use it. Then six more. Before you know it, you're maintaining a fragile constellation of custom solutions that nobody fully understands. The mitigation is to design for reuse from day one, even if reuse seems unlikely. Naming conventions, documented schemas, and a public catalog of available assets reduce the support burden dramatically. I maintain a simple internal wiki that lists every analytics product my team has shipped, its purpose, its owner, and its current health status. It takes maybe twenty minutes to update weekly and it cuts my ad-hoc request volume by roughly half because people can find existing solutions instead of asking for new ones.

What matters most in this role
It's not the tools. It's not the SQL speed. It's the ability to say "here's what we can answer with confidence, here's what we can't, and here's what would change that." People respect that because it's honest and it saves everyone time. The Data Analysis Product Manager who ships fast but ships wrong is remembered for the wrong shipment. The one who slows things down to get the scope right is initially frustrating and eventually indispensable. The technical skills are learnable. The judgment comes from seeing enough projects fail for the wrong reasons to develop a feel for the right ones. My advice is to volunteer for the ugly projects first. The ones with bad data, unclear questions, and stakeholders who don't trust each other. Those teach you more in three months than five clean dashboard builds.


