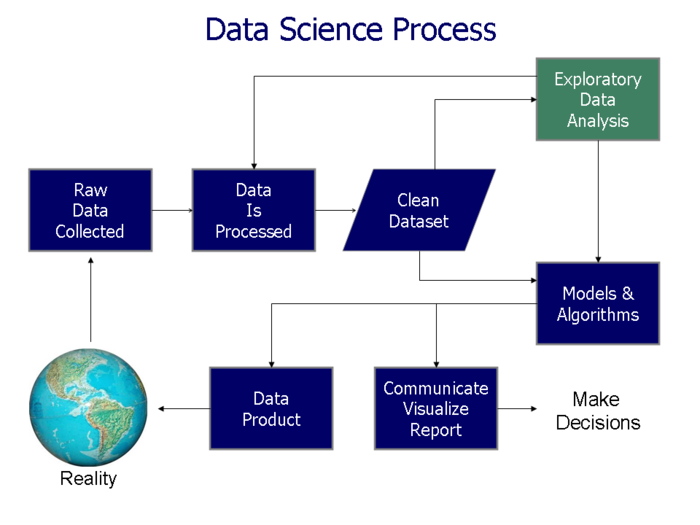
Getting a Data Analysis Project Python working properly
Most people think setting up a data analysis project in Python is about installing packages. It's not. It's about building a structure that won't fall apart when the dataset grows past 500MB and your Jupyter notebook starts segfaulting from memory pressure. I've watched people spend three weeks debugging import cycles and relative path hell because they never bothered to organize their work into a proper project layout from day one. The first thing I do before touching any data is create a virtual environment. Not optional. Using your system Python for data analysis is asking for dependency conflicts between projects, and you will regret it when a coworker's project requires pandas 2.1 and yours still needs 1.5. Run python -m venv venv, activate it, and install exactly what you need. Don't install the entire scientific Python stack at once. pandas, numpy, matplotlib, and openpyxl are enough for most initial work. Add things as you discover you need them.
Data Analysis Project Python Structure That Doesn't Collapse Under Its Own Weight
Here's a folder layout that has survived actual production work for years without needing reconstruction: project_root/ data/ raw/ processed/ external/ notebooks/ src/ __init__.py loader.py pipeline.py visualisation.py requirements.txt README.md .gitignore The separate data directories matter more than people realise. When you run the same cleaning script five times and each version overwrites the original, you lose traceability instantly. Keep raw data read-only. Put cleaned outputs in processed. Downloaded third-party datasets go in external. This prevents accidental mutation of source material, which is how bugs enter projects and stay hidden for weeks.
Everything that reads or writes files should live in src/. Notebooks are for exploration, not production code. I know this is heresy in some circles, but I have a specific story about why this distinction matters. Last year I inherited a notebook that was 800 lines long and had hardcoded file paths like /home/user/datasets/final_output_v7_cleaned.csv scattered across seven different cells. The data source had moved, the column names had changed, and the person who wrote it was gone. I spent two days reconstructing the pipeline from the notebook alone. I could barely tell which imports were used and which were dead code from an earlier experiment. After that, I put every reusable function in src/ and kept notebooks strictly for interactive analysis. It cut my debugging time on future projects from hours to minutes. One thing beginners consistently get wrong is the relationship between pandas and Dask. Pandas loads everything into memory, which is fine until it isn't. When I hit a CSV that was 4.2GB and my machine has 8GB of RAM, the notebook kernel dies during the read step. You don't need to switch to Spark or a database. Dask DataFrame mimics the pandas API closely enough that porting code takes maybe thirty minutes. The bottleneck with Dask is shuffle operations, so if your analysis involves heavy groupby joins across large datasets, Dask gets slow fast. For moderate-sized data that just happens to be bigger than comfortable, it's a solid stopgap. Another thing nobody tells you about Python data analysis: NaN handling is where projects quietly die. pandas represents missing values in multiple incompatible ways depending on dtype. A float column uses numpy.nan, an object column uses None, and a string column (the new pyarrow-backed string dtype) uses pd.NA. These don't compare equal to each other. Write a conditional that checks for missingness without being explicit about dtypes and you will encounter edge cases where the condition evaluates differently on identical-looking data. The workaround I use now is a helper function that runs at the top of every pipeline:
Get the Full Details

def clean_nulls(df): for col in df.columns: df[col] = df[col].replace([np.inf, -np.inf], pd.NA) return df Run this immediately after loading, before any calculations. It catches the infinity values that sneek in during division operations and normalises the null representation across the entire frame. Without it, aggregate functions behave inconsistently and you waste time wondering why your mean is wrong. For reproducibility, pin your dependencies in requirements.txt with exact versions. Use pip freeze > requirements.txt after you've tested the full pipeline end-to-end. Don't commit it earlier, because you'll iterate and the snapshot will be stale. A .gitignore should exclude the venv directory, __pycache__, and any data files larger than 10MB. I learned that last one the hard way when I accidentally committed a 2GB parquet file to git and the repository became unusable for anyone cloning it.
Visualisation code belongs in src/ too, not buried in notebooks. Matplotlib and seaborn are stateful in confusing ways. When you call plt.figure() inside a loop in a notebook cell, the state bleeds into the next cell. Put your plotting logic in functions that take explicit figure and axis arguments. It makes testing trivial and prevents charts from stacking on top of each other unexpectedly. If your analysis involves repeated transformations across multiple datasets, look into pandas' eval method or Polars. Polars is a Rust-backed dataframe library that gives you concurrent execution for free on multi-core machines. A groupby operation that takes 45 seconds in pandas often completes in under 8 seconds in Polars on the same dataset. The tradeoff is that Polars doesn't support every edge case that pandas does, particularly around mixed dtypes in single columns and certain timezone-naive operations. But for clean tabular data, it's worth the learning curve. The hardest part of any Data Analysis Project Python is deciding when to stop building infrastructure and start actually analyzing the data. There's a threshold where you spend more time architecting the perfect pipeline than you would have spent manually doing a quick dirty analysis. For small projects under a few hundred rows, a single Jupyter notebook is fine. Don't over-engineer everything. But once the work grows beyond personal use or the data volume threatens to break your setup, the structure I've described becomes necessary rather than optional.