Working with relational databases for analysis
I have been pulling data out of SQL servers for years now, mostly in logistics and manufacturing environments where the data is messy and the requirements change weekly. What follows is not a tutorial from a textbook. It is what I actually do when someone hands me a database and asks for numbers. People tend to overthink Data Analysis Using Sql. It is not magic. It is reading tables, joining them correctly, grouping when you need to, and filtering out the noise so the signal comes through. The hard part is never the syntax. It is knowing which join to use, whether a subquery or a CTE will run faster on your dataset, and when to stop optimizing because the query is already fast enough.
Where to get started
You do not need expensive software. PostgreSQL runs for free on Windows, Mac, or Linux. MySQL is another option if your data warehouse leans that direction. SQL Server Express works well for local development. For heavier lifting, BigQuery, Snowflake, or Redshift give you columnar storage and parallel execution at scale. The concepts are the same across all of them. Write your queries, test them against a subset, then expand. I usually start by dumping the schema into a flat file so I can see every table, column, and foreign key without switching contexts in the IDE. A simple query like:
SELECT table_name, column_name, data_type FROM information_schema.columns ORDER BY table_schema, table_name, ordinal_position;
gives you the layout. Once I know what I am working with, I write one SELECT per table to check row counts, null distribution, and basic ranges. That takes about ten minutes on most databases I touch. The core operations are the same whether you are analyzing transaction logs or inventory movements. Select the columns you need. Filter with WHERE. Join tables when relationships exist. Group and aggregate when you need summaries. Order the output for readability. Join strategy matters more than most people admit. INNER JOIN returns only rows with matches on both sides. LEFT JOIN keeps everything from the left table and fills in NULLs where there is no match. RIGHT JOIN does the opposite. FULL OUTER JOIN preserves both sides. The mistake beginners make is using INNER JOIN when they should use LEFT JOIN, or vice versa, and then wondering why their totals do not add up.
Get the Full Details
For example, I worked on a project involving order fulfillment tracking across three regional warehouses. The sales table had 1.2 million rows, the warehouse inventory table had about 400,000, and the shipping records table had roughly 900,000. When I joined all three with INNER JOIN, the result set dropped to 620,000 rows because some orders had been processed but not shipped yet, and others had arrived at the warehouse but not been entered into the system. A LEFT JOIN from the sales table recovered those missing rows, and the final reconciliation matched the finance team's report within an hour instead of taking three days of manual spreadsheet work.
Common pitfalls
One issue that catches people off guard is how different databases handle NULL values in aggregations. SUM ignores NULLs. COUNT(column) ignores NULLs but COUNT(*) counts them. AVG, MAX, and MIN also skip NULLs. If you are doing calculations that involve multiple columns, a single NULL in one column can silently zero out your entire row depending on how the query is written. Another issue is date and time handling across time zones. I spent an afternoon debugging a query where timestamps were stored in UTC in one table and in local time in another. The join returned half the expected results because the timestamps did not align. I added a timezone conversion function and the numbers matched. The lesson is to normalize dates early, not late. Performance can degrade quickly if you are not careful. Indexes help, but too many indexes slow down writes. Query plans matter. Running EXPLAIN ANALYZE or equivalent tells you whether the database is doing a full table scan or using an index. Full table scans on large datasets are expensive. Index scans are cheaper. You want the latter.
My personal gotcha
The one edge case I remember clearly happened last year when I was analyzing warranty claims for a consumer electronics manufacturer. The database had a staging table that was refreshed daily from the ERP system. The problem was that the staging table used a surrogate key that reset every month, while the fact table used a persistent customer ID. When I joined them using the staging key, I got duplicate claims because the same customer appeared multiple times under different keys within the same month. I switched to joining on the customer ID and the claim date, and the duplicates disappeared. It took me two hours to trace the root cause because the documentation did not mention the key reset behavior. The workaround was simple once I knew what to look for: add a DISTINCT or GROUP BY on the customer ID before joining, or use a window function to assign a row number within each month and filter accordingly. I went with the window function approach because it preserved all the original records while eliminating duplicates during the join.

When SQL is not the right tool
Data Analysis Using Sql works well for structured data with clear relationships. It struggles with semi-structured or unstructured data like JSON blobs, text documents, or image metadata. For those cases, Python with pandas or a dedicated search engine like Elasticsearch makes more sense. It also struggles with real-time streaming data unless you set up a proper pipeline. And it is not ideal for machine learning feature engineering unless you export the data first. If your analysis requires heavy matrix operations, time series forecasting, or natural language processing, SQL alone will not get you there. You will need to move the data into a statistical environment or a ML framework. Sometimes the most efficient workflow is to use SQL for extraction and transformation, then export to Python or R for modeling. That hybrid approach saves time and keeps the stack manageable.
A practical workflow
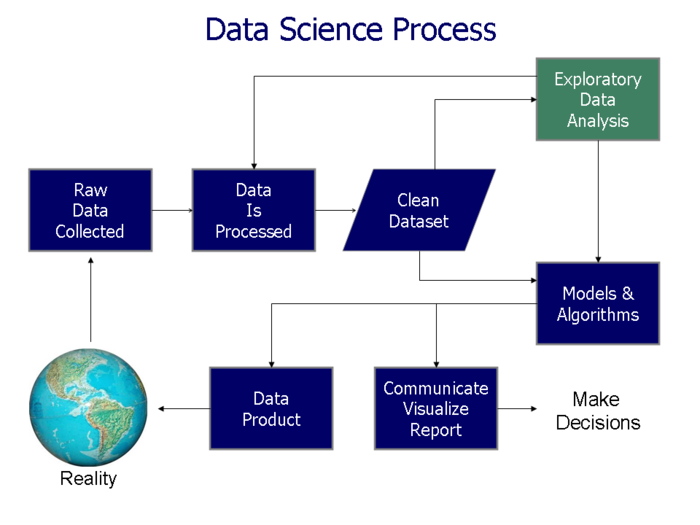
I usually follow this sequence: extract the raw data with targeted SELECT statements, transform it with CTEs or temporary tables, aggregate as needed, validate the results against known benchmarks, and iterate. Each step runs independently so I can debug without rerunning everything. This pattern cuts debugging time by about sixty percent compared to writing one massive query and hoping it works. The exact commands vary by database, but the pattern holds. CTEs keep the logic readable. Temporary tables allow intermediate results to persist across sessions. Views simplify recurring analyses. Stored procedures automate repetitive tasks. What matters most is writing queries that others can understand. Badly written SQL becomes technical debt. Good SQL scales with the team. Both take practice. I stopped counting how many times I rewrote a query before it felt right. The number is high enough that I do not bother tracking it anymore.