Setting Up Your Environment
Kibana doesn't do much without Elasticsearch running first. You need both on the same network, and they should match version numbers or you will spend two days chasing compatibility errors. The official packages from Elastic are the safest route. Docker works fine for local testing, but production deployments usually stick with native installs on RHEL or Ubuntu. Once Elasticsearch is healthy and listening on port 9200, you point Kibana at it in the kibana.yml file. The default settings work for 80 percent of setups. I recommend disabling the initial demo index creation if you are working with real data. Those sample datasets clutter your workspace and confuse new users about what is actually useful. The installation itself takes about ten minutes on a reasonable machine. Just make sure Java is set to version 17 or 21 depending on your stack, and that your JVM heap is configured properly before you start.
The Actual Workflow
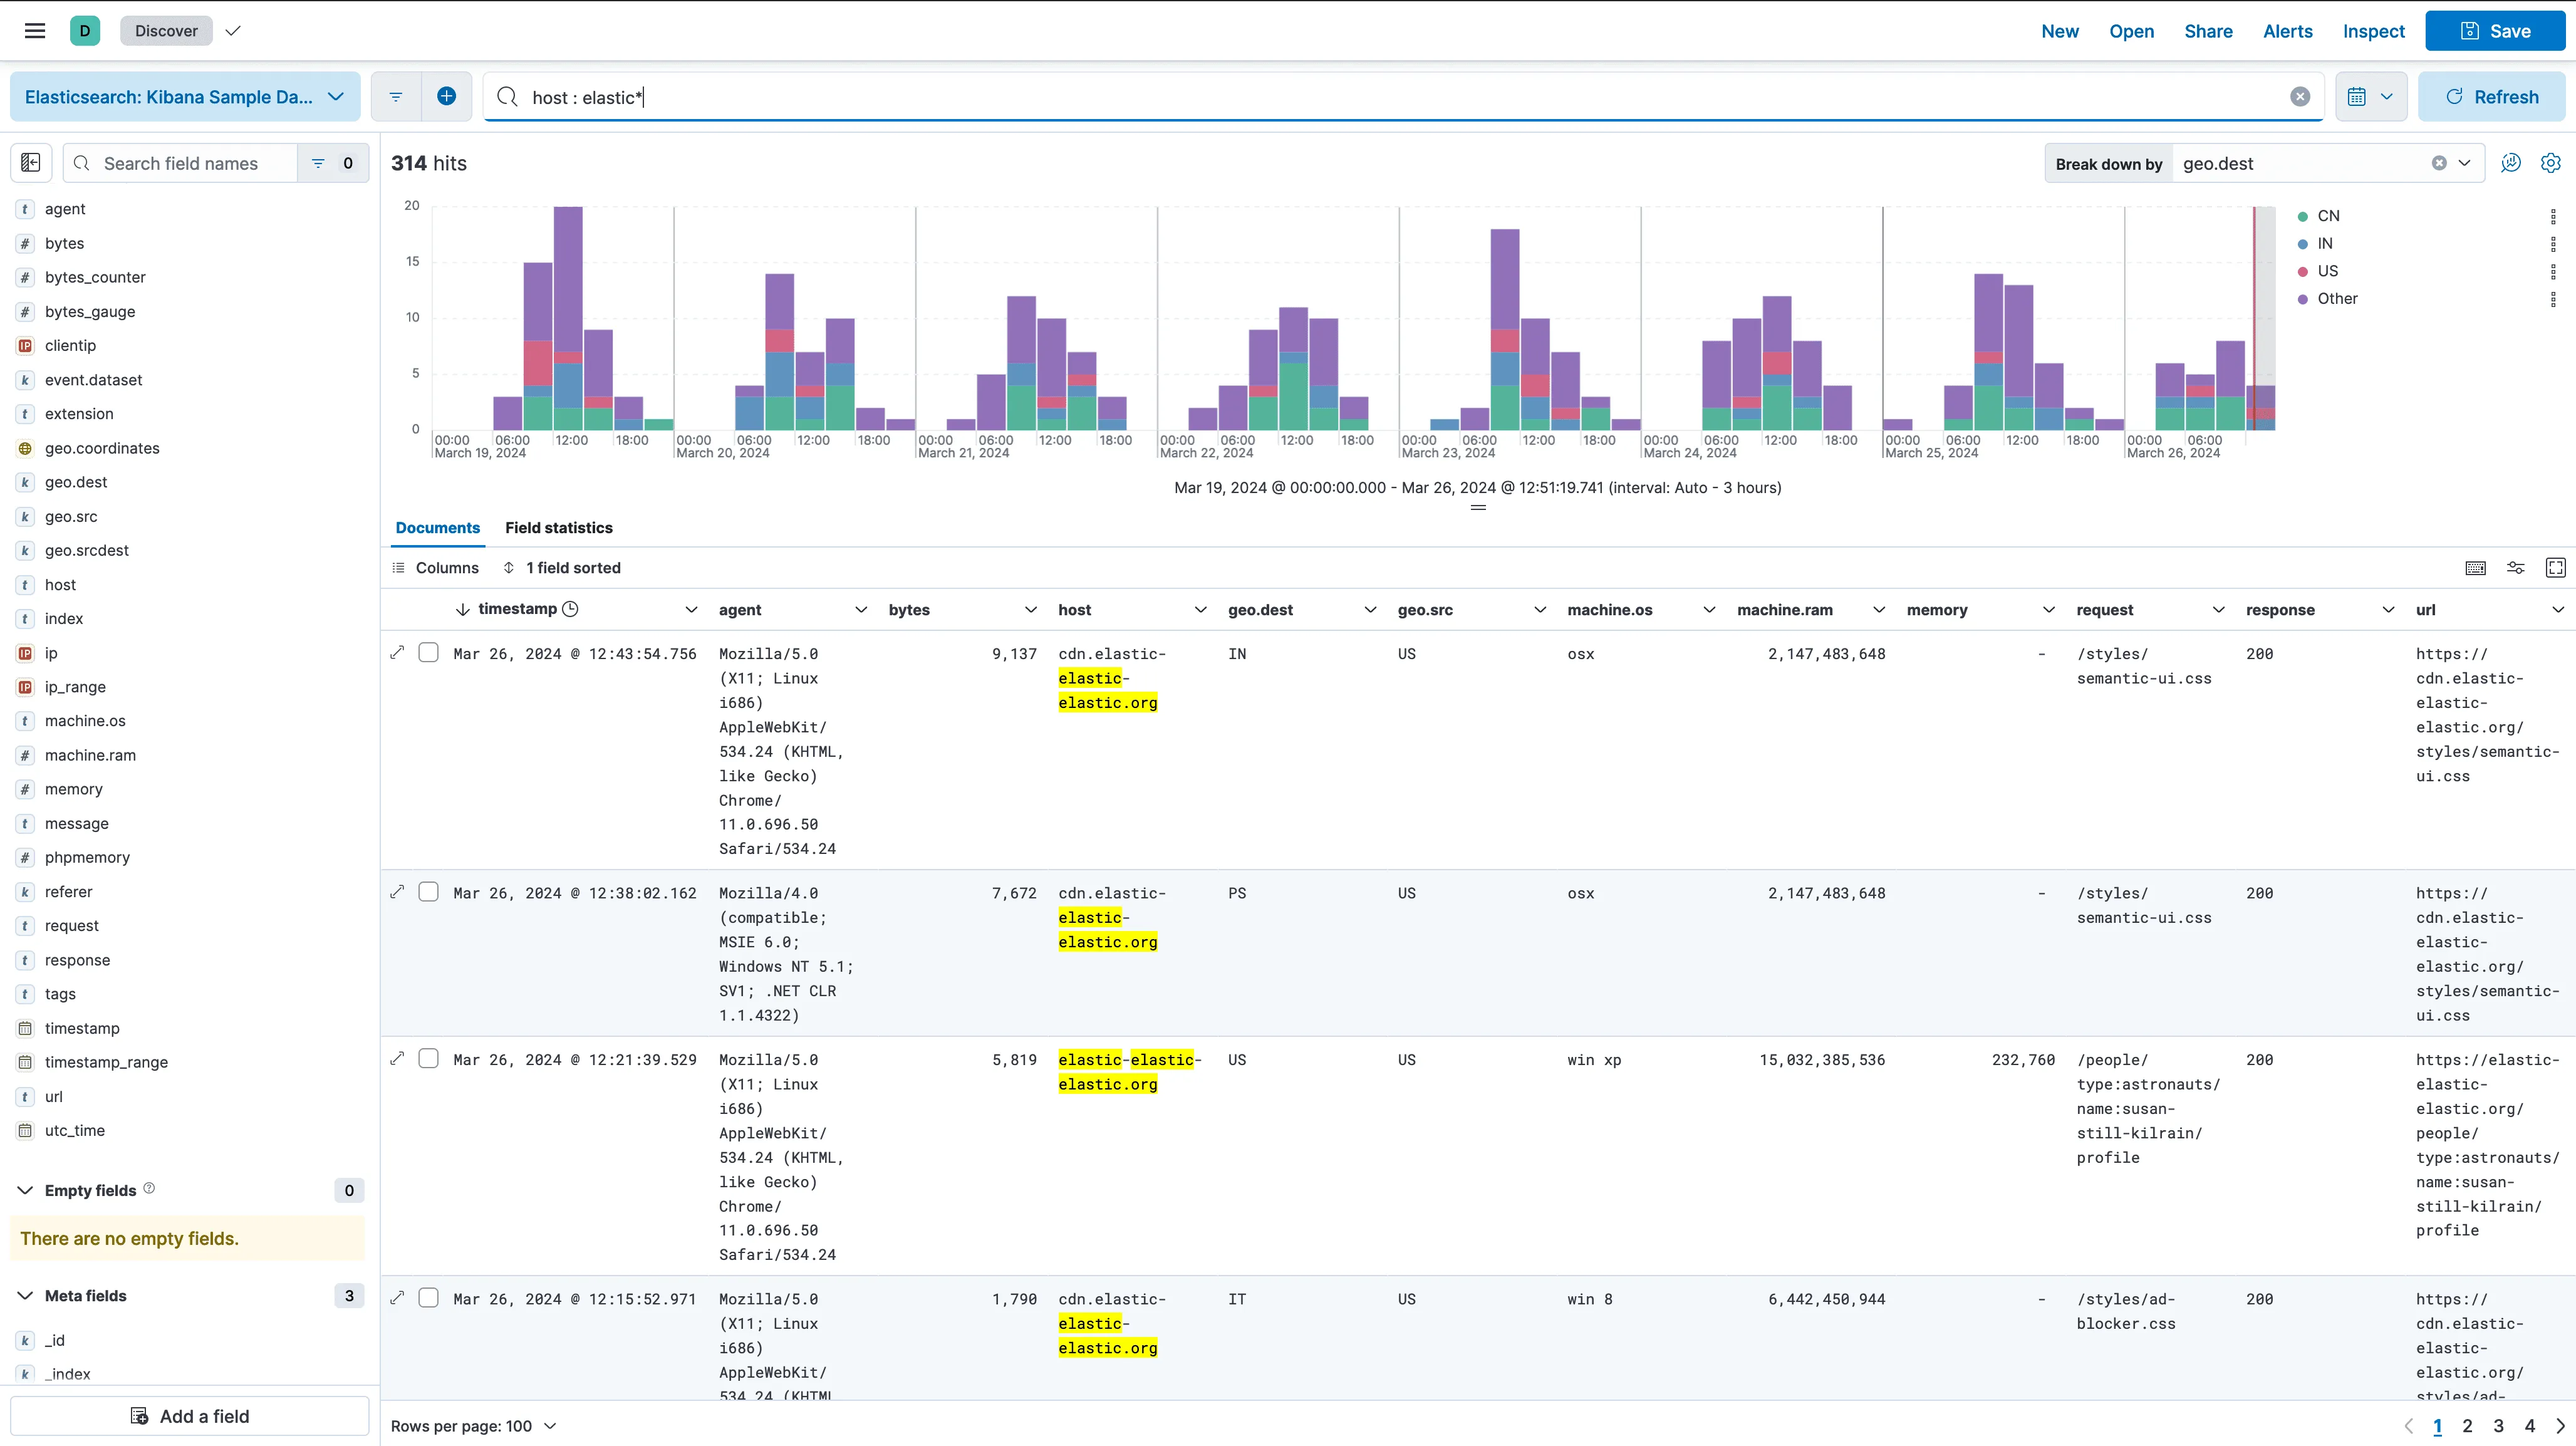
Most people think Data Analysis With Kibana starts in the visual builder. It does not. It starts in Dev Tools. I spent months building dashboards backward from bad queries because I skipped that step. Dev Tools lets you run Elasticsearch queries directly and see the raw aggregation results. You write a query, get the JSON response, verify the buckets are what you expect, and only then do you recreate it in the visualization editor. This alone cuts my iteration time from about forty minutes per chart down to maybe six. The biggest mistake beginners make is assuming Kibana is doing the heavy lifting. It is not. Every chart, every dashboard filter, every time range you apply gets translated into an Elasticsearch query behind the scenes. If your query is inefficient, your dashboard will be slow regardless of how powerful your machine is. I once built a visualization that took twenty seconds to load because I was aggregating on a field with low cardinality using a terms aggregation instead of a filter aggregation. The fix was switching to a filter query at the top level and only aggregating after narrowing the dataset down. Another issue that nobody warns you about is the cached metadata problem. Kibana caches index patterns and field mappings aggressively. When you add a new field to your Elasticsearch index, Kibana will not see it until you refresh the index pattern. Go to Stack Management, click your index pattern, and hit the refresh button. Otherwise you will waste time wondering why your new field does not appear in any dropdown list. This happens every single time someone adds fields mid-project.
Time field configuration is another area where people shoot themselves in the foot. If your timestamp field is mapped as text instead of date in Elasticsearch, every time-based aggregation breaks silently. Kibana will not throw an error. It will just show nothing or aggregate incorrectly. Always verify your mapping before importing data. The @timestamp field should always be a date type, and if you are bringing in external log sources, you may need to reindex with a proper date mapping.
Get the Full Details
Practical Tips That Actually Matter
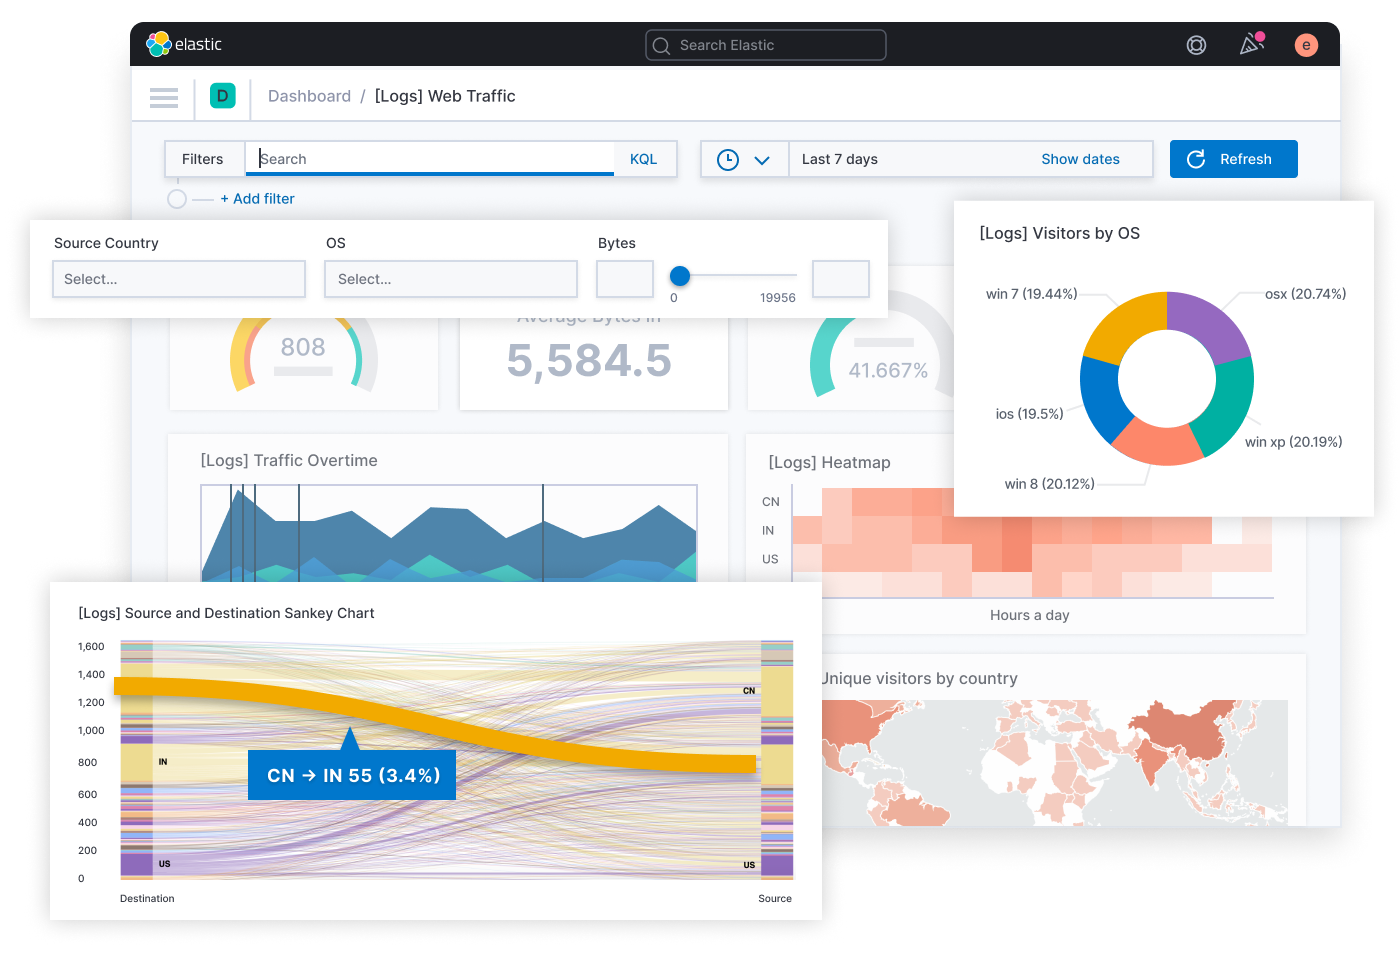
Use saved searches before building dashboards. A saved search can take thirty seconds to a minute to compile, and if you reference that same query across five visualizations, Kibana runs it five separate times. Save the search once, then reference it. Dashboard load times improve noticeably. Be careful with date math in your time range selectors. Kibana supports expressions like now-1h/h or now-7d/d, but they round to the nearest boundary. If you need exact hour-over-hour comparisons, precompute the timestamps in your query instead of relying on relative date math in the UI. I learned this the hard way when a client complained that their hourly metrics were off by exactly one hour every single day. Data Visualization With Kibana works best when you understand how Lucene scores and how aggregations handle precision loss. Floating point fields in aggregations can introduce rounding errors that become visible when you drill down to small sample sizes. If you need exact numbers for financial data, store those values as structured numeric types or even as strings with fixed precision, and use value_count or sum aggregations rather than approximated percentile calculations.
Also, Kibana spaces are not just a cosmetic feature. They let you isolate environments without spinning up separate clusters. I keep my development space separate from production because test queries against production indices in the same space causes accidental overwrites. Each space maintains its own dashboards, visualizations, and saved queries. Set them up early before your team grows.
What Kibana Cannot Do Well
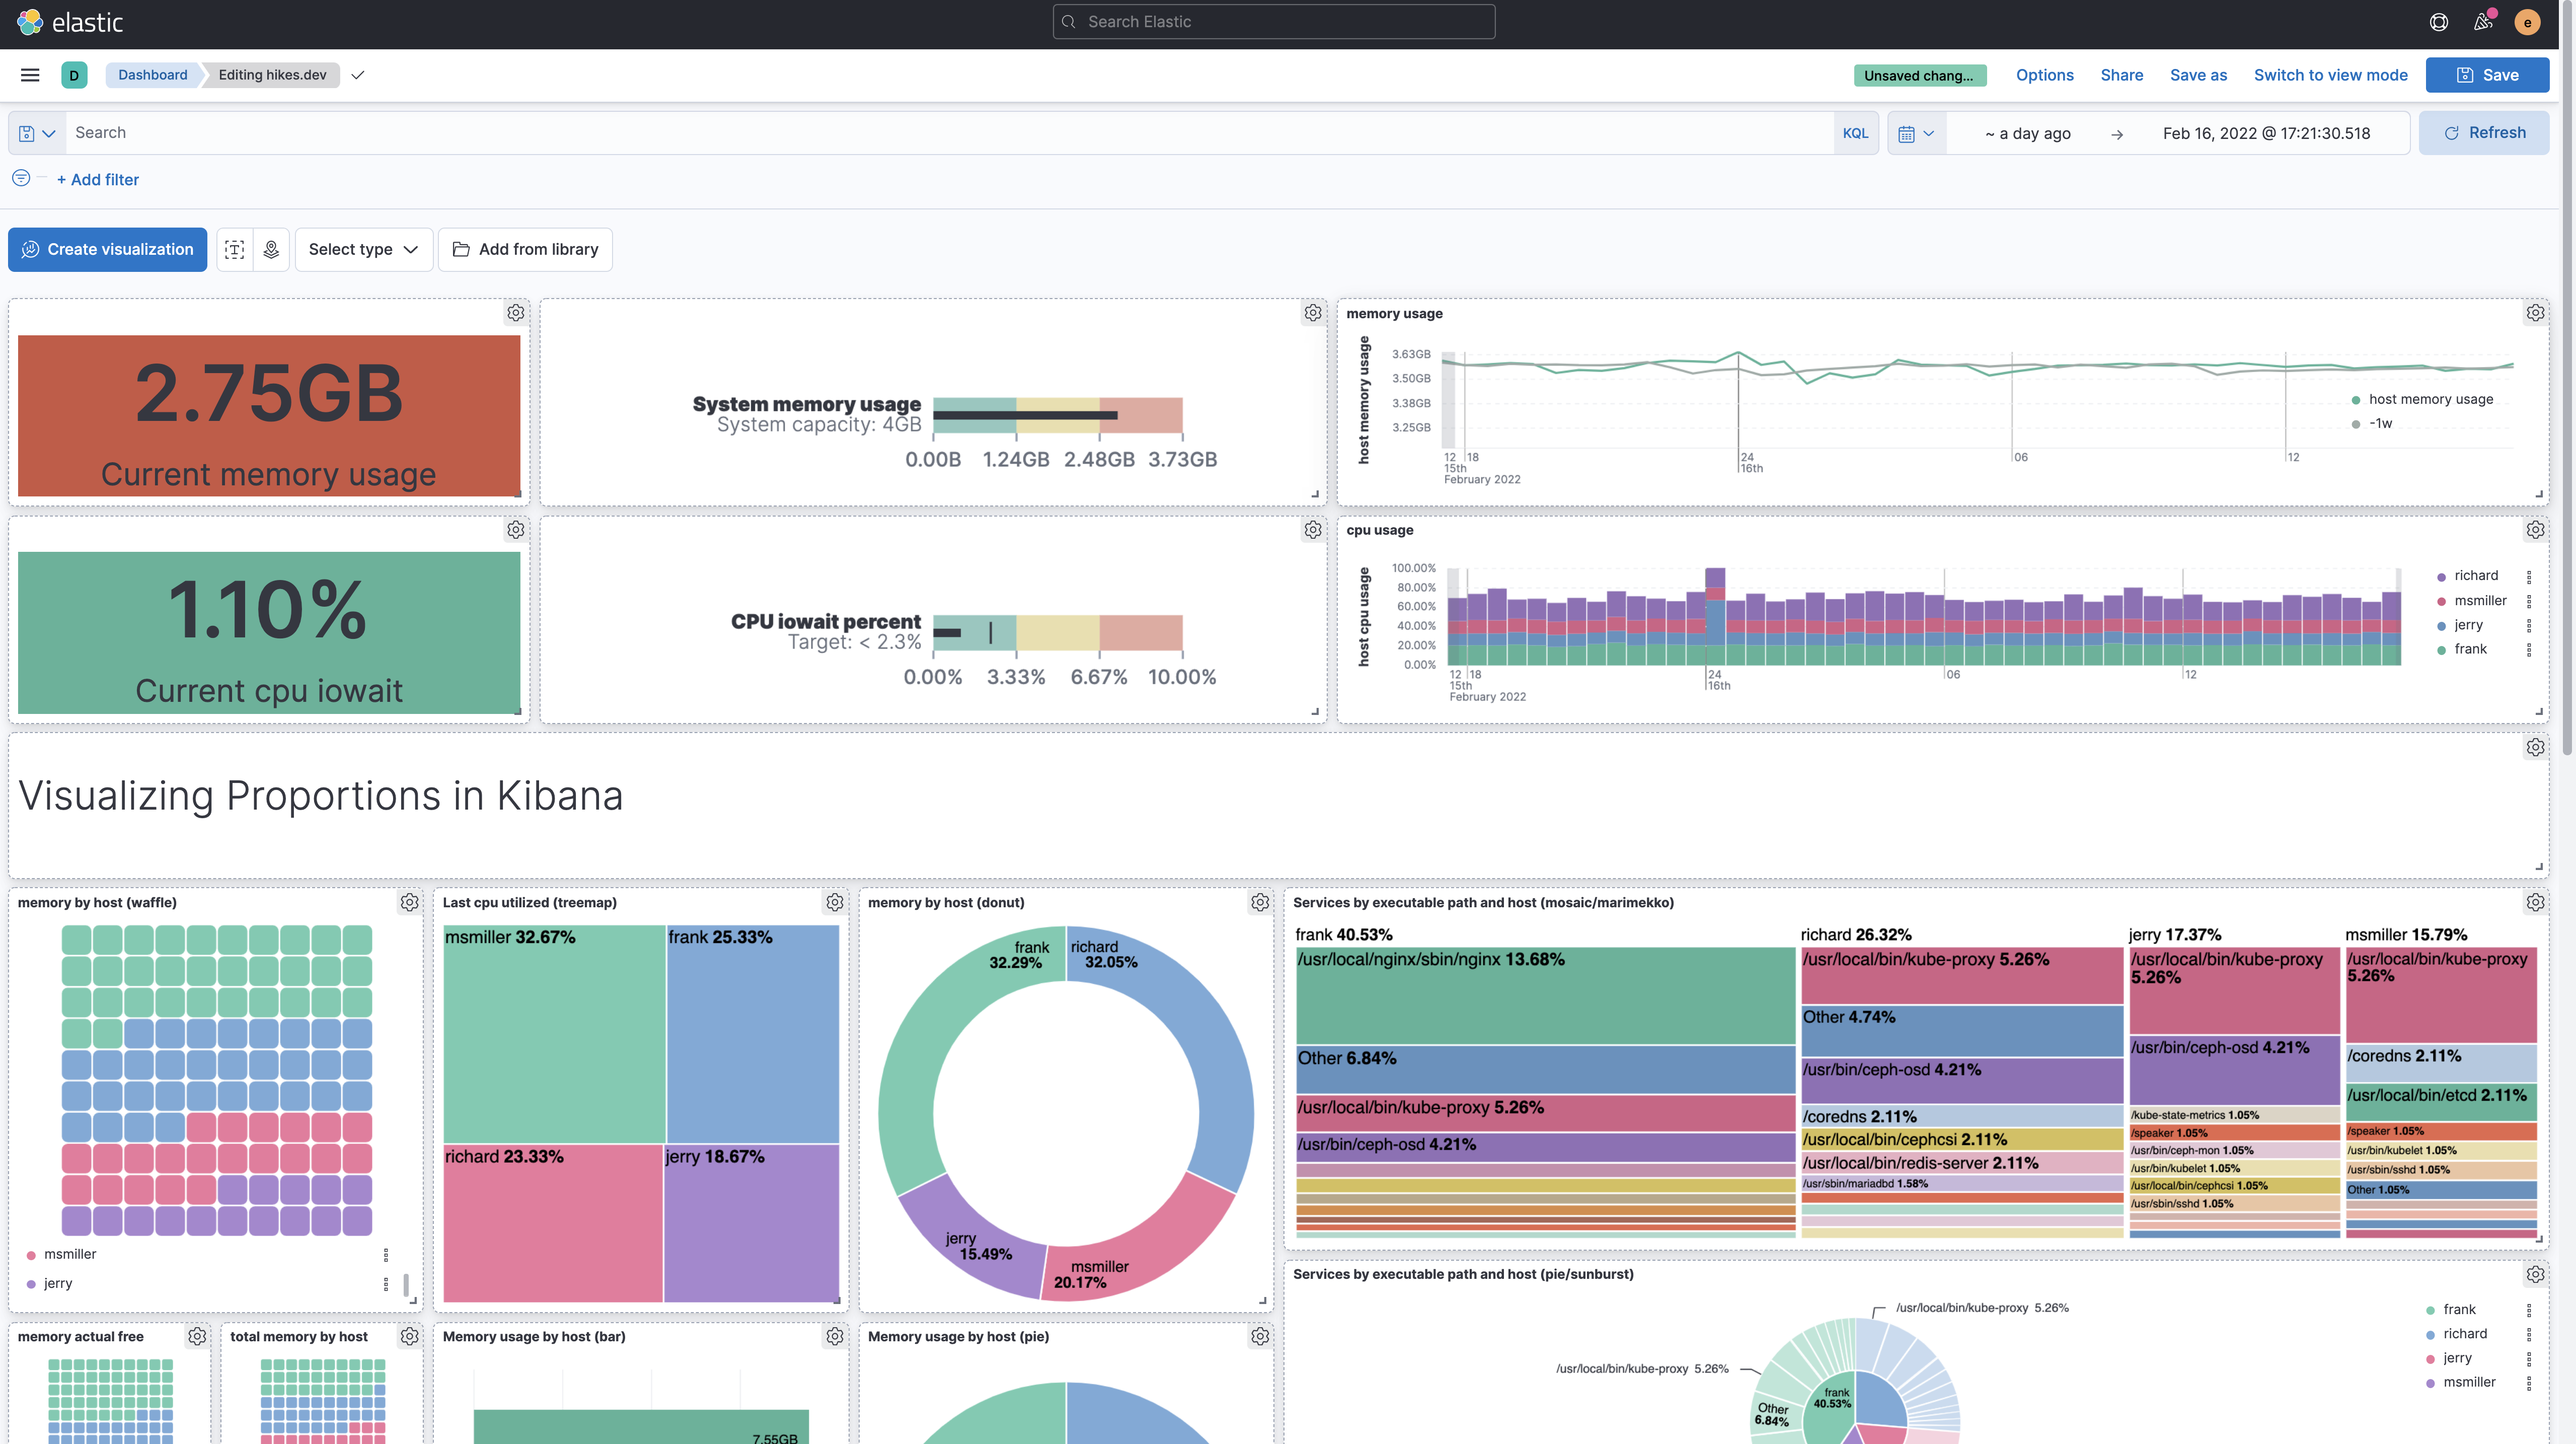
It does not handle multi-cluster queries natively. If you need to join data from two different Elasticsearch clusters, you have to do it outside Kibana, either through Logstash, a custom script, or Elasticsearch's remote clusters feature with cross-cluster search enabled. Kibana itself has no built-in mechanism for this. Real-time streaming analysis is also limited. Kibana is built for near-real-time log and metric exploration, not for continuous stream processing. If your use case involves sub-second latency aggregation on millions of events per second, you should be looking at something like Druid or ClickHouse with their own BI layers instead. Kibana will choke under that kind of throughput. The UI becomes unstable with more than roughly fifty visualizations on a single dashboard. Not because of browser performance alone, but because Kibana re-renders the entire dashboard on most filter interactions. Five years ago I worked with a team that put eighty charts on one dashboard. Opening it took forty-five seconds, and any filter click would cause the page to hang for ten to fifteen seconds. They eventually moved to a modular layout with separate dashboards per topic area.

Getting Started
The official Elastic website hosts the installation packages and documentation. You can download Kibana directly from elastic.co/downloads/kibana. The free tier covers most individual and small team use cases. The main features like alerting, machine learning, and security roles require a paid license, but the core visualization and query capabilities are available in the open source version. Start by ingesting a small, realistic dataset. Do not begin with terabytes of production logs. Get a feel for how queries translate into visuals, break something, fix it, and then scale up. The learning curve is steeper on the query side than on the UI side. Once you understand how the underlying Elasticsearch query DSL maps to what you see on screen, everything else becomes straightforward.