
The Reality of Doing Data Analysis With Open Source Tools
I spent roughly three days last month chasing a silent bug in a Python script that was supposed to merge two CSV files. The merge completed without errors, but the row count dropped by about 40,000 records. It turned out one of the files had a hidden UTF-8 BOM character in its header row that was silently corrupting the join key. pandas read it fine, but the key comparison failed for every single row. The workaround was trivial once I found it, but finding it consumed more time than the actual analysis would have taken. This is the day-to-day reality of Data Analysis With Open Source Tools, and most tutorials completely skip over the stuff that actually eats your time. The standard toolkit is probably what you already expect. Python with pandas for data manipulation, Jupyter or VS Code for interactive work, SQLite or PostgreSQL for storage, and either matplotlib or plotly for visualization. R still holds ground in academic and statistical environments, particularly with ggplot2 and dplyr. For anyone doing this regularly, the Python stack is the more practical default if you need to productionize anything afterward. R and Python can coexist on the same machine without conflict, and many people actually run both depending on the task at hand.
What You Actually Need to Know About Data Analysis With Open Source Tools
Most beginners learn to load a clean CSV into pandas, run a few groupby operations, and call it a day. That works until the data doesn't fit in memory, or the dates are inconsistently formatted across five different files, or you need to repeat the exact same pipeline next week and can't remember which parameter you changed. The gap between "I made a chart once" and "I have a reproducible workflow" is where most people stall out. One thing nobody tells you early on: the order in which you write your code is almost never the order you should write it. Beginners tend to start with data loading and exploration, then gradually add cleaning steps. This produces a notebook that is nearly impossible to rerun cleanly because intermediate state leaks between cells. The more useful approach is to write the final analysis step first, or at least define your input and output schema before you touch any data. You will waste less time moving cells around and deleting old outputs. When I moved from Jupyter notebooks to a project structured with a src/ directory, a Makefile, and pytest-based validation checks, my iteration time for full pipelines dropped from something like 45 minutes of manual checking down to about eight minutes of automated verification. The upfront cost was roughly two days of restructuring, and it paid for itself within the first month.
The Tools, Used in Practice
pandas remains the workhorse for tabular data, but it has hard limits. Once your dataset exceeds roughly 70 percent of your available RAM, performance degrades unpredictably. I ran into this with a transaction log that was 18 GB on disk but required about 40 GB in memory after parsing. The solution was switching to Dask DataFrame for the aggregation steps while keeping pandas for smaller intermediate transformations. Dask does not support every pandas operation, and some edge cases around multi-index joins still produce incorrect results silently, so validation against a known subset is essential before trusting the full output. For SQL, PostgreSQL is the sensible default if you need anything beyond simple queries. The window functions, CTEs, and materialized views save you from pulling enormous datasets into Python in the first place. Filtering and aggregating at the database layer before exporting usually cuts your working dataset by an order of magnitude or more. I had a case where a query that took twelve minutes running against a full export in pandas completed in eleven seconds when pushed to PostgreSQL, because the query planner filtered rows before they ever left the database. Visualization with matplotlib is functional but rigid. plotly adds interactivity without much extra effort, and altair is worth learning if you work with medium-sized datasets and want declarative grammar. For quick internal charts, matplotlib is fine. For anything shared outside your immediate team, plotly or a static PNG export from a well-configured matplotlib script will prevent follow-up questions about filters and date ranges.
Get the Full Details

Storage and Workflow Design
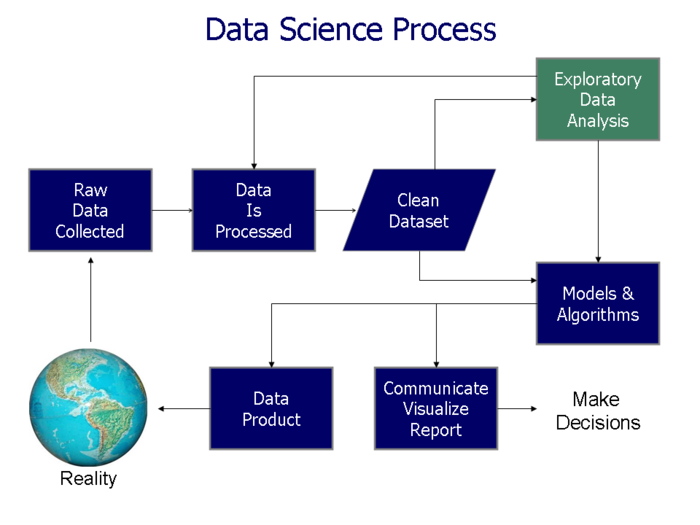
SQLite is often dismissed as a toy database, but for personal or small-team data analysis projects it is genuinely adequate. It stores everything in a single file, handles concurrent reads without locking issues in most cases, and requires zero configuration. The downside is write concurrency. If two processes are appending to the same SQLite database simultaneously, you will encounterlocked database errors. A single writer with multiple readers is fine. Two writers is not. A pipeline that survives contact with reality usually looks something like this: raw data lands in an unstructured folder, a validation step checks schema and basic quality metrics, cleaned data moves to a staging area, and transformed data ends up in the final analysis store. Each step should be idempotent. If you rerun step three after fixing a bug in step two, steps three and four should still produce correct results without manual intervention. I learned this the hard way when a re-run of a monthly report produced different numbers because an earlier cleaning step had been applied twice due to a missing guard clause.
Common Pitfalls That Wasted Hours
Missing values behave differently across operations in pandas. A column of floats with NaN values will stay float, but if you mix NaN with strings during a concat or merge, the entire column can become object dtype, which breaks numeric operations silently. Checking dtypes after every major transformation is faster than debugging wrong results later. Date parsing is another minefield. The American date format MM/DD/YYYY versus European DD/MM/YYYY will not raise an error if you do not explicitly specify the format. I once spent an afternoon investigating an apparent 15 percent spike in early-year transactions before realizing the source system had swapped the day and month columns for about thirty thousand rows. pd.to_datetime() with dayfirst=True caught it immediately on a second pass. Another issue that comes up repeatedly is timezone handling. Pandas timezone-naive and timezone-aware datetimes do not raise errors when compared or merged, but the results will be wrong if one side is in UTC and the other is not. Always standardize to a single timezone at the ingestion step and verify with an explicit assertion rather than hoping the downstream code handles it correctly.
Where Open Source Tools Fall Short
Open source data analysis tools are not a universal solution. They struggle in three areas where proprietary alternatives may be necessary. The first is extremely large-scale distributed processing. Spark is the open source option here, but it introduces significant complexity for datasets that a single machine could handle with optimized pandas code. If your data fits in memory, do not use Spark. The overhead is real and the debugging experience is worse. The second gap is collaborative governance. Open source stacks do not provide built-in role-based access control, audit trails, or lineage tracking for transformations. If you are working in a regulated environment or with multiple stakeholders who need to understand where numbers come from, you will eventually need something like Great Expectations for validation, dbt for transformation lineage, or a proprietary platform that handles this natively. The third area is UI-based workflows. Not everyone on a team writes code. If you need business users to explore data without a developer, open source tools require substantial additional investment in tools like Superset or Metabase, and even those have limitations compared to purpose-built commercial BI platforms. This is not a flaw in the open source tools, it is simply a mismatch between what they are designed for and what some organizations require.
Practical Recommendations
Start with a small project and build the pipeline structure from day one, even if the project feels too small to justify it. The structure you ignore now becomes technical debt later. Use virtual environments or conda environments consistently. Mixing package versions across projects is the fastest way to lose a afternoon to dependency conflicts. Learn to read tracebacks properly instead of copying them into a search engine and hoping for the best. Most errors contain the exact file and line number where the failure occurred. The error message is usually more informative than you give it credit for. Invest time in learning SQL if you have not already. Every data analysis workflow benefits from pushing computation to the database layer whenever possible, and the skills transfer regardless of which Python or R tools you use. The tools change. The principle of filtering and aggregating before you extract does not.
Backup your raw data before you transform it. Not the processed output, the raw input. Transformations are reversible, restored originals are not. I have seen people lose months of data collection because they deleted the source folder after a successful export, assuming the pipeline had preserved everything. It had not.


