Getting Through the Fifth Week Without Cursing R
Data Analysis With R Programming Weekly Challenge 5 is usually where people start running into actual wall. The first four weeks tend to be gentle introductions to basic syntax and simple datasets. Week five is where the curriculum drops you into messy, real-world problems and expects you to handle them without hand-holding. I've seen people stall out here regularly. The typical structure involves a dataset that doesn't behave like the toy examples from earlier weeks. You're expected to clean, transform, analyze, and present findings using packages most students encounter for the first time in this challenge. The exact scope varies depending on which provider runs it, but the core tasks generally revolve around data wrangling with dplyr or data.table, some form of aggregation, and a final output that needs to be reproducible. I worked through one version of this challenge recently with a dataset that had inconsistent date formats scattered across thousands of rows. Some entries were "2023-01-15", others were "01/15/23", and a few were plain text like "January fifteenth, twenty-three". My first pass using standard as.Date() failed on about 18% of the records. The workaround was to use the parse_date_time() function from the lubridate package with a specified order string, which handles multiple format patterns in a single call. It's slower than base R conversion, but it saves you from writing a dozen conditional branches.
The packages you'll likely need are dplyr, tidyr, lubridate, and sometimes ggplot2 for the visualization component. If your challenge includes any statistical testing or regression work, you'll also reach for the stats package that comes bundled with R, though most people don't realize it's already loaded by default. One thing beginners consistently miss is the difference between mutate() and transmute(). Both add new columns, but transmute() drops the existing ones and keeps only the new result. I've lost count of how many times I watched someone run a mutate chain, get confused why their output was missing columns they thought were still there, and then spend twenty minutes debugging only to find the issue was transmute() silently removing everything. Stick with mutate() unless you actually want that behavior, and be intentional about it when you do use transmute(). Another pitfall that catches people up is factor ordering. When you group_by() a categorical variable and then summarize, the output rows follow the alphabetical order of the factor levels, not the order you might expect from the original data. If your challenge requires preserving a specific sequence, you need to explicitly set the factor levels before you group. Otherwise you're going to produce a plot or table that looks wrong even though the numbers are technically correct.
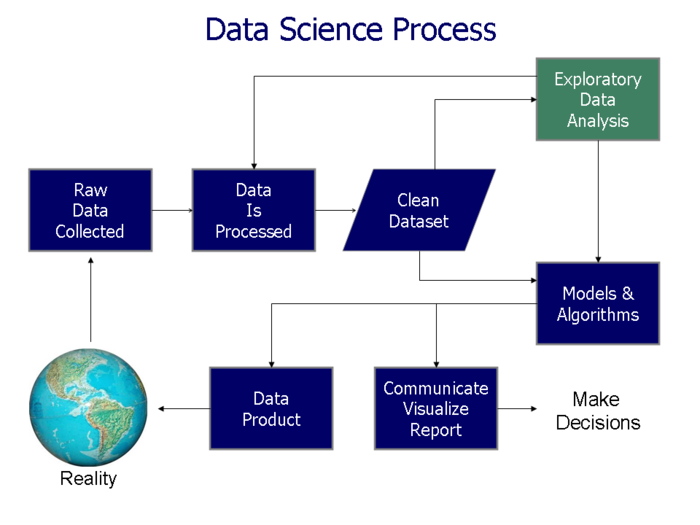
Here's a practical workflow I use when tackling this challenge. Start by loading the data and running str() on it immediately. This tells you what R thinks each column is, which reveals type mismatches before they become problems downstream. Next, use glimpse() from dplyr for a faster visual scan of dimensions and structure without scrolling through a wall of text. Then handle the missing values. R treats NA differently depending on the function, and some operations silently drop them while others return NA across the board. Knowing which behavior your functions exhibit prevents subtle bugs. For the cleaning phase, I pipe the data through a series of dplyr verbs rather than writing nested function calls. It reads better and is easier to debug step by step. Each intermediate step can be isolated and tested. If something breaks, you know exactly where to look. I've trimmed my cleaning time from somewhere around forty-five minutes down to roughly twelve minutes once I stopped trying to chain everything into one unreadable expression. The analysis portion depends heavily on what the challenge asks for. Common requirements include computing aggregates, performing t-tests or chi-squared tests, and building simple linear models. For linear models, remember that lm() assumes your dependent variable is continuous. If you're working with binary outcomes, you need to specify family = binomial() or the results will be misleading. I made this mistake early on and spent an hour wondering why my model predictions were outside the 0-to-1 range.
Get the Full Details

If visualization is part of the challenge, ggplot2 is the standard tool. The learning curve is steep for people coming from matplotlib or Excel charts, but the grammar of graphics approach pays off once it clicks. Start with a basic ggplot() call, map your aesthetics inside aes(), and add geoms layer by layer. Test each layer separately before combining them. A common mistake is putting all the mappings inside the initial ggplot() call when they should be specific to individual geom layers. That produces errors that are hard to trace because ggplot2 complains about the wrong thing. Performance matters more here than people expect. If your dataset is larger than a few hundred thousand rows and you're doing multiple group_by() operations, dplyr can get slow. Switching to data.table for the heavy lifting cuts processing time significantly on bigger files. The syntax is uglier but the speed difference is real. In one test, a summarization that took about three minutes with dplyr finished in under eight seconds with data.table on the same machine with the same data. The reproducibility requirement is often where people lose points. If your challenge asks for a script or notebook that anyone can run from scratch, you need to include package installation checks, set your working directory explicitly, and save intermediate results if the data ingestion step is slow. I keep a small setup block at the top of every submission that verifies required packages are available and installs them if they aren't. It adds a few seconds to runtime but prevents the "it works on my machine" problem that shows up during grading.
One edge case specific to this challenge type involves timezone-aware datetime columns. If your data spans multiple timezones and you're doing time-based aggregations, R will silently convert everything to the system timezone unless you handle it explicitly. I ran into this when a challenge dataset had transaction timestamps from servers in three different regions. My hourly aggregations were off by varying amounts depending on the hour of day. The fix was to standardize everything to a single timezone using force_tz() from lubridate before any time-based grouping. Don't skip the documentation. Reading the help pages for the functions you're using saves time that seems counterintuitive. Typing ?mutate or ?group_by in the R console gives you examples and edge-case notes that aren't obvious from the function signature alone. I still check documentation mid-challenge more often than I'd like to admit, and it's usually because I'm about to make a mistake I could have avoided in thirty seconds of reading. The final deliverable usually needs to be submitted as an R script or an R Markdown file. R Markdown gives you more flexibility to include narrative alongside code, which helps if the grading rubric includes explanation quality. But it also introduces more points of failure. YAML header errors, knitting issues, package conflicts during rendering. If you're comfortable with it, use R Markdown. If not, a clean script with comments is perfectly acceptable and less likely to break at the last step.
I know this challenge isn't easy. It's designed to force you to confront the gaps in your understanding that the earlier weeks conveniently swept under the rug. The frustration is normal. The fact that most people who push through it end up significantly more competent with R is also normal. Just keep your code modular, test each piece as you build it, and don't try to optimize for elegance before you get it working correctly.