What Actually Shows Up in These Assessments
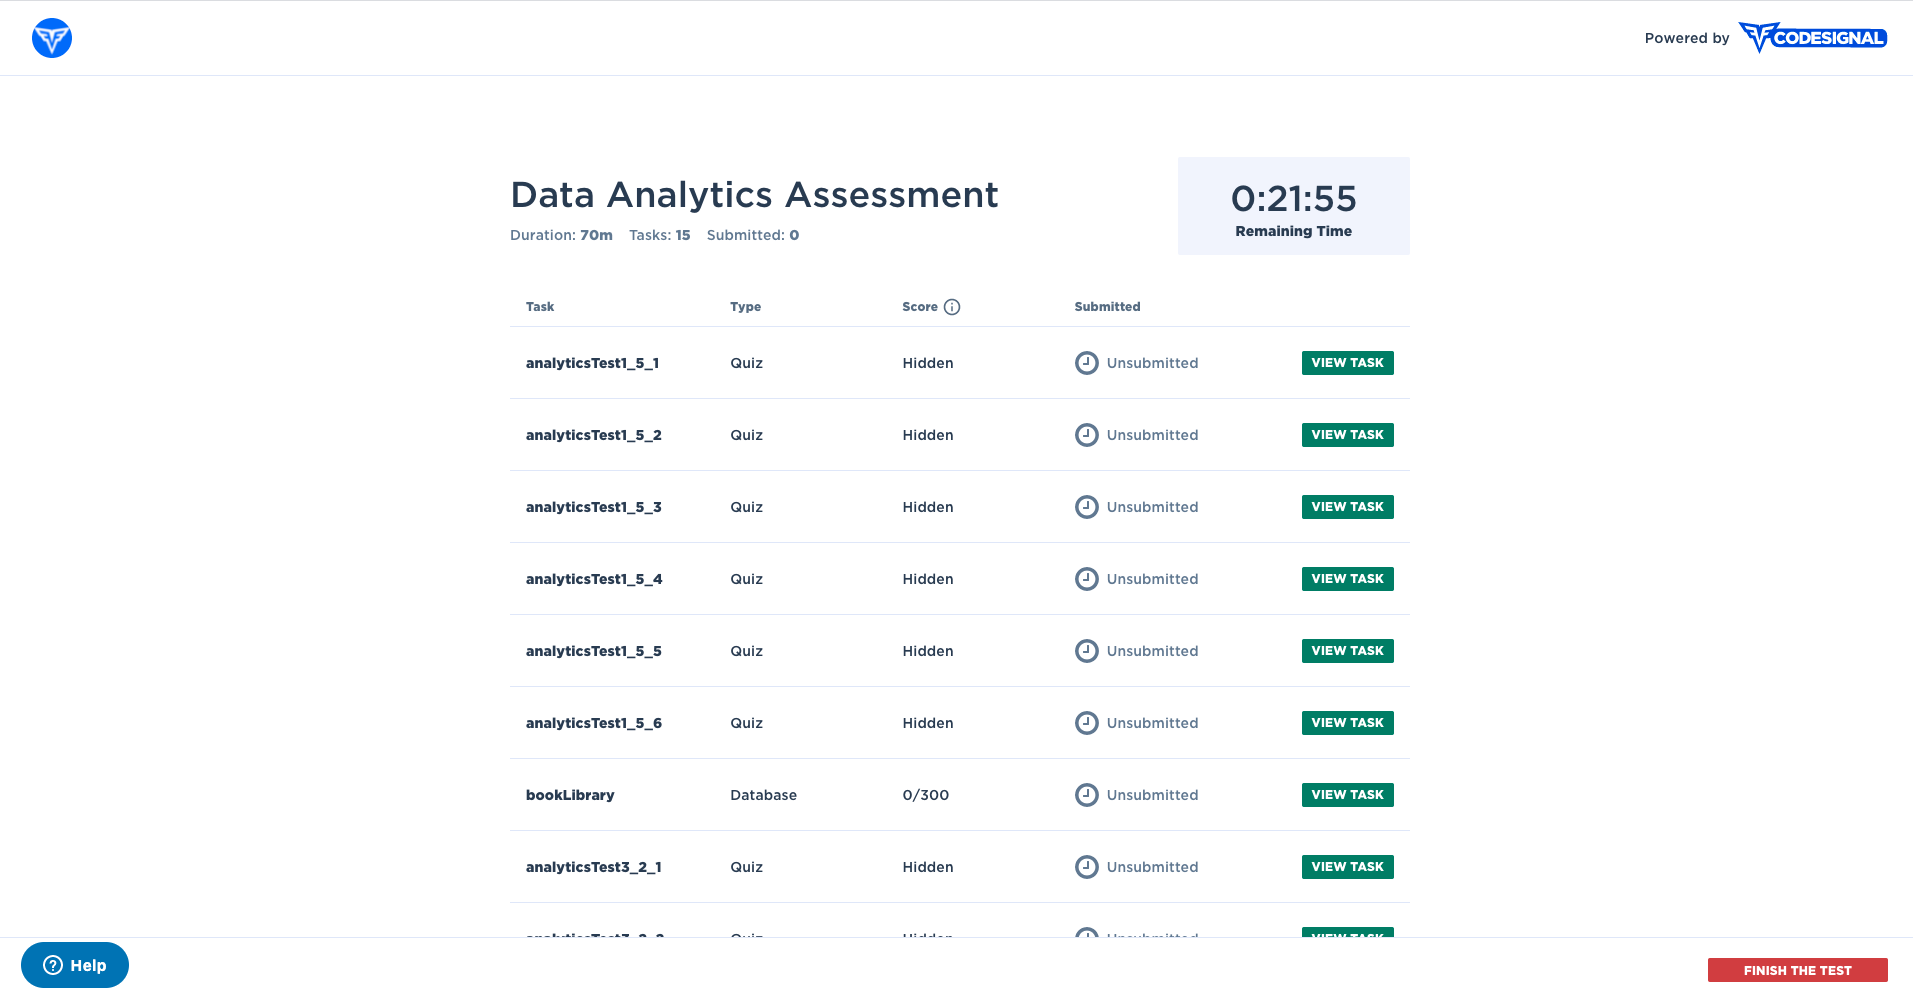
Most Data Analyst Assessment Examples you'll encounter fall into three buckets. There's the SQL round where you're given a messy schema and asked to write queries that join tables correctly and handle edge cases. The spreadsheet round where you're handed raw transactional data and expected to clean it, pivot it, and produce a summary. And the case study where you get a business question with no clear answer and have to figure out what analysis would actually be useful. I took my first one at a fintech startup. They gave me a PostgreSQL database with five tables and a prompt asking for monthly active users. Pretty straightforward, right. The trick was that their "active user" definition changed mid-year, and the relevant column was stored as a string formatted as MM/DD/YYYY instead of a proper date type. Half the candidates submitted queries that completely missed the conversion layer. I ended up writing a CASE statement that handled the date format change and also flagged records where the string didn't match either pattern. They called me back two days later.Data Analyst Assessment Examples That Actually Test Something
Here's a breakdown of the formats you'll see and what they're measuring. SQL challenges typically test whether you understand LEFT JOIN versus INNER JOIN, how NULLs behave in aggregations, window functions like ROW_NUMBER or RANK, and whether you can structure a complex query readably. A common task is calculating month-over-month growth or identifying users who churned. You need to know how to write a CTE versus a subquery, because that matters for readability and sometimes for query planner performance. Excel or Google Sheets tasks usually involve cleaning dirty data — duplicates, inconsistent date formats, text that looks like numbers. Then they want a pivot table or a VLOOKUP/XLOOKUP relationship mapped out. The hidden trap here is always the formatting. Someone will put "Jan 2024" in one cell and "2024-01" in another and expect you to aggregate them together. Write down every assumption you make about the data before you start cleaning. Case studies are where people lose points not because they can't analyze but because they overcomplicate. You'll get something like "Should we launch product X in market Y?" The right move is to ask clarifying questions, outline what data you'd need, propose a simple framework, and then work through it. You don't need a complex regression model. You need a clear chain of reasoning from the question to the recommendation.I once watched a candidate spend forty minutes building an elaborate Python script with multiple visualization libraries for a take-home assessment. The prompt asked for a single chart showing trend over time. The hiring manager's feedback was that the code was impressive but they couldn't figure out which chart was the actual deliverable buried in six files. Keep it simple. One clean script. One clear output. One paragraph explaining what it means.
How to Actually Prepare Without Wasting Time
Practice SQL on platforms like LeetCode or StrataScratch, but focus on medium-difficulty questions that involve window functions and self-joins. Do at least ten of those. They repeat the same patterns — consecutive login streaks, retention cohorts, running totals — in different clothing. For spreadsheet work, take a raw CSV dump from Kaggle and clean it without looking at a tutorial. Force yourself to deal with the inconsistency. That's the skill being tested. For case studies, find past interview stories on Blind or Reddit and work through them out loud. Structure your thinking around the MECE framework or a simple revenue decomposition. The point isn't to be fancy. It's to show you can organize a messy problem into a series of answerable questions.One thing nobody tells you: write comments in your code. Even if the assessment says no explanation needed, a commented query costs nothing and signals that you think about maintainability. I've seen candidates fail a second-round interview simply because the panel noticed their SQL had zero readability and decided they wouldn't survive in a team environment.
Pitfalls That Kill Otherwise Strong Candidates
Missing the edge case where a join produces duplicate rows because of a many-to-many relationship. If you're joining orders to customers and a customer has multiple orders in the same period, your aggregation will be wrong. Always count distinct IDs unless the business logic explicitly requires duplicates. Assuming NULL means zero. It doesn't. AVG(), SUM(), and COUNT() all behave differently with NULLs. COUNT(*) counts rows. COUNT(column) counts non-null values. This distinction matters when you're computing metrics like average session duration. Not handling date inconsistencies. Data in the wild rarely uses ISO format consistently. Learn to use CAST, CONVERT, or TO_DATE functions depending on the SQL dialect. Postgres and BigQuery handle these slightly differently. Over-optimizing queries that will run on a dataset of a few thousand rows. Readability matters more than query plan efficiency in an assessment setting. If the evaluator can't follow your logic in thirty seconds, you've already lost points regardless of how fast it executes.The hardest assessment I've ever sat through was a live SQL round where the interviewer kept changing the requirements mid-query. "Actually, filter out test accounts." "Now segment by region." "Make sure you exclude refunds." The key was staying calm and restructuring the CTE rather than rewriting from scratch each time. I treated it like a real production task, not a puzzle to solve perfectly on the first try.
Get the Full Details

What Good Results Look Like
A strong SQL answer uses CTEs to break the problem into named steps, handles NULLs and duplicates explicitly, and includes a brief note about assumptions. A strong spreadsheet answer shows the original data, the cleaned version, and the final output in separate sheets with clear labels. A strong case study walks through the question, the approach, the data gaps you'd need, the analysis you'd run, and a recommendation grounded in the results. There's no single correct way to structure these, but there are definitely wrong ways. Wrong is a forty-slide deck for a question that needed four bullet points. Wrong is a SQL query that works but reads like a grocery list. Wrong is an analysis that answers a question nobody asked.If you want references, the Data Analyst Assessment Examples on Glassdoor and Blind threads are worth skimming. They're not always accurate but they'll show you the tone and difficulty level companies are targeting. Some firms like Stripe and Airbnb publish their actual questions online. Those are good because they reveal whether the bar is technical depth or practical judgment. Most places care more about the latter.