What Actually Happens When You Open a Spreadsheet
I spent three days last month tracing a revenue discrepancy that turned out to be a locale formatting issue. A European partner's file used commas for decimals while our systems expected dots. The numbers "looked" right but were shifted by factors of 100. That kind of thing eats weekends. Data analytics and data analysis aren't the same thing, though people use them interchangeably until their boss asks for clarification. Here is the difference in practice.
Data Analytics And Data Analysis
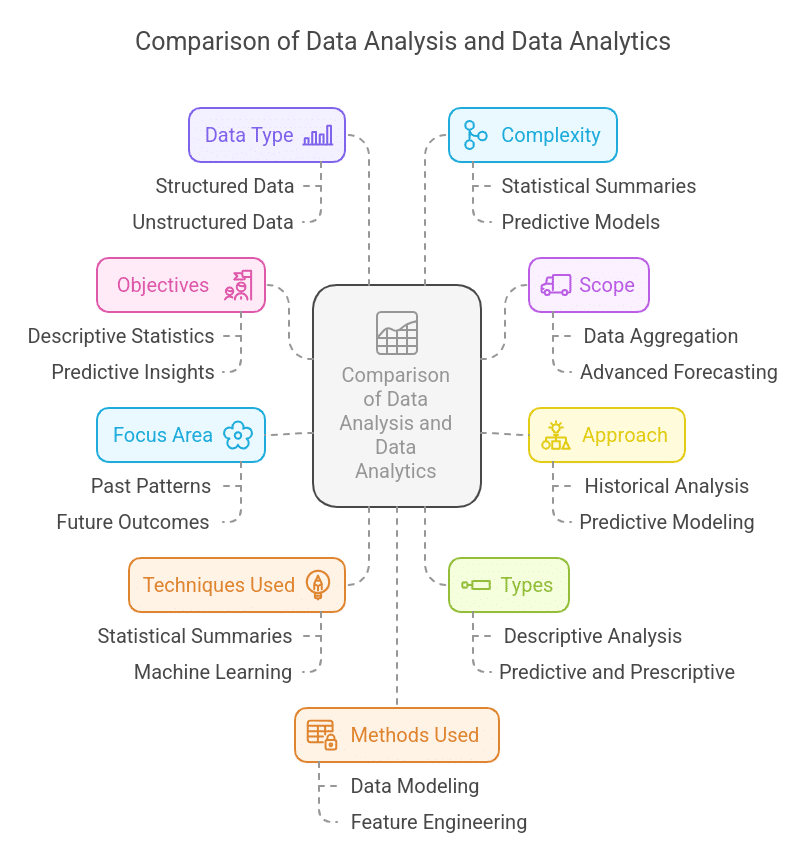
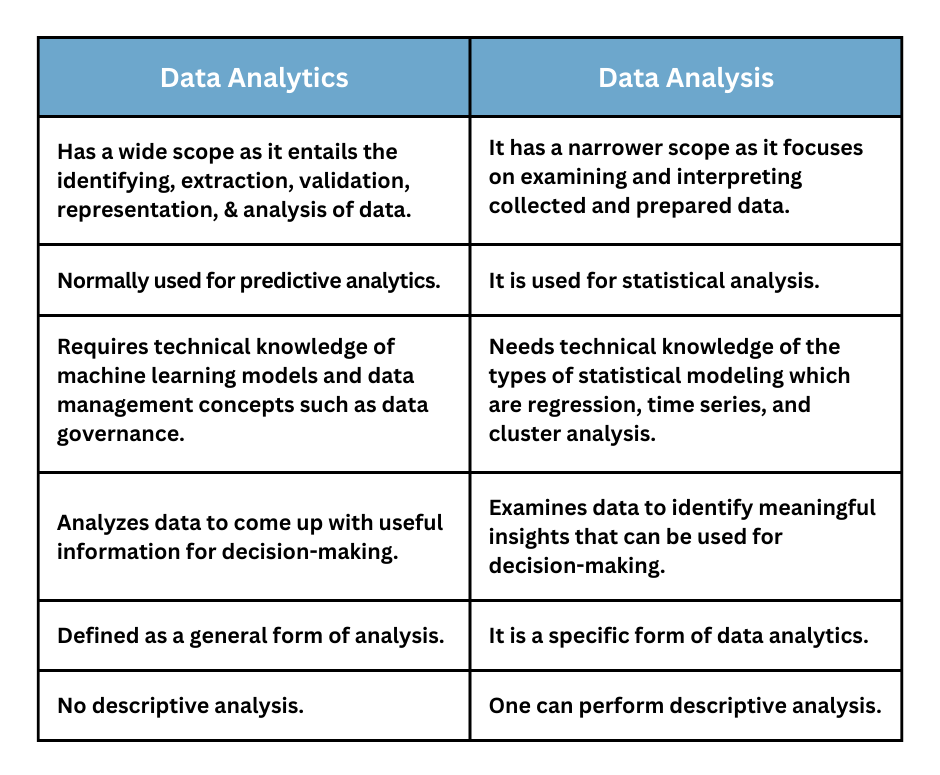
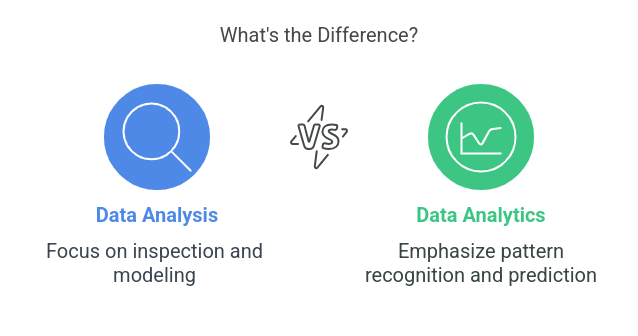
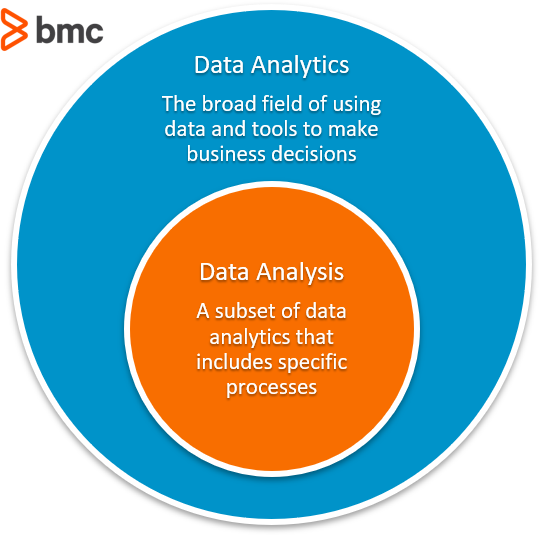
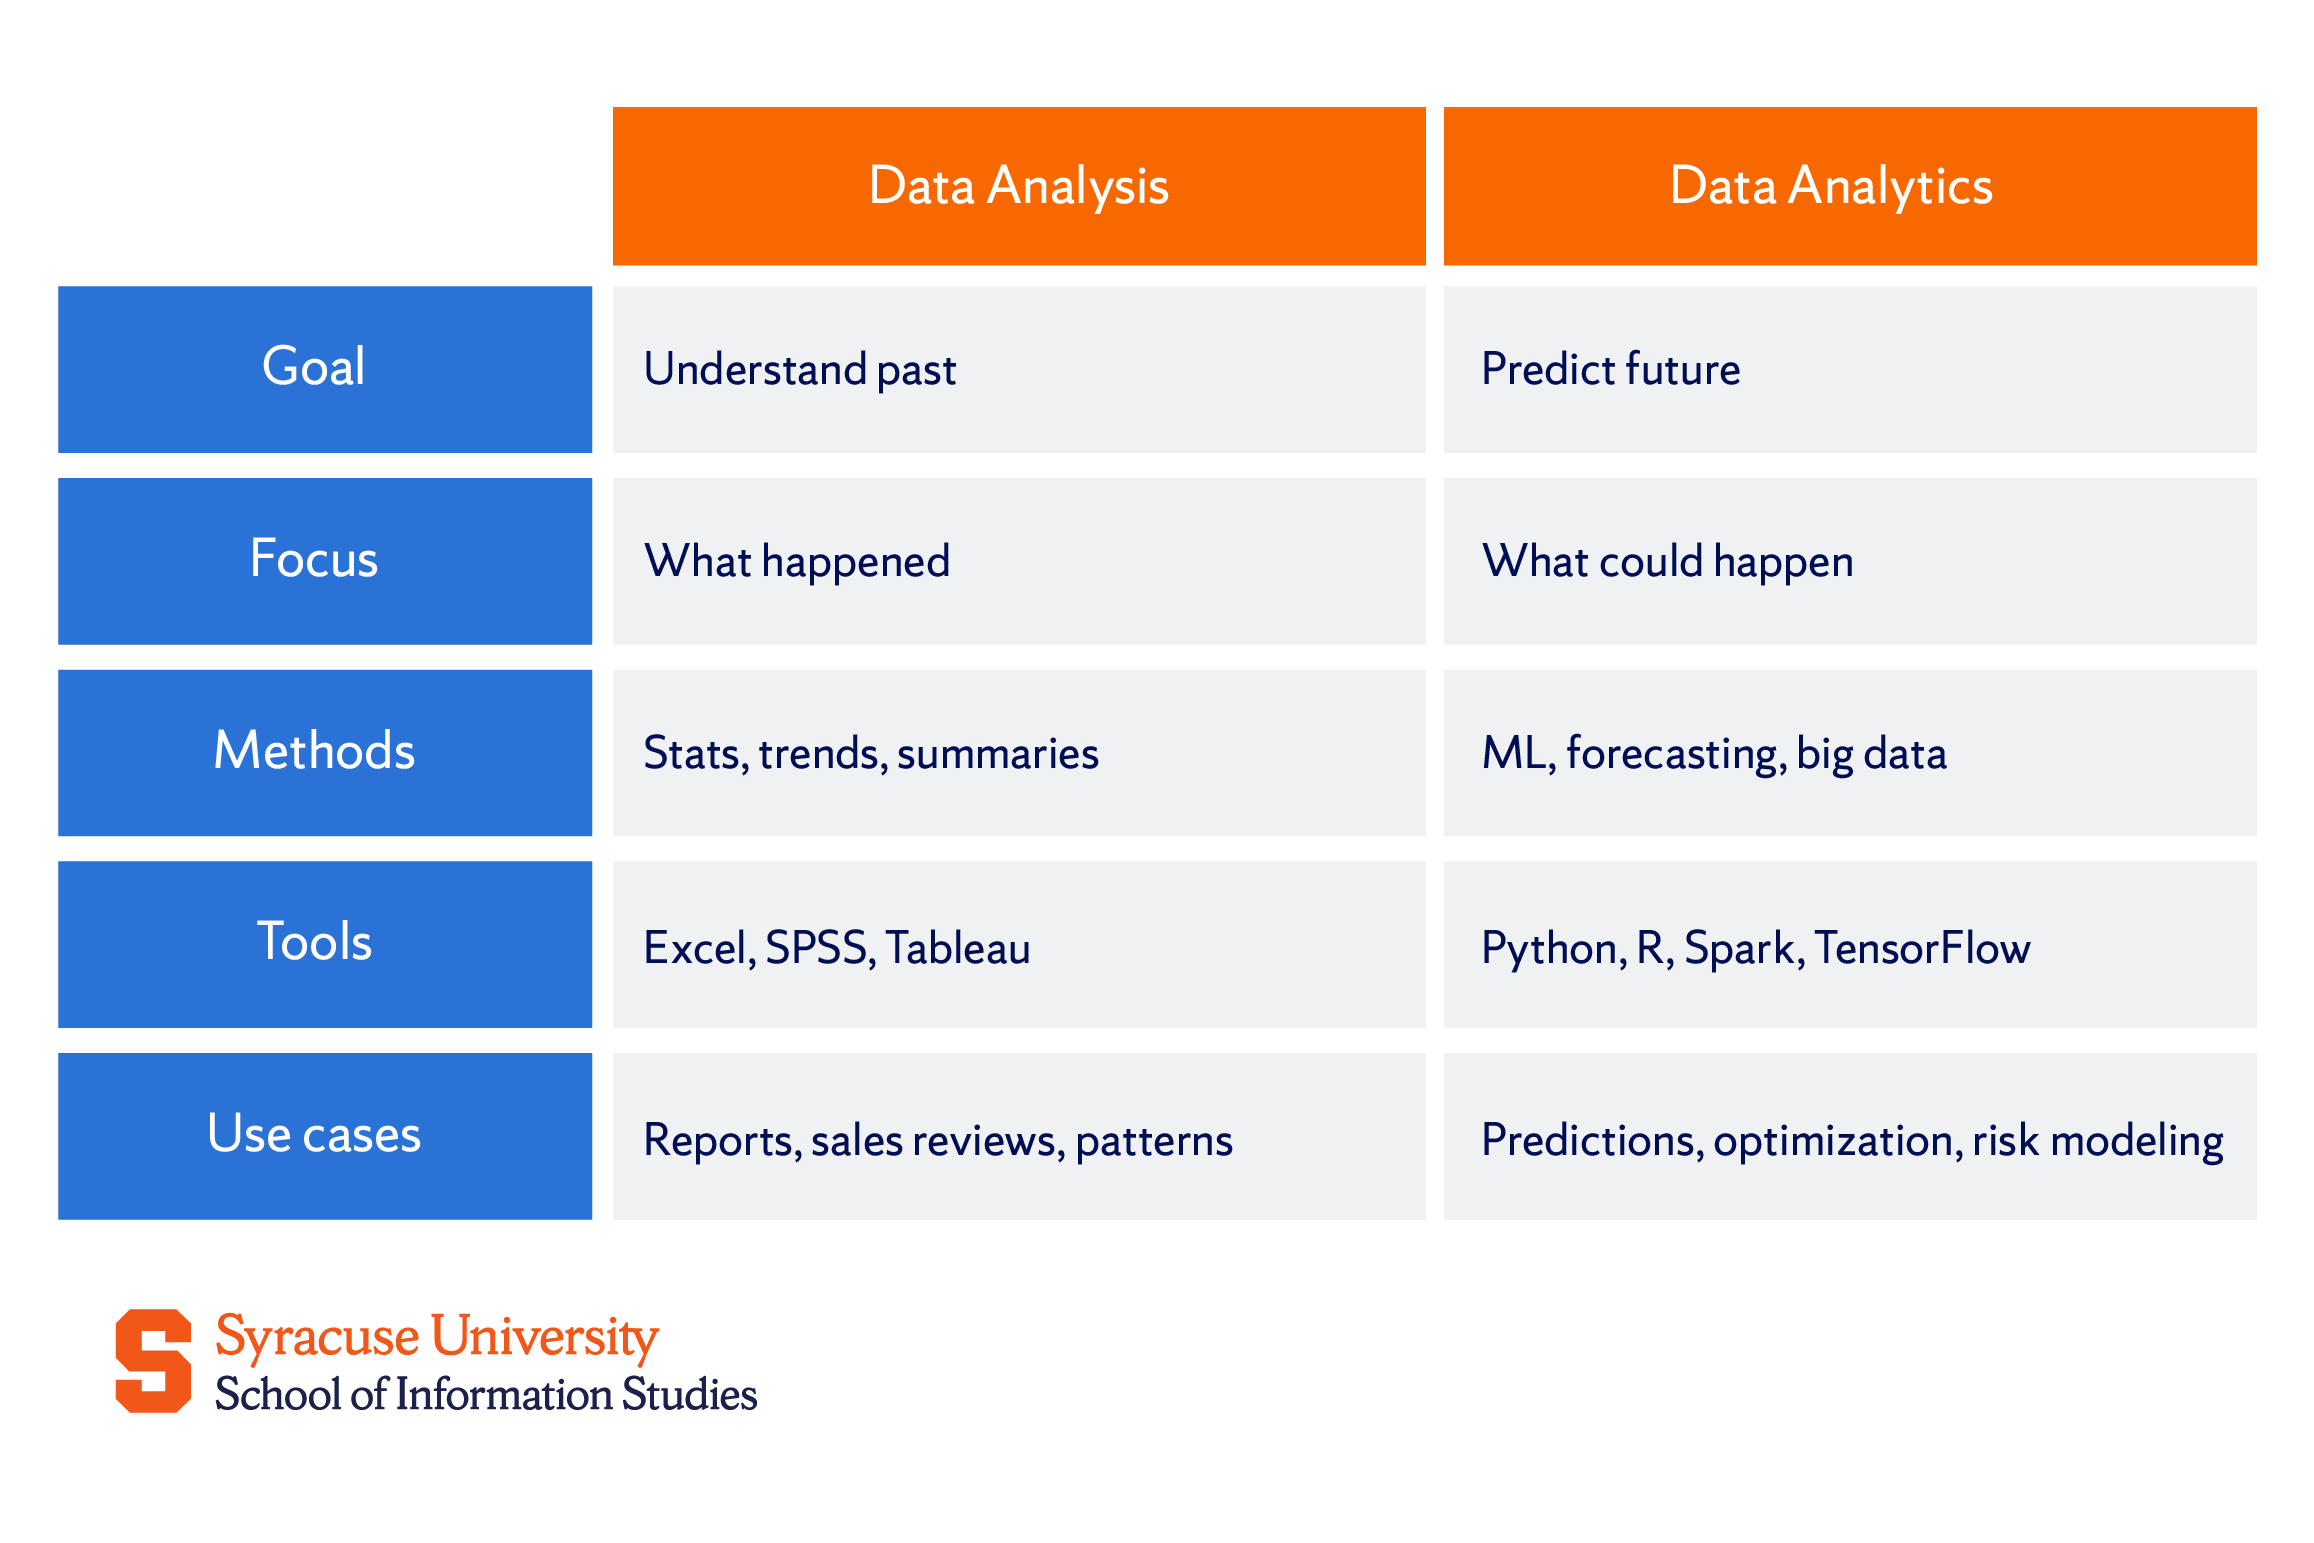
Data analysis is the narrower discipline. It takes existing data and describes what happened or why it happened. You clean the dataset. You check distributions. You write a query or run a pivot table. You produce a report or dashboard that answers a specific question: What were our Q3 conversions by channel? Why did churn spike in March? Data analytics is broader and more iterative. It encompasses analysis but also includes building models, designing experiments, setting up pipelines, and creating systems that keep answering new questions without starting from scratch every time. Analytics is the practice of turning raw data into ongoing decision support. Analysis is a single pass through that process. Most job postings don't separate them. They want someone who can do both and call it analytics.
The Workflow Nobody Talks About
Before anyone gets to insights, there is the actual work. Here is a practical sequence that works for most business datasets: Define the question clearly enough that you can state what a wrong answer looks like. Vague questions produce vague spreadsheets. "Improve our marketing" is not a question. "Which email subject line format drives the highest open rate for prospects who downloaded our whitepaper in the last 90 days?" is a question you can run a test against. Locate the data. This step takes longer than people expect. You will discover that the metric you need is defined differently in three systems. Sales reports it at close date. Billing reports it at invoice date. Product analytics reports it at account activation. Pick one source of truth and document the choice. Do this before you write any code.
Get the Full Details
Extract the data using a repeatable query, not a manual export. If you are clicking through a dashboard to download CSV files every week, you have built a fragility into your workflow. A SQL query or an API call that you can rerun in seconds is worth the hour it takes to write it once. Clean the data. This is where projects go to die. Handle missing values intentionally. Document why you excluded them. Filter out records that do not belong to the population you defined. Check for duplicates. Validate ranges. If a column called "age" contains the value 187, something is wrong and it is probably not a birthday database. Analyze. Descriptive statistics first. Distributions. Cross-tabs. Then move to whatever inferential or predictive technique matches your question. Do not skip to regression because a blog told you it looks impressive. If your question is descriptive, a well-built pivot table is the correct tool and it will finish in forty seconds.
Validate your findings against an independent subset or a sanity check from a different angle. If your analysis says revenue increased 300 percent after the site redesign, check whether the tracking implementation changed at the same time. Often it has. Communicate the result with the method attached. Not just the number. The method tells the reader whether to trust it.
Tools That Actually Matter
SQL. If you only learn one skill, learn this. It is the language of pulling data from the places where it lives. You do not need advanced window functions to get through 80 percent of real work. You need INNER JOIN, WHERE, GROUP BY, and a basic understanding of date functions. Pandas or equivalent. Once data leaves the database and enters your local environment, a DataFrame library gives you control over filtering, aggregation, and transformation without writing loops. It is fast enough for datasets up to a few hundred million rows on a decent machine. A visualization tool. Tableau, Power BI, or even Matplotlib if you prefer code. The goal here is not to make things look pretty. It is to create a representation that reveals patterns faster than a raw table does. If your chart requires a paragraph of explanation to make sense, it is not doing its job.
A statistics package when you need it. R or Python with Scikit-learn or Statsmodels. These are not required for everyday analysis but they become essential when you move beyond description into modeling or hypothesis testing.
Common Mistakes That Waste Days
Selection bias is the most damaging one because it hides itself. You analyze customers who respond to your survey and conclude they represent all customers. They do not. The people who responded likely had either a very strong opinion or too much free time. Both groups are unrepresentative. Correlation without mechanism. Two variables moving together does not mean one causes the other. I once saw a model correlate coffee shop density with startup valuations in a city and the team nearly shipped it as a strategic insight. Population density explained both variables. Removing it collapsed the relationship entirely. Overfitting validation metrics. Running a model on a single train-test split and reporting the accuracy as gospel. That number will degrade on new data. Use cross-validation or at least a time-based holdout set. In my experience, a model that scores 92 percent on a test set usually lands closer to 78 percent on production data unless the data distribution is remarkably stable.
Ignoring the unit of analysis. Aggregating transaction-level data to the customer level and then treating each row as independent when the same customer appears multiple times across segments. Your confidence intervals will be wrong. Your p-values will lie to you.

When Standard Methods Fail
Small sample sizes. Statistical tests assume certain distributions and adequate power. When you have fewer than thirty observations in a group, t-tests and ANOVA lose reliability. I have learned to default to non-parametric methods like Mann-Whitney U or bootstrapped confidence intervals in these cases. The results are wider and less exciting, but they are honest. Survivorship bias in event analysis. Looking only at users who completed a funnel and asking what made them convert. You miss the users who dropped off at step one. Fix this by including the drop-off population in your comparison group. The difference between converters and abandoners is usually more informative than the characteristics of converters alone. Time series with structural breaks. Seasonal models fail when a policy change, a pandemic, or a product launch shifts the baseline. Detecting these shifts matters more than fitting the prettiest curve. An intervention analysis or a simple pre-post comparison with a control group often outperforms a sophisticated ARIMA model in these scenarios because it does not assume continuity.
Setting Up a Practical Workflow
Create a project structure. I use directories for raw_data, processed_data, code, and output. Even a simple three-project setup keeps you from losing intermediate files and makes it possible for someone else to reproduce your work. Document the transformation steps in a single README or script so the chain from raw to final is visible. Use version control for your code, not just your outputs. Your analysis script is the asset. The CSV you exported last Tuesday is a snapshot that will not help anyone understand how you got there. Git handles this better than you think it will. Automate the boring parts. If you manually run the same SQL query and paste results into a template every Monday, write a script that does it. Python with a cron job or a simple Task Scheduler routine takes the repetition out of your week. The time savings are usually measured in hours per month, not minutes.
Keep a log of decisions. When you drop a column, remove an outlier, or switch a metric definition, write down why and when. Six months later you will forget and your future self will curse you for it. A five-line note in a text file prevents an hour of investigative confusion.
How to Evaluate Whether Your Work Is Useful
The quickest test is whether someone can act on your finding without emailing you for clarification. If the answer requires a meeting to explain, the analysis has not reached completion. Actionable means the reader understands what changed, by how much, and what you recommend they do next. Another test is reproducibility. Give your code and a description of your data source to a colleague and ask them to rerun it. If they cannot get the same result within an hour, your process needs tightening. This is not about paranoia. It is about making sure your conclusions survive contact with reality. A third test is falsifiability. Can you state in advance what result would prove your hypothesis wrong? If not, you are not doing analysis. You are collecting evidence that supports a conclusion you already wanted.
A Real Example From My Own Work
Recently I was asked to identify which onboarding steps predicted long-term retention for a SaaS product. The first dataset looked clean enough. I ran a survival analysis and found that users who completed the profile setup within twenty-four hours had a 68 percent retention rate at ninety days compared to 41 percent for those who took longer. The result felt solid. Then I checked whether the two groups differed in other ways. They did. The fast completers were primarily from a referral program that also included a personalized welcome call from a human. The slow completers were mostly organic signups with no human contact. The twenty-four-hour threshold was not the cause. The welcome call was. I reran the analysis controlling for the touchpoint type. The effect of speed within each group dropped to statistical noise. The actionable insight shifted from "make onboarding faster" to "assign a human touchpoint during onboarding and let speed be secondary." The recommendation changed completely because I took the time to check the confounder. Skipping that step would have sent the product team down a costly optimization path that addressed the wrong lever.
Where to Start If You Are New
Begin with a real dataset you care about. Not the Iris dataset. Something that actually exists in your work or hobby. Customer records, personal finances, sports statistics, public government data. The emotional connection to the subject keeps you going when the cleaning phase gets tedious. Learn SQL before Python. It forces you to think about structure and relationships instead of jumping straight into visualization. You will encounter cleaner data after you know how to pull it correctly. Beginners who start with dashboards often build beautiful charts on messy sources and do not realize the mess until the numbers stop adding up. Read documentation instead of watching tutorial videos for edge cases. Tutorials show the happy path. Real problems live in the FAQ sections and the issue trackers. When your join returns duplicate rows or your date conversion fails on a specific format, the answer is rarely in a five-minute video. It is in the official docs or a Stack Overflow thread with twenty upvotes and a detailed explanation.
The Honest Bottom Line
Data analytics and data analysis are not glamorous. They are mostly patient debugging, careful reading, and repeated checking of assumptions. The people who seem to produce brilliant insights on schedule usually spent most of their time making sure the foundation was not cracked. If you build habits around clear questions, documented processes, and honest validation, your work will be reliable. Reliable work is what gets used. Insightful work that cannot be reproduced does not.
