What a Data Lake Actually Looks Like When You Build One
A data lake is a storage architecture that holds raw and processed data in its native format until it is needed. Most people oversell this concept. They describe it as a magical solution where you throw everything in and the analytics team finds answers. In practice, a data lake is just cheap object storage with pipelines that feed it. The technology stack around it is what makes it usable or makes it a total mess. I helped architect a Data Lake Technology Stack for a logistics company a few years back. We were ingesting GPS telematics, weather feeds, driver logs, and warehouse inventory data all at once. The biggest headache wasn't ingestion. It was schema drift on the GPS side. One supplier changed their JSON payload structure without announcing it. All our downstream transformations broke silently for about six hours. Half a million records went into the lake with mismatched field names. We caught it because I had written a validation check that compared the hash of incoming records against a baseline from the previous day. That check should have been there from the start. It wasn't, which is the real story here.
The Actual Components You Need
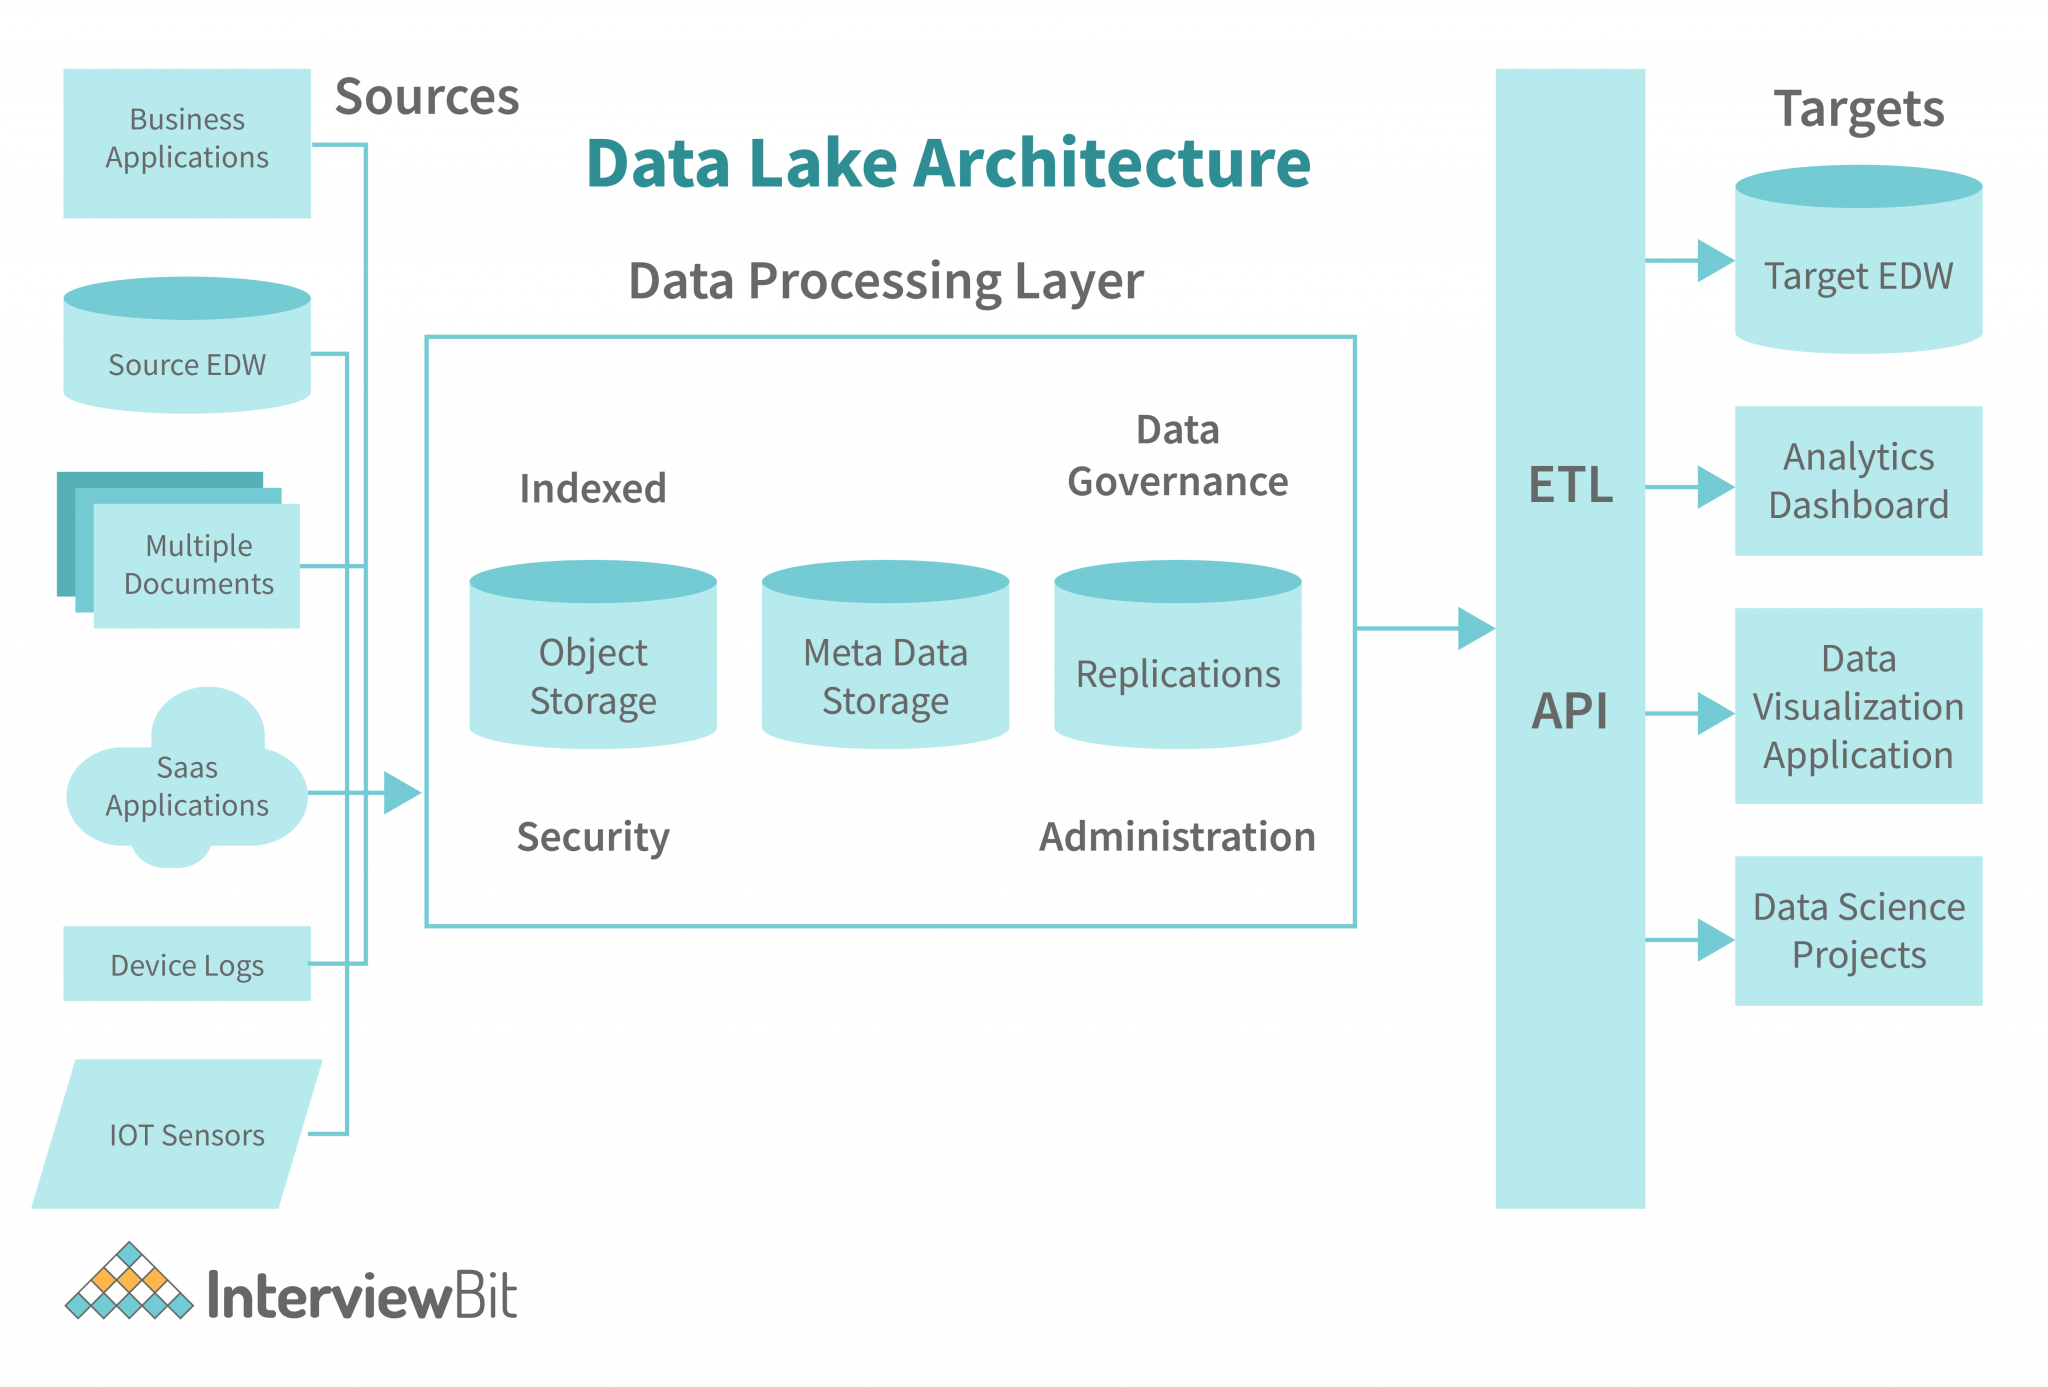
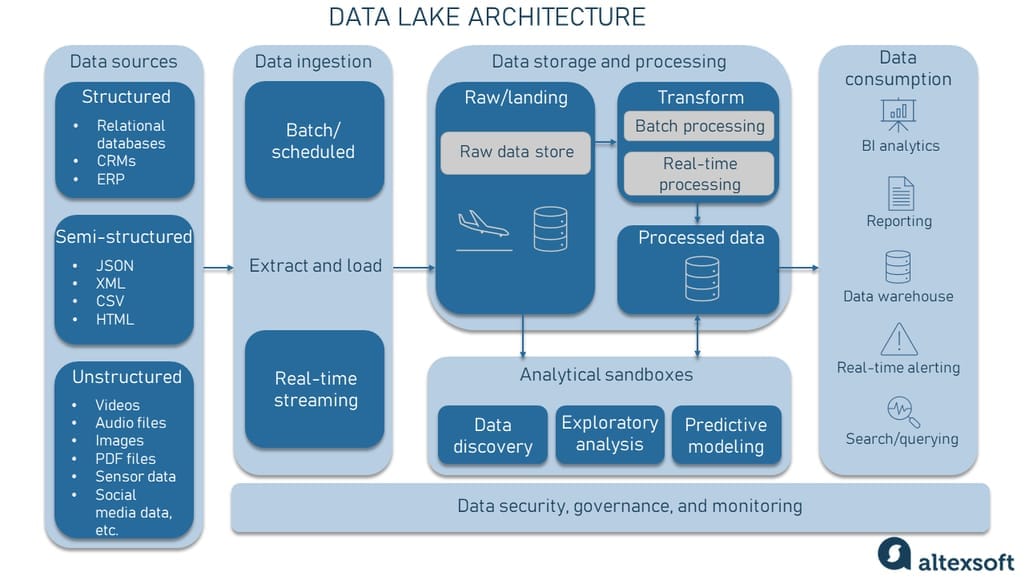
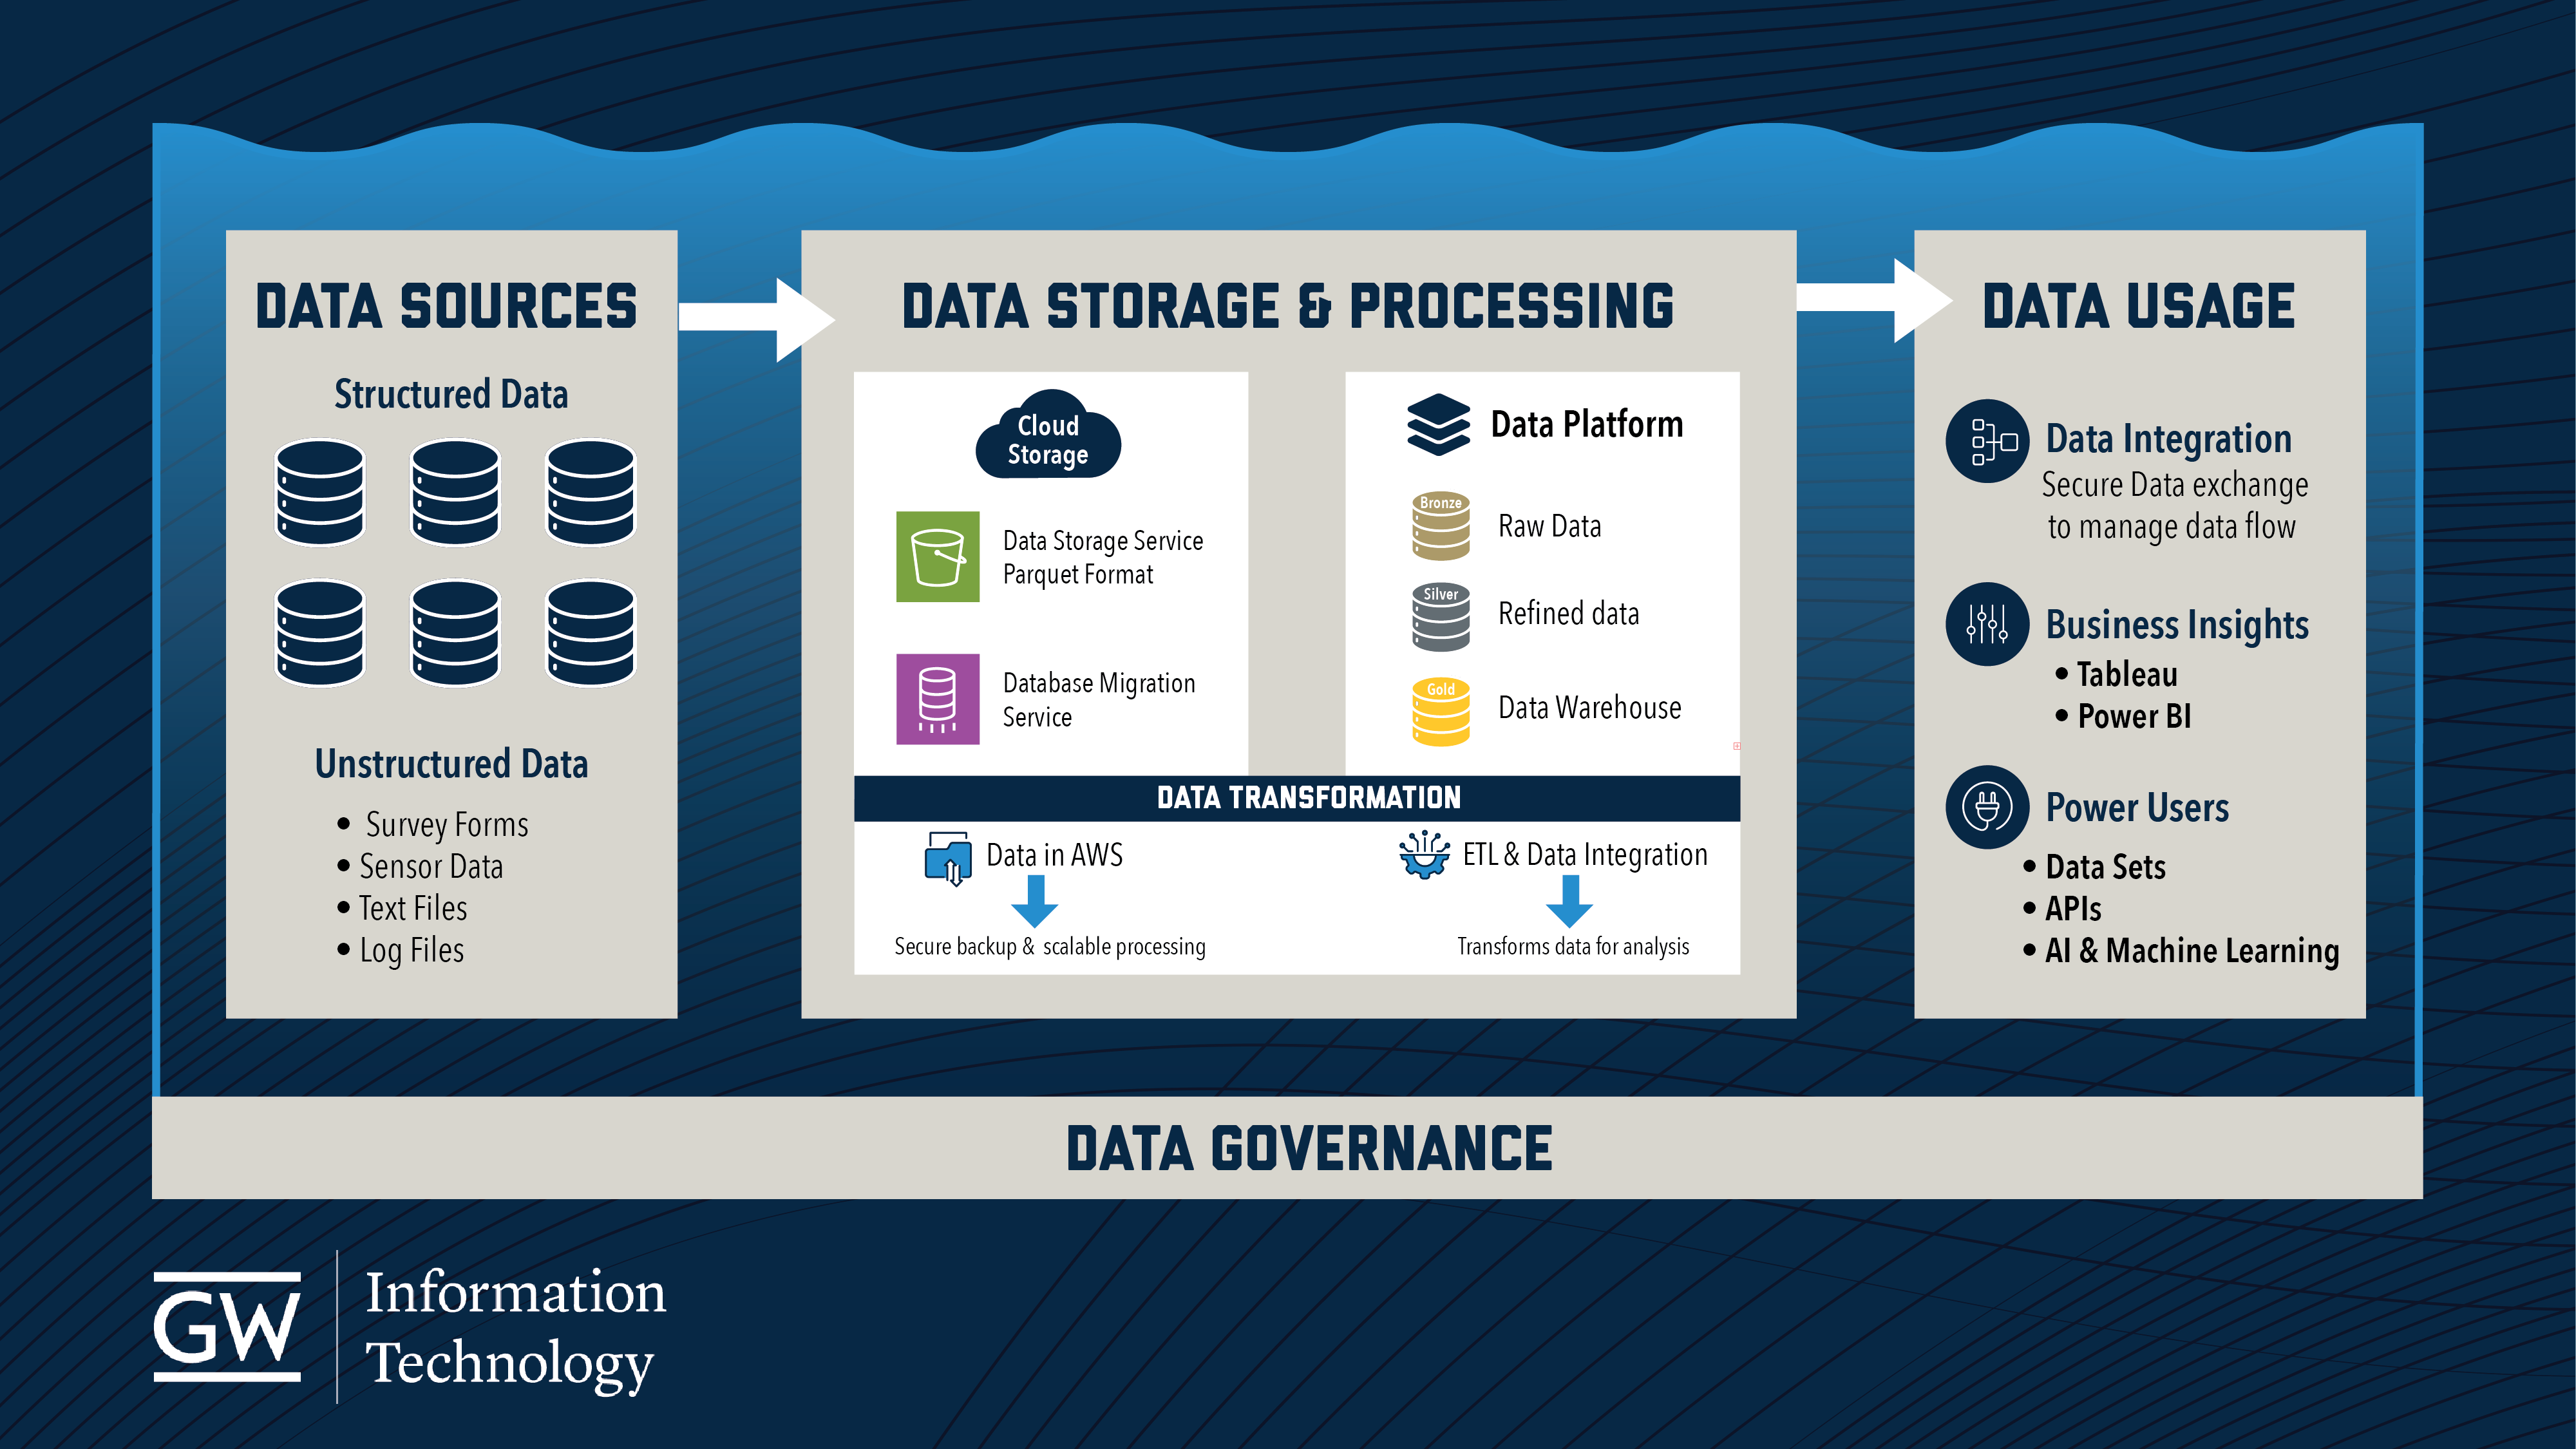
Let me walk through the layers. At the bottom you have object storage. AWS S3, Azure Blob, Google Cloud Storage. Pick one based on where your infrastructure already lives. Don't overthink this decision. The cost difference between them is negligible for most workloads. I've seen teams burn weeks debating storage vendors when they should have just spun up the cheapest option and moved on. Above that sits your ingestion layer. Apache Kafka handles real-time streaming. Apache NiFi works for batch flows with some routing logic. If you are pulling from databases, Debezium is solid for change data capture. For a one-time historical load, something simple like a Python script with pandas might be enough. I once used a basic Apache Spark job to backfill three years of transaction data into a lake. It took four hours and cost about sixty dollars in compute. Not exactly elegant, but it worked. The metastore is where things get interesting. Apache Hive, AWS Glue Data Catalog, or Delta Lake's built-in catalog. This is what gives your raw files any structure at all. Without a metastore, your lake is just a bunch of orphaned files that nobody can query efficiently. I spent two weeks debugging a query that kept failing because the metastore had stale partition information. The data was there. The catalog just didn't know about it. Re-registering the partitions fixed it immediately. This happens more often than you would expect.
For processing, you have options. Apache Spark is the default for heavy lifting. dbt works well if your team already knows SQL. Trino or Presto gives you interactive querying across multiple sources. Apache Flink is worth considering if you need true stream processing with state management. Each of these has trade-offs. Spark is powerful but resource hungry. Trino is fast for ad-hoc queries but struggles with writes. Flink is excellent for complex event processing but has a steep learning curve. Orchestration ties it all together. Apache Airflow is the most common choice. Prefect and Dagster are modern alternatives with better developer experience. I switched our team from Airflow to Prefect because we were hitting limitations with Airflow's scheduler under high task concurrency. The migration took about three days. Not great, not terrible.
Get the Full Details

What Nobody Tells You About Data Lakes
Here is a counter-intuitive point. The raw ingestion layer should be immutable. Once data lands in the lake, nobody should modify it. I know this sounds extreme. It creates problems when you need to fix bad data. The right approach is to write corrections as separate records in a different path, not to overwrite the original. This way you maintain an audit trail and can reproduce any analysis at any point in time. Another thing that catches people off guard. Data lakes don't solve data quality problems. They amplify them. When you can store everything cheaply, people store everything. Soon you have terabytes of logs, temporary files, and abandoned experiment data clogging your system. We had a project where 40 percent of the storage was occupied by data that nobody knew how to classify. Setting up retention policies and lifecycle rules from day one would have prevented that. We learned the hard way. The biggest pitfall I see is treating the lake as a dumping ground and hoping governance happens later. Governance cannot be an afterthought. You need to decide on naming conventions, partitioning strategies, and access controls before you ingest the first record. I recommend starting with a simple contract. Every dataset needs a owner, a schema definition, and a freshness SLA. Without these three things, your lake becomes untrustworthy within months.
When a Data Lake Is the Wrong Choice
Data lakes fail when your data is highly structured and your queries are predictable. If you are running the same five reports every morning on clean relational data, a data warehouse is faster and cheaper. Looker, Snowflake, BigQuery, Redshift. These platforms handle structured analytics better than a lake plus a query engine. You are paying for flexibility you don't need. Lakes also struggle with small datasets. If you are dealing with less than a few terabytes, the overhead of a full lake architecture outweighs the benefits. A well-designed relational database will serve you better and require less maintenance. The storage cost advantage of object storage disappears at that scale. There is also the human factor. A data lake requires discipline. Engineers need to understand partitioning, serialization formats, and catalog management. If your team is small or new to this space, the learning curve can delay projects by months. I have seen startups attempt a full lake implementation with a team of four people and end up abandoning it after six months. They ended up building a much simpler ELT pipeline with dbt and a cloud warehouse, and it worked perfectly for their needs.
If you are going to build a lake, start small. Ingest one data source. Get the pipelines, the catalog, and the query layer working end to end. Then add the next source. The tendency is to design the perfect architecture on paper and then try to implement it all at once. That rarely works. The logistics company I mentioned started with just the GPS telemetry. We spent two months getting that pipeline to production quality before touching anything else. By the time we brought on the weather and inventory data, the patterns were familiar and the deployment was straightforward. The technology choices matter less than the process. Pick tools that your team can actually operate. A slightly less powerful tool used well beats a best-in-class tool that sits unused because nobody knows how to configure it properly. I have seen this pattern repeat across countless projects. The tool is never the bottleneck. The bottleneck is always the team's familiarity with the tool.
Monitoring and What to Watch
You need observability from day one. Track ingestion latency, record counts per source, and schema changes. Set up alerts for when a pipeline falls behind schedule or when record counts drop below expected thresholds. I once missed a failed ingestion job for three days because there was no alerting. The data was simply missing from the dashboard, and nobody noticed until someone asked why the numbers looked wrong. For data quality checks, Great Expectations and dbt tests are both reasonable choices. Don't skip this step. I have pulled reports from lakes where the underlying data was silently corrupted, and the corruption had been there for weeks. The numbers looked plausible. Only a deep dive revealed the issue. Automated quality checks catch these problems before they become expensive to fix. Storage costs tend to grow faster than expected. Enable lifecycle policies that move infrequently accessed data to cooler storage tiers. We reduced our monthly storage bill by about thirty percent just by moving data older than ninety days to the cheaper tier. The access time increased marginally, but nobody complained because the data was rarely queried.
If you want to explore the ecosystem further, the open source projects I mentioned are all available on GitHub. Apache Spark, Apache Kafka, Apache Airflow, Debezium, Trino. Each has extensive documentation and active communities. The official sites are the best starting points for setup guides and configuration references. There are also managed alternatives for most of these if you prefer not to self-host. Confluent for Kafka, Databricks for Spark, Astronomer for Airflow. These cost more but save operational overhead. The reality of building a Data Lake Technology Stack is that it is mostly about plumbing. Getting data to move reliably from point A to point B, in the right format, at the right time. The glamorous parts are the analytics and the dashboards. But those only work if the foundation is solid. Spend your energy on the foundation. Everything else follows.