The actual work behind cleaning and transforming data
Data Manipulation Practice is less about learning a syntax and more about developing patience for the gaps between what your dataset looks like and what it needs to become. I spend most of my time dealing with CSV exports from legacy systems where dates shift between formats mid-column, strings contain embedded newlines that nobody bothered to escape, and numeric fields occasionally hold text values because someone typed "N/A" directly into a spreadsheet three years ago. The first thing most people get wrong is thinking this is linear. It isn't. You load a file, you try a transformation, it fails because of a single bad row, you debug, you adjust, you rerun, and only then do you realize the real problem started upstream when the data was collected. I had a pipeline break recently because a partner organization switched their API response format from camelCase to snake_case without updating their documentation. Six columns of data suddenly appeared empty. The fix wasn't complex, but tracing it back through five intermediate transformations took about four hours of manual spot-checking. Now I validate schema shapes at every stage boundary and log mismatches immediately rather than letting them propagate silently.
Data Manipulation Practice for real datasets
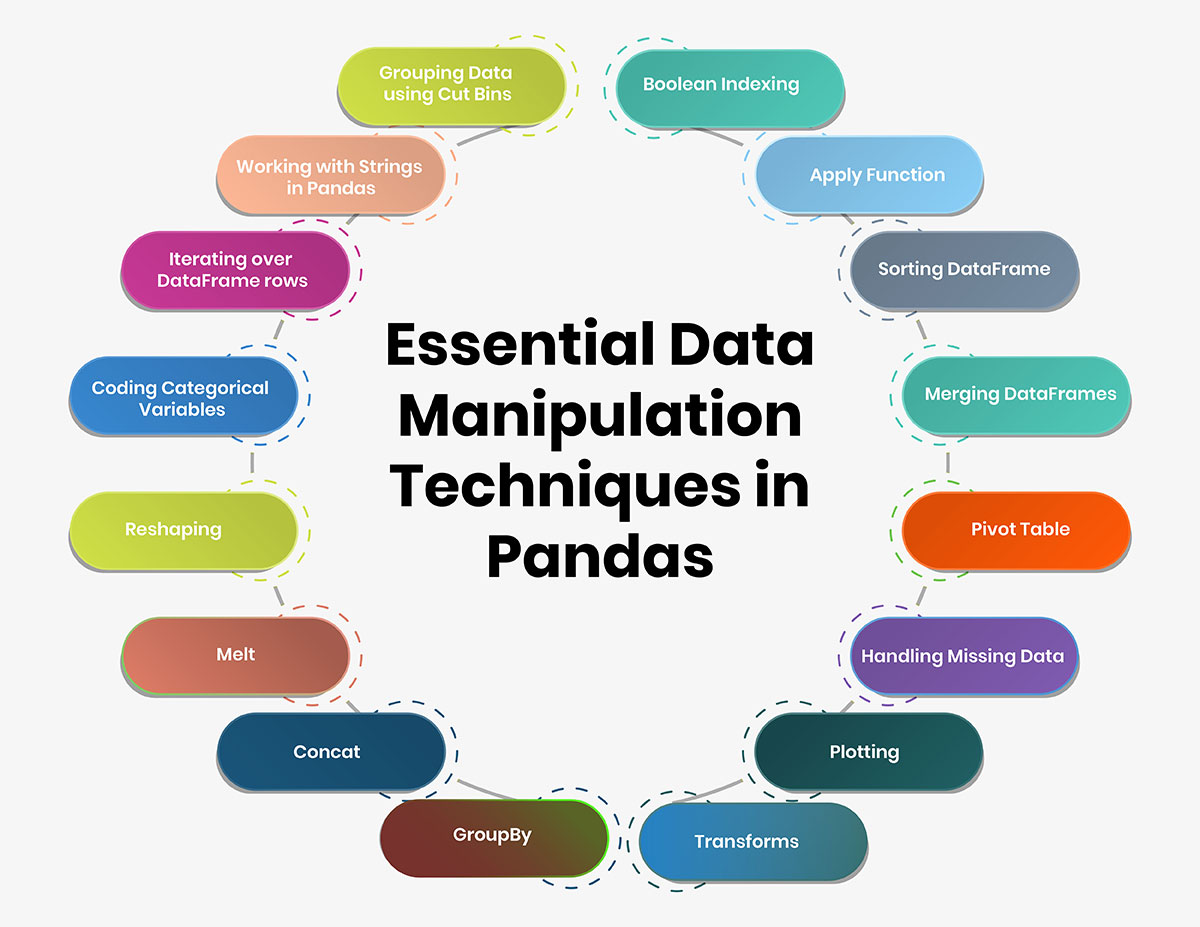
Start by understanding the shape of your data before you write a single line of code. A quick exploratory pass using head counts, null distributions, and unique value counts per column saves far more time than rushing into aggregation logic. In pandas, that's roughly df.shape, df.isnull().mean(), and df.nunique() across each column. For any dataset over a million rows, use sampling. Reading the entire thing just to check types is wasteful and unnecessary. When you handle type coercion, be explicit about it. Don't let pandas infer types on read. Call pd.read_csv() with a dtypes dictionary or use pd.to_numeric() with errors='coerce' so invalid values become NaN instead of throwing exceptions that kill your entire script. I learned this the hard way on a project where a single malformed currency field containing a dollar sign and comma simultaneously turned an entire column into object type, which then broke a merge operation downstream. Converting with error coercion resolved it in a single line. Merging is where most people introduce bugs. When joining two datasets, always verify the join keys exist in both sides and check cardinality. A many-to-many merge on poorly scoped keys can silently duplicate rows and inflate your record count by ten or hundred times. Before any merge, run a count comparison on the key column in each dataframe. If df1[key].nunique() doesn't match the grouping in df2, you're looking at a one-to-many relationship, not a clean primary-foreign key pair.
Vectorization matters more than people admit. Looping through rows with iterrows or apply on a row axis is slow. For a column of strings, use str.replace() and str.contains() instead of applying a lambda. For arithmetic operations, use the built-in vectorized methods. On a dataset with two million rows, this difference typically means the distinction between finishing a transformation in thirty seconds versus forty minutes. Handling missing data deserves more care than most tutorials give it. Dropping NaN values indiscriminately is a common mistake, especially in time-series or transactional data where the absence of a value itself carries information. The right approach depends on context. If a column represents a measurement where absence means the sensor simply didn't record anything, forward-fill or interpolation makes sense. If it represents a categorical field where "not applicable" is meaningful, keep it as its own category. I once worked with a customer churn dataset where dropping missing values in the "last_contact_date" column removed the entire segment of customers who had never been contacted, which was exactly the group the analysis was supposed to target. The model performance degraded noticeably after that cleanup. When reshaping data between wide and long formats, use pd.melt() and pd.pivot() or pivot_table() rather than manual rearrangement. These functions handle the index and column reassignment cleanly and are harder to get wrong. The reshape operations also make it easier to feed data into plotting libraries or statistical models that expect a particular orientation.
Get the Full Details
One thing beginners consistently overlook is performance trade-offs with different data structures. A standard dataframe works fine for datasets up to around a hundred thousand rows. Beyond that, consider using polars or dask depending on whether your bottleneck is speed or memory. Polars handles out-of-core operations gracefully and its expression-based API is faster for group-by aggregations on large splits. The learning curve is steeper, but the runtime improvement is noticeable on datasets above a million rows. Writing clean transformation code means treating each step as a reversible operation. Keep your source data untouched and create new columns incrementally. If a transformation breaks later, you want to be able to trace back without reprocessing everything from scratch. I structure my scripts so that each major transformation block is separated by a checkpoint save, usually as a parquet file, so I can reload and continue without rerunning earlier steps. Parquet is preferable to CSV for intermediate storage because it preserves data types and compresses well, which cuts both read and write times significantly on large datasets. Validation at the end matters too. After all your manipulation is done, run summary statistics again and compare them against expected ranges. If your revenue column suddenly shows negative values where none should exist, or your date range extends beyond the collection period, something went wrong in a transformation you assumed was safe. Automated checks that flag deviations from baseline statistics can catch these issues before they reach a report or dashboard.