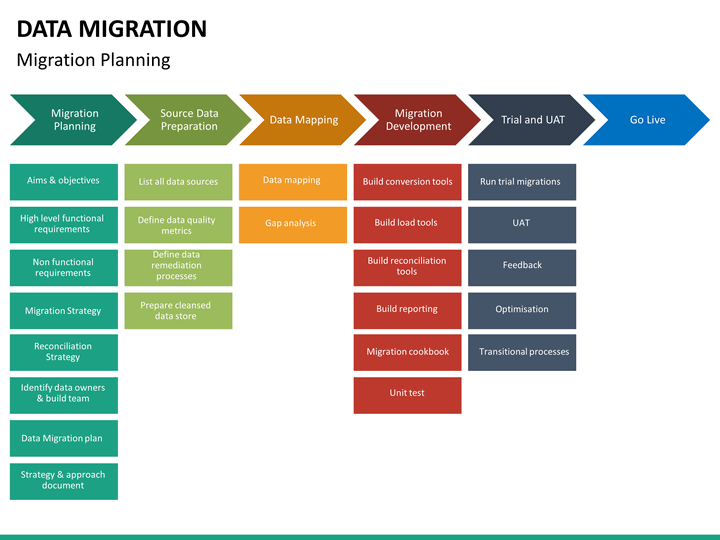
Mapping Data Migration Like a Boring Spreadsheet, or It Will Haunt You Later
The actual work of a data migration is rarely the move itself. It's the mapping. I learned this the hard way during an ERP upgrade where we spent three weeks on ETL pipelines and one week on a CSV file that should have taken two days. A Data Migration Mapping Template is essentially a structured spreadsheet or document that defines the relationship between source fields and target fields, along with the transformation rules needed to bridge the gap. It's not glamorous, but it's the single most important deliverable in any migration project. Without one, you'll be staring at a corrupted database at 2 AM trying to figure out why customer names appear as "LastName FirstName" instead of "FirstName LastName."
Building a Data Migration Mapping Template That Actually Works
Set up a spreadsheet with these columns: Source System Name, Source Field Name, Source Data Type, Target System Name, Target Field Name, Target Data Type, Transformation Rule, Validation Notes, and Confidence Level. That's it. Don't overcomplicate it. Every extra column just becomes noise you ignore after week one. The real value isn't in the structure. It's in filling in the transformation rules with enough detail that someone else can execute them without asking you questions. "Trim whitespace" is not a sufficient transformation rule. "TRIM function on the left and right of the string, then replace consecutive spaces with a single space" is. Specificity prevents rework, and rework is where projects die. Here's a practical example I ran into recently. We were migrating from a legacy CRM built in 2003 to a modern platform. The source had a single field called "Full Address" containing strings like "123 Main St Apt 4B, Springfield, IL 62704." The target system required five separate fields: Street Line 1, Street Line 2, City, State, Postal Code. A naive mapping would attempt a simple regex split, and about forty percent of the records would fail because the formatting varied wildly—some entries had "Apt" instead of "Apt," others used "#4B," and a few had no apartment number at all.
The workaround was to write a custom parsing script that checked for common apartment/unit indicators first, extracted the postal code from the end using a pattern match, and dropped everything else into Street Line 1. Records that still couldn't be parsed went into a rejection queue for manual review rather than silently corrupting the target. That rejection queue saved us from importing 200 malformed addresses that would have broken our shipping integrations downstream. One thing most people miss when building their mapping template: they map the obvious fields first. Names, emails, phone numbers, dates. These are usually straightforward. The fields that destroy migrations are the ones nobody thinks about until it's too late. Internal status codes, for example. One system might use "A" for Active, "I" for Inactive, and "D" for Deleted. The other uses 0, 1, and 2. If your mapping template doesn't explicitly document this numeric-to-letter conversion, the target system will either reject the data or set every record to Active because the default for an unmapped integer field is often zero. Another counter-intuitive insight: data type mapping matters more than field name mapping. You can have perfect field alignment, but if the source stores dates as text in MM/DD/YYYY format and the target expects ISO 8601 (YYYY-MM-DD), your migration will either fail or produce garbage dates. Always document the data type on both sides and specify the exact transformation. Don't assume the ETL tool will handle it. Most tools handle simple conversions, but edge cases like date formatting and decimal precision require explicit rules.
Get the Full Details

The biggest limitation of any mapping template, spreadsheet-based or otherwise, is scale. Once you exceed roughly fifty field mappings with unique transformation rules, the spreadsheet becomes impossible to maintain. At that point, you're better off moving to a dedicated data integration platform like Talend, Pentaho, or even a custom Python script with a JSON configuration file. Spreadsheets work fine for small-to-medium migrations with under thirty fields and simple transformations. Beyond that, the overhead of keeping the template in sync with the actual migration logic outweighs the simplicity. There's also the issue of evolving source data. If the source system changes its schema mid-migration—which happens more often than you'd think because business units decide to add fields or rename them—the mapping template becomes stale. I've seen projects where the source team added a new required field two weeks before go-live, and because it wasn't in the mapping template, it got dropped silently. Always include a version column in your template and a change log. When something shifts, update both immediately. For those starting out, here's a minimal template you can copy into any spreadsheet application:
Row 1: Headers — Source System, Source Field, Source Type, Target System, Target Field, Target Type, Transformation Rule, Validation Method, Confidence (H/M/L), Notes Row 2+: One row per field mapping. Fill in each column before moving to the next field. Don't skip the Validation Method column. This is where you document how you'll verify the mapping is correct—sample query, record count comparison, spot-check against source records, or automated test script. Confidence levels help you prioritize review effort. High confidence means the mapping is straightforward and well-understood. Low confidence means it's unclear, complex, or based on assumptions that need validation. Focus your testing time on the low-confidence mappings. That's where the problems live.
The template itself won't save you from a bad migration. But a well-maintained one will catch issues before they hit production, and that's the difference between a smooth cutover and a weekend spent restoring from backup.