How to Build a Practical Data Warehouse Without Losing Your Mind
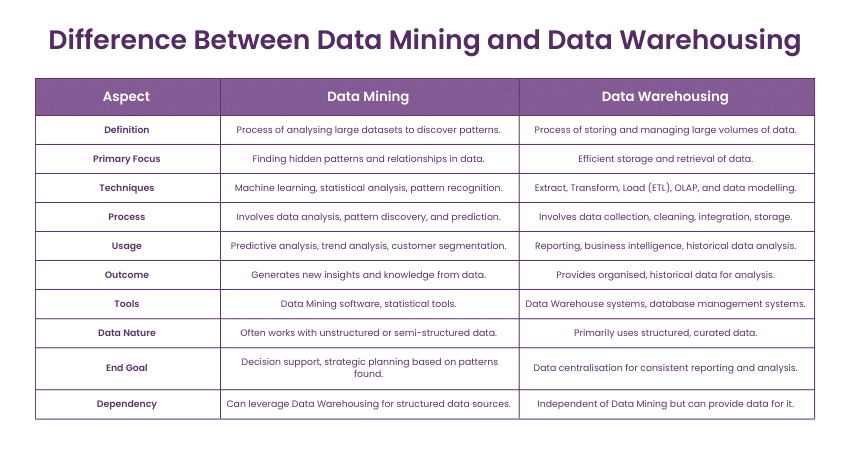
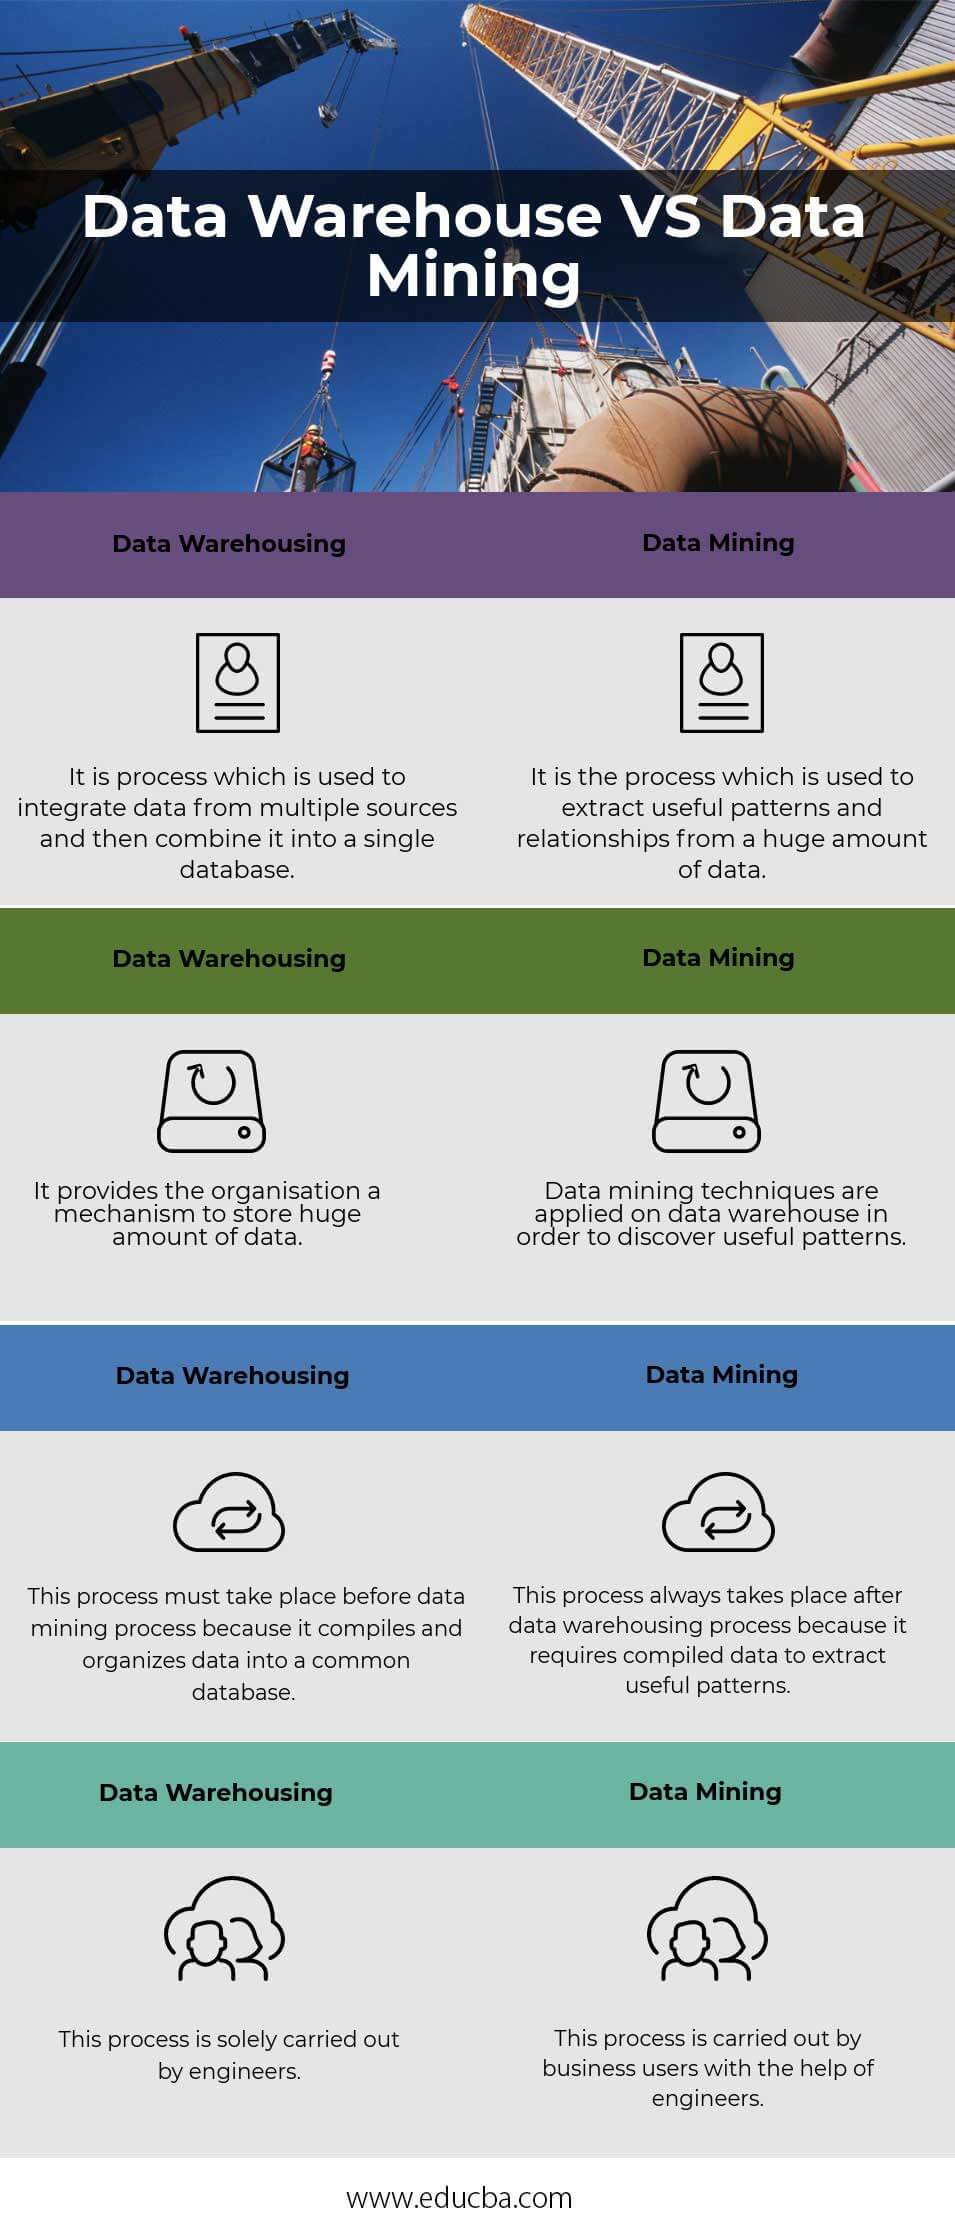
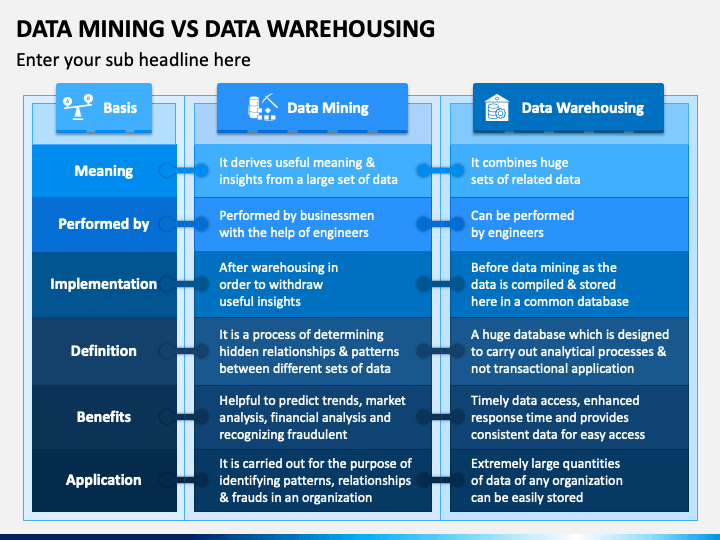
I spent three months trying to force a snowflake schema onto a project where a star schema would have been the obvious answer. The queries ran acceptably for a while, then degraded into something unholy once the facts table crossed 400 million rows. Here is what I learned doing it wrong so you don't have to. Data Mining And Warehousing works by separating the heavy analytical queries from the operational ones. Your OLTP database is doing something like processing transactions, while your warehouse is designed to scan millions of records across multiple joins. Mixing them in the same system is the first mistake I see, and it is almost always a painful mistake.
ETL Pipeline Setup for Small to Medium Datasets
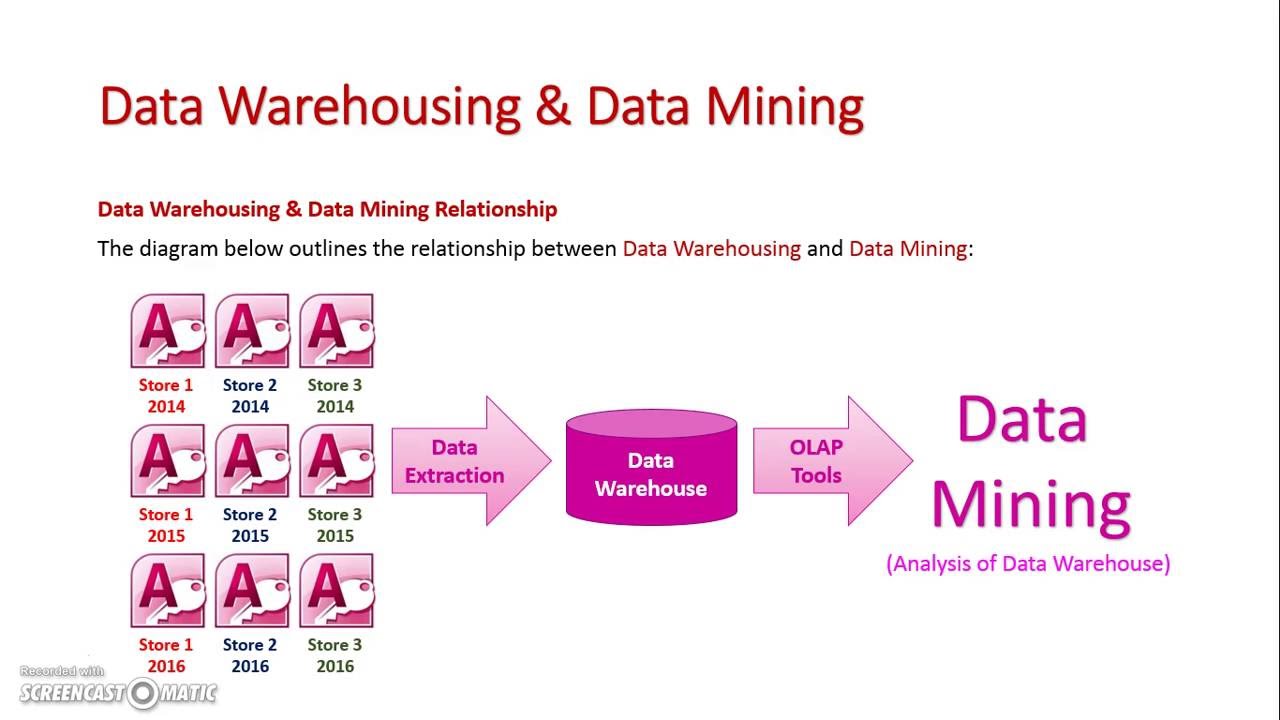
Start with a simple extract-transform-load pattern. I typically use Python with pandas for the transform layer when the data volume stays under fifty million rows. Beyond that, you want to move to something like Apache Spark or at minimum a proper SQL-based transformation engine running inside the warehouse itself. The difference between doing transformations in application code versus letting the database handle them is not trivial. It is the difference between an ETL job that finishes overnight and one that finishes at lunchtime the next day. For extraction, avoid querying your production database directly during business hours. I set up a read replica or use a change-data-capture tool like Debezium to pull only what changed. This alone cut our warehouse refresh time from roughly forty-five minutes per run down to about eight minutes because we were no longer scanning entire tables. The setup cost is higher upfront, but the ongoing savings are real.
The Core Architecture: Schema Design
Most beginners jump straight into building tables without deciding on a schema first. A star schema is usually the right call. You have a large fact table surrounded by smaller dimension tables. The fact table contains the numerical measurements and foreign keys. The dimension tables contain the descriptive attributes. This layout aligns naturally with how analytical queries actually work, which is filtering on dimensions and aggregating the facts. There is a common assumption that data mining means just running algorithms on the warehouse data. In practice, it means cleaning and transforming data to a point where your mining or modeling queries don't break. Garbage in, garbage out is an oversimplification, but it is not wrong. I once spent two weeks fixing data quality issues that originated from a third-party API returning null values in completely random patterns. The workaround was to add a data quality validation step at the ingestion boundary that flagged and quarantined rows with suspicious patterns before they ever reached the warehouse. It added about four minutes to each extraction cycle, which was cheaper than the alternative.
Get the Full Details
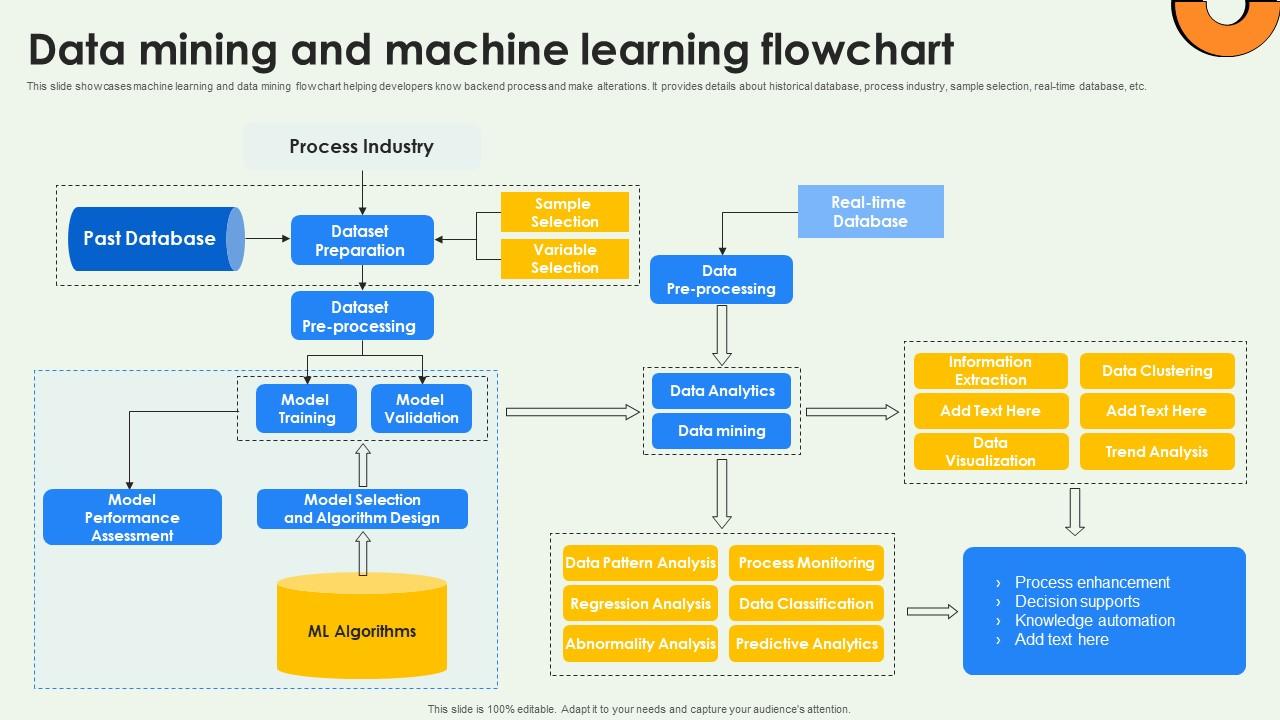
Data Mining And Warehousing in Practice
Once your warehouse is built, the data mining part involves querying it with analytical workloads. This is where most people get stuck because they treat analytical queries the same way they treat transactional queries. They are not the same. Analytical queries scan large portions of the data and perform aggregations across multiple rows. Transactional queries look up specific records. You optimize for different things entirely. Partitioning your fact tables by date is one of the most effective and underutilized techniques. When you partition a table by month, queries that filter on a single month can skip reading most of the data. I have seen full analytical scans drop from four minutes to twelve seconds after adding proper partitions. The tradeoff is that writes become slightly more complex, but for a warehouse, reads vastly outnumber writes, so this is almost always worth it. Indexing in a warehouse is different from indexing in an OLTP system. You do not want many small indexes. Indexes cost space and slow down bulk inserts. Instead, use columnar storage if your warehouse engine supports it, and rely on partition pruning and bitmap indexes for low-cardinality dimension columns. A good rule of thumb is to keep indexes only on the columns that appear most frequently in your WHERE clauses, and even then, measure whether the index is actually helping before trusting the query planner to make the right choice.
Common Pitfalls That Will Waste Your Time
One counter-intuitive issue is over-normalization. Normalization is great for transactional databases because it prevents update anomalies. In a warehouse, every join is a performance hit. It is almost always better to denormalize dimension attributes and repeat them across fact rows. The storage cost is negligible compared to modern disk, and the query performance gain is significant. A fact table with six joins to dimension tables will feel noticeably slower than one where those same attributes are duplicated directly in the fact table. I measured this difference on a dataset with roughly twelve million rows and saw query times drop from 2.3 seconds to 0.7 seconds after denormalizing three of my five dimension joins. Another issue is slow-growing dimensions. These are attributes that change very infrequently, like a customer's country or a product category. People often treat them the same as regular dimensions, but they can cause unnecessary complexity in your fact table over time. The standard approach is Type 1 slowly changing dimension handling, which simply overwrites the old value. This keeps your fact table lean. Only use Type 2 tracking when you actually need the historical record of changes, and be honest about whether you need that. Most projects do not.
Tools and Implementation Path
For a practical stack, Airbyte or Meltano handles the extraction and loading well for small teams. dbt is the standard for transformations and it integrates cleanly with modern cloud warehouses like Snowflake, BigQuery, or Redshift. If you are working with really large volumes, Spark on Databricks or similar infrastructure becomes necessary. The tool choices matter less than the discipline of keeping your extraction, transformation, and loading layers separated and version-controlled. The data mining piece benefits from having your warehouse queryable by a tool like Jupyter, Tableau, or a dedicated ML platform. You do not need to move data out of the warehouse for mining. Running models against live warehouse data through direct SQL queries or federated connections is usually more efficient than exporting to CSV files and re-importing them somewhere else. I used to export my data to CSV and load it into R for mining queries. That approach meant I was always working with stale data and the export process alone took about twenty minutes per run. Moving the mining queries directly into the warehouse eliminated that delay entirely and gave me access to the full dataset without any transfer step.