Why This Book Is More Trouble Than It Looks
Data Mining: Concepts and Techniques by Han, Kamber, and Pei is the standard textbook for most graduate-level and advanced undergraduate courses in the field. It covers classification, clustering, association rules, frequent pattern mining, and other core algorithms with mathematical rigor. The third edition remains widely used, which means there are a lot of people searching for solutions, answer keys, and working walkthroughs of its problems. I have spent years seeing students struggle with these chapters, and the problems in this book are genuinely tricky. They assume a level of mathematical maturity that not every reader has, and the exercise sets are not always cleanly separated by difficulty level. The most common request is for full solution manuals, but those are rarely distributed legally. What most students actually need is chapter-by-chapter guidance, worked examples, and explanations of the harder proofs. I usually tell people to focus on getting detailed explanations rather than a PDF answer key. The real value is understanding how a decision tree handles continuous attributes, how the Apriori algorithm prunes candidate itemsets in a way that matters for memory, or how density-based clustering handles parameter selection when your data is not uniformly distributed. Those concepts are where the book becomes difficult, and where most solution guides actually help you more. I ran into a specific problem once while working through Chapter 8 on cluster analysis. A student was trying to apply DBSCAN to a dataset with varying densities and kept getting terrible results. The default Eps and MinPts values simply did not work. The textbook explains the algorithm, but it does not walk through parameter tuning on messy real data. I showed them how to use a k-distance graph to pick Eps, and then how to experiment with MinPts starting from four and moving upward. That small adjustment changed their cluster output entirely. The lesson here is that the book gives you the theory. The practice is where most people get stuck.
How the Book Is Structured and Where Students Typically Get Lost
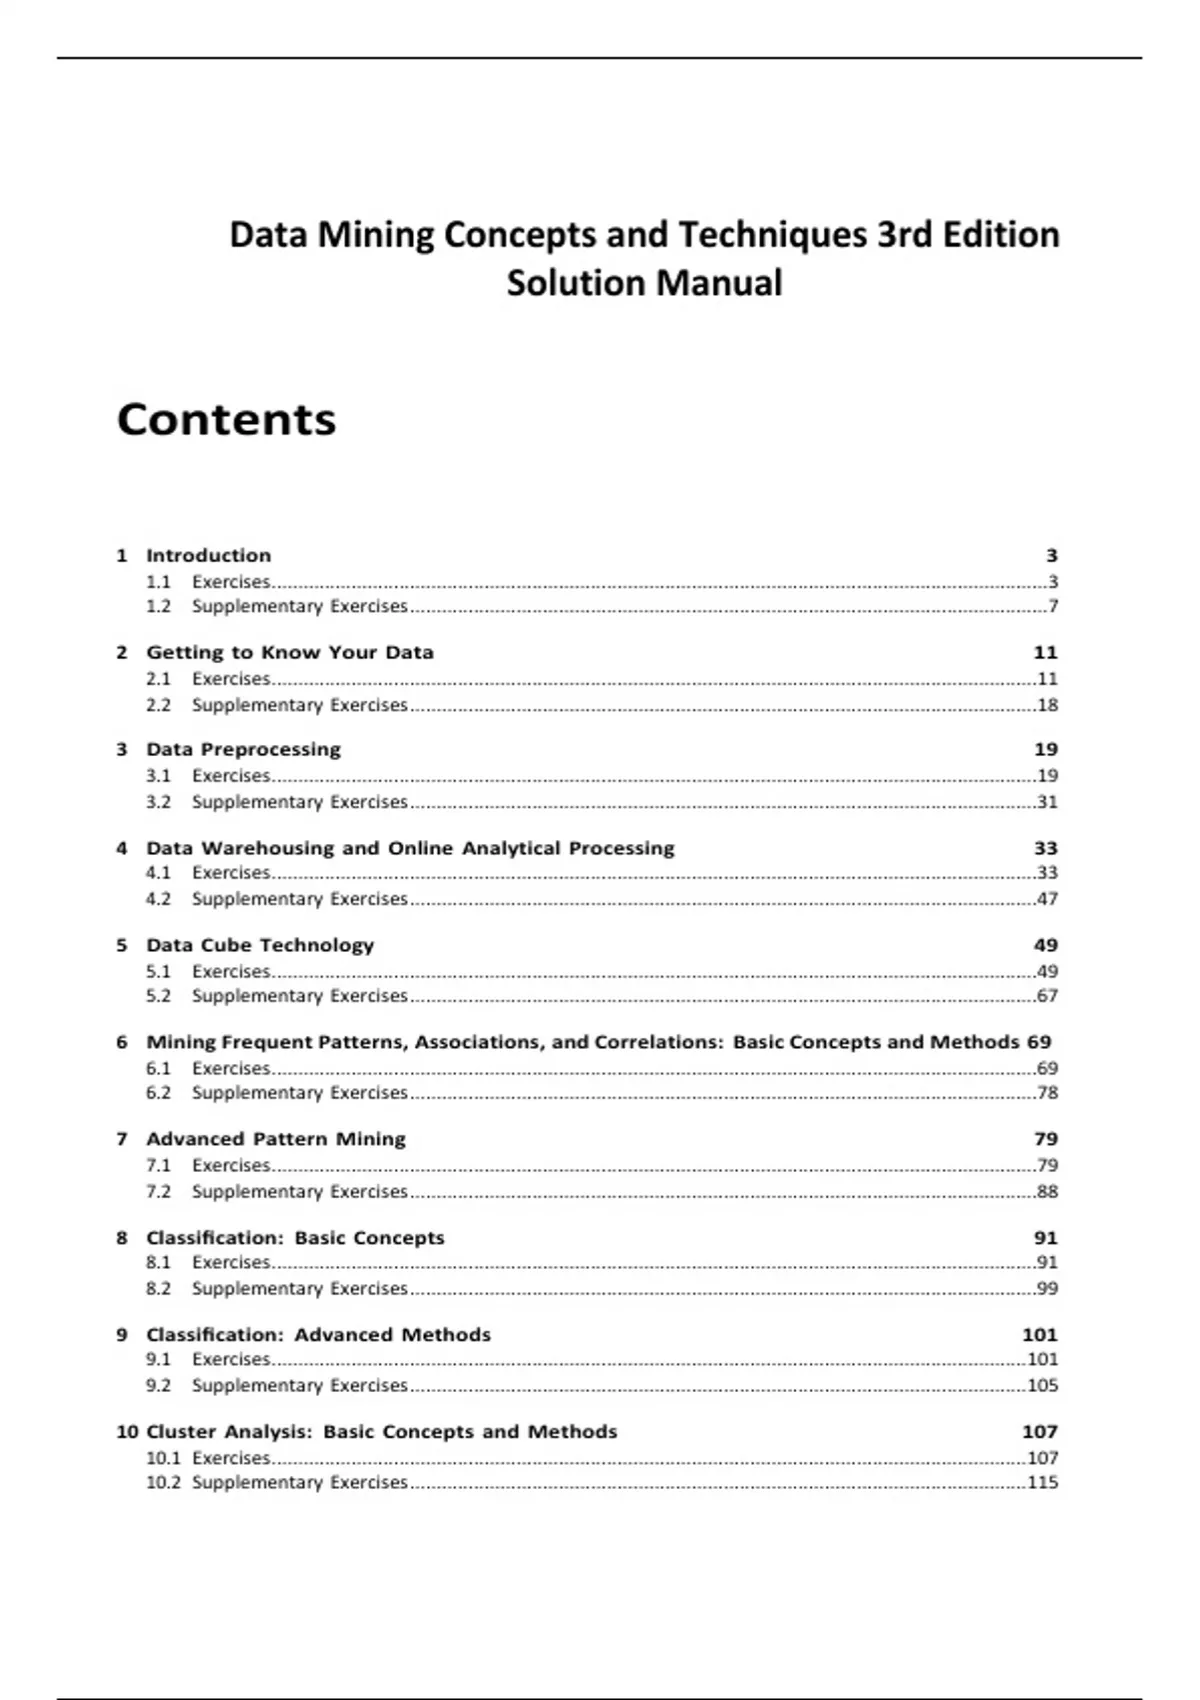
The text is divided into foundational material, advanced methods, and specialized topics. The early chapters cover metadata, data preprocessing, and basic statistical foundations. The middle sections handle frequent patterns, classification, and clustering. The later chapters move into outlier detection, web mining, and text mining. Each chapter ends with exercises that range from routine calculations to proof-based questions. The jump from simple numerical exercises to proofs using probabilistic bounds is one of the places where students lose their way. Classification chapters, especially the ones covering decision trees, naive Bayes, and support vector machines, receive the most attention because they are central to applied work. The Apriori algorithm is explained thoroughly, and the proof of the downward closure property is included. Students often miss the connection between that property and the actual efficiency gain. Without grasping that pruning step, the algorithm feels like a list of rules rather than a scalable procedure. Similarly, the FP-tree section can feel abstract until you see how conditional pattern bases are built and why they allow frequency counting without generating candidates. Clustering is another area where the gap between theory and practice is wide. K-means is straightforward in presentation, but convergence behavior, initialization sensitivity, and the choice of K are not always obvious to beginners. Density-based methods add Eps and MinPts as new parameters, which introduces another layer of tuning difficulty. Hierarchical clustering is covered, but the book does not dwell on scale issues or how to visualize dendrograms at large sizes. These omissions are not failures of the textbook. They are simply boundaries of a single-volume reference.
What Most People Mistake for a Complete Solution Set
There are many websites that claim to offer full solutions for every exercise in the third edition. Some of them are scanned copies of unofficial solution manuals. Others are partial answers posted on student forums. A few are outright incorrect because they were generated without verifying the mathematics. I have seen answers that confuse J48 with C4.5, treat Laplace smoothing as if it is unrelated to conditional probability, and present association rule confidence calculations that do not match the support values in the problem statement. If you want reliable help, you should treat any solution source as a starting point rather than a final authority. Verify the calculations yourself. Run the algorithm on a small synthetic dataset. Check that the itemset support counts match the transaction database. For classification problems, compute the error rates from first principles. This takes extra time, but it prevents you from memorizing wrong steps. The textbook problems are designed to be worked through, not copied.
Get the Full Details
A Practical Approach to Getting Useful Help
Start with the official textbook and its notation. Make sure you understand the definitions before you look at any worked example. Then work the easier exercises on your own. Only after that should you consult a solution for the harder problems. When you do, compare your intermediate results with the provided ones. If they differ, trace back to find where the divergence happened. Most errors come from small arithmetic mistakes or misunderstandings of a definition rather than from a fundamental flaw in the method itself. For algorithm chapters, implement the pseudocode yourself. I wrote a small Python script for Apriori once while debugging my own misunderstanding of candidate generation. Running it on a ten-item dataset made the pruning behavior obvious in a way that reading about it never did. That same approach applies to decision trees, gradient boosting, and even the clustering algorithms. A few hours of implementation usually resolve more confusion than a week of passive reading. When you encounter a problem that involves a proof, treat it differently. Work backward from the conclusion. Identify the lemma or theorem you need to invoke. Check the definitions that appear in the hypothesis. Most textbook proofs rely on standard results from discrete mathematics or probability theory, so if those foundations feel shaky, go back and fill that gap before returning to the exercise.
Common Pitfalls I See Repeatedly
Students frequently misuse confidence and support in association rule evaluation. They calculate confidence by dividing a rule’s support by the total number of transactions instead of by the support of the antecedent. This produces inflated numbers that look plausible but are mathematically wrong. Another frequent issue is treating correlation and causal rules as interchangeable. The book is clear on this point, but it is easy to forget when you are under time pressure. In clustering, people often report only the final cluster assignments without checking stability. Running k-means twice with different initial centers can yield completely different partitions if the data contains overlapping spherical clusters. This is not a flaw in the algorithm. It is a property of the objective function, and recognizing it early saves a lot of wasted effort. For hierarchical clustering, merging decisions can be highly sensitive to distance metrics. Euclidean distance, Manhattan distance, and correlation-based distance can produce very different trees for the same dataset. Outlier detection is another area where beginners rush through the exercises. Statistical methods assume a specific distribution. Distance-based methods require careful distance metric selection. Model-based methods need you to specify the number of components correctly. If your data violates the underlying assumptions, the results will look clean but be meaningless. I learned this the hard way when a student tried to use a Gaussian mixture model on a dataset with heavy-tailed distributions and then complained that the outliers kept shifting with every run.
Where the Textbook Falls Short and What to Use Instead
No single book covers everything. The third edition is strong on classical algorithms and mathematical foundations. It is weaker on modern developments such as deep learning-based feature extraction, online mining, streaming algorithms, and large-scale distributed implementations. If your course touches on those topics, you will need supplementary material. For distributed computing, papers on MapReduce implementations of Apriori and Spark-based clustering algorithms are more relevant than anything in this book. For streaming data, you will want sources that cover the DGIM algorithm and related techniques for approximate frequency counting. Another limitation is the lack of comprehensive code examples. The pseudocode is clear, but translating it into production-quality code requires additional practice. I recommend pairing the book with hands-on projects in Python or R. Libraries such as scikit-learn, MLlib, and the arules package in R let you verify your manual calculations against optimized implementations. This dual approach reduces confusion and builds practical skill faster than reading alone.
Final Thoughts on Using This Resource Effectively
The search for Data Mining Concepts And Techniques 3rd Edition Solutions is common because the book is challenging and widely assigned. The most productive path is not to find a complete answer key. It is to learn how to verify each step yourself, implement the algorithms, and understand the assumptions behind every formula. When you do that, the textbook becomes a reliable reference rather than a source of frustration. When you skip that process, you end up memorizing answers without understanding, and that does not help anyone in the long run.


