The actual mechanics of pulling signal out of enterprise data
Most people treat data mining as if it's some sort of black box you hand a CSV to and get insights back. It doesn't work like that. You spend roughly 70% of your time on dirty, unglamorous work before you ever run a single model, and the remaining 30% is mostly arguing with stakeholders about what "actionable" actually means. The process itself breaks down into a handful of concrete steps that any team can follow, assuming they have patience and decent infrastructure.Data Mining In Business Intelligence
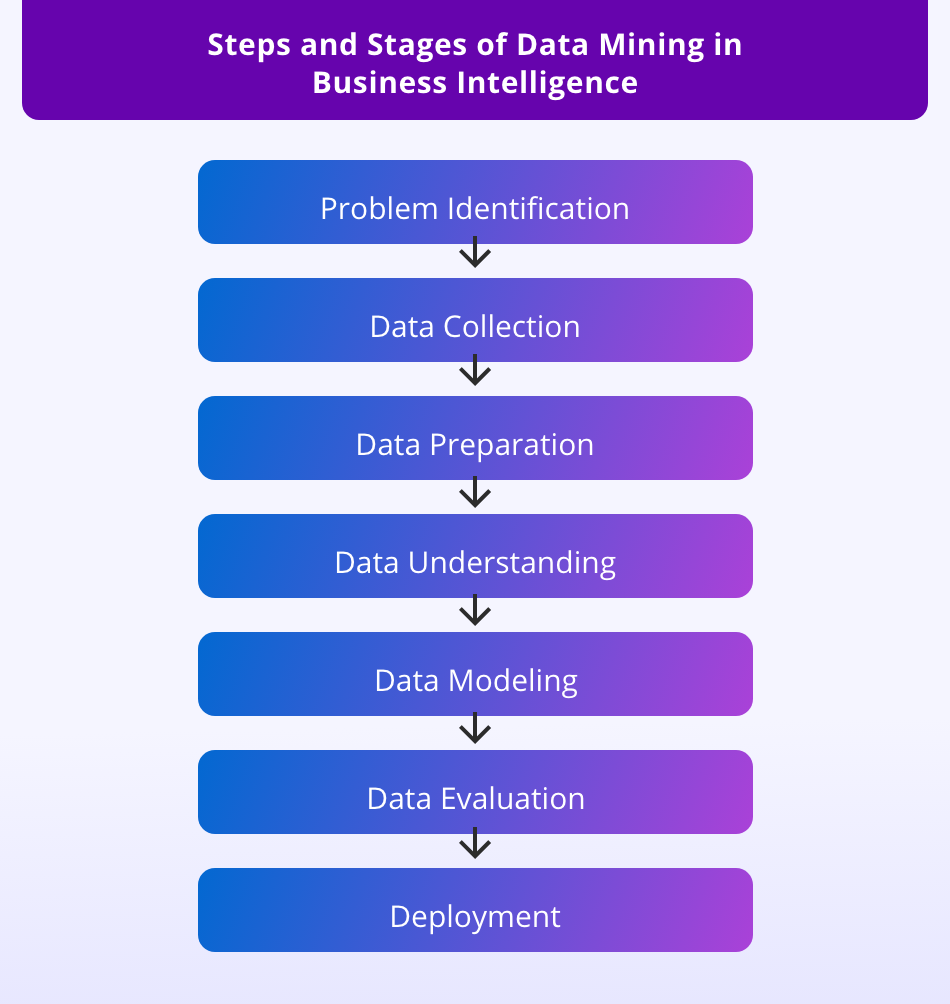
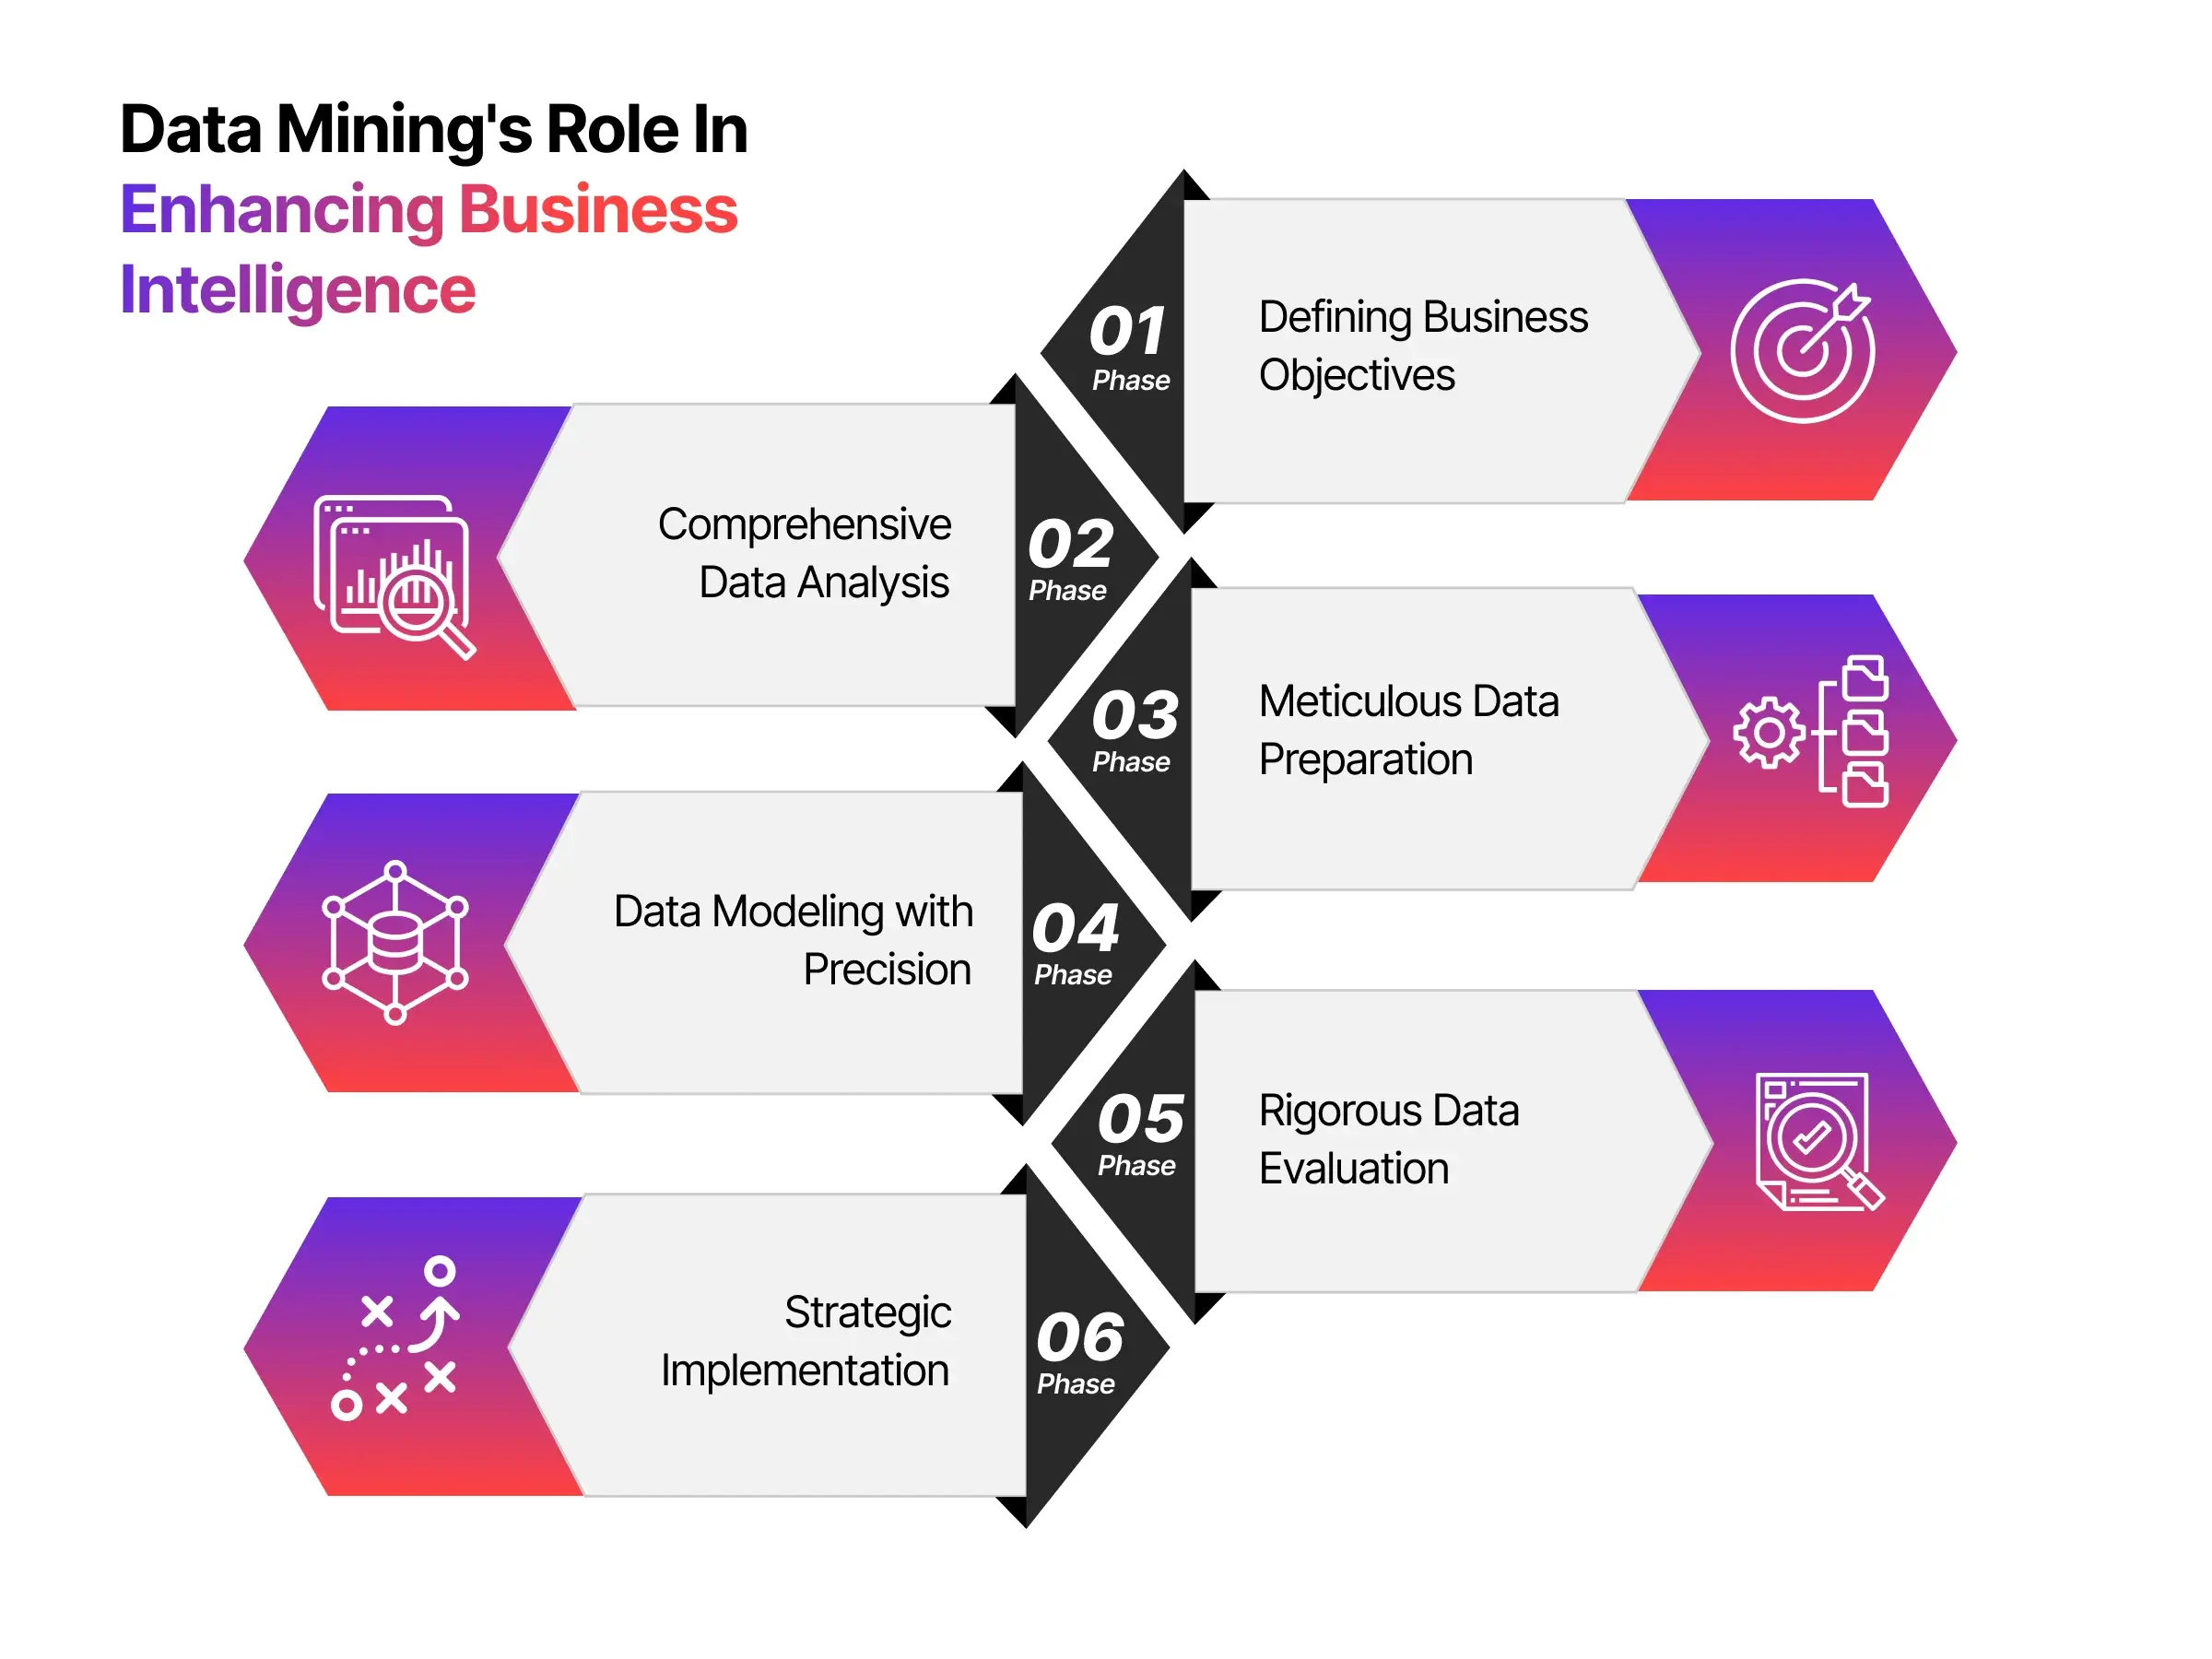
At its core, you're taking raw transactional records and transforming them into patterns that decision-makers can act on. The workflow starts with data selection, where you pull from whatever sources are relevant. That's usually a mix of CRM logs, ERP tables, web analytics exports, and sometimes external APIs. Then comes cleaning. This is where the real work happens. Missing values, duplicate rows, format mismatches between systems, and the occasional column named something like "client_id_v2_fresh" that someone created in a hurry three years ago and now nobody remembers what it means. After that, you move to transformation. Here you normalize, aggregate, and reshape data into a format suitable for analysis. Then feature selection determines which variables actually matter instead of just being noise. Once your data is ready, you pick an algorithm and train a model. Finally, you evaluate the results against a held-out test set and deploy what works. I've seen teams skip the evaluation step entirely and just ship whatever their model spit out first. That's how you end up with dashboards full of confident-looking numbers that are completely wrong. Don't do that. Always hold out a portion of your data for validation. Something like 20% of your dataset. Check precision, recall, and F1 score depending on whether you care more about false positives or false negatives. A model that scores 95% accuracy on an imbalanced dataset where 95% of the samples are one class is essentially telling you nothing useful. It's just predicting the majority class every time. Here is what actually happens in a production environment. You build a pipeline. Most teams use something like Apache Spark for large-scale processing because it handles distributed computation reasonably well, and Python libraries like scikit-learn or XGBoost for the modeling side. If your data volume is small enough, pandas works fine but it starts choking around a few hundred thousand rows depending on your machine. For recurring reports, I usually wrap everything in a DAG using Apache Airflow so the whole sequence runs automatically on a schedule. This usually cuts manual effort down from a half-day per run to about ten minutes of checking whether the overnight job succeeded.
There are specific problems that show up constantly and most beginners don't anticipate them. One I ran into recently involved a retail client where purchase timestamps were stored in three different time zones across their regional databases. The model trained on Eastern Time data performed perfectly until we tried to apply it to transactions from the Pacific region. The clustering algorithm was grouping purchases by time-of-day and the shifts broke the pattern entirely. The fix was straightforward once I found it. I added a normalized hour column calculated against UTC rather than local time before feeding anything into the model. Took about twenty minutes to implement and completely resolved the issue. Without that normalization, the results were garbage and I wasted two full days debugging why a perfectly trained model was producing nonsense predictions. Another common trap is data leakage. This happens when information from the future leaks into your training data through poorly constructed features. A classic example is including a customer's total lifetime spend when you're trying to predict whether they'll churn next month. Of course they haven't churned yet if their total spend includes transactions from next month. It's a simple mistake but it produces models that look amazing in development and fail completely in production. Always audit your feature list line by line and ask whether each variable would actually be known at prediction time in a real deployment scenario. When you're choosing algorithms, remember that complex doesn't mean better. A well-tuned logistic regression often outperforms a deep neural network on tabular business data. Start simple. Fit a baseline model first. Get your accuracy, your confusion matrix, and your baseline metrics logged. Then only move to more complex methods if the baseline genuinely isn't sufficient for the problem at hand. Gradient boosting machines tend to be the best default choice for structured data problems. They handle missing values reasonably well, require less feature engineering than many alternatives, and produce interpretable feature importance scores which management actually finds useful even if the math behind them is approximate.
Deployment is where most projects stall out. You build a model in a Jupyter notebook, it looks great, and then you need to put it somewhere that actually generates business value. Most of the time this means either a REST API endpoint that feeds predictions into an existing dashboard or a scheduled batch process that writes results to a database table your BI tool can read directly. If you're using tools like Tableau, Power BI, or Looker Studio, the batch approach is almost always simpler. Just write your predictions to a table and let the visualization layer handle the rest. Building real-time APIs adds complexity that rarely pays for itself in most business intelligence use cases unless you have a specific need for live predictions. The biggest bottleneck I see in practice is not technical. It's stakeholder alignment. A data mining project fails far more often because the business side had different assumptions about what the model would output than because the model itself was poorly constructed. Before you write a single line of code, get a written agreement on the success criteria. What metric matters. What threshold counts as acceptable. What happens if the model is right 80% of the time versus 95%. Getting this conversation done upfront saves weeks of rework later when someone decides the model isn't good enough after you've already deployed it. For hands-on work, scikit-learn remains the standard entry point. It covers classification, clustering, regression, and dimensionality reduction in a consistent API. If you're dealing with larger datasets, XGBoost or LightGBM for tree-based models. For clustering, DBSCAN tends to outperform K-means on real-world data because it doesn't force you to specify the number of clusters beforehand and it handles noise points properly. K-means will assign every point to a cluster even when that point is clearly an outlier. That matters more than you might think when you're trying to identify fraud or abnormal behavior patterns in transaction data.
Get the Full Details
Monitoring deployed models is something almost nobody does adequately. A model that performed well at launch will degrade over time as underlying patterns shift. Customer behavior changes. Market conditions change. Your data distribution drifts. Set up a simple monitoring pipeline that tracks prediction distributions and key performance metrics over time. If the drift gets too large, it's usually cheaper and faster to retrain the model than to debug why an old one stopped working. Most teams I've worked with only revisit their models when something breaks visibly. By then you're already behind. Checking monthly is reasonable. Weekly is better if your data changes fast. The tools themselves are mostly commoditized now. The differentiation comes from how well you understand the underlying problem and how carefully you handle the data. Anyone can import a library and call fit on a dataset. Doing it correctly, with proper validation, awareness of bias, and realistic expectations about what the results can and cannot tell you, is the actual skill. Everything else is just setup.