What you actually need to know before walking into these interviews
Data pipeline architecture is one of those topics where everyone seems to have an opinion, but only a few people have actually shipped something that doesn't fall apart at scale. The interview questions will test whether you've done the work or just watched videos about it. Here is how to actually prepare. Most candidates fail at the basic mapping section. They can name tools—Kafka, Airflow, Spark—but they can't explain why they would use one over the other in a specific scenario. I have seen engineers confidently recommend Kafka for a batch-only use case where the data comes in once per hour and gets processed. That is not a trick question. That is someone who memorized a list without understanding the tradeoffs.
Data Pipeline Interview Questions: The real ones
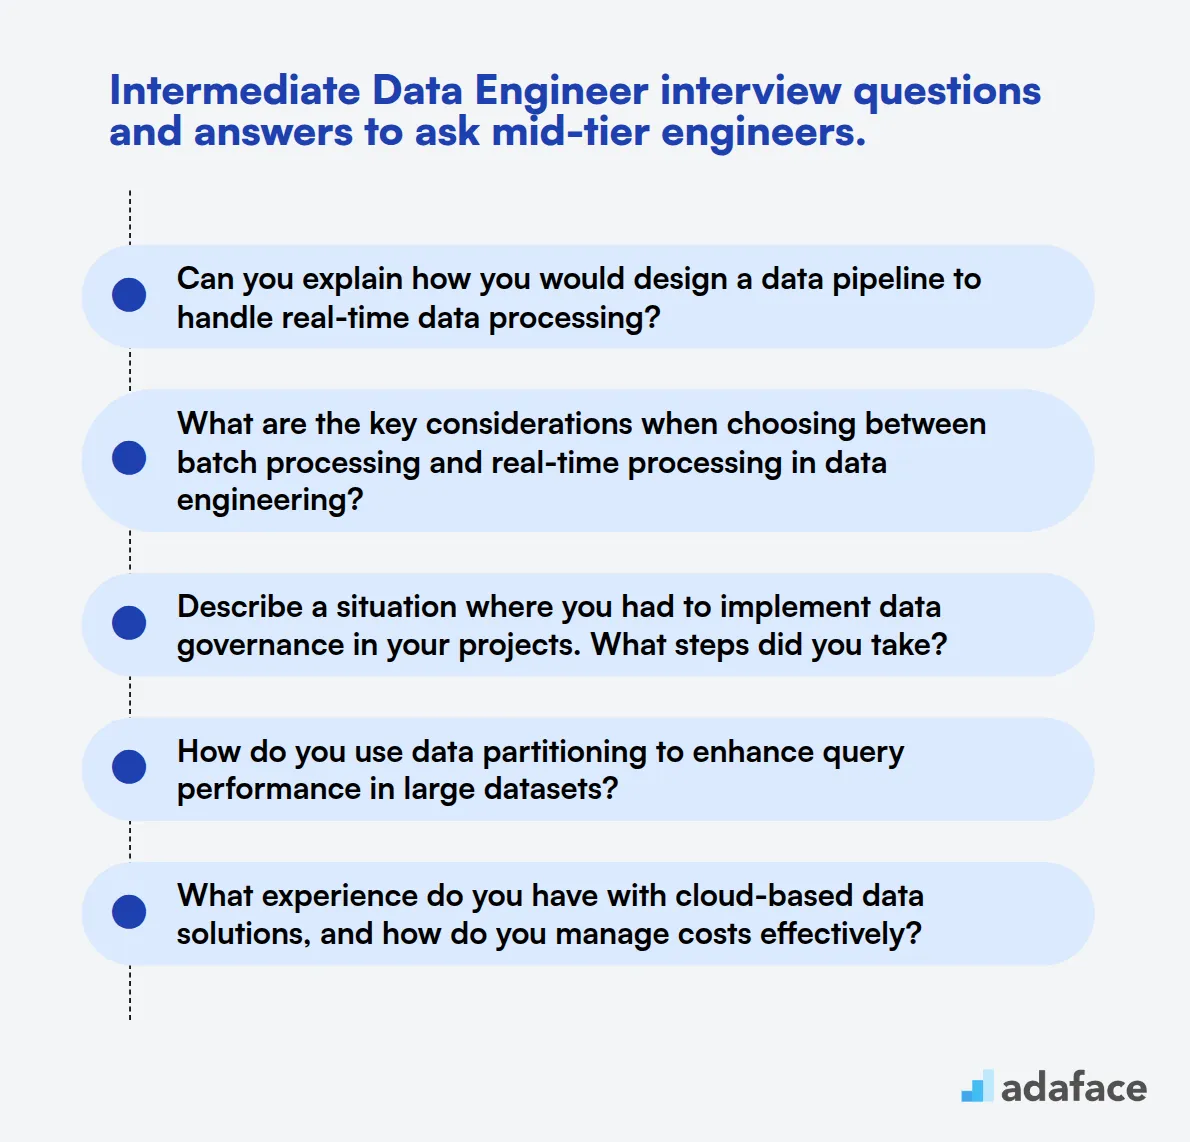
The questions that matter tend to cluster around four areas: pipeline design, data consistency, tool selection, and operational failure. Here is how they actually play out in practice. You will almost always get a design question. Something like "Design a pipeline that ingests clickstream data from a mobile app and lands in a data warehouse within five minutes." The interviewer is not looking for a perfect answer. They are looking to see if you ask clarifying questions first. How much data per second? What is the source system? Are there compliance requirements? Do you need exactly-once semantics or is at-least-once acceptable? A candidate who dives straight into "I'd use Kafka and Flink" without asking these things usually does not have enough experience. Here is a specific example from my own work. I was building a pipeline that pulled transaction records from three separate PostgreSQL databases across different regions and loaded them into Snowflake for a financial reporting dashboard. The data had to be consistent within 90 seconds. We chose Debezium for CDC, routed through Kafka, and used a Python-based transformation layer before loading into Snowflake via the streaming API. About three months in, we started seeing duplicate rows during failover events because Kafka's at-least-once delivery was doing exactly what it was designed to do. The workaround was adding a deduplication step using a composite key of (transaction_id, region, timestamp_bucket) with a window function in Snowflake. It added maybe two seconds to the processing time per batch, which was acceptable. But the key insight was recognizing the problem early. Many teams do not think about this until a stakeholder complains about incorrect totals.
You will also get questions about consistency models. This is where people who have only worked with small-scale ETL jobs tend to struggle. Understanding the difference between strong consistency, eventual consistency, and causal consistency matters. In most data pipelines, you are working with eventual consistency because that is what distributed systems give you. The question is whether your downstream consumers can handle that. If you are building a real-time fraud detection system, eventual consistency might mean losing money. If you are building a daily marketing report, it means nothing at all. Here is a counter-intuitive point that most beginners miss: latency optimization is often the wrong priority. I have sat through too many pipeline discussions where the team spent weeks reducing latency from 10 minutes to 30 seconds. Thirty seconds is fast. But the real bottleneck was the transformation logic in the middle layer, which was using a naive join approach that scaled linearly with data volume. When the source data doubled, the pipeline did not just take twice as long—it took four times as long because of how the shuffle was working. The fix was switching to a broadcast join for the smaller dimension tables. That single change cut processing time from 45 minutes to under six minutes. The team had been chasing a latency number without understanding what was actually driving the cost. Another common area is schema evolution. You will be asked how you handle schema changes in a pipeline. The naive answer is "I use Avro with a schema registry." The correct answer acknowledges that schema evolution is painful and explains the strategies: forward compatibility, backward compatibility, and full compatibility. Most production systems rely on backward-compatible schema changes, which means new fields are optional and old consumers do not break. But this is not always enough. I once dealt with a pipeline where a vendor updated their API and removed a field we depended on. There was no warning, no deprecation period. Our entire dashboard went dark for six hours while we figured out a workaround. The lesson was straightforward: always build schema validation and alerting into your pipeline. If a field disappears, you should know within minutes, not after a stakeholder sends an angry email.
Get the Full Details

You will get questions about error handling and monitoring. This is not glamorous but it is where experienced engineers separate themselves from the rest. A production pipeline needs dead letter queues, retry logic with exponential backoff, and meaningful alerting. Not all errors are equal. A transient network timeout should be retried. A malformed JSON file should go to a dead letter queue and trigger a ticket. I learned this the hard way when I had a pipeline that silently failed for two days because the output directory permissions changed on the target server. The scheduler kept running but every job was writing to /dev/null effectively. We caught it only because a manual audit discovered the missing data. After that, I made it a rule that every pipeline must have a health check that validates output row counts against expectations and alerts immediately if they deviate by more than five percent. Tool-specific questions will come up. You should know your primary tools well, but you should also understand the landscape. Spark and Flink are both stream processing frameworks, but they serve different purposes. Spark is fundamentally batch-oriented with streaming capabilities layered on top. Flink is a native stream processor that handles micro-batching when needed. If you need sub-second latency with complex event processing, Flink is the better choice. If you are doing large-scale batch transformations, Spark is more mature and easier to debug. There is no universal answer. Airflow is another tool that gets asked about constantly. Everyone uses it. Not everyone uses it well. The main problem I see is that people treat Airflow as a scheduling tool rather than a workflow orchestration tool. Airflow's strength is in managing dependencies between tasks, not in executing heavy data transformations. If you are running massive Spark jobs from Airflow, you are usually doing it wrong. Let Spark handle the computation. Let Airflow handle the coordination. Mixing the two responsibilities creates brittle pipelines that are hard to maintain.
dbt comes up a lot now, especially for analytics engineering roles. The question is usually about how dbt fits into a modern pipeline. The honest answer is that dbt is a transformation layer, not an ingestion or orchestration tool. It sits between your data warehouse and your consumers. It handles SQL-based transformations, testing, and documentation. It works well if your team is comfortable with SQL. It works poorly if you need complex logic that SQL cannot express efficiently. I have seen teams try to force dbt to do things it was never designed for—real-time streaming, complex aggregations across multiple warehouses—and end up with a mess that was harder to maintain than the original pipeline. One more thing about interviewing for these roles: be ready to talk about what broke and how you fixed it. I do not mean a minor bug. I mean a real failure. A pipeline that went down during a critical business moment. A data quality issue that affected thousands of users. The interviewer wants to hear about your thought process under pressure. How did you diagnose the problem? What did you communicate? How did you resolve it? What did you learn? Here is a story that has stuck with me. We had a pipeline feeding a customer segmentation model used by the sales team. The pipeline was running on a weekly schedule. One Monday morning, the entire week's segment updates were missing. The sales team had a major campaign scheduled for Tuesday and the segmentation data was critical. I traced the issue to a corrupted dependency in our Docker container that Airflow was pulling from an internal registry. The container build had been broken by a library update three days prior, but nobody noticed because the weekly run was not scheduled until Monday. We did not have a pre-flight check. That was the gap. I implemented a dry-run task that validated all container images before the actual execution. It took about an hour to build and added maybe thirty seconds to the pipeline runtime. It prevented a similar incident from ever happening again.
The bottom line is that data pipeline interviews are not about knowing every tool. They are about demonstrating that you understand the systems you are building, that you have dealt with failures, and that you can reason through tradeoffs. The people who prepare best are the ones who can talk about both the successes and the failures with equal detail.