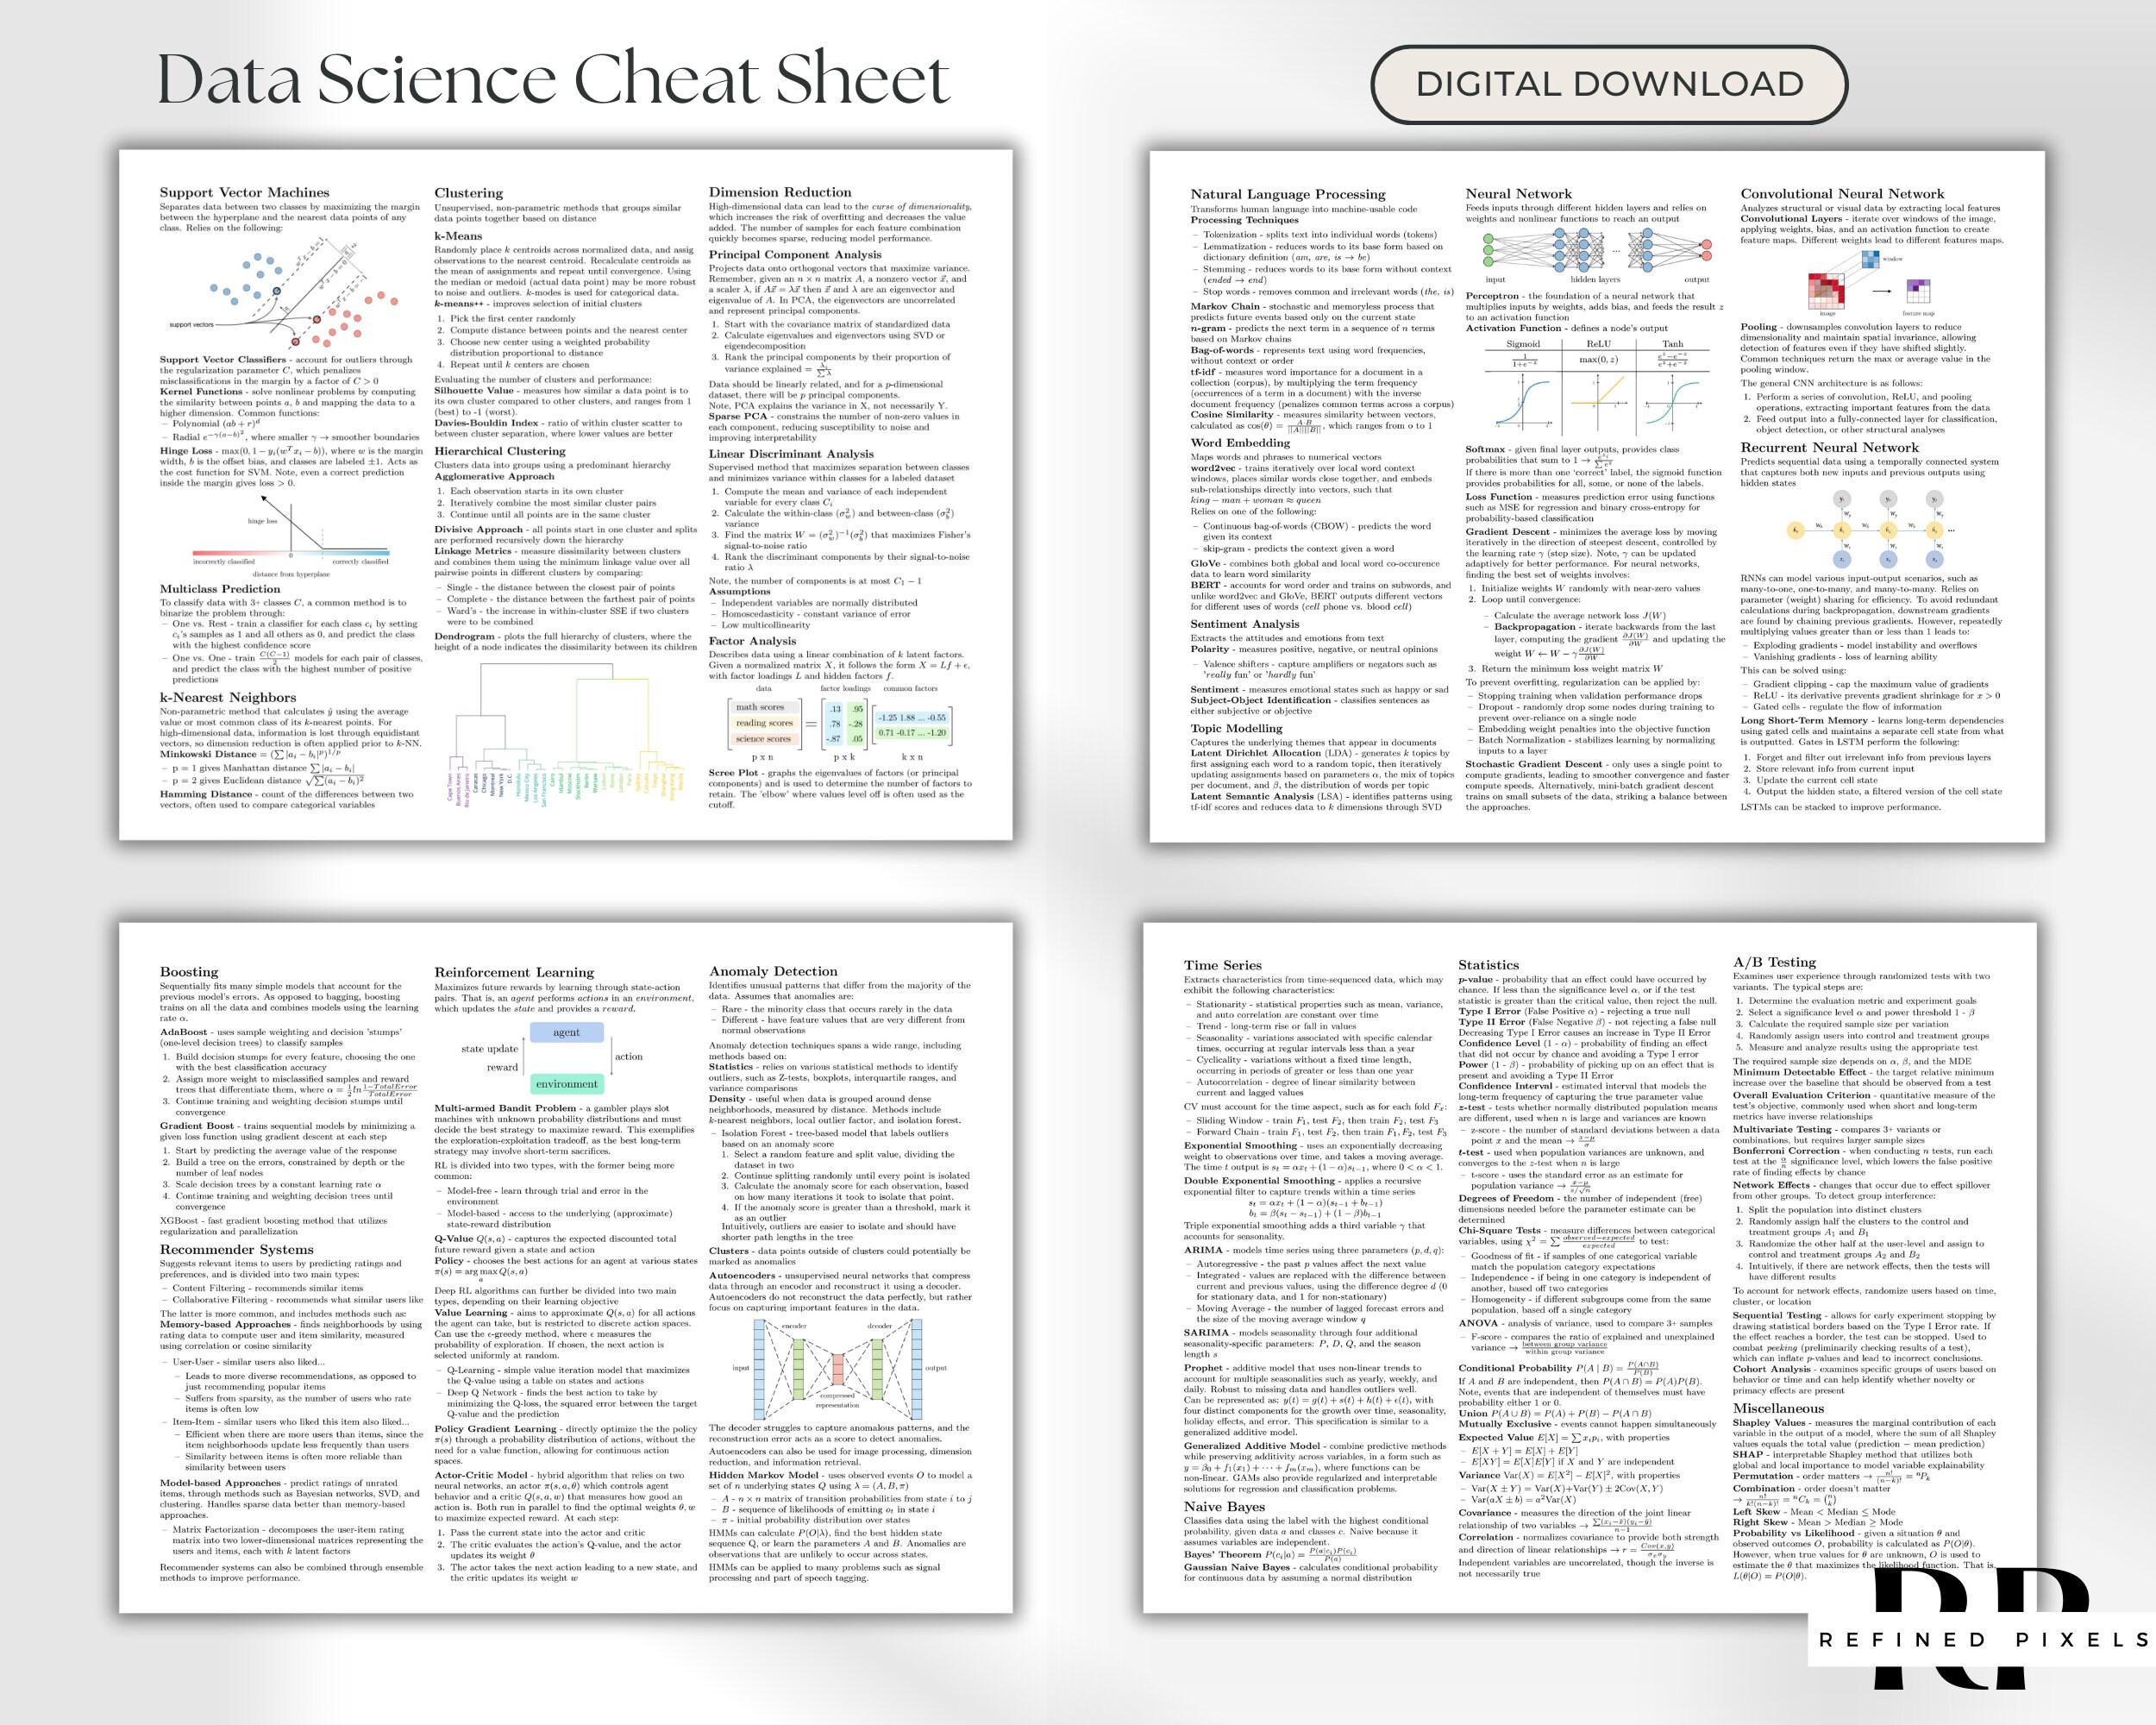
Why I Keep Making One
I used to try and memorize pandas syntax. That lasted about two weeks before I spent forty-five minutes Googling how to drop NaN values while a manager was hovering behind my chair. Now I keep a living Data Science Cheat Sheet on my desktop. It is not glamorous. It works. The best cheat sheets are not Wikipedia articles condensed into bullet points. They are reference material built from actual mistakes. Mine is organized the way I actually think when I am wrestling with a broken pipeline, not the way a textbook wants you to learn.
Data Science Cheat Sheet Essentials
A useful one covers the things that change under you. Python libraries shift. SQL dialects vary. R keeps adding new packages. A static PDF gets outdated in three months. I maintain mine as a plain Markdown file that I pull from a private GitHub repo. Sync it across machines with git pull. Takes ten seconds. The sections I always include: Python/NumPy/Pandas — grouping, reshaping, missing data handling, string operations, merge types. The things that take longer to look up than to just write out again.
SQL — window functions, CTEs, date manipulation, common joins. Left join behavior differences between PostgreSQL and MySQL trip people up constantly. I note those. Scikit-learn — pipeline setup, cross-validation, hyperparameter grids, metric names. Don't forget that accuracy lies to you on imbalanced datasets. Matplotlib/Seaborn — figure sizing, subplot layout, color palettes, saving with transparent backgrounds. These are minor annoyances that stack up.
Get the Full Details
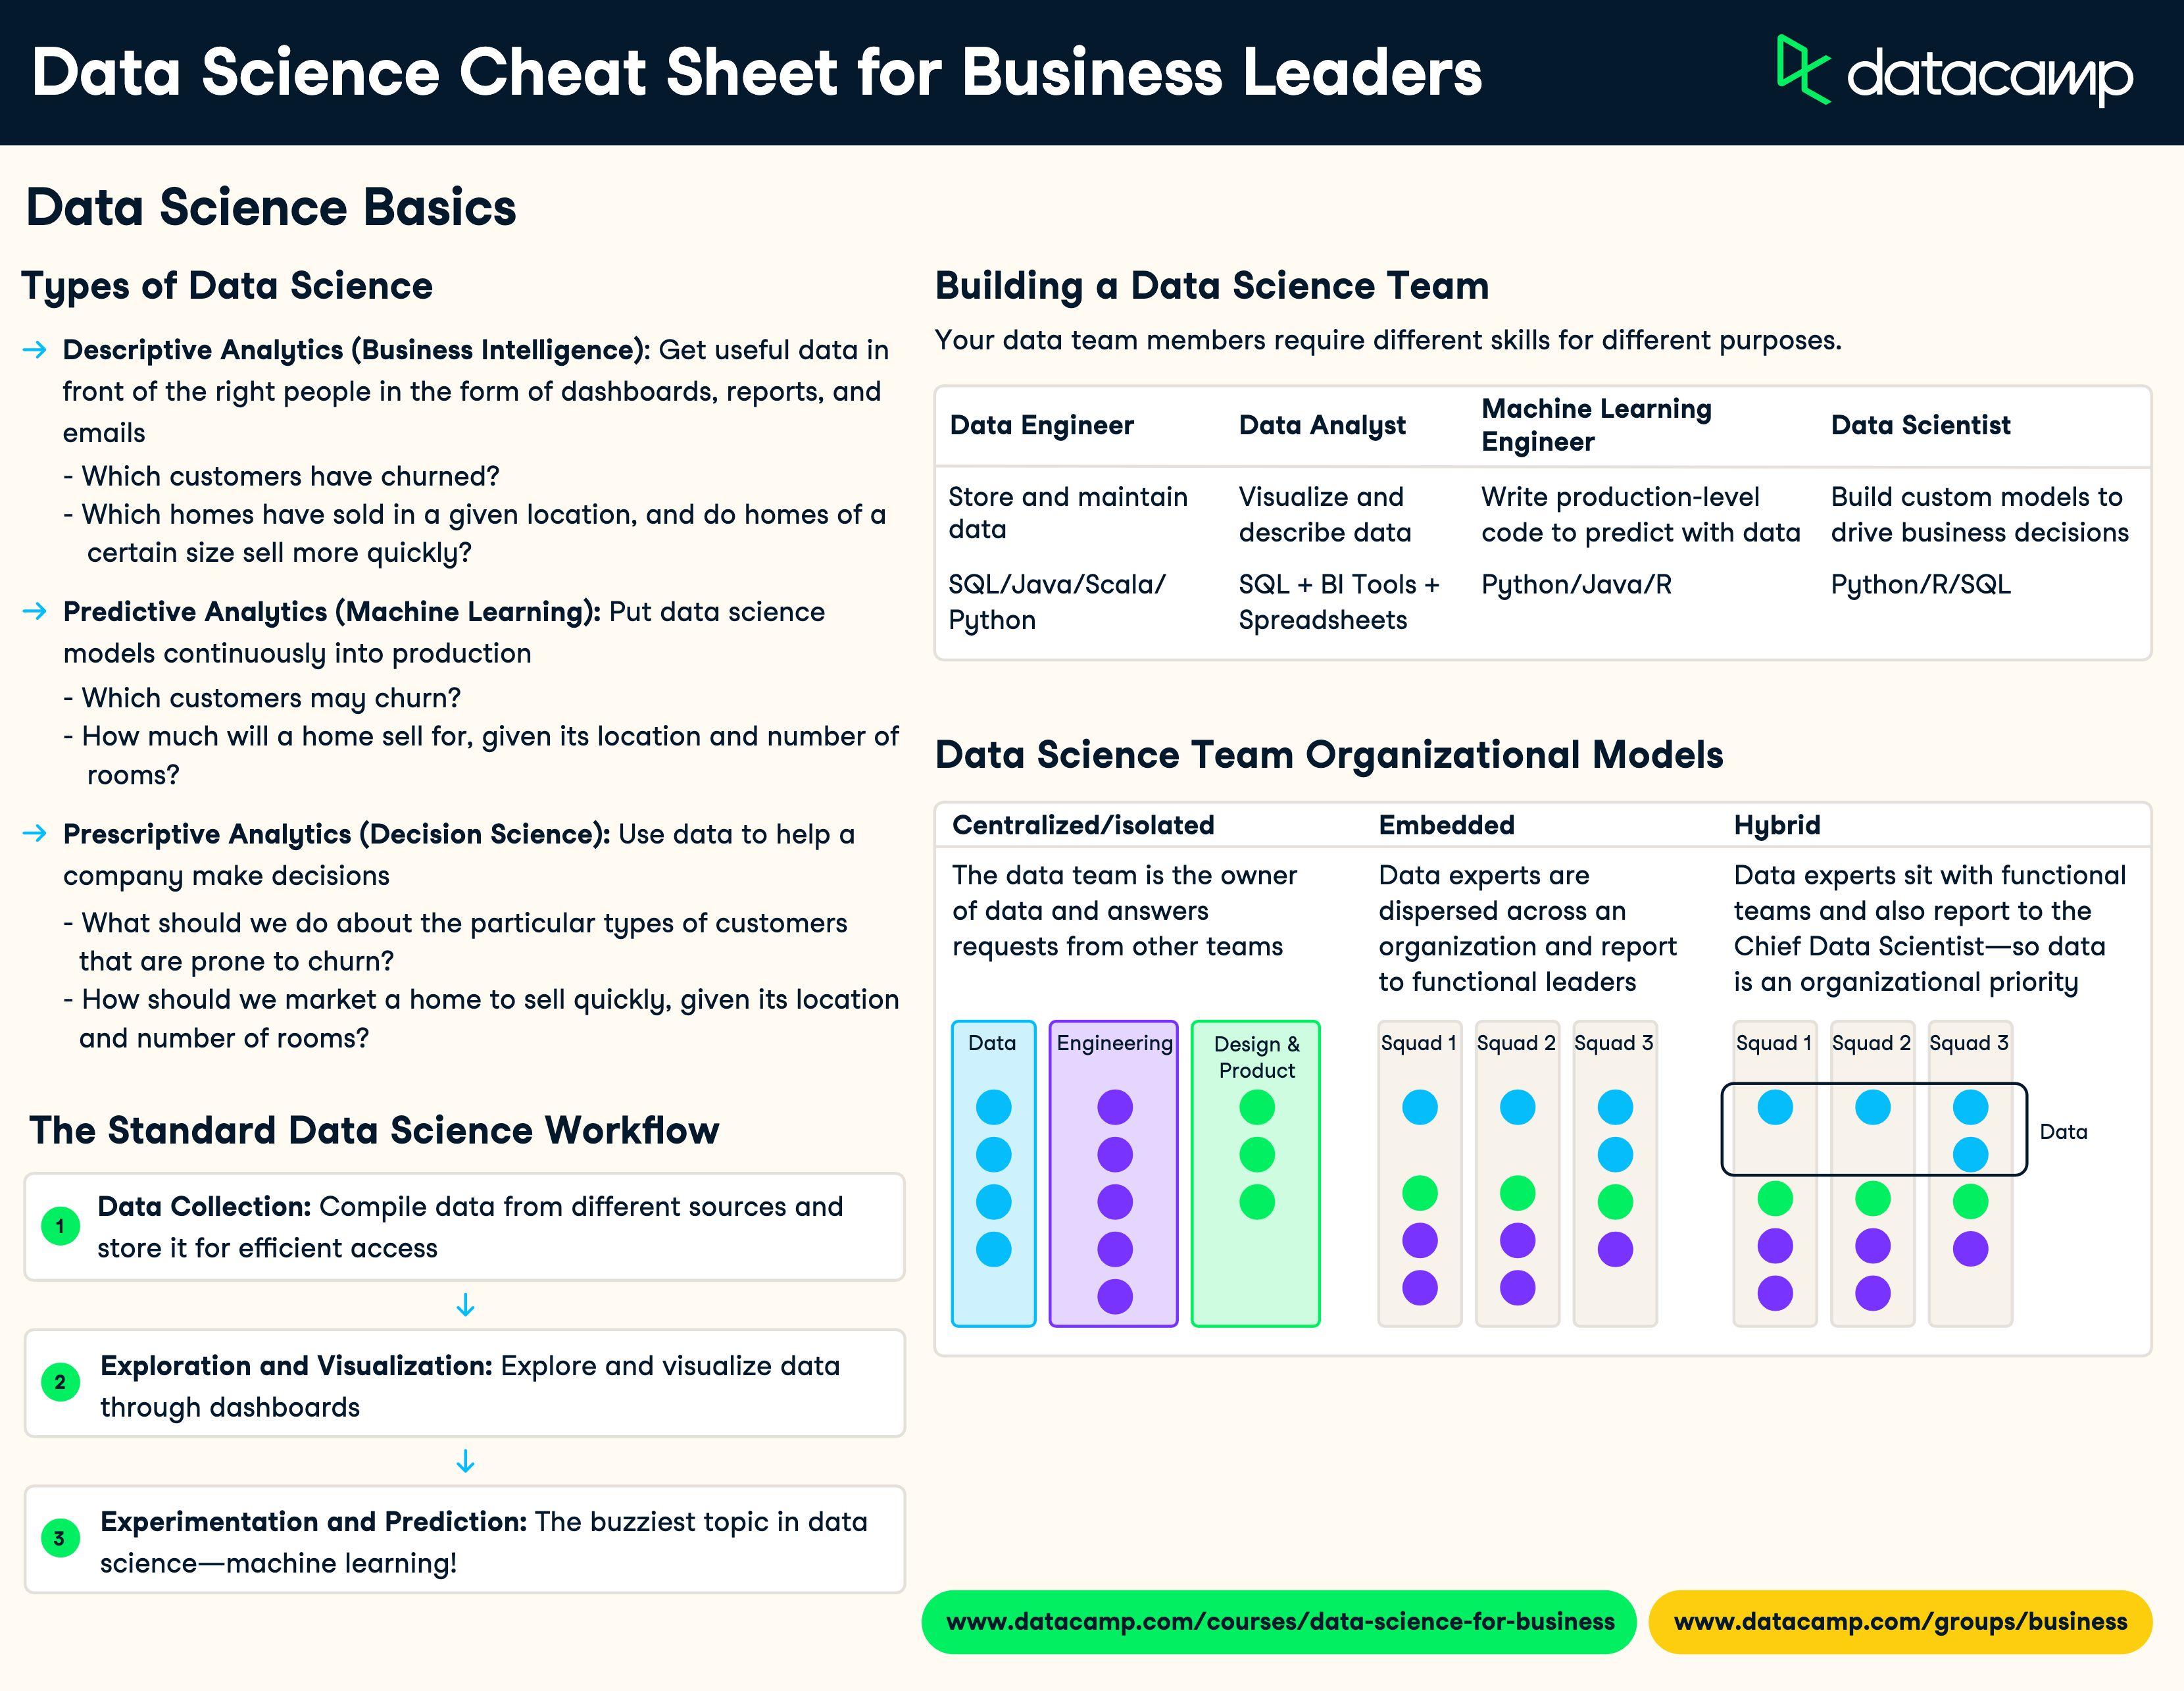
Git — I include basic commands because I always forget the difference between reset and revert until it is too late. Docker — container basics, volume mounts, image building. My team uses containers for reproducibility and I reference the Dockerfile syntax at least once a week. Regular expressions — I never remember the exact flags. I keep a small section for string extraction and validation patterns.
I also track environment setup notes. Conda vs. pip conflicts, virtual environment activation, common package installation failures on M-series Macs. These are not glamorous topics. They are the reason half my morning goes.
How I Actually Use It
I do not read it cover to cover. I open it and search for the specific command or pattern I need. It is a lookup tool, not a study guide. If I need to relearn something deeply, I go back to documentation or a course. The cheat sheet exists for the stuff I use but do not use often enough to retain. The real value shows up during pair programming or when someone else is looking over my shoulder. Instead of tab-switching between Stack Overflow and my editor, I point at the relevant section. It saves maybe three minutes per session, but those minutes multiply across a project.
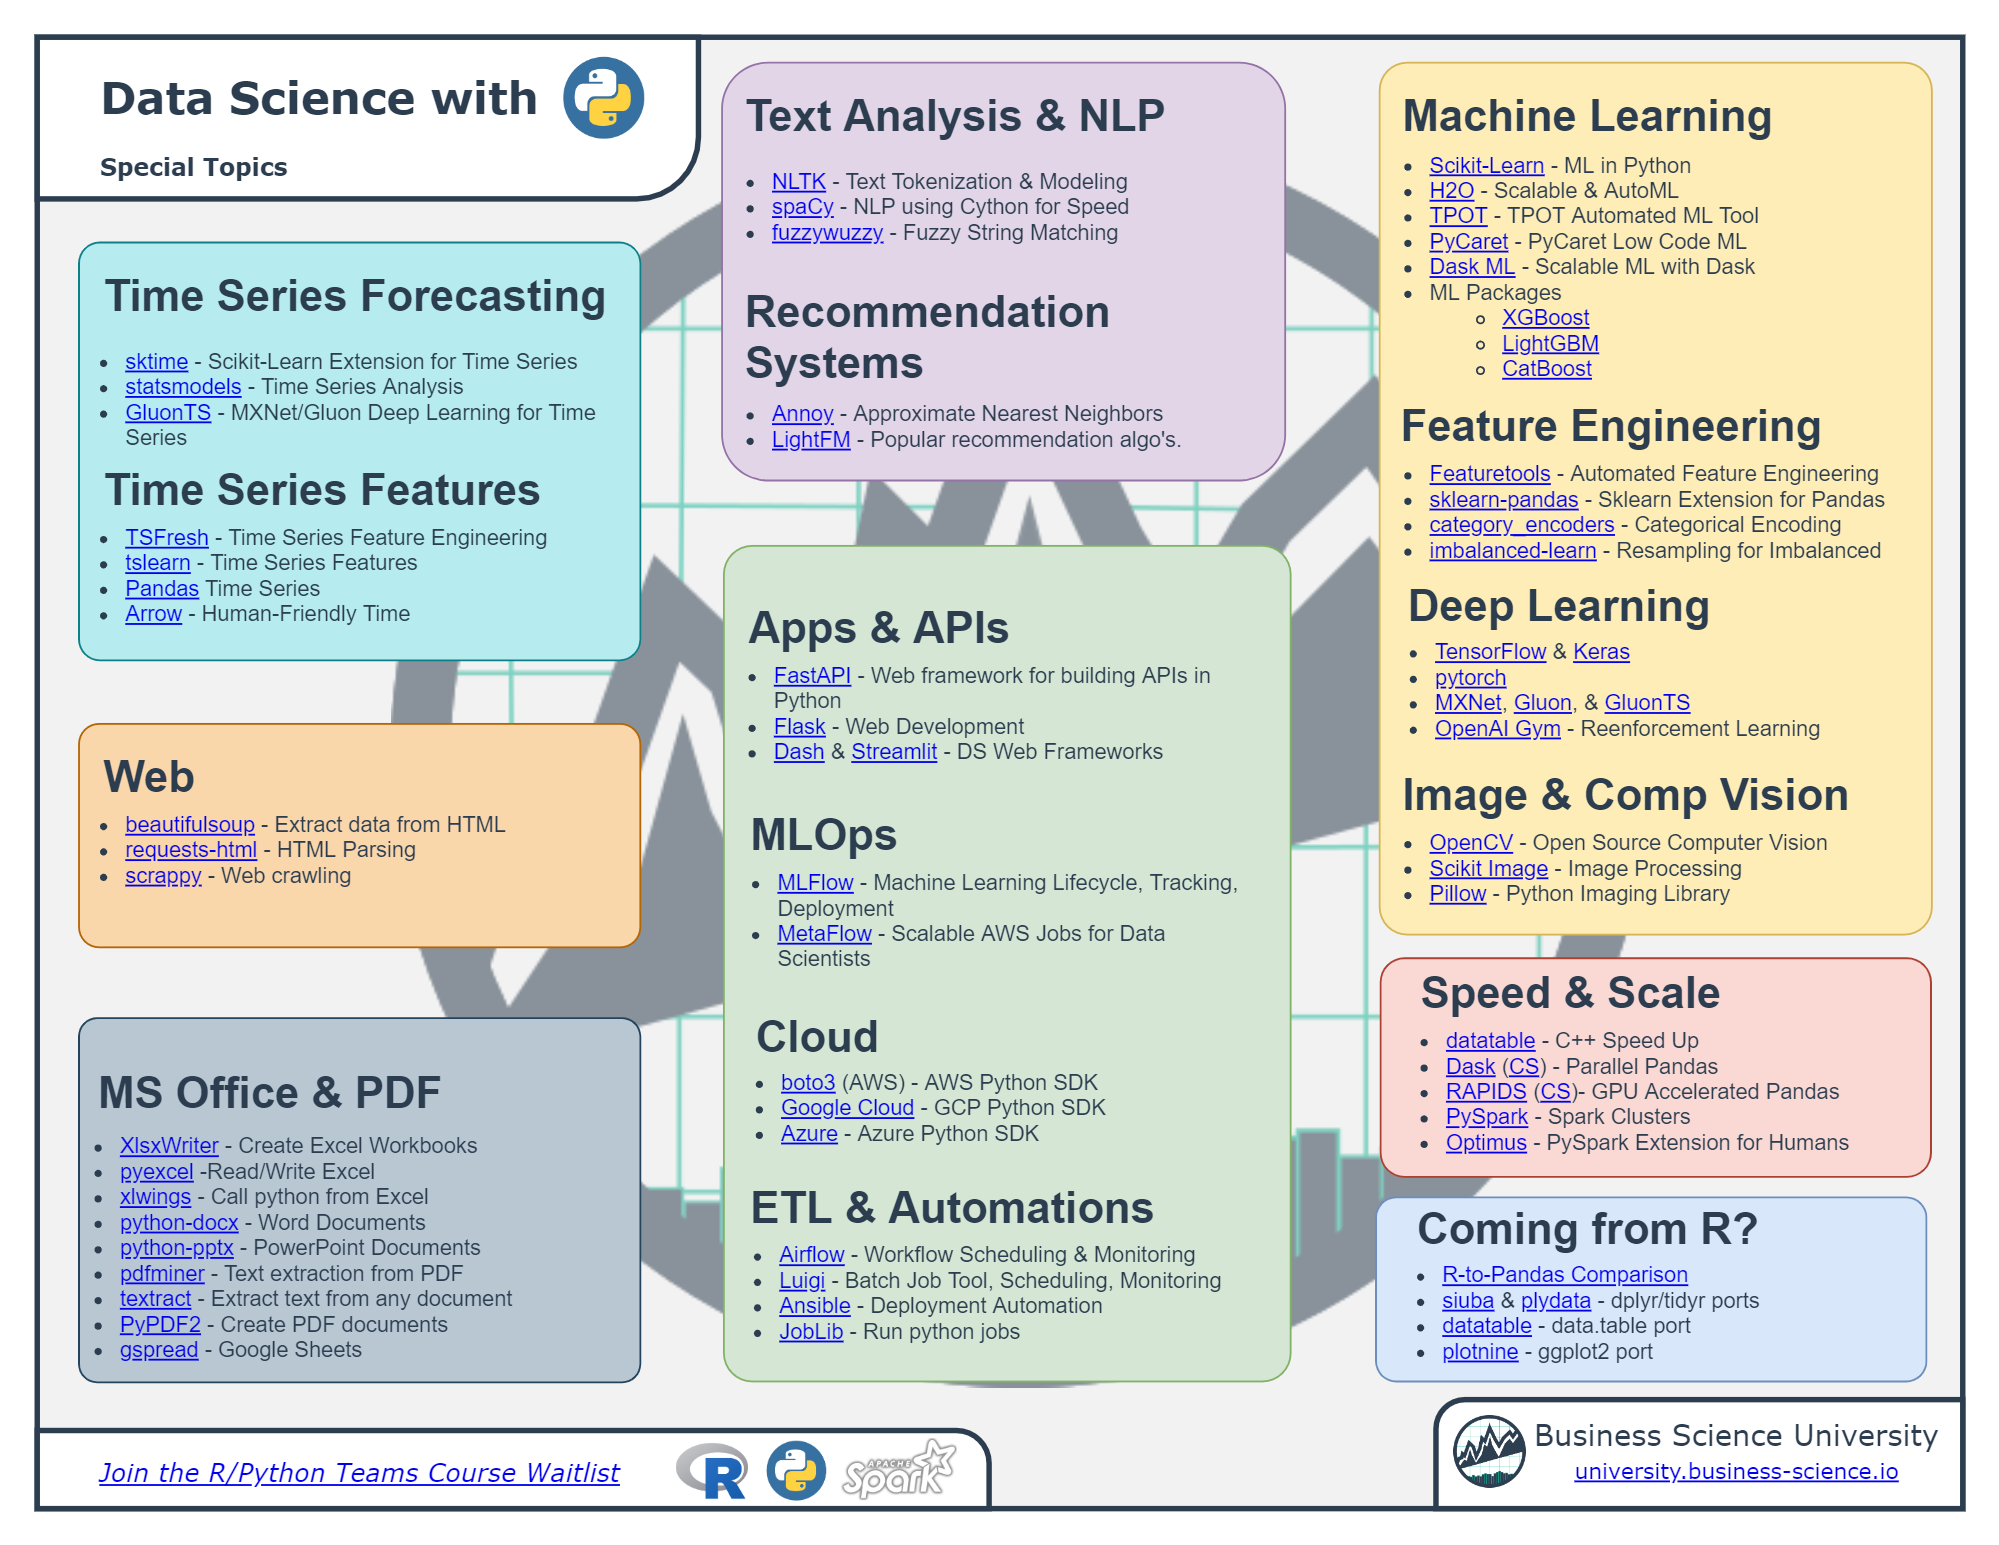
Common Mistakes I See
People make their cheat sheets too comprehensive. A thousand entries with full explanations becomes something nobody consults. You want concise, actionable lines. Code snippets over prose. If you cannot scan it in thirty seconds, it is too long. Another mistake: copying someone else's. A cheat sheet from 2022 written for pandas 1.3 will have deprecated syntax by now. Pandas dropped support for certain string methods in 2.0. If your sheet still says to use .str.contains() with regex=False as the primary example, you are teaching bad habits. Always check the version your snippets are written against. A third mistake: not including failure modes. I once spent an hour debugging a merge that was failing silently because one column was integer and the other was float. I had the correct syntax on my cheat sheet. I did not have a note saying to verify dtypes before merging. I added that after. Now every join section in my Data Science Cheat Sheet includes a dtype check reminder.
A Specific Problem and Workaround
Last year I was working on a project where we needed to aggregate hourly transaction data across multiple timezones. My initial approach used pd.Grouper with freq='H' and a UTC tz localisation. It worked fine on the sample dataset. Then I ran it against the full production data and got a KeyError on the DatetimeIndex that made no sense. The issue was that some rows had timezone-naive timestamps mixed with timezone-aware ones in the same column. Pandas accepted it during creation but rejected it during grouping. The workaround: explicitly coerce all timestamps to timezone-aware using pd.to_datetime(df['timestamp'], utc=True) before any grouping. I added this edge case to my cheat sheet under a section called "Timezone Pitfalls." Now I never hit it twice.
Where to Get Started
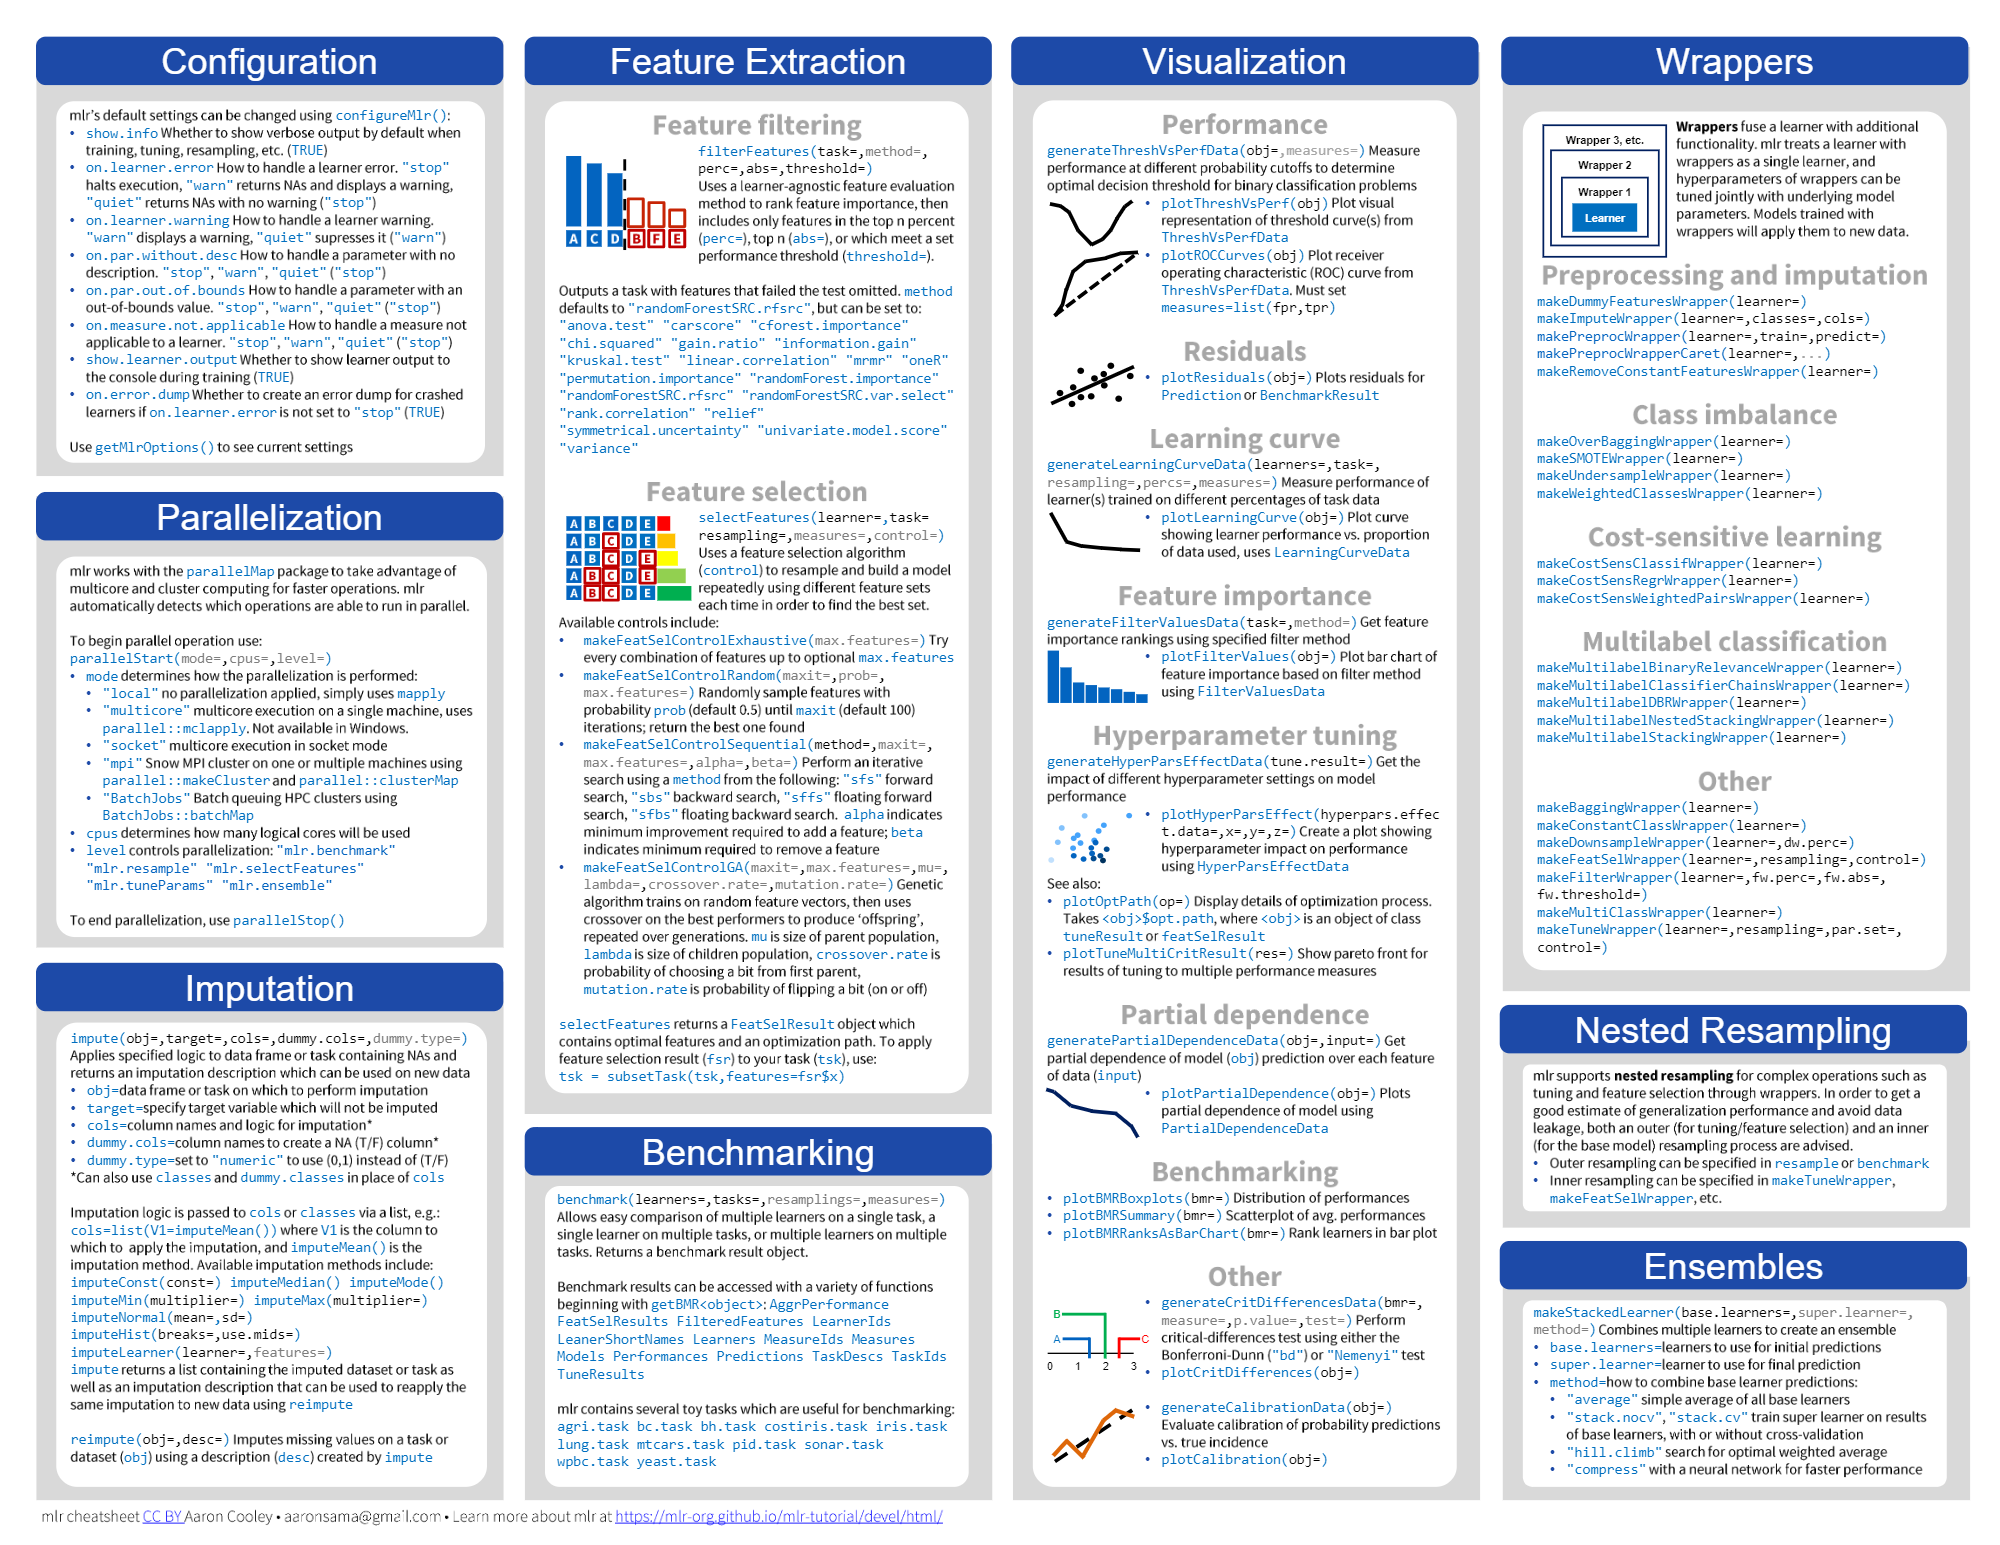
If you want a ready-made option, the official pandas and scikit-learn documentation includes printable quickreference pages. They are solid starting points but they are generic. The actual benefit comes from personalizing yours. I would recommend building yours in plain text or Markdown. Not a fancy HTML page. Something you can open in any editor, search with Ctrl+F, and edit without special software. Jupyter notebooks work too if you prefer code cells next to explanations. Include your own errors. Every time you get stuck on something, write the solution down in the sheet. That is the actual method. You accumulate it over months. It becomes genuinely useful only after you have suffered through the same problem three or four times.
Downsides to Acknowledge
A cheat sheet is a crutch. If you rely on it for everything, you will never develop the intuitive understanding that comes from repetition. It is fine for keeping momentum on routine tasks. It is not a substitute for knowing why a method works or when it breaks. Some interviewers also take a dim view of candidates who cannot write basic operations without referencing material. Know the difference between reference and crutch. Another limitation: they do not scale well to entirely new tools. When a new library becomes standard in your workflow, you start from scratch. I have done this twice now with polars and it felt like losing a season of accumulated knowledge. Consider keeping a separate mini-sheet for emerging tools so you do not bloat the main document. There is also the maintenance burden. Libraries update. Syntax changes. Deprecated functions break existing snippets. I schedule a quarterly review of my sheet. It takes about twenty minutes and prevents hours of confusion later.
Final Note
Start simple. Three sections. Twenty useful commands. Add to it when something frustrates you. Do not overthink the format. The best cheat sheet is the one you actually open when you need it, not the one that looks most organized on GitHub.