What You Actually Need When You're Deep in a Project
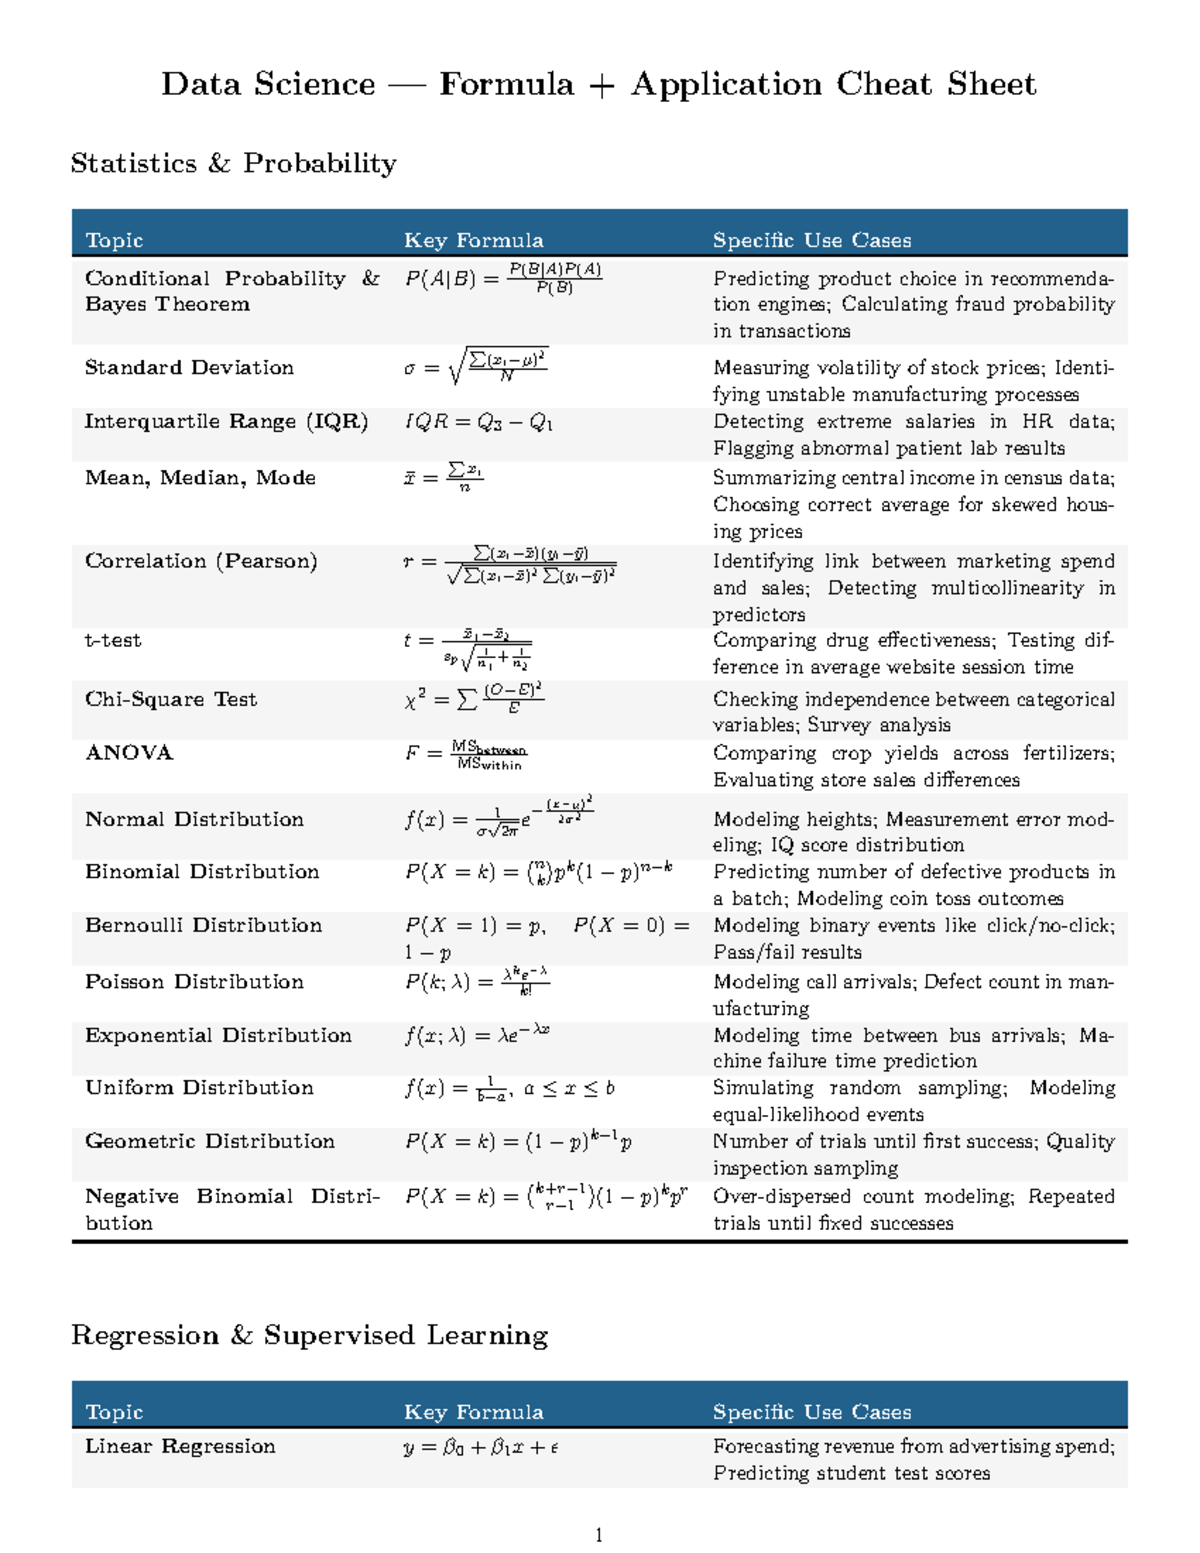
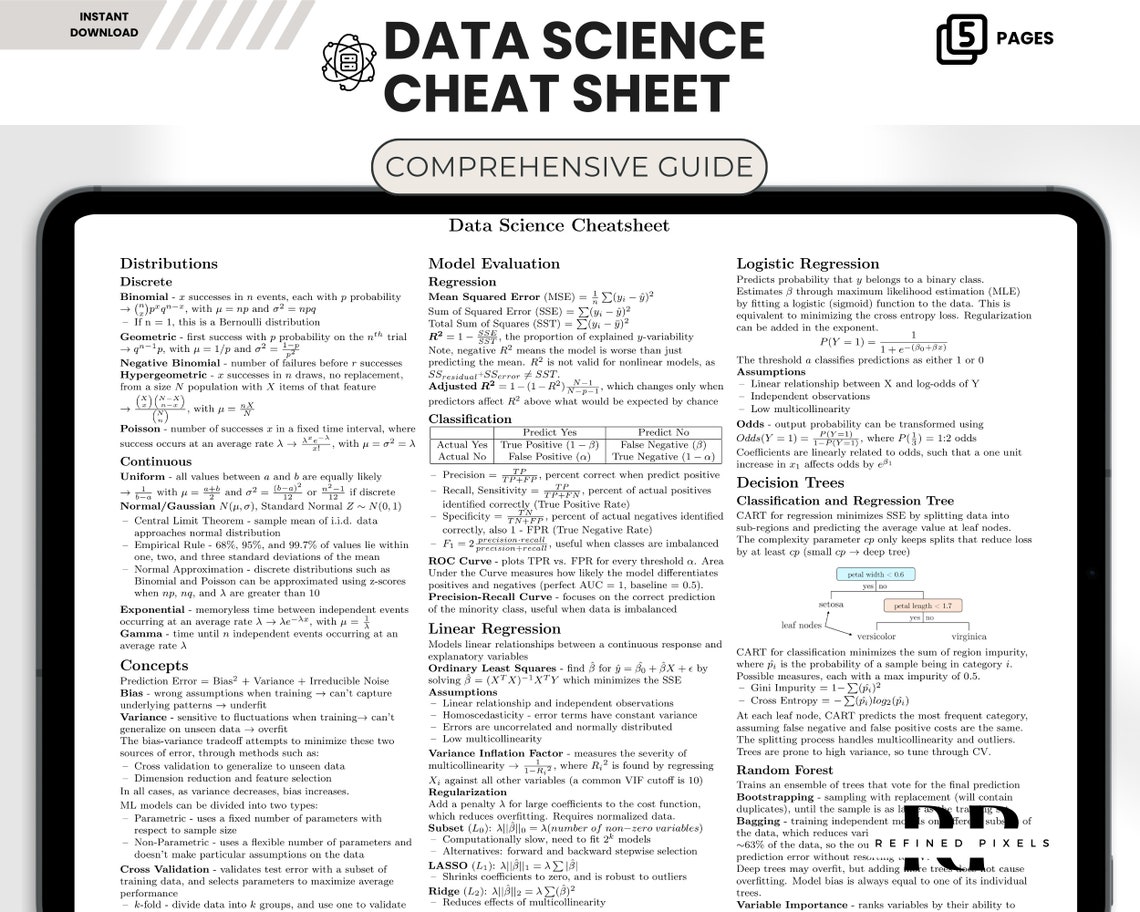
I used to keep three different cheat sheets open in browser tabs while working on a production model. Python syntax, SQL patterns, statistics references. It was messy. The industry has shifted toward consolidated references that cover the full pipeline, and the Data Science Cheat Sheet 2026 is one of those consolidated guides that actually attempts to cover pandas operations, model selection decisions, visualization choices, and evaluation metrics in a single document. Here is how it works in practice.
Data Science Cheat Sheet 2026
The cheat sheet is organized around the workflow you actually follow, not the order you learn things. That matters because the sequence changes how you use the reference. You start with data preparation, move into exploratory analysis, then modeling, then deployment considerations. Each section contains the most common functions and syntax patterns with their parameters, not full explanations of the underlying theory. For pandas, which is where most people spend the majority of their time, the sheet covers merge strategies, pivot table construction, groupby aggregations, and the difference between .loc and .iloc indexing. Beginners often skip past .loc but I have seen entire pipelines break because someone used .iloc on a DataFrame that had been filtered and reindexed. The cheat sheet shows the correct syntax for boolean indexing chains, which saves about ten minutes of debugging per occurrence. The statistics section is where most cheat sheets go wrong. They list formulas without context. This one specifies when to use a t-test versus a z-test, which assumptions each requires, and what happens when your sample size is under thirty with non-normal data. The practical detail is the note about using bootstrapping as a fallback when normality assumptions fail, with the approximate confidence interval formula included.
I ran into a specific problem last quarter where a client needed to calculate harmonic mean for a weighted averaging problem in a customer churn model. The standard cheat sheet templates all referenced arithmetic mean or geometric mean. I had to derive the weighted harmonic mean implementation from first principles because none of the standard references I had covered it. The workaround was constructing a custom pandas aggregation function using numpy's reciprocal approach, which looked like this: pd.Series(1/values).mean() inverted and then scaled by the weight column. It took me twenty minutes to implement after the reference failed me.
Get the Full Details
Model Selection and Evaluation Coverage
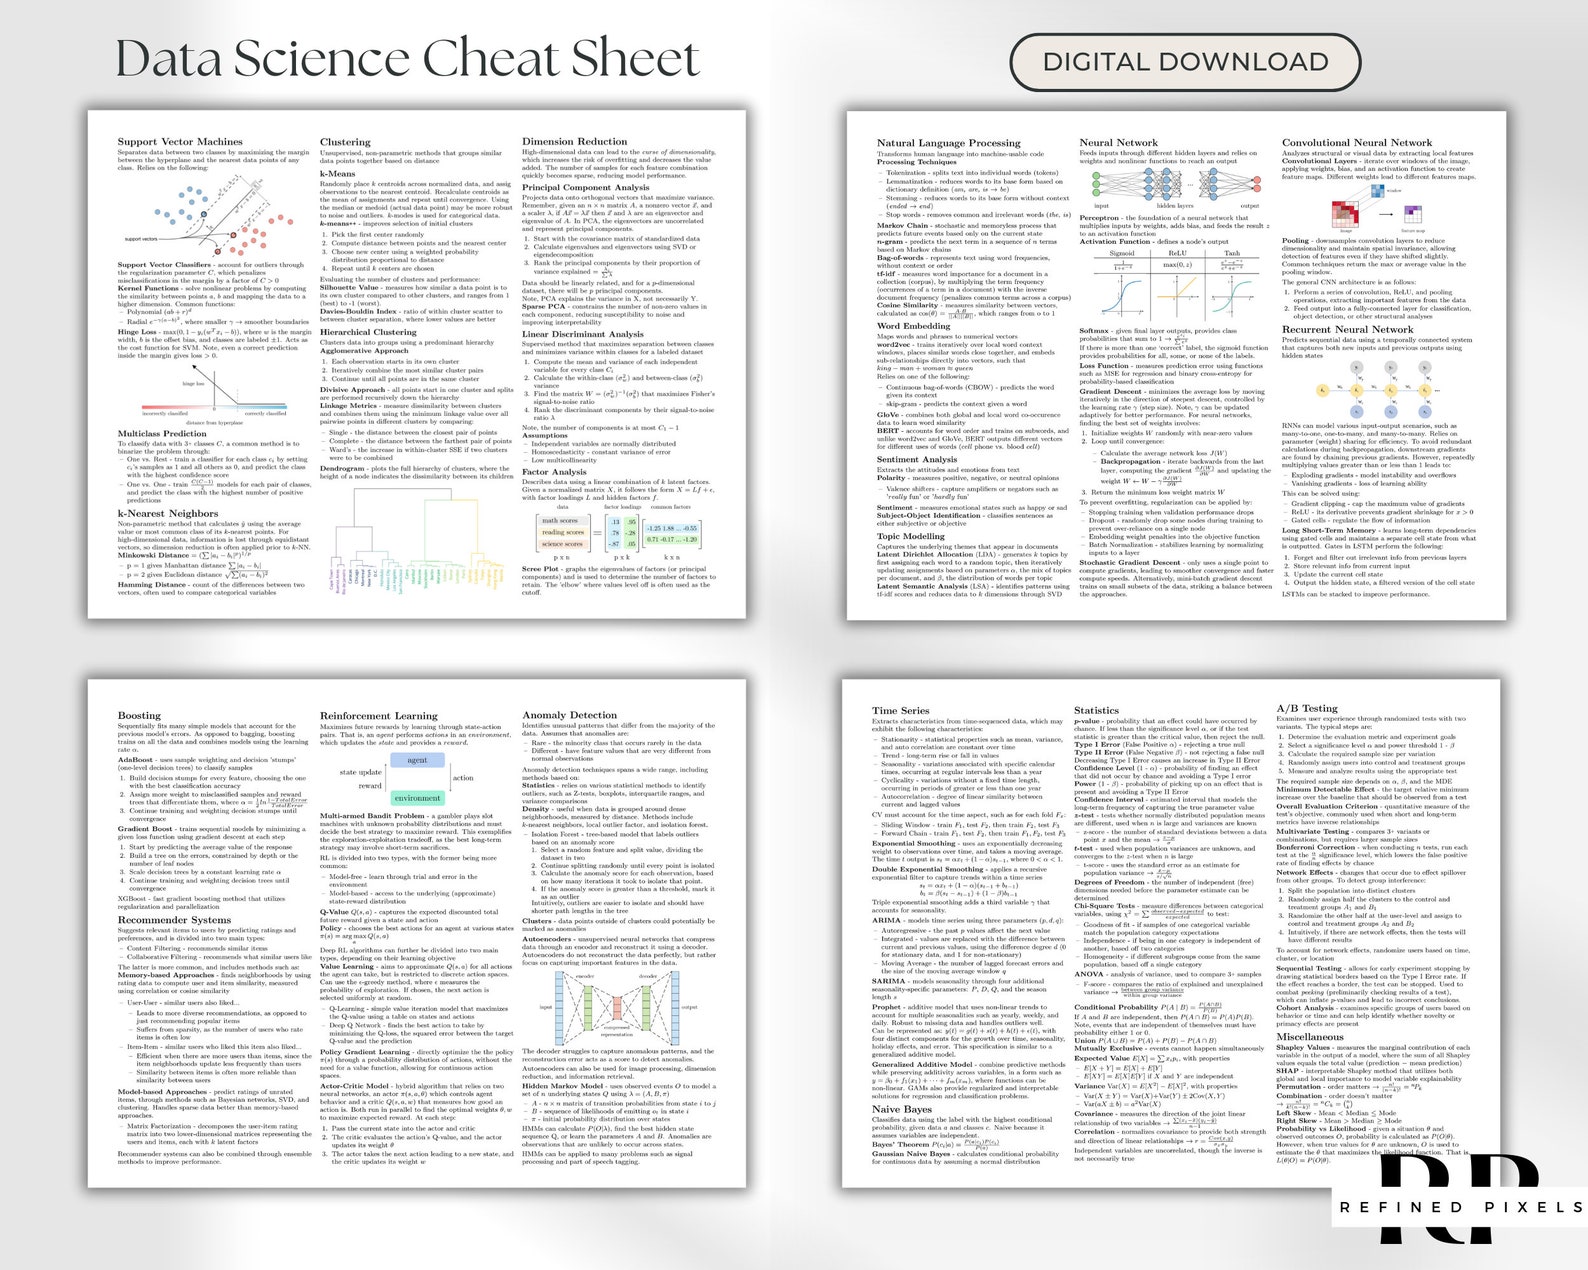
The modeling section maps directly to the scikit-learn API structure. Each algorithm entry shows the constructor signature, the key hyperparameters, and the default values. What most people miss is the section on metric selection for imbalanced datasets. The cheat sheet explicitly calls out that accuracy is useless below 85% class balance and recommends precision-recall AUC over ROC AUC when the positive class is under ten percent of your data. The cross-validation section deserves attention because it includes stratified k-fold examples for classification and time series split patterns for sequential data. A common mistake is applying standard k-fold CV to time series data, which leaks future information into training. The cheat sheet documents the correct TimeSeriesSplit pattern with a concrete example. For visualization, the guide covers matplotlib parameter tuning for publication-quality output, seaborn aggregate plotting functions, and the tradeoffs between plotly interactivity and static rendering speed. The practical guidance here is about choosing the right chart type for the data shape, not just listing every chart option available.
Deployment and Pipeline Considerations
The later sections cover model persistence with joblib, basic Flask API endpoints for model serving, and Docker container specifications for production deployment. These sections are lighter than the analysis portions but include enough syntax to get you started without searching documentation for each command. The environment setup section lists package versions that are compatible with each other. This is important because scikit-learn 1.4 breaks compatibility with numpy versions below 1.24, and pandas 2.1 requires python 3.9 minimum. The cheat sheet includes a conda environment specification block that you can copy directly.
Limitations You Should Know About
The cheat sheet does not cover deep learning frameworks beyond basic Keras API reference. If you are working with transformers, PyTorch, or custom architectures, you still need the official documentation. It also does not address cloud-specific implementations like AWS SageMaker or GCP Vertex AI workflows, which have their own syntax and deployment patterns that differ from local implementations. Another gap is the lack of coverage for streaming data processing. Tools like Apache Kafka integrations, Spark DataFrame operations, and real-time feature engineering pipelines are outside the scope of a document of this size. For those workloads, you need separate references. The statistical inference section is concise to the point of being incomplete for advanced use cases. Bayesian methods, causal inference frameworks, and multi-level modeling approaches are not included. If your work involves any of those areas, this cheat sheet will not serve as a complete reference.
How to Actually Use It Effectively
Keep it open alongside your IDE but do not read it cover to cover. The design assumes you already know which section you need and are looking up specific syntax. Reading it linearly wastes time because the document is organized for lookup, not consumption. The most useful approach is printing the pandas and evaluation sections on physical paper. Screen reading slows down syntax lookup because you are scrolling and searching. A printed reference cuts lookup time from about forty seconds to under ten seconds per query, which compounds over a long coding session. If you want to download the current version, it is available from the Sapiens AI documentation repository at the official channel. The file is updated quarterly and includes version-specific notes about deprecated functions in each library. Always check the changelog before applying patterns from earlier versions, because pandas removed the .ix indexer and some sklearn utilities changed their parameter names between versions.