Why Nobody Reads a Full Data Science Manual Anymore
I still keep a printout of my cheat sheet pinned to the wall behind my monitor. Most people think that is ridiculous because they assume you can just google anything instantly. The problem is that google gives you stack overflow threads from 2016, three different syntax variations for pandas merge depending on whether you are using version 0.24 or 2.1, and a lot of answers that work for your specific case but not the actual dataset you are sitting with at 2 AM before a deadline. A well organized reference saves you about forty five minutes on a typical debugging session, assuming you know where to look. That is roughly twenty five percent of a standard two hour data cleaning round. The whole concept started because data science has this ridiculous number of libraries and each one changes its API slightly between versions. Pandas renamed a bunch of methods between 1.0 and 2.0. Scikit learn dropped support for certain parameter combinations. Seaborn updated its color palette defaults and broke half my saved figures without warning. Having a single quiet place that documents what actually works right now, rather than what the documentation claims should work, has been genuinely useful for me over the last several years.
What Is a Data Science Cheat Sheet Cute
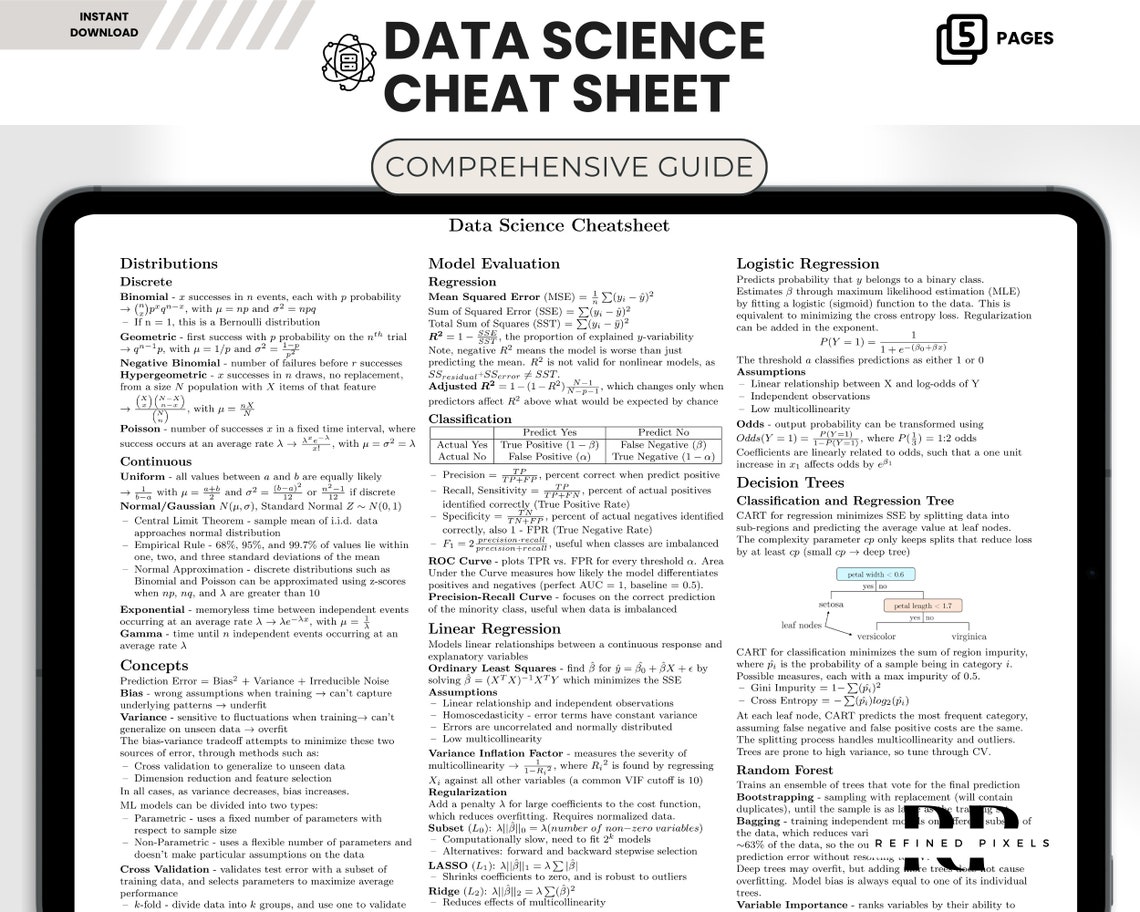
A Data Science Cheat Sheet Cute is simply a condensed reference document that pairs essential syntax and quick code examples with a softer, more approachable visual style. You will see pastel color coding, rounded corners, friendly icons, and sometimes kawaii style illustrations mixed in with the actual technical content. It is not fundamentally different from a brutalist black and white cheat sheet. The information density is usually the same. The difference is purely aesthetic and that matters more than you would expect because you will actually look at something that does not make you want to close your eyes. I have found that people who work with data for long hours tend to develop a kind of visual fatigue from staring at high contrast terminal windows and dense documentation pages. A cheat sheet with a gentle color palette and a slightly playful layout reduces that cognitive friction just enough that you remember to glance at it instead of scrolling past it. It sounds trivial. It is not when you are trying to recall whether the argument is called kind or include_groups in the groupby aggregation function.
What a Good One Actually Covers
The sections that matter are the ones you forget under pressure. Most beginners put too much emphasis on theory summaries and not enough on the actual function signatures they will need. Here is what I look for when I am evaluating or building a reference sheet: Pandas and data manipulation form the biggest chunk. You need merge and join syntax, set index and reset index, pivot and melt, datetime parsing, and the difference between loc and iloc. This is where most time gets wasted because the methods exist in multiple forms and the default parameters change behavior in ways that are not obvious until your output shape is wrong. Statistics and probability basics should include when to use which test, how to read a p value without getting philosophical about it, and the actual formulas for things like standard error and confidence intervals. Not the full derivations. The formulas you need to plug numbers into at 11 PM.
Get the Full Details

Visualization needs a section on matplotlib versus seaborn versus plotly tradeoffs, basic customization that actually moves the needle, and how to set up consistent figure styles. Most people never learn to create a default style and end up spending twenty minutes adjusting tick labels on every single plot. Machine learning shortcuts are another critical area. Model selection flow, hyperparameter names for the main sklearn estimators, train test split versus cross validation setup, and the preprocessing pipeline classes. I keep a quick reference for the exact parameter names because I cannot remember whether it is max_depth or max_leaf_nodes across every tree based model. SQL and data extraction deserve their own section because you will switch between pandas and SQL constantly. Basic joins, window functions, common table expressions, and how to translate a pandas operation into a SQL equivalent and back again.
How I Actually Use Mine in Production
I print the cheat sheet onto A3 paper and tape it to the wall. I also keep a digital version on my second monitor as a browser tab that never gets closed. When I start a new project I spend maybe ten minutes skimming the relevant sections before writing a single line of code. This does not prevent mistakes but it does reduce the initial friction of opening four different documentation pages and comparing version notes. Here is a specific example of why this matters in practice. Last month I was working with a time series dataset that had inconsistent timezone handling across different source files. Some were naive datetimes, some were UTC, and some were local time with no offset information. I spent about an hour trying different pandas timezone methods before I remembered that the cheat sheet had a section on timezone aware versus naive datetime handling with a clear warning about what happens when you concatenate them. The workaround was to explicitly convert everything to UTC using tz_localize on naive columns and tz_convert on aware columns before concatenation. I could have avoided that hour if I had looked at the reference first. Another edge case that comes up constantly is missing data behavior across different libraries. Pandas drops missing values by default in most aggregation functions, but numpy and scipy handle them differently, and sklearn refuses to fit anything with NaN values unless you use an imputer or a model that supports them natively. I keep a quick table on my sheet that shows the default handling behavior for the main functions I use, grouped by library. It is a small thing but it prevents entire categories of silent bugs.
Common Mistakes People Make With Cheat Sheets
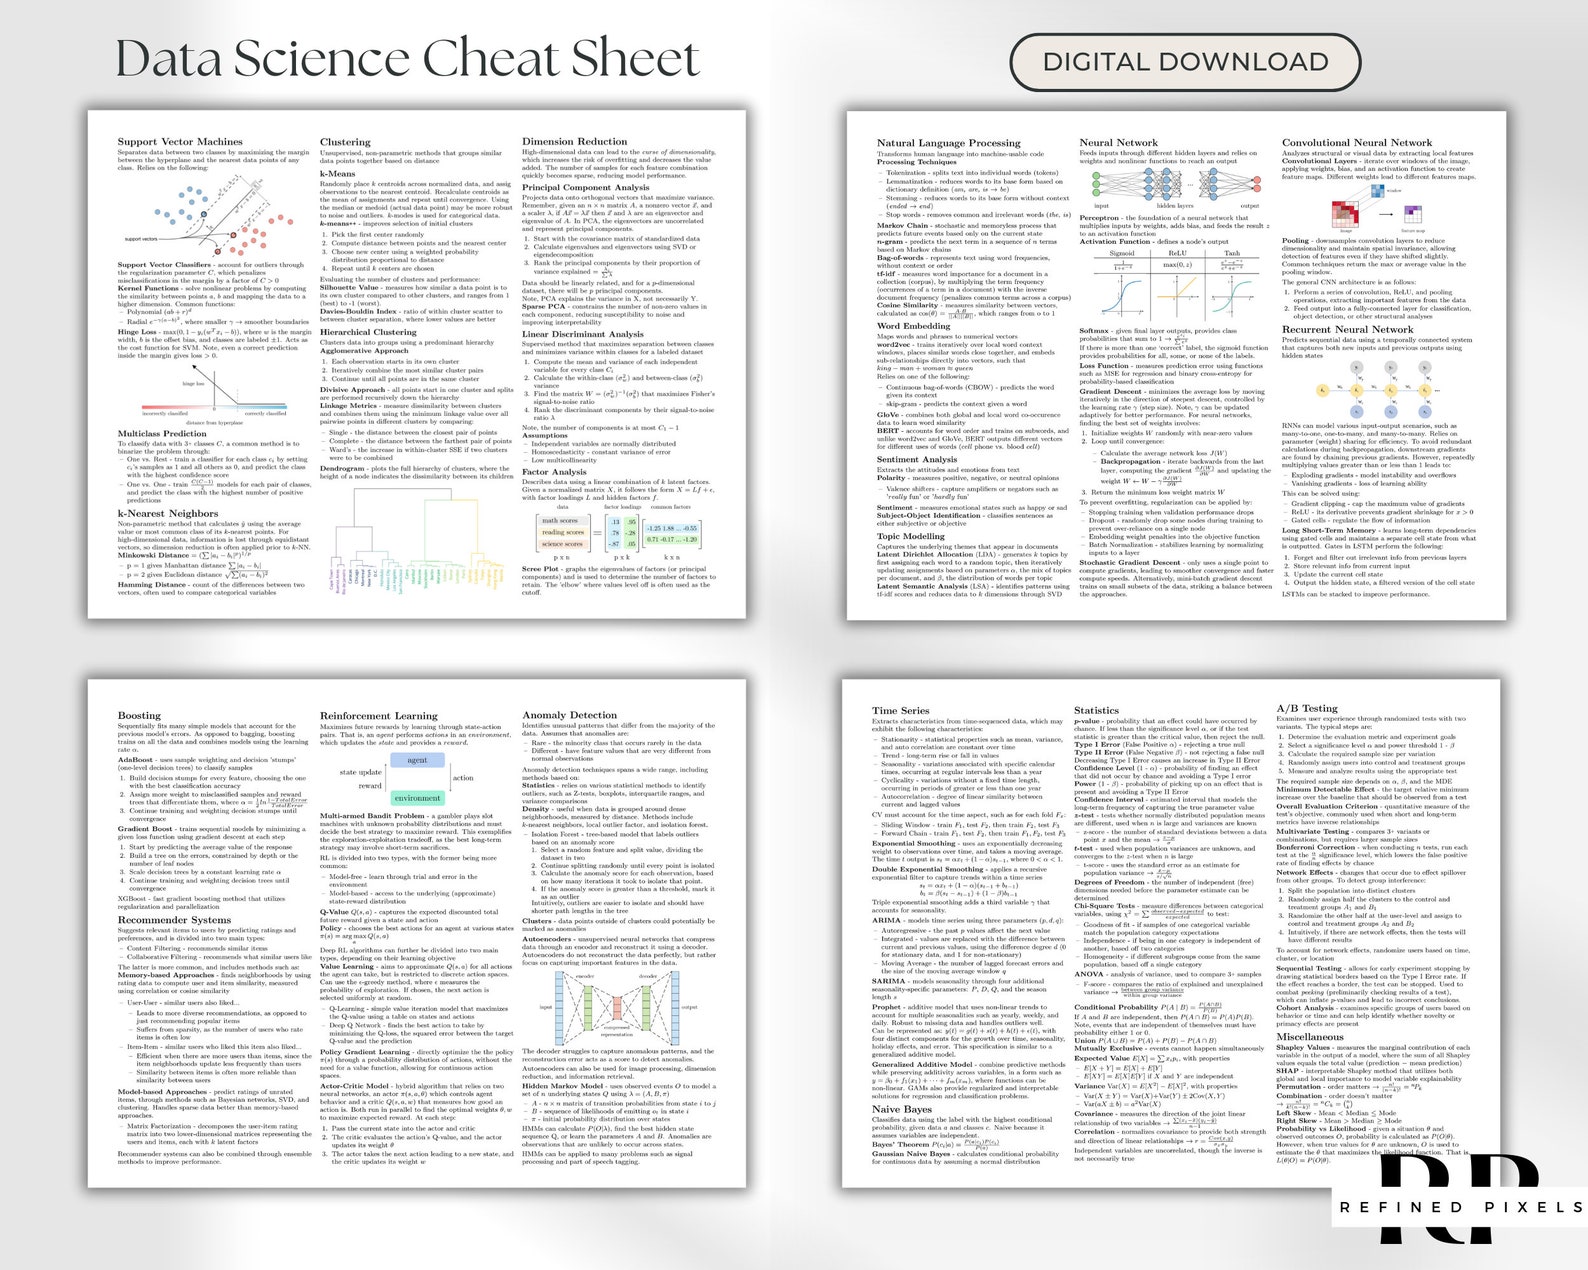
The biggest mistake is treating a cheat sheet as a substitute for understanding. I have seen people memorize syntax patterns without grasping what the underlying operation does, which leads to copying code that looks right but produces incorrect results because the input shapes or dtypes do not match. A cheat sheet is a lookup tool, not a learning strategy. You should understand the concept first, then use the sheet to remember the syntax. Another issue is outdated references. The data science ecosystem moves fast and a cheat sheet from two years ago may contain deprecated methods. I check mine against the current documentation every few months and update anything that has changed. Pandas 2.0, for example, changed several default behaviors and deprecated a handful of methods that still appear on older sheets. Some people also make their sheets too comprehensive. A reference that tries to cover everything becomes useless because you cannot find anything quickly. I keep mine to about five pages of actual content. If I cannot find a commonly used function on that sheet, I add it. Everything else stays out.
Where to Find or Build One
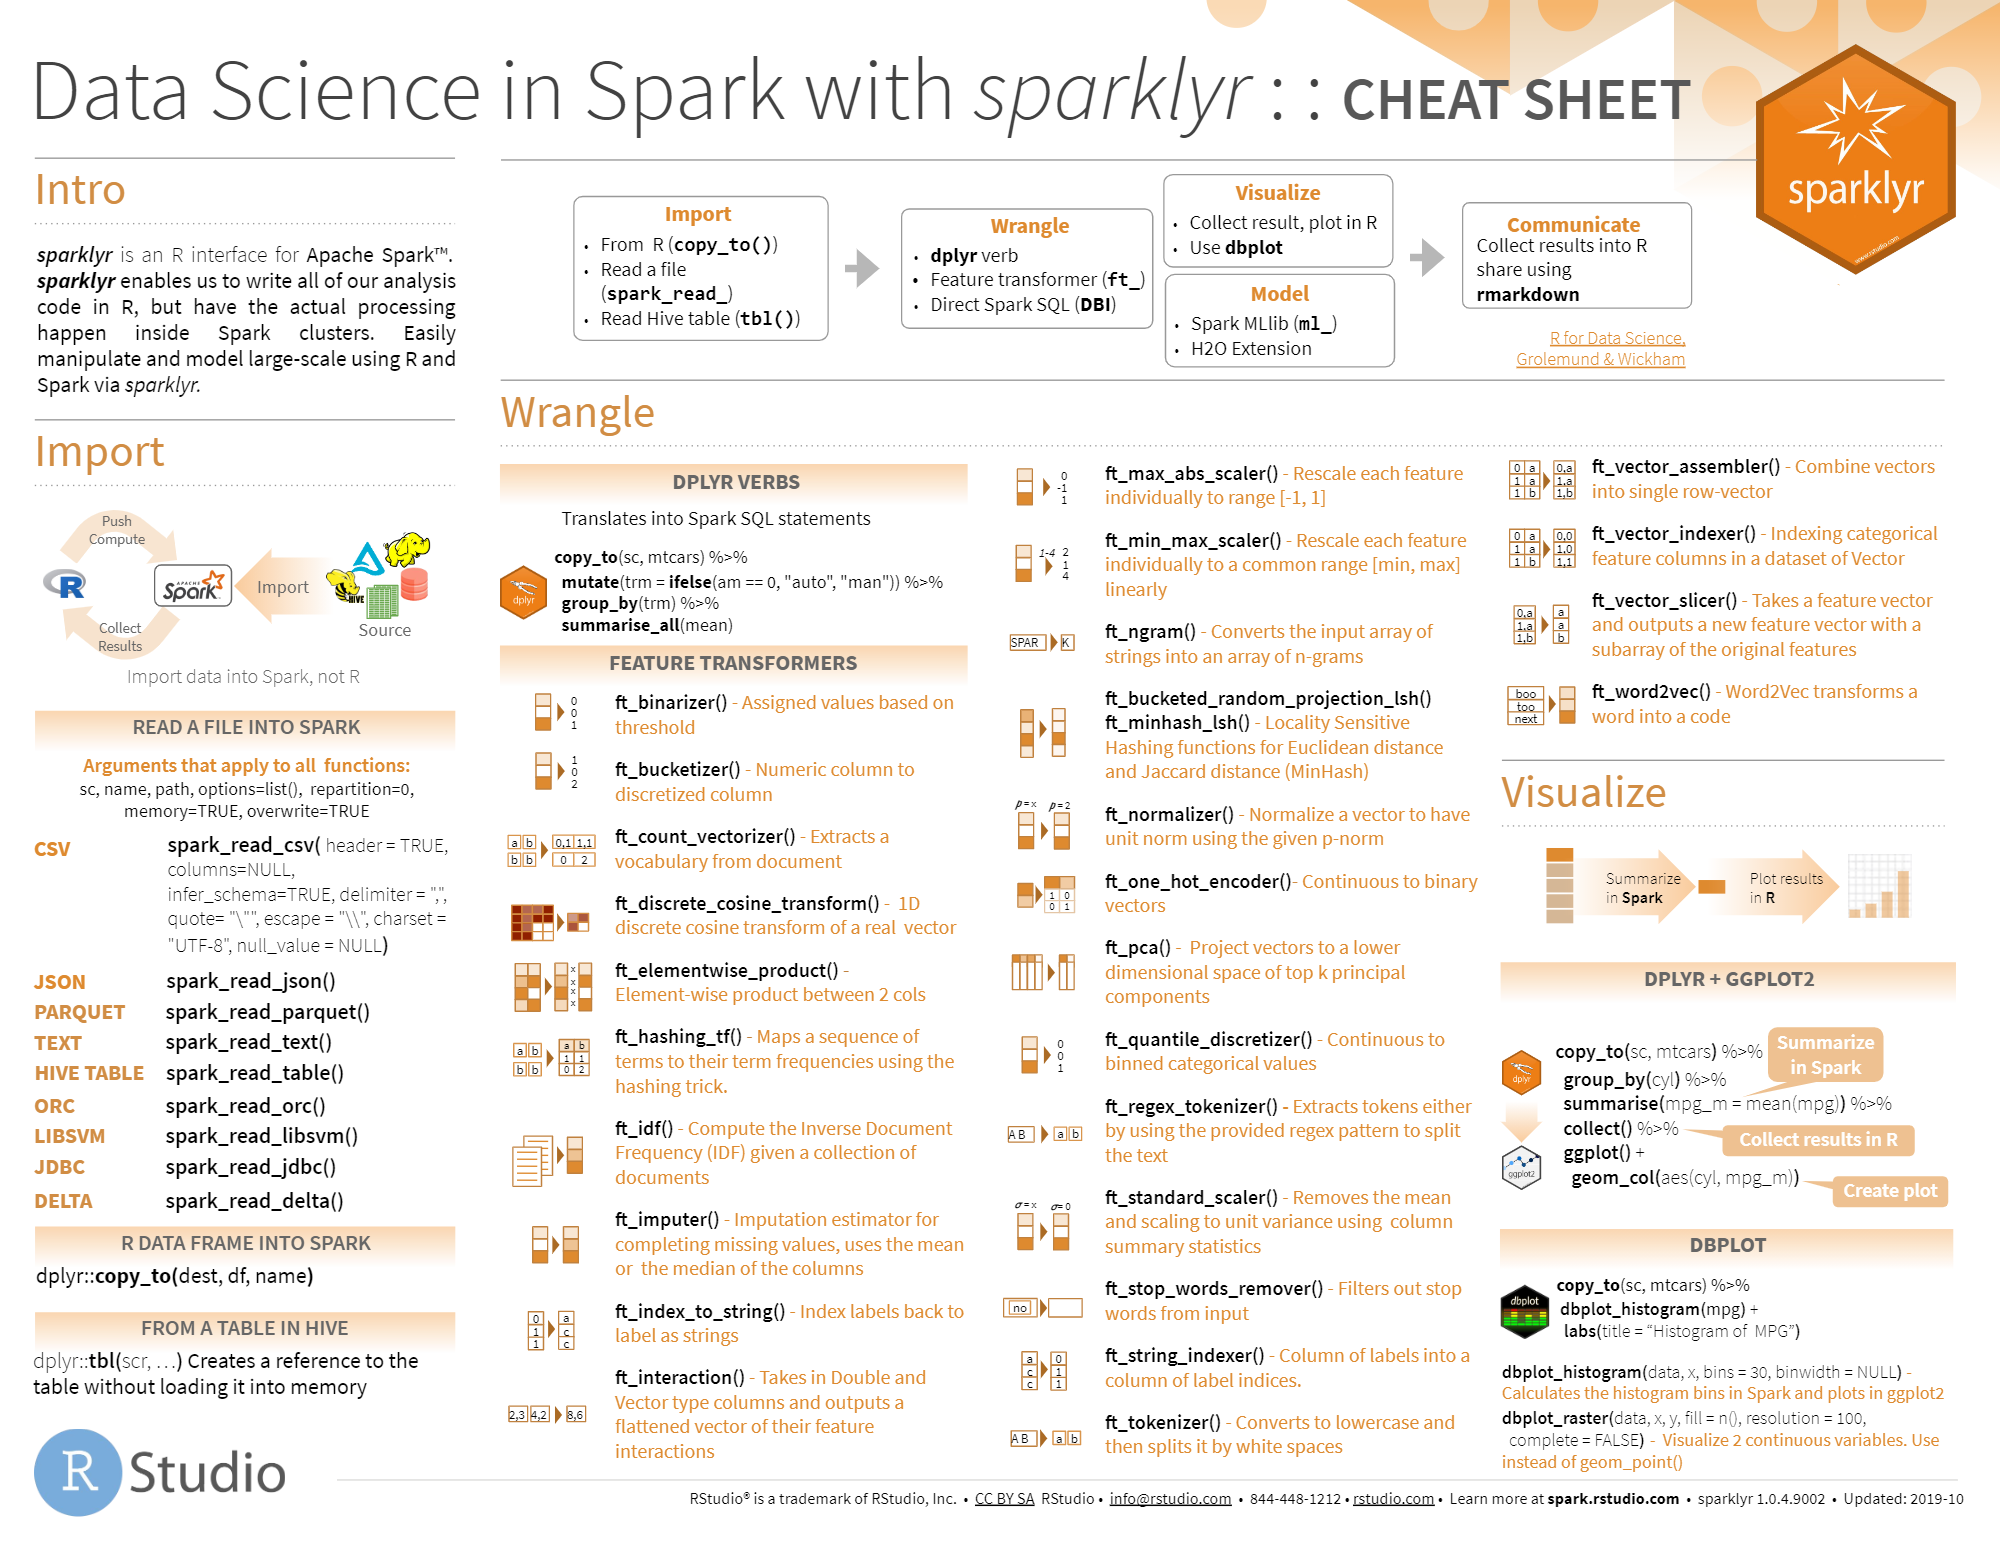
There are several publicly available options. RStudio publishes well maintained cheat sheets for pandas, ggplot2, and sql that are technically solid but visually austere. Kaggle has community created reference cards that vary in quality. GitHub has numerous repositories with printable versions, and many are released under permissive licenses. If you want something with an actual cute aesthetic, you will mostly find community created versions on platforms like Gumroad, Etsy, or individual developer portfolios. These tend to be more expensive and less technically rigorous than free options, but the visual appeal is higher. I have used both kinds and honestly the difference in practical utility is minimal. The cute ones are nicer to look at. The free ones are usually more accurate because they get updated more frequently by people who actively use the tools. Building your own is often the best option if you have specific needs. I started with a template and added the sections I actually referenced, then removed anything I never used after three months. The process of building it forced me to organize my knowledge in a way that made it stick better than any tutorial ever did. You can use tools like Canva, Illustrator, or even LaTeX if you prefer precise control over the layout.
Limitations You Should Know About
A cheat sheet cannot keep up with rapid API changes. Even if you update it monthly, there will be gaps between what is documented and what the latest release actually does. When you run into an error that your sheet does not address, you still need to read the official documentation or search GitHub issues. The sheet is a first step, not a complete solution. They also tend to be overly optimistic about edge cases. Most reference sheets show clean examples with perfect data. They rarely document what happens when your input has mixed types, missing values in unexpected places, or extremely large datasets that cause memory issues. I add these exceptions to my own sheet over time as I encounter them, but a static downloaded version will not have that accumulated knowledge. Finally, cheat sheets do not teach you how to think about problems. They give you the vocabulary and the syntax, but the actual skill of knowing which tool to reach for in a given situation comes from doing the work. I have seen people who can recite every method in a reference but struggle to build a simple pipeline from scratch because they have never practiced the integration.
The most effective approach is to use the sheet alongside actual project work. Read a section, implement it in a real dataset, note what did not work as described, and update your sheet accordingly. That cycle of use and refinement is where the real value lives.