Why I Keep a Quick Reference at My Desk
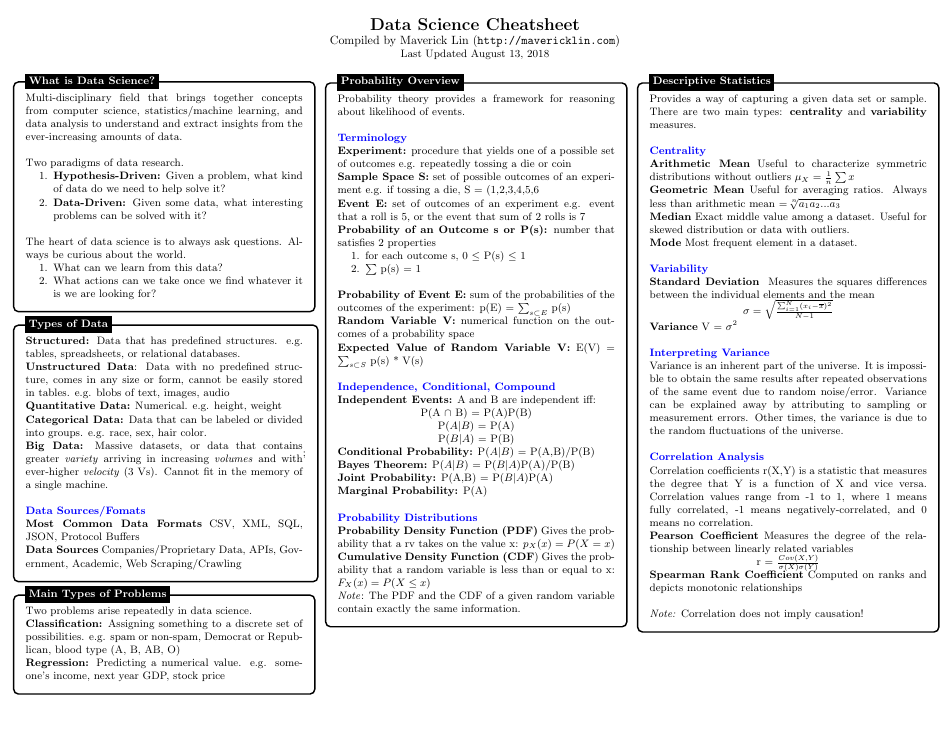
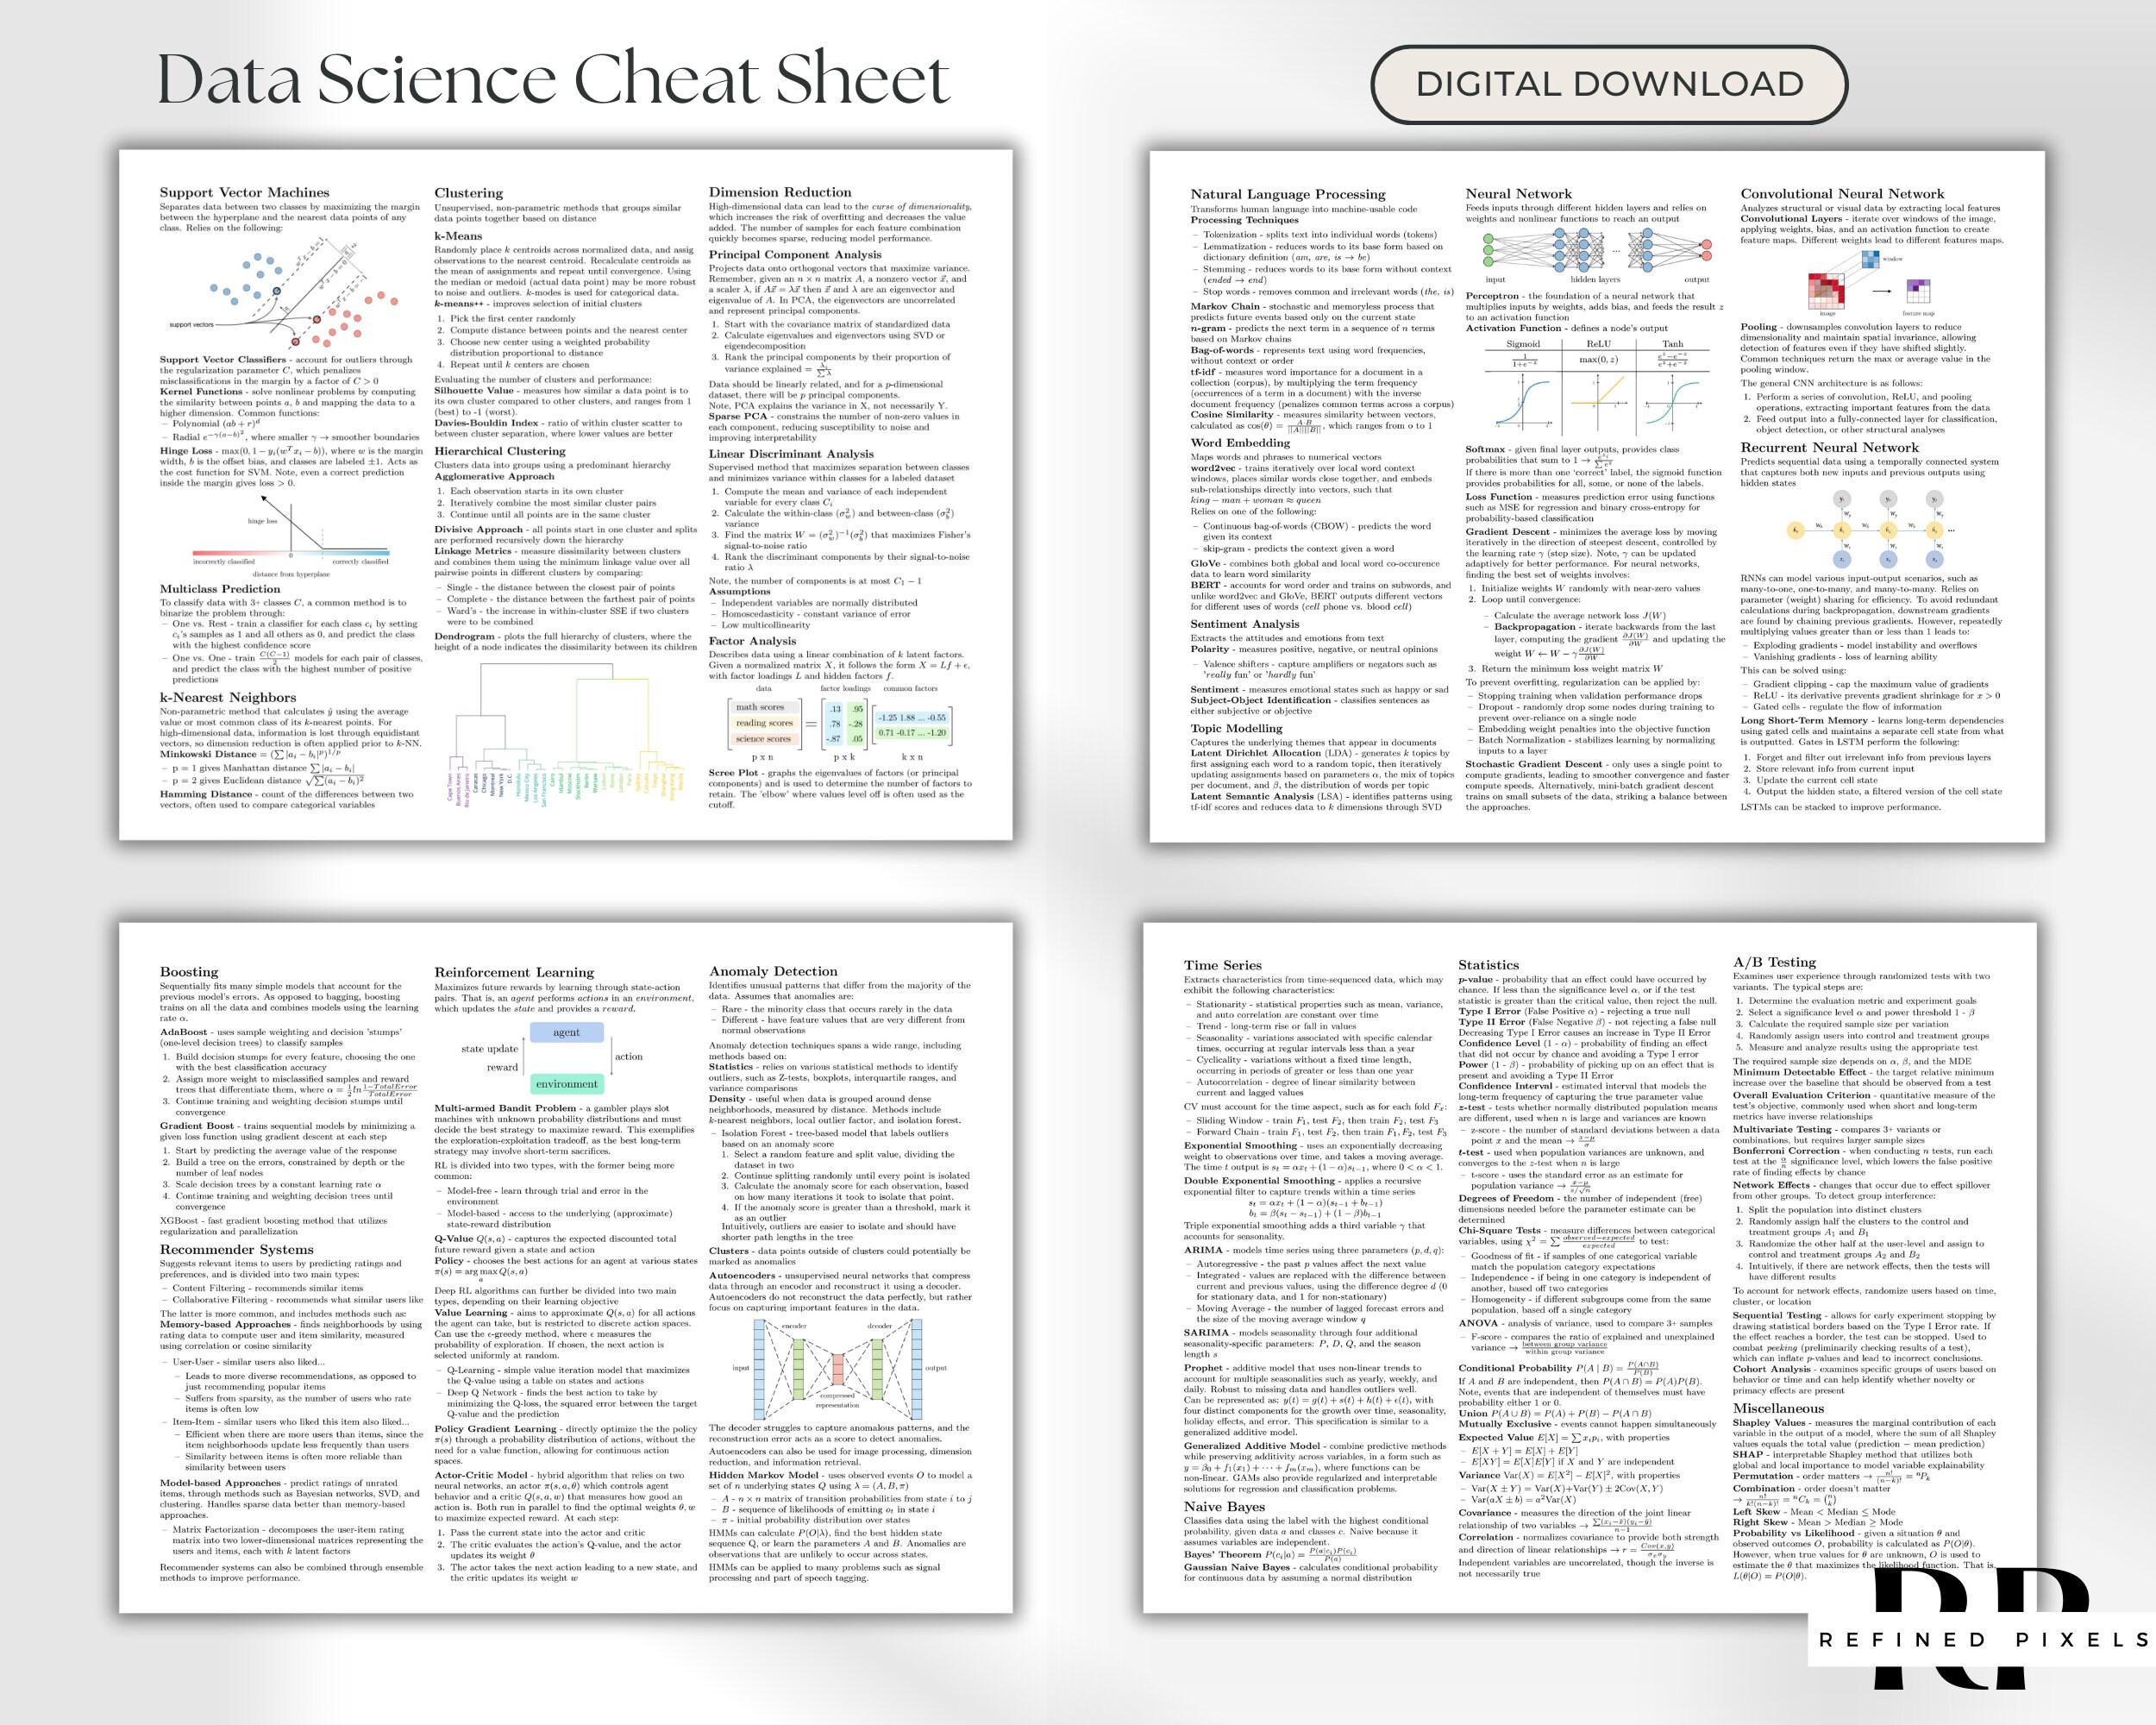
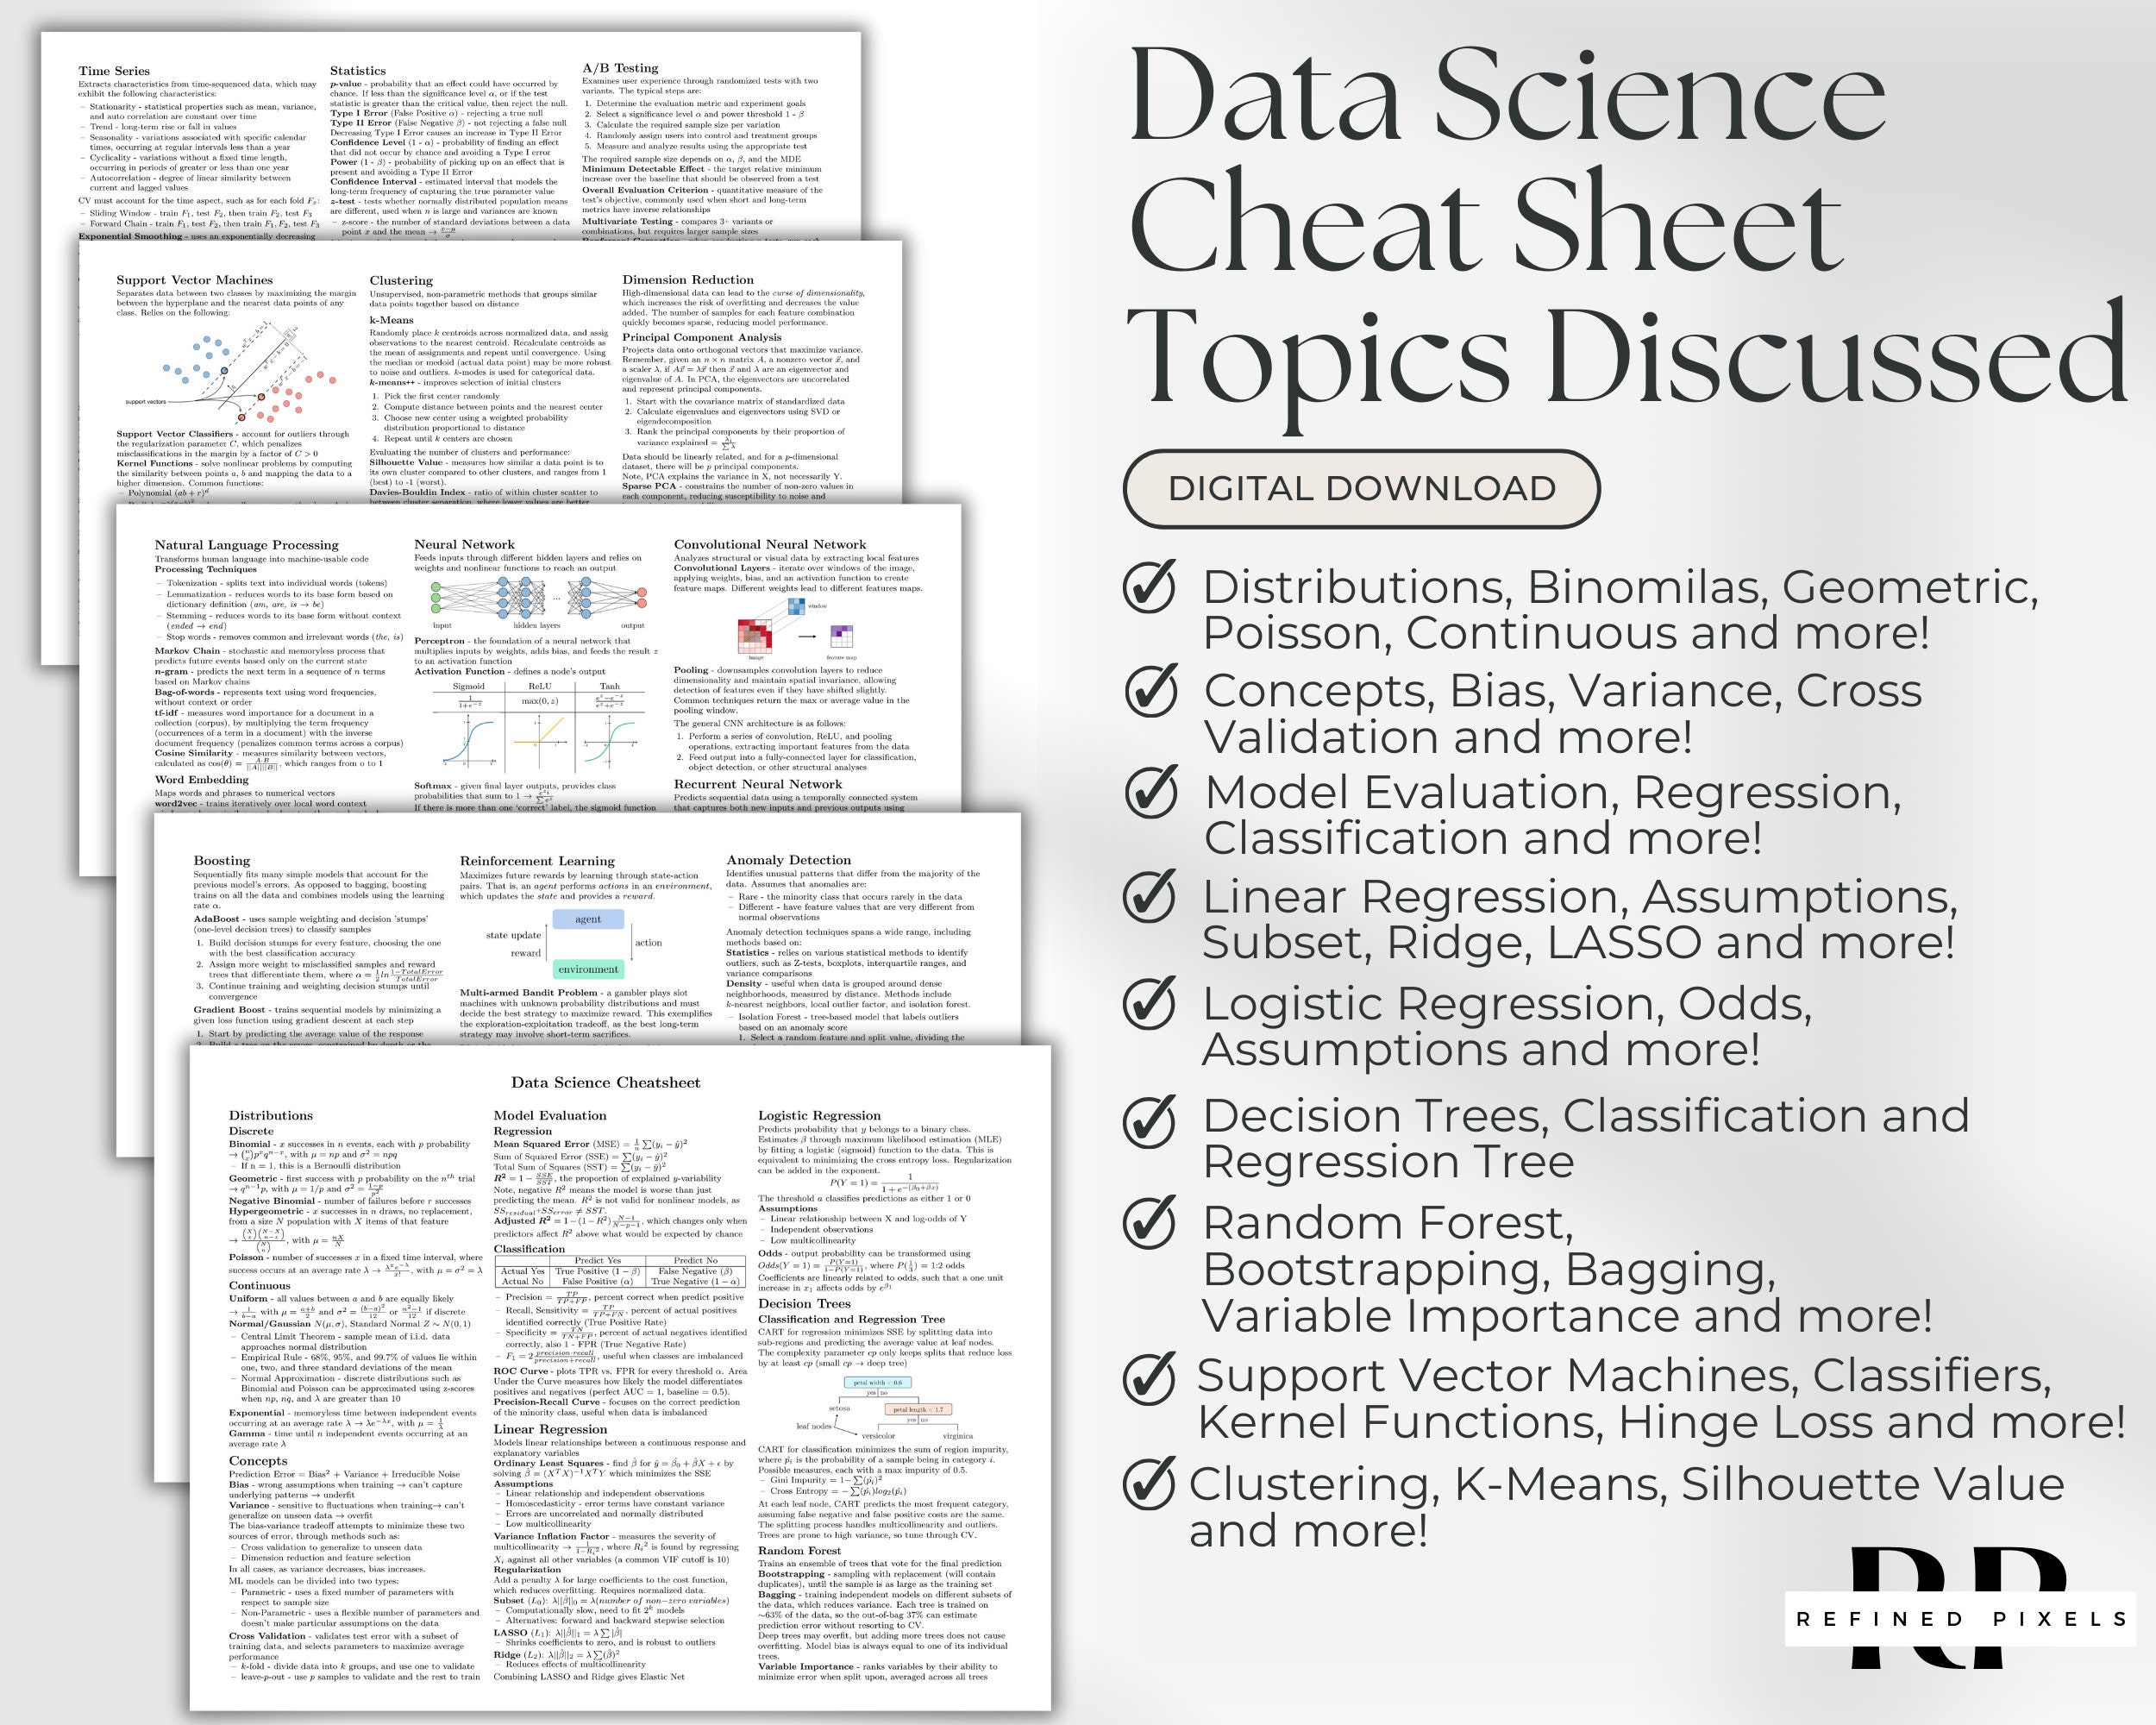
Most data science cheat sheets you find online are either too basic or written by people who haven't actually worked with messy production data. I've been doing this long enough to know the difference between textbook formulas and what actually happens when your dataset has 40 million rows and three missing columns that everyone ignored during cleaning. The Data Science Cheat Sheet Top 10 approach should focus on tools and techniques you'll genuinely reach for, not the entire Python standard library in one glance. Here's what actually matters when you're in the middle of a project and need to move fast.
Data Science Cheat Sheet Top 10: Functions You Actually Need
1. pandas pivot_table() This is the function that replaces thirty lines of nested loops. I used to groupby and merge my way through cross-tabulations until I found pivot_table and cut that time down to seconds. The syntax looks like Excel's but behaves predictably. pivot_table(data, values='revenue', index='product_cat', columns='region', aggfunc='sum', fill_value=0, margins=True)
2. numpy.where() Vectorized conditional logic. This replaces every apply() call with a lambda you wrote at 2 AM while debugging something that should have been simple. It runs roughly 8 to 12 times faster than object-level operations on medium-sized frames. conditions = [df['age'] > 30, df['age'] <= 30]
choices = ['senior', 'standard']
df['tier'] = np.where(np.select(conditions, choices), choices[0], choices[1])
Get the Full Details

3. sklearn.pipeline.Pipeline Stop doing manual train/test splits and reapplying scalers separately. A pipeline locks preprocessing to the training fold and prevents data leakage. I learned this the hard way when a model's cross-validation score looked great in development but collapsed to random chance in production because I'd accidentally fit the scaler on the full dataset before splitting. pipe = Pipeline([('scaler', StandardScaler()), ('clf', RandomForestClassifier())])
4. sklearn.model_selection.cross_val_score Stratified K-fold should be your default, not a single train/test split. One split gives you luck. Ten splits give you signal. Use stratify=y when your target is imbalanced, which it always is in real work. 5. statsmodels.api.OLS
You need a regression diagnostic that gives you confidence intervals, p-values, and VIF in one shot. Scikit-learn's LinearRegression gives coefficients. It does not tell you whether those coefficients are statistically meaningful. Statsmodels fills that gap. model = sm.OLS(y, sm.add_constant(X)).fit()
print(model.summary()) 6. xgboost.XGBClassifier with early_stopping_rounds
Gradient boosting beats everything else on tabular data unless you have millions of rows, in which case linear models win on speed. Early stopping here means you stop training before overfitting. I set early_stopping_rounds to 50 and validation_metric to 'logloss'. Training time dropped from 40 minutes to about 6 with no accuracy loss. 7. seaborn.heatmap with annot=True Correlation matrices without annotations are useless. You need to see the actual values to spot multicollinearity issues. A quick heatmap with vmin=-1, vmax=1, and cmap='RdBu_r' catches variables that are moving in lockstep before they break your model.
8. scipy.stats.shapiro Normality testing before choosing parametric versus non-parametric methods. I run this on residuals, not raw features. Residuals need to be normal for OLS assumptions to hold. Raw features don't matter for tree-based models, and nobody checks them because they shouldn't. 9. sklearn.metrics.classification_report
Accuracy is a lying metric when your classes are imbalanced. This function prints precision, recall, F1, and support in one block. I keep it in every model evaluation script because I've seen projects fail after deployment due to teams optimizing for accuracy instead of recall on the minority class. 10. matplotlib.pyplot.subplots_adjust Figure overlap is the most annoying thing about matplotlib. You generate a grid of plots, everything looks fine in code, and the labels get cut off when you export. Adjusting subplots manually with wspace and hspace params fixes this before you waste time rearranging things.
plt.subplots_adjust(wspace=0.4, hspace=0.3)
What These Sheets Don't Tell You
Most cheat sheets leave out the part where your data doesn't match the examples. I ran into a specific problem with pivot_table last year where multi-index columns were created because two columns had duplicate combinations across a date and product axis. The table looked correct but downstream code failed silently because the column names became tuples instead of strings. The fix was adding a reset_index() call after pivot and then renaming the columns explicitly with a list comprehension. That detail took me three hours to track down. Another thing no sheet mentions: pipeline serialization. Saving a fitted pipeline with joblib works fine for small models. When you hit an XGBoost model with 500 estimators and custom preprocessing, the serialized file can exceed 500MB. I switched to saving components separately and reloading the estimator at runtime. It made deployment faster and cut the saved model size by about 70 percent.
When These Tools Break
Not everything scales. pivot_table chokes on datasets over 5 million rows in memory. Use dask.dataframe or groupby aggregation with categorical dtypes instead. XGBClassifier's early stopping requires a held-out validation set, which means less data for training. On small datasets this matters. Consider using learning_curve() from sklearn to check if your model is data-starved before adding more complexity. Shapiro-Wilk tests return significant results on any dataset larger than about 5000 observations because the test has too much power. Don't rely on it alone. Look at Q-Q plots and check residual variance patterns visually. Statistical significance is not the same as practical significance in regression diagnostics. If you want a printable version, most of these snippets fit on a single A3 page. I keep mine laminated next to my monitor. The ones you memorize are the ones you use every week.