The uncomfortable truth about data science leadership
Most leaders don't actually need to know how to code a random forest. They need to understand what their data science team is capable of, where the traps are, and how to make decisions when the model outputs are uncertain. That distinction matters more than people admit.
I spent three years managing a team that built churn prediction models for a subscription service. We had an impressive AUC of 0.89 on the test set. Then we launched it into production and watched revenue actually drop for two quarters. The issue wasn't the model. It was that the engineering team had implemented the scoring pipeline using nightly batch jobs instead of real-time inference, and by the time the scores were available, the customer had already churned. I learned more from that failure than from any certification course.
Data Science For Leaders: Making It Work
What the job actually requires
Data Science For Leaders isn't about being the smartest analyst in the room. It's about creating conditions where the team can do their best work without constant interference from leadership who don't understand the feedback loop between hypothesis and validation. You need enough technical literacy to spot when someone is BSing you, and enough humility to know when to step back and let them figure it out.
The core competencies break down into four areas that most leadership programs completely ignore:
Problem framing. This is the single most important skill and the most commonly neglected one. A data science team handed a vague objective like "improve customer retention" will waste three months building something nobody asked for. A team given a specific question like "what is the probability a customer will churn within 30 days, and which intervention has the highest marginal ROI for each probability tier?" will produce something usable in six weeks. Your first responsibility as a leader is translating business ambiguity into testable hypotheses.
Data infrastructure literacy. You don't need to set up the pipeline yourself, but you need to understand the difference between a batch ETL process and a streaming architecture well enough to know why a request for "real-time dashboards" might require a complete redesign of the data layer and cost forty thousand dollars in additional engineering time. I once had a stakeholder ask why we couldn't just connect Tableau to the transactional database directly. Explaining that this would have taken down the production system for our entire app during peak hours required me to not know the answer off the top of my head but to understand enough to say "that's a bad idea" with confidence and provide the alternative.
Ethical and regulatory awareness. GDPR, CCPA, model interpretability requirements under the EU AI Act, fair lending laws. These aren't abstract concerns. They have concrete impacts on what features you can use, how you can store data, and whether your model outputs can be used for automated decision-making at all. I once had to kill a project entirely because the training data contained geographic proxies that would have violated fair housing regulations in the United States. The model itself was technically sound. The use case wasn't.
Communication under uncertainty. Data scientists will tell you their confidence intervals. Leaders need to translate those into business risk assessments. When a model says there is a 73% probability that a pricing change will increase revenue with a 95% confidence level, what you actually communicate to the board is different from what you communicate to the engineering team and different again from what you communicate to the legal department. Each audience needs a different framing of the same underlying uncertainty.
Common mistakes that cost real money
The most expensive mistake I've seen leaders make is treating data science as a delivery function rather than a discovery function. You hire a team to build models on demand, you give them a requirements document, they deliver a model, everyone is happy. Except the requirements document was based on assumptions that were never validated, the model solves the wrong problem, and the organization has spent six months and roughly two hundred thousand dollars building something that looks good on a slide deck but changes nothing operationally.
Another pattern that appears constantly: leaders who demand high accuracy metrics without understanding the cost structure of false positives versus false negatives. In my churn prediction example from earlier, the team optimized for overall accuracy, which sounded great at 94%. But the business cost of a false negative (predicting a customer would stay when they actually left) was twelve times higher than a false positive. The model was technically accurate and commercially disastrous.
There is also the toolchain problem. Leaders who insist on the latest framework because it made headlines, or who require every model to be built in Python because "that is what the industry uses," often create unnecessary friction. If your team is comfortable with R and the project involves heavy statistical testing and regression diagnostics, forcing Python adds nothing except migration overhead. I managed a team that switched from Python to Julia for a time-series forecasting project because the native probabilistic programming support reduced development time by about forty percent on that specific workload. The team was not happy about the switch initially. They were happier when the project finished two weeks early.
Building a team that doesn't require your constant input
Hiring for data science leadership requires a different approach than hiring for most other technical roles. You are not looking for the person who can reproduce a Kaggle notebook. You are looking for the person who can look at a messy, incomplete, partially migrated dataset and figure out what question it can actually answer, then communicate that limitation to stakeholders before they form expectations that will later become disappointments.
When I interviewed candidates, I stopped asking them to solve coding problems on a whiteboard after about six months. It tested the wrong thing. Instead, I would give them a real business scenario with intentionally messy parameters. Here is one I used: our support ticket volume has increased thirty percent over six months. The VP of Customer Success wants a model that predicts which tickets will escalate to management. What do you need to know before you can tell her whether this is feasible, and what would the first three steps look like?
The candidates who impressed me spent the first five minutes asking about data availability, ticket classification history, escalation definitions, and whether anyone had manually tagged escalations in the past. The candidates who disappointed me immediately started talking about gradient boosting and feature importance without understanding what the target variable actually was. Escalation is not a binary event. It is a process with multiple stages, and if your historical data only captures the final outcome, your model will learn the wrong thing.
Compensation and retention. Data scientists are in high demand and they know it. The average tenure in the industry is between eighteen and twenty-four months. You will lose people. The ones who leave usually cite one of three reasons: unclear expectations, lack of impact on business decisions, or being treated as report generators rather than problem solvers. Pay them competitively, give them problems that matter, and involve them in decision-making from the start rather than bringing them in at the end to "make the numbers pretty."
Measuring success without being fooled
AIC, BIC, cross-validation scores, precision-recall curves, F1 scores. All of these are useful. None of them tell you whether the model is making the company better off.
The metric that matters most to a leader is the decision impact. Before any project starts, you should be able to articulate what decision will change based on the model output and by how much. If you cannot answer that, the project should not start. I once saw a classification model with an AUC of 0.92 deployed for fraud detection that saved the company approximately eight thousand dollars per year in prevented fraud, while costing forty thousand dollars annually to run in cloud infrastructure and engineering overhead. The model was excellent. The business case was negative.
I also stopped trusting accuracy and F1 scores almost entirely after the churn incident. They are easy to game, easy to misunderstand, and rarely aligned with actual business outcomes. Instead, I pushed for expected value calculations tied to real unit economics. What does it cost to intervene with a customer predicted to churn? What is the lifetime value of that customer? What is the cost of a failed intervention? Multiply those together with the model's predicted probabilities and you get a number that actually reflects whether the project is worth doing.
When data science is the wrong answer
This is the part most leaders won't hear from their data teams. Sometimes the answer is already obvious and collecting more data is just procrastination dressed as rigor. Sometimes a simple rule-based system does the job without the maintenance overhead of a machine learning pipeline. Sometimes the right answer is to hire a person rather than build a model.
I had a case where leadership wanted a predictive model for employee attrition to flag at-risk workers. The data team prepared the pipeline, gathered features, and started training. I sat on the project for two weeks before telling the VP of HR that we already knew who was leaving. The answer wasn't hidden in the data. It was in exit interviews, in manager 1-on-1 notes, in the fact that people tend to announce they are leaving three to four months before they actually walk out. A model wouldn't improve on that signal. What would improve it was actually acting on the signals we already had.
Use data science when the pattern is non-obvious, the volume of decisions is too large for human judgment, and you can measure the outcome. Do not use it when a policy change, a process redesign, or a conversation with the right person would be faster and cheaper.
Gallery Data Science For Leaders
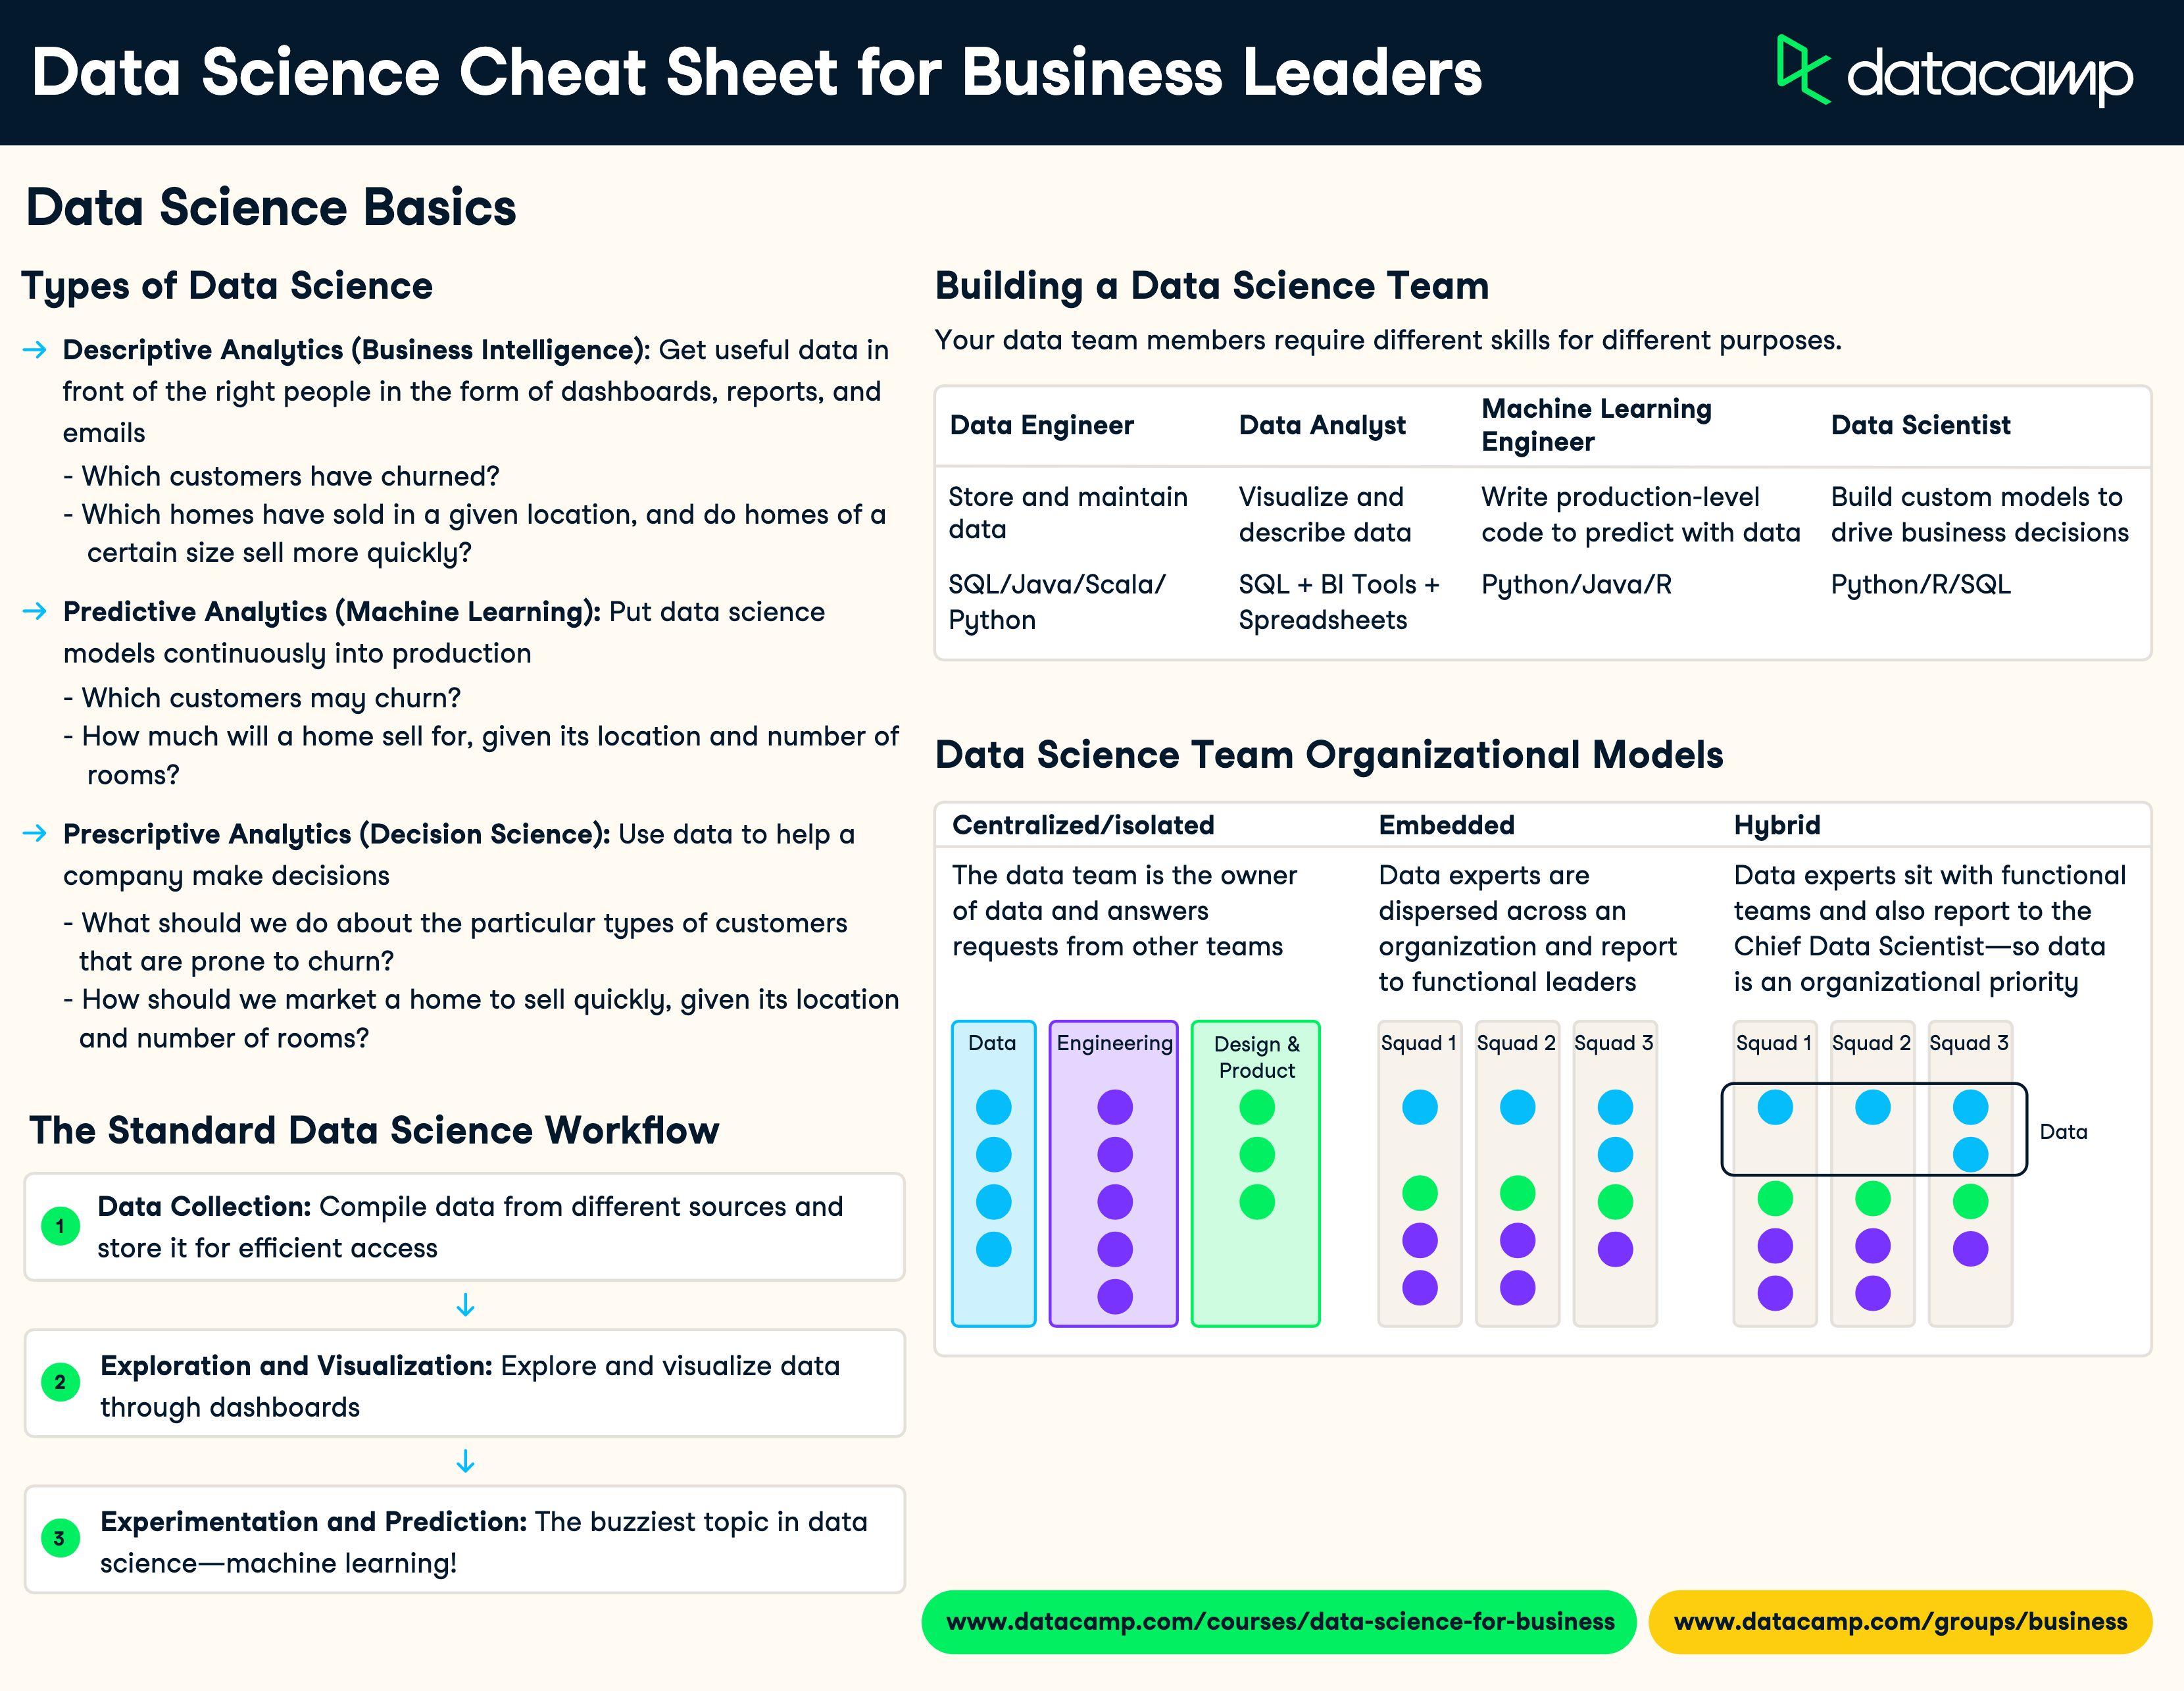
Data Science Cheat Sheet for Business Leaders | DataCamp
Data Science for Business Leaders
12 Inspiring Data Science Leaders for 2024 - Fusion Chat
Top Data Science for Business Leaders Certification 2025
Online Course: Data Science for Business Leaders from Pragmatic Institute | Class Central