Why most people skip the boring part and pay for it later
Data science projects don't fail because the model is wrong. They fail because someone built a beautiful pipeline on top of garbage data and called it a day. I spent three weeks debugging a production model that kept drifting, only to find the feature store had silently switched from reading parquet to reading CSV somewhere in the staging environment. The schema was identical, but the timestamp formatting differed by timezone. That kind of thing ruins your week. If you are starting fresh, or trying to get up to speed this year, here is how the landscape actually looks when you strip away the hype. This isn't a theoretical overview. It is a practical Data Science Guide 2026 based on what I have seen work in production environments over the last few years.
The Data Science Guide 2026: what actually matters now
The field has shifted. A few years ago, everyone was racing to publish the highest accuracy number on a Kaggle leaderboard. Now the game is different. It is about deploying models that don't break when the data distribution shifts five percent from what you trained on. It is about building systems that run reliably month after month without constant manual intervention. Here is what you need to know about the current state of things, not what the courses tell you. Python is still the baseline. It remains the dominant language for data science work. Pandas, NumPy, Scikit-learn, PyTorch, and similar libraries cover most day-to-day needs. R has its place in certain academic and statistical niches, but for anything involving production deployment, Python is the safer choice. You will find more hiring opportunities, more community support, and more tooling options. This isn't a controversial take. It is just where the ecosystem landed.
SQL is non-negotiable. You cannot do data science without querying data, and most enterprise data lives in databases. Knowing how to write efficient queries, understand joins across large tables, and spot when a subquery is making your code crawl will save you from a lot of frustration. I recently joined a project where the initial analysis took eight hours because someone wrote a left join that scanned the entire table instead of filtering first. A simple WHERE clause before the join brought it down to four minutes. The tooling has fragmented and then partially consolidated. You will see people recommend different stacks depending on who they follow online. In practice, most teams converge on a handful of tools: Jupyter or VS Code for exploration, Docker for reproducibility, and some form of cloud platform for running pipelines. The specific choices matter less than understanding why you are choosing them.
Get the Full Details
Building a working foundation without overcomplicating it
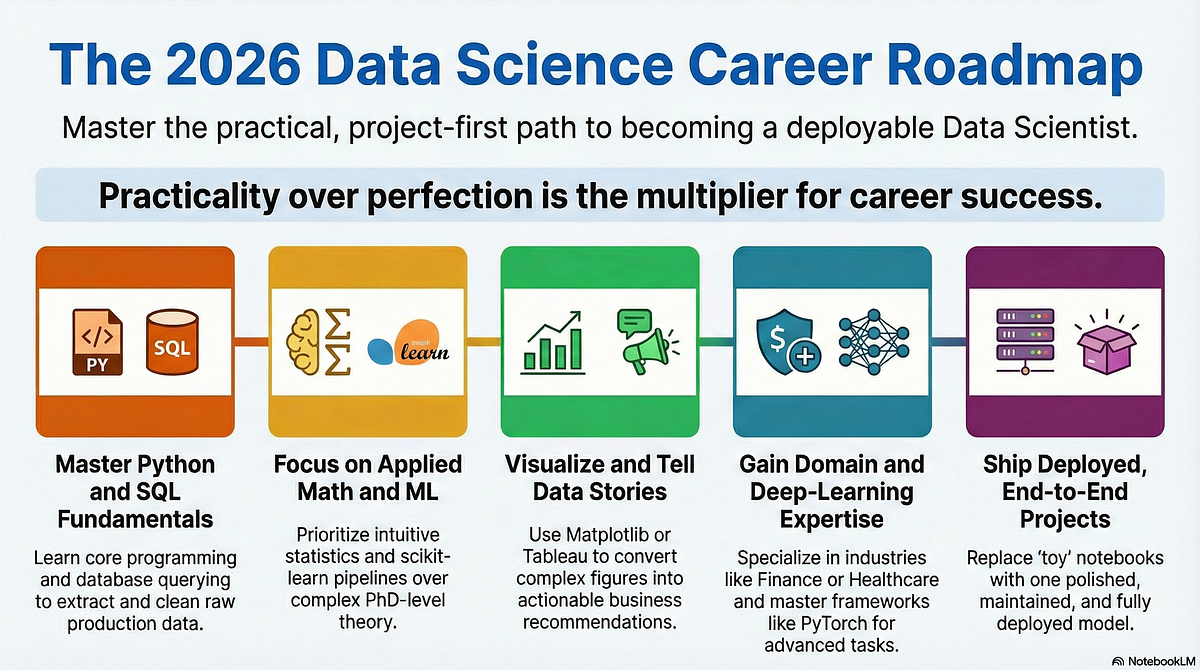
Most beginners try to learn everything at once. They start with statistics, then machine learning, then deep learning, then MLOps, all before they have built a single thing end to end. That approach usually leads to burnout or shallow understanding across the board. A better path is to build something small and complete, then add depth where it matters. Start with a project that has a clear question and accessible data. Find a dataset on something you actually care about. Maybe it is sports statistics, maybe it is music metadata, maybe it is weather patterns in your region. The domain doesn't matter much for learning. What matters is that you care enough to push through the tedious parts. Build the full pipeline. Load the data, clean it, explore it, train a model, evaluate it, and save the results. Even if the model is simple. Even if the code is messy. You need to feel the complete loop to understand where things actually go wrong. I learned more from my first terrible project than from any tutorial series. It had missing values I didn't handle properly, a leaky feature I didn't catch until evaluation, and a deployment step I skipped entirely. All of those failures taught me something real.
Focus on data cleaning before modeling. This is where most people underestimate the time investment. Expect to spend sixty to seventy percent of your project time on data preparation. The remaining thirty percent is split between modeling, evaluation, and communication. If you are finding yourself spending equal time on cleaning and modeling, your data quality is probably worse than you think and you need to go back to the source. Learn to read error messages. This sounds obvious but it is genuinely the skill that separates people who finish projects from people who abandon them. Most error messages contain the exact line number and a description of what went wrong. Google the error text. Stack Overflow has the answer for almost every common failure mode. I still do this regularly even after years of experience. Someone else has definitely encountered your exact problem before.
Machine learning in practice: what the textbooks leave out
Textbook machine learning teaches you ideal conditions. Your training and test data come from the same distribution. Your features are clean. Your labels are accurate. Reality is considerably messier. One thing that never gets emphasized enough is the importance of your validation strategy. Random train-test splits work fine for static datasets. They fail catastrophically for time-series data, grouped data, or anything with temporal or structural dependencies. I once worked on a churn prediction model where the random split gave us ninety-two percent accuracy. When we validated on a time-based holdout from the following month, accuracy dropped to sixty-four percent. The model had essentially learned patterns from the training period that didn't generalize. Switching to a time-series split during development would have caught that immediately. Feature engineering matters more than model choice for most problems. A well-engineered feature set with a simple logistic regression often outperforms a complex model with raw features. This is especially true when you have limited data. Deep learning models need volume. Tree-based models and linear models can extract signal from smaller datasets if the features are constructed thoughtfully.
Watch for data leakage. This is the silent killer of data science projects. Leakage happens when information from the target variable or future data accidentally enters your training set. Common sources include aggregating data after the fact, encoding categorical variables using global statistics instead of per-fold statistics, or including features that shouldn't exist at prediction time. During one project I was working on, a customer ID column was accidentally left in the feature set. The model achieved near-perfect accuracy because it was essentially memorizing IDs rather than learning patterns. The fix was careful column-by-column auditing of every feature against the prediction timeline.
MLOps and the part nobody talks about until it breaks
Training a model is the easy part. Getting it into production and keeping it there is where projects typically fall apart. I have seen fully trained models sit unused for months because no one documented the environment setup, the data pipeline dependencies, or the retraining schedule. The minimum viable production stack involves versioning your data, your code, and your model artifacts. DVC or similar tools handle data versioning. Git handles code versioning. Model registries track which model performed best under which conditions. Without these, you will eventually need to reproduce a result and have no idea which version of which dataset produced it. Containerize everything you ship. Docker containers solve the classic problem of "it works on my machine." Define your environment explicitly, lock your dependency versions, and ship the container. This adds overhead initially but eliminates entire categories of deployment failures later. The upfront cost is roughly one to two days of setup time. The long-term savings are measured in avoided midnight incident calls.
Monitor models after deployment. A model's performance degrades over time as the underlying data distribution shifts. This is called concept drift and it is inevitable. Set up monitoring for prediction drift, input feature drift, and downstream metric degradation. Catching drift early lets you retrain before business impact becomes measurable. Ignoring it means you will discover the problem when someone complains that the model output looks wrong.

What this field looks like from the inside
Data science work is mostly communication and iteration, not coding. You spend a lot of time explaining to stakeholders why their intuition about the data might be wrong, or why the model can't answer the question they actually want answered. You also spend a lot of time redoing analysis because the initial question changed. This is normal. The first version of almost every project is wrong in some way. The skills that distinguish good practitioners from the rest tend to be understated. Writing clear documentation. Asking precise questions before starting analysis. Knowing when a simpler approach is sufficient. Understanding the business context well enough to spot when a technically correct answer is practically useless. A few years ago I spent two weeks building a sophisticated ensemble model for a forecasting problem. The business stakeholder asked me to present the results and then asked a single question that made the entire model irrelevant: "Can we just use last year's numbers and apply a growth rate?" The answer was yes, and it was more accurate than my model for their actual use case. I wasted two weeks. The lesson stuck. Before investing significant effort into any analysis, clarify what decision the output will actually drive. If the decision doesn't change based on your model's output, the model isn't worth building.
Where beginners get stuck and how to move past it
The most common bottleneck I see is the tutorial trap. People work through dozens of guided tutorials, each with clean data and explicit instructions, and then hit a wall when given a raw dataset and no direction. The gap between tutorial proficiency and independent capability is real. Bridging that gap requires deliberate practice with unstructured problems. Find messy datasets. Work with incomplete information. Make decisions without knowing the right answer in advance. This is how you develop the judgment that matters most in this field. Tutorials teach you mechanics. Real projects teach you judgment. Contributing to open source or internal tools accelerates learning. Reading other people's code exposes you to patterns and structures you wouldn't develop on your own. Fixing bugs, improving documentation, or adding small features to existing projects builds practical skills faster than another standalone tutorial.
Don't chase every new framework. The ecosystem generates new tools constantly. Most don't survive or become standards. Focus on fundamentals that transfer across tools: statistics, programming discipline, data wrangling, and communication. The specific library you use today will likely be different in three years. The underlying principles remain the same.
Data Science Guide 2026 for realistic career positioning
If you are looking to enter this field or advance within it, here is an honest assessment of what carries weight and what doesn't. Certificates from online platforms demonstrate initiative but carry limited weight with experienced hiring managers. They show you completed coursework. They don't show you can handle ambiguous problems or work in a team. Projects that matter are the ones where you solved a real problem with real data. A GitHub repository with a complete end-to-end project, clear README documentation, and evidence of iteration carries more signal than ten certificates. Employers want to see that you can take something from idea to delivery. Specialization pays off, but not early on. Generalist skills get you hired. Specialized skills get you promoted. Spend your first one to two years building broad competence across the full data pipeline. After that, go deep in one or two areas that interest you and align with market demand. Current areas with genuine demand include MLOps engineering, causal inference for business decision-making, and generative AI application development. None of these require advanced degrees. They require demonstrated ability to ship working solutions.
The landscape keeps changing. What worked in 2023 doesn't fully apply anymore. The core requirements haven't shifted as much as the peripheral tools and expectations. You still need solid programming, statistical literacy, and the ability to think critically about data. Everything else is implementation detail. If you have the fundamentals and a track record of finished projects, you can adapt to whatever comes next. That has been true for a while and it will remain true regardless of which guide you follow this year.

