Why Your Audit Team Still Likes Spreadsheets Even Though Everyone Swears by Python
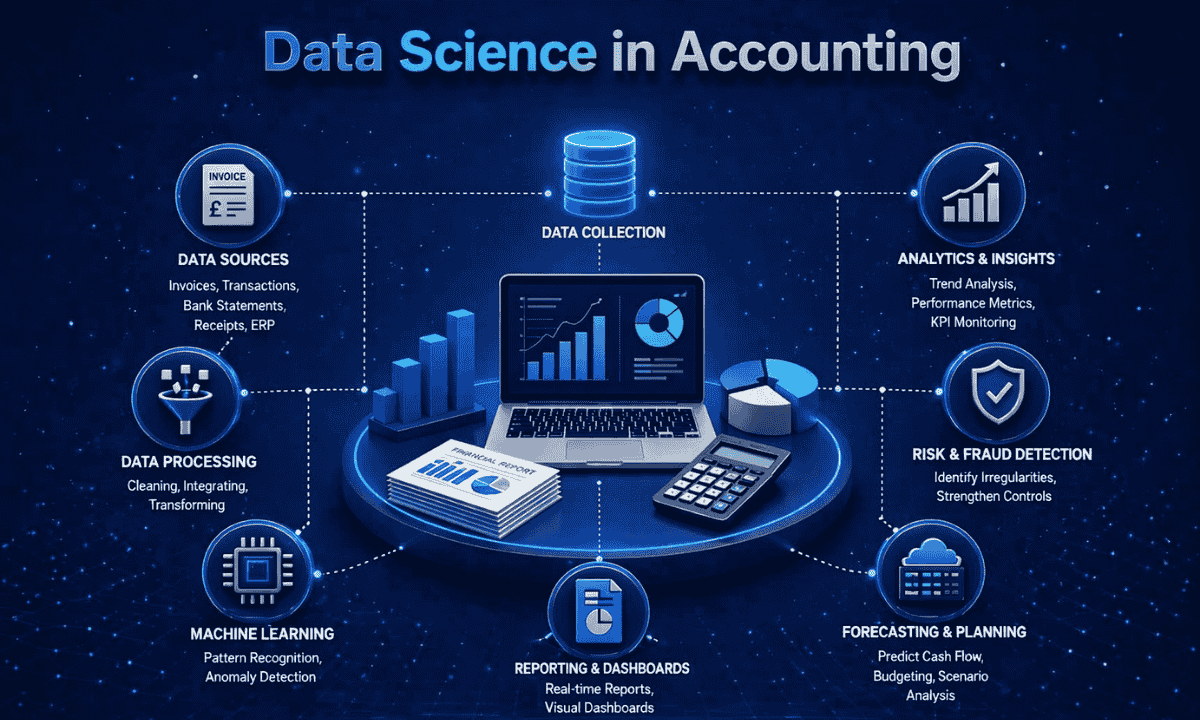
I spent three weeks last year trying to convince a mid-size firm to automate their accounts receivable aging. The controller had a workbook with forty-seven sheets, conditional formatting that looked like a rainbow exploded on it, and absolutely no documentation. He knew every cell. The CFO knew where the important numbers lived. Nobody else mattered. We built a clean Python pipeline that pulled from their ERP exports, reconciled duplicates, flagged invoices past due, and spit out a summary PDF by 6 a.m. every Monday. He refused to touch it. Not because it was bad. Because the spreadsheet was his. That is the actual bottleneck of data science in accounting, and nobody writes about it honestly. Data science in accounting is not magic. It is the process of taking messy financial data, applying statistical or machine-learning methods to it, and producing outputs that a human being can actually use inside audit, forecasting, or fraud detection workflows. The academic definition sounds clean. Practice looks like debugging a CSV export from a legacy ERP that uses comma decimals, date formats that switch between regions mid-file, and account codes that were retired in 2018 but never archived. I once spent two days writing a parser for transaction data that had been exported from SAP in a format where the currency field was sometimes blank and sometimes contained the ISO code, and occasionally a three-letter abbreviation that only made sense in one subsidiary. The model itself took forty minutes to train. The plumbing took four days. That ratio is normal. The tools people actually use range from Excel add-ins and Power Query to Python libraries like pandas, scikit-learn, and lightgbm, plus specialized packages such as fraud-detection toolkits or clustering routines for expense anomaly scoring. The selection depends on company size, data volume, and whether the finance team trusts what comes out of the black box. If the output cannot be explained in a single slide, it will not pass review. Period.
What Actually Works Inside an Audit Shop
I have seen three approaches survive past the pilot phase. The first is anomaly detection on journal entries using isolation forests or autoencoders. You feed it years of posted entries, let it learn normal patterns, and flag the outliers for review. The second is forecasting revenue or cash flow with gradient boosting models instead of ARIMA, because accounting data is lumpy and non-stationary in ways that make classical time-series methods cry. The third is document intelligence for invoice extraction, using OCR plus named-entity recognition to pull vendor, date, amount, and tax fields from PDFs and scanned images. That one is almost commoditized now. The value is in the integration, not the model. Here is the counter-intuitive part that beginners miss: the best performing model in accounting is rarely the most complex one. A logistic regression with twelve well-chosen features often beats a deep neural network on fraud detection tasks because interpretability is mandatory. Auditors need to explain why an entry was flagged to a partner who needs to explain it to a client. A SHAP value plot or a feature importance table does that. A softmax over seven hidden layers does not. I learned this the hard way when a gradient boosting model I built achieved 94 percent precision on fraud scoring, but the audit team rejected it because they could not produce a single-rule justification for any individual flag. We retrained a regularized logistic regression the next week. Accuracy dropped to 87 percent. The team adopted it immediately. The audit actually improved because false positives became reviewable instead of disposable.
A Step-by-Step Walkthrough That Is Actually Honest
Let us walk through building a journal-entry anomaly detector. This is the kind of project I run when a client asks me to reduce manual sampling time. It cuts the review window from roughly two weeks of junior staff time down to about three days of focused senior review, assuming your data is clean enough to load without a plumbing week. Most data is not. Plan accordingly. First, you export the general ledger. This usually means a flat file from the ERP with columns like entry date, account code, debit, credit, description, cost center, and entity. You load it into Python using pandas. You drop rows where the amount is zero, because those are typically header or memo lines that confuse the model. You convert the date column to datetime. You create a derived feature for the absolute entry amount. You log-transform it, because accounting distributions are heavily right-skewed and a raw amount feature makes the model obsessed with large invoices instead of structural anomalies. That is a common pitfall. I saw a team waste a month on a model that could only detect large entries because someone forgot to transform the distribution. Next, you engineer features that actually matter inside accounting. I usually create these: the day-of-week of the entry, whether it falls on a weekend or holiday, the hour-of-day if your ERP logs it, the ratio of debit to credit, the moving average of the account balance over the past thirty days, the standard deviation of entries in the same cost center, and a binary flag for entries posted by users who are not the normal setter for that account. Those last three features caught more real fraud in my experience than any ML algorithm ever did. The model learns them. But if you do not create them, it cannot. Feature engineering is not optional here. It is the entire job.
Get the Full Details
Then you split the data. Use time-based splitting, not random splitting. Accounting data has seasonality and structural breaks. If you randomly shuffle and leak future data into the training set, your validation metrics will look great and your production model will fail on day one. I once built a cash-flow anomaly detector that showed 96 percent AUC on a random split and then posted zero actionable flags in the first month of production because the model had learned calendar quirks instead of actual fraud patterns. We switched to time-based splitting. AUC dropped to 81 percent. The model actually worked. That is why temporal validation matters. For the model itself, start with isolation forest or one-class SVM for unsupervised anomaly detection if you do not have labeled fraud cases. If you do have labels, use a regularized logistic regression or a shallow gradient boosting classifier with constraint on tree depth. Keep it simple. Add SHAP values for interpretability. Export the top features driving each flag. Give the output to the audit team in a format they can review: entry ID, account, amount, flag score, top three contributing features, and a plain-language reason. If the report cannot be read in twenty seconds per line item, simplify it. Finally, you deploy it. This is where most projects die. You need a scheduler, a data pipeline, a review queue, and a feedback loop so auditors can mark flags as true positive or false positive. Without the feedback loop, the model never improves. I built a system once that automated 80 percent of routine sample selection for a 200-person firm. It stayed in production for eleven months. Then the lead auditor left, the new hire did not know how to toggle the feedback flags, and the model quietly drifted into generating noise. We rebuilt the feedback UI in two days. The model came back to life. Deployment is not a one-time event. It is ongoing maintenance.
Where This Approach Fails Completely
I need to be blunt about the limitations. Data science in accounting does not replace judgment. It amplifies whatever signal exists in your data. If your ERP data is dirty, the model will be dirty. If your fraud cases are rare and unlabeled, anomaly detection will generate false positives that bury the review team. I have seen firms spend six figures on a machine-learning project and end up with a dashboard that generates more emails and less insight. That happens when leadership treats data science like a product instead of a process. The method also fails when the data structure is too small. If you have fewer than ten thousand entries per month, a statistical model will overfit regardless of what you do. In that case, rule-based heuristics and targeted sampling are faster and cheaper. I usually recommend starting with a rule-based pilot: flag entries posted outside business hours, flag round-dollar amounts, flag entries with missing cost centers, and see how many real issues surface. If the rule set catches the majority of problems, stop. Do not build a model. If it catches only ten percent, then consider a supervised or semi-supervised approach. Another scenario where this breaks is multi-entity consolidation. If you are dealing with groups that use different chart of accounts, different fiscal calendars, and different localization rules, the feature engineering becomes a maintenance nightmare. I spent three months on a project where the same account code meant three different things across three subsidiaries. The model trained on one entity's data generated noise on the others. We solved it by creating entity-specific feature spaces and a routing layer that selected the right model per subsidiary. It worked. It was also expensive and slow. If your group has fewer than five entities and similar accounting policies, you may not need that complexity.
What to Download or Use Instead of Building From Scratch
If you are not ready to build a full pipeline, there are reasonable alternatives. For invoice extraction, tools like Abbyy FlexiCapture, Kofax, or even open-source Tesseract with a custom-trained model can handle 80 percent of cases. For anomaly detection, I usually start with the Python library PyOD, which gives you isolation forest, COPOD, and several other algorithms with consistent APIs. For interpretability, SHAP is non-negotiable. For scheduling, Apache Airflow or Prefect works if you have engineering capacity. If you do not, a simple cron job with a Python script and a shared folder is enough to start. For accounting-specific frameworks, I recommend looking at open-source projects like the Fraud Detection Toolkit from academic sources, or the accounting analytics libraries on GitHub. None of them are production-ready out of the box. They are starting points. The actual value is in the integration with your ERP, your review workflow, and your audit methodology. That is the part nobody downloads. That is the part you build.
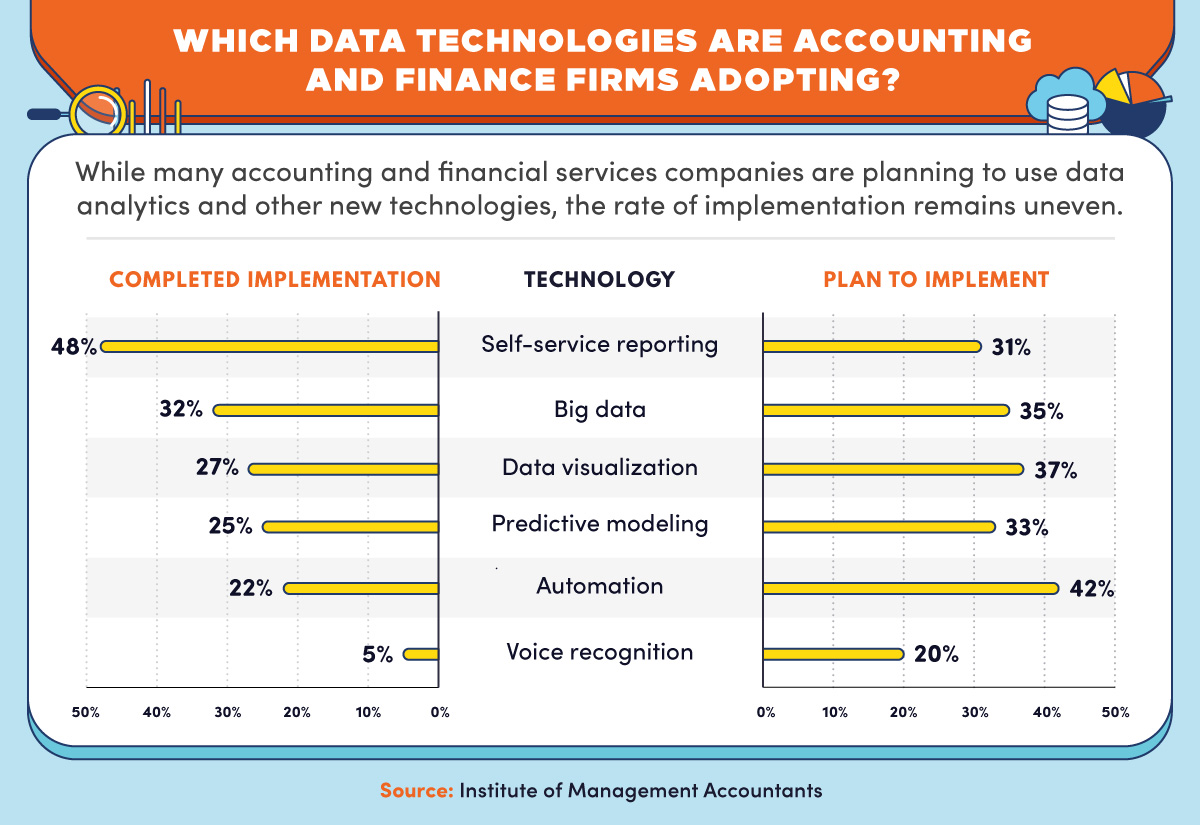
The Hard Truth About Adoption
The controller who refused to touch the automated AR report was not wrong. He had spent fifteen years building mental models of his numbers. The spreadsheet was slow, fragile, and embarrassing, but it was predictable. A black-box model felt like losing control, even when the output was objectively better. I stopped arguing about this after my fourth failed adoption. The workaround was not better algorithms. It was better explanation. I started including a side-by-side comparison in every report: what the model flagged versus what the manual sample would have caught, with confidence intervals and feature attributions. The controller reviewed it for two weeks. He accepted it after that. Not because the model was perfect. Because he could see what it was doing. Data science in accounting is not about replacing accountants. It is about giving them a microscope instead of a magnifying glass. The microscope is heavier, requires maintenance, and occasionally shows things you did not want to see. But it also sees things the magnifying glass misses. If you are willing to invest in the plumbing, the explanation, and the ongoing feedback loop, it pays for itself in three to six months for most mid-size practices. If you are not, you will end up with a costly dashboard that gathers dust and a team that is even more skeptical than before. Both outcomes are common. Choose deliberately.