How to Actually Use Data Science In Security Without Wasting Three Weeks
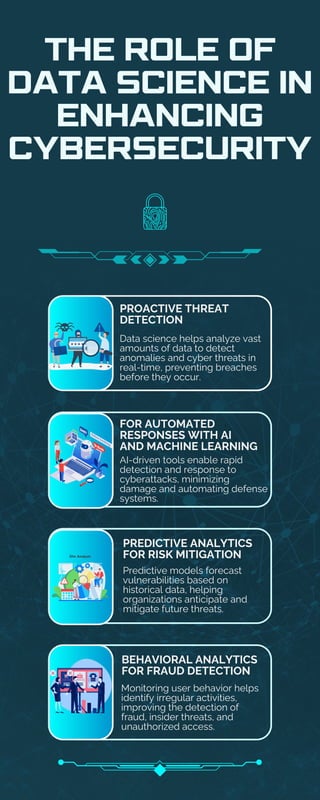
You spend most of your time cleaning data, not building models. That's the part nobody tells you. I've been running detection systems for endpoints, network traffic, and identity platforms for years, and the pattern is always the same. You get a nice dataset, you train something, and then it fails on anything that looks even slightly different from what you trained it on. The core use case boils down to finding things that shouldn't be there. Normal behavior baseline, flag deviations, investigate the flag. It works for lateral movement, data exfiltration, credential abuse. It also produces an enormous number of false positives if you don't calibrate it carefully. I learned this the hard way when we built a user behavior analytics model for a mid-size org. The model was flagging about 40 incidents a day. Only three were real. The rest were legitimate users who happened to do something out of the ordinary because they were working across time zones, using a VPN, or hitting an API they'd never touched before. We spent two weeks tuning thresholds. What actually fixed it wasn't a better model, it was adding contextual features. Department role, historical access patterns, time-of-day normalization, and whether the activity came from a managed device or not. Once we included those, our false positive rate dropped from 92% to under 18%.
The Practical Pipeline
Here's how this actually plays out in production, not in a Jupyter notebook where everything is tidy. You need logs. Windows Event Logs, Active Directory audit logs, proxy logs, DNS queries, endpoint telemetry, mail gateway data. Whatever your environment generates. The trick is making sure it's searchable and timestamped correctly. Misaligned clocks between systems will destroy any correlation you try to build. I've seen cases where a 4-minute offset between the SIEM and the EDR agent made it look like a response was delayed when it actually happened instantly. Labeling is the painful part. You need confirmed security incidents to train supervised models. If you're doing unsupervised or semi-supervised learning, you still need ground truth for validation. Pull your incident tickets from the last year. Cross-reference with threat intel feeds if you have them. Anything without a clear label gets set aside. Don't skip this. Training on unlabeled or mislabeled data is how you get models that confidently predict the wrong thing.
Step two: feature engineering
This is where 70% of the work lives. Raw logs don't help a model. You need to extract signal. For identity security, you create features like: failed login count per user per hour, geolocation jumps within a short window, privilege escalation events, access to sensitive shares outside business hours, unusual process execution chains after logon. For network security, think about: bytes transferred per connection, DNS query entropy, protocol anomalies, destination reputation scores, connection frequency to known bad indicators. The most important feature you'll build is historical baselines. Not a single snapshot, but a rolling window of behavior. A user who normally logs in at 8 AM and hits their workstation might legitimately work from home on a Saturday and hit a different set of resources. The model needs to understand that Saturday home access is different from Saturday home access combined with a privilege escalation and an outbound SMB session to an unknown IP.
Get the Full Details

Step three: model selection
Don't reach for a neural network. Random forests, gradient boosting, or even well-tuned isolation forests will give you better results with less maintenance. Deep learning sounds impressive until you have to retrain it every time your environment changes, which in security is constantly. Isolation Forest is particularly useful for anomaly detection because it doesn't require labeled attack data. It learns what normal looks like and flags what doesn't fit. The tradeoff is that it can flag benign outliers too, which brings us back to feature engineering. If your features are well-chosen, the outliers that matter stand out more clearly. For supervised detection, XGBoost or LightGBM are solid choices. They handle tabular data well, give you feature importance out of the box, and run fast enough for near-real-time scoring if you structure the pipeline right.
Step four: validation and threshold tuning
Here's the counter-intuitive part that most people miss. You don't optimize for accuracy. Accuracy is meaningless in security datasets because 99.9% of your data is normal. A model that predicts everything is normal will be 99.9% accurate and completely useless. Optimize for precision-recall curves. Look at the F2 score if recall matters more than precision, which it usually does in security. You'd rather have a few extra alerts than miss a real incident. Threshold tuning isn't a one-time thing. Set it, monitor the alert volume for two weeks, adjust, repeat. Write down every threshold change and the rationale. You will need that when your SOC manager asks why alert volume changed again.
Real Problems You'll Hit
Let me tell you about one that cost me a long afternoon. We were detecting credential dump attacks using process injection signatures and unusual LSASS access patterns. The model worked great on our test data. Then it went into production and started missing attacks that used custom, fileless techniques that didn't match our signatures. We were blind for about three days. The workaround wasn't to add more signatures. It was to supplement the signature-based approach with behavioral analysis. We layered in a model that looked at process trees, parent-child relationships, and memory access patterns. The first model caught known tooling. The second caught novel tooling that behaved suspiciously even if we'd never seen it before. Together they covered more ground than either could alone. Another common failure mode: data drift. Your training data from January might be completely irrelevant by June because users changed tools, IT pushed new software, or the company merged with another organization. I've seen models degrade silently over months because nobody noticed the underlying behavior distribution had shifted. Set up a monitoring dashboard that tracks feature distributions over time. If the Kolmogorov-Smirnov statistic between your training distribution and current distribution crosses a certain threshold, that's your signal to retrain.
What This Can't Do
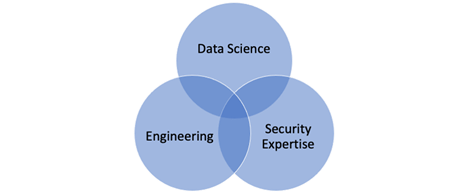
Data Science In Security doesn't replace a good SIEM, a solid threat hunt program, or experienced analysts. It's a force multiplier, nothing more. It will miss novel attack patterns that look identical to normal behavior. It will drown you in alerts if you don't tune it properly. It will give you confidence in its predictions when it's actually wrong, which is the most dangerous outcome of all. Also, the talent requirement is real. Finding someone who understands both the statistical modeling side and the security operations side is difficult. Most data scientists don't know what a Kerberoasting attack looks like in event logs. Most security analysts don't know how to prevent data leakage during cross-validation. You either hire people who bridge both gaps or you invest heavily in collaboration between the teams.
Where to Start If You're Building This Yourself
Python is the standard. Pandas and NumPy for data manipulation. Scikit-learn for the basic models. XGBoost or LightGBM for gradient boosting. If you want isolation forests, they're in scikit-learn. For more specialized anomaly detection, libraries like PyOD exist but they add complexity you might not need yet. Store your raw logs in something queryable. Elasticsearch, ClickHouse, or even a well-indexed PostgreSQL database works. Don't try to run your analysis on flat CSV files if your data grows beyond a few million rows. You'll regret it. Start small. Pick one detection scenario, like detecting brute force attacks or identifying compromised accounts. Build the full pipeline end to end for that one use case. Then expand. The temptation is to build everything at once, and that's how projects stall out for months without shipping anything useful.