
The Uncomfortable Truth About Hiring Interns in Data Science
Most people think data science intern interviews are about testing whether someone can code a random forest or derive backpropagation on a whiteboard. They are not. The actual problem is figuring out who will survive a first job without requiring hand-holding for every pandas operation. I spent three years hiring interns at a mid-size fintech company before we stopped the whole exercise and started using a different model. Here is what I learned, and what the questions on our pad actually looked like. The phrase "Data Science Intern Interview Questions" shows up everywhere, but almost nobody writes about what the questions reveal after the candidate answers. The ones that matter test for two things: statistical literacy and production intuition. Both are rare in undergraduates. When you find someone with even a grain of both, you hire them immediately, regardless of their GitHub portfolio. We stopped asking coding puzzles early. LeetCode-style problems do not predict internship performance. We switched to take-home projects using messy CSVs pulled from our own transaction logs. You hand the candidate 40 megabytes of data with missing values, timestamp bugs, and a clearly stated business goal. Then you watch what they do before they write a single line of model code.
Questions That Separated the Candidates Who Actually Stayed
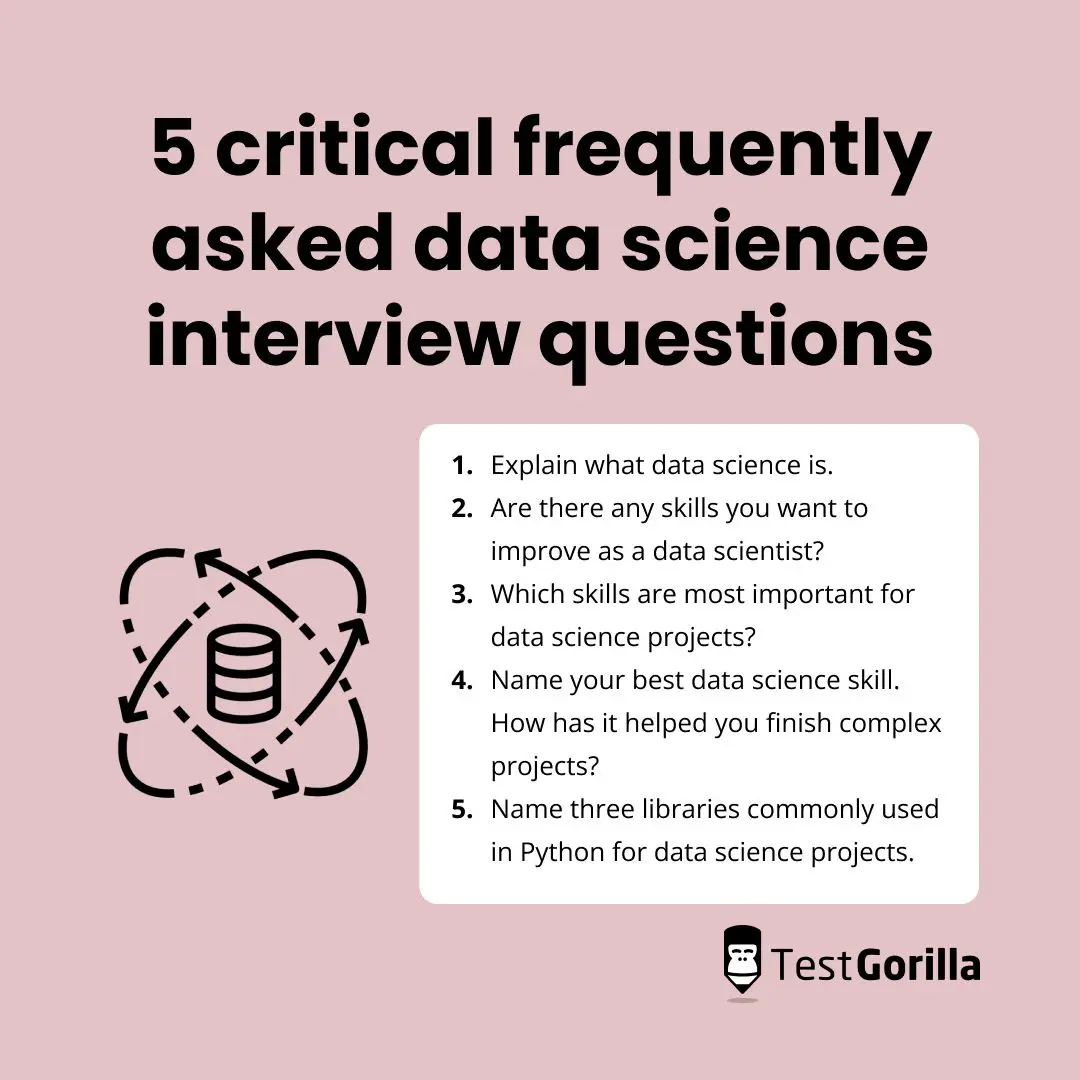
Here is the list that worked for us. They are not fancy. They are annoyingly specific. Q1: "Walk me through how you would handle a column with 73% missing values. When would you drop it? When would you keep it?" The expected answer involves the relationship between the missingness mechanism and the outcome variable. If the missingness is related to the target — which happens constantly in production data — dropping the column introduces bias. If the column is just noise with random gaps, imputation or removal makes sense. Most candidates pick an imputation strategy and stop talking. The good ones ask what the business question is. The right imputation strategy depends entirely on whether you are predicting churn or forecasting revenue.
Q2: "You trained a model that achieves 94% accuracy on train and 61% on test. What happened?" Data leakage. That is the short answer. But I want to hear them explain how leakage occurs in a time-series setting. Most interns know about train-test split. Almost none of them know about time-based split until we tell them. In our case, we were building a fraud detection model where fraudulent transactions clustered in certain weeks. Random shuffling leaked future patterns into the training set. The fix was straightforward: sort by timestamp, hold out the last 20% for testing, and never shuffle time-series data unless you deliberately want to simulate a different reality. Q3: "Explain p-value to someone who only knows basic arithmetic."
Get the Full Details
This question filters people who memorized definitions from YouTube without understanding the concept. A p-value is not the probability that your hypothesis is true. It is the probability of observing data at least as extreme as what you collected, assuming the null hypothesis is correct. The candidate who explained it using a coin-flip analogy — "If I flip a coin 100 times and get 75 heads, how likely is that if the coin is fair?" — demonstrated actual comprehension. That person got an offer.
A War Story From Our Third Cohort
We had a candidate who aced every technical question but could not deploy anything. Their models worked perfectly on clean Jupyter notebooks and completely failed in production. The problem was environment drift. They used Python 3.9 on their machine, we ran 3.11. Their scikit-learn version was six months newer. The pipeline broke on import errors, not logic errors. This is not a rare problem. It is the default state of intern work unless someone enforces strict environment pinning. The workaround we implemented after that was brutal but effective. Every intern had to containerize their project before the second week. Dockerfile, requirements.txt with pinned versions, and a Makefile that documented every build step. No exceptions. The ones who shipped containers understood software engineering better than the ones who just wrote scripts.
The Metrics Nobody Talks About
Interviewers fixate on metrics like F1-score and ROC-AUC. These matter after deployment, not during screening. The metrics that predict intern success are process metrics: documentation quality, version control hygiene, and how they handle feedback. A candidate who iterates slowly but documents every step is more valuable than a fast coder who leaves no trail. We hired two interns last year who wrote mediocre models but had immaculate README files. They became the most productive team members because every senior engineer could read their work in five minutes. The ones with elegant models and no comments caused three separate incidents where we lost hours chasing bugs that existed only in their local environment. Elegance without traceability is a liability in a team setting.

What to Ask About Real Projects
Every intern claims to have done a Kaggle competition. The claims rarely match reality. When I ask about their projects, I look for three things: data cleaning effort, error analysis, and ablation studies. Most candidates skip straight to modeling. The best ones describe spending 80 percent of their time on data wrangling and 20 percent on experimentation. That distribution is closer to the truth than anyone admits publicly. I once had a candidate who built a model achieving 97 percent accuracy on a customer segmentation task. When I asked what segments their model produced, they could not tell me. They had optimized for accuracy without understanding the downstream use case. The business asked for interpretable clusters, not a black box that maximized a metric. This mistake is extremely common. The fix is simple: always map your evaluation metric to a business outcome before training begins.
Common Pitfalls in the Screening Process
Interviewers often evaluate candidates against senior-level expectations. That is a mistake. Interns are not expected to architect scalable pipelines. They are expected to learn quickly and follow instructions without repeating the same error twice. When we held interns to senior standards, we filtered out the most coachable people and kept only the people who already knew everything. That group was dangerous because they resisted feedback. The second pitfall is over-weighting algorithm knowledge. Knowing the math behind XGBoost is useful. Knowing when not to use XGBoost is more useful. A candidate who explained that gradient boosting adds unnecessary complexity to a dataset with 500 rows and four features demonstrated better judgment than the one who implemented it anyway. Simplicity is a feature, not a bug.
How We Eventually Stopped Using Traditional Interviews
After three years, we realized the interview process itself was introducing bias. Candidates from well-funded universities performed better because they had access to compute resources and mentorship. Candidates from underfunded programs had equal talent but fewer opportunities to practice. We switched to a blind coding challenge where everyone received identical instructions and a standardized dataset. The performance gap narrowed significantly, though it did not disappear entirely. The remaining gap came from communication skills, not technical ability. Non-native English speakers struggled to explain their reasoning during whiteboard sessions, even when their code was correct. We adjusted by allowing written responses alongside verbal explanations. This change improved diversity without reducing quality.
The One Question We Still Ask
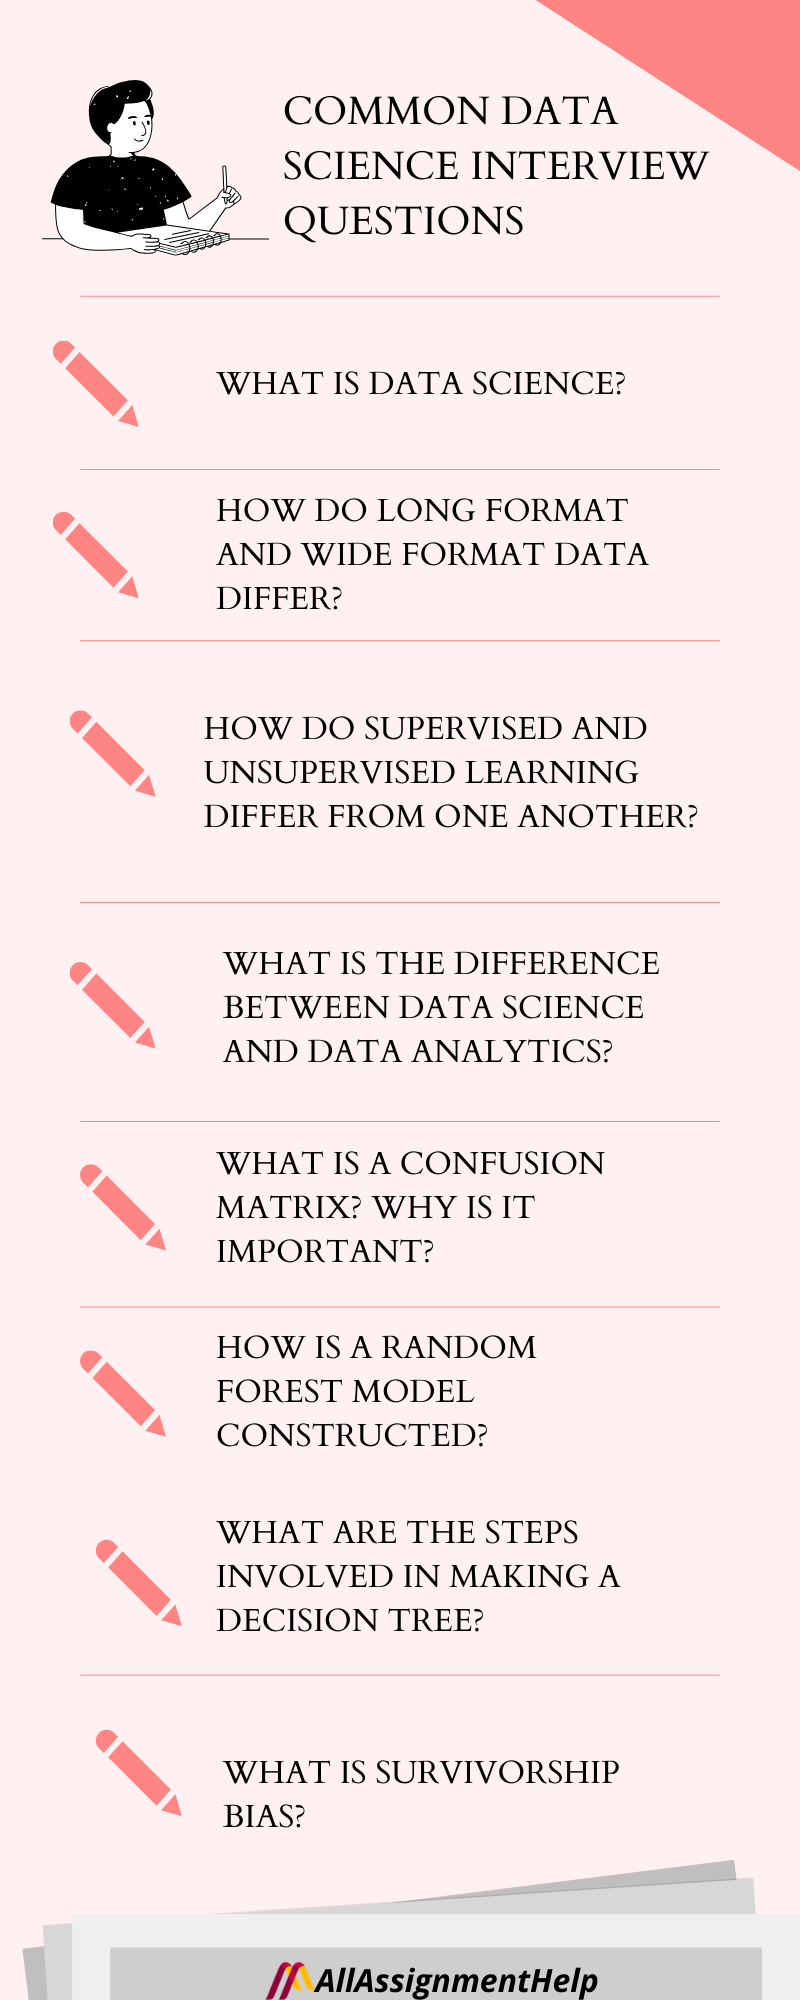
"Tell me about a time you made an error in your analysis. How did you catch it, and what did you do about it?" This question reveals integrity and debugging habits. Everyone makes mistakes. The question is whether they notice, admit, and fix them. Candidates who blame external factors or pretend their code was flawless usually hide bigger problems. The ones who describe a specific error with a specific fix tend to be the ones who grow the fastest during the internship. I have seen promising interns flame out because they could not admit when they were wrong. I have also seen average interns become indispensable because they owned their mistakes early. The pattern is consistent enough that I give this question disproportionate weight in my final decision.
Practical Advice for Candidates
If you are preparing for a data science intern interview, stop memorizing algorithms. Start building projects with messy data. Spend more time on data cleaning than modeling. Learn to explain your choices in plain language. Practice writing documentation that another engineer can follow six months later. These skills matter more than any metric you can achieve on a competition leaderboard. The interviewers we hired after leaving were surprised by how few candidates understood basic statistics. Things like confounding variables, selection bias, and the difference between correlation and causation. These concepts are covered in every introductory course, but the coverage is rarely deep. A candidate who can articulate why correlation does not imply causation using a real example from their project will stand out immediately.
Why Most Intern Programs Fail Without Structure
We watched several companies run intern programs that produced nothing of value. The pattern was always the same: no clear deliverables, no mentorship, and no evaluation framework. Interns spent their summer writing scripts that were never used, then left with a vague sense of accomplishment and a LinkedIn endorsement. The company gained nothing except a slightly larger Slack history. Structured programs assign mentors, define milestones, and require public presentations at the end. The presentation is not optional. It forces the intern to synthesize their work and communicate it to a mixed audience. The ones who cannot explain their project clearly usually had unclear thinking to begin with. The presentation surface area is small but revealing.

The Tools That Actually Matter
Pandas, SQL, and git. Those three tools cover 90 percent of intern work. Everything else — PyTorch, Spark, Airflow — is bonus material. Candidates who master the core trio before learning fancy libraries consistently outperform those who jump straight to deep learning. The latter group often builds models they cannot debug or deploy. The former group writes scripts that actually run in production. I recommend one more skill: basic visualization. Not seaborn aesthetics, but clear communication. A well-labeled plot with appropriate axis ranges conveys more information than a complex dashboard with thirty metrics. The interns who learned to choose the right chart for the right message became the ones everyone wanted to work with.
Final Thoughts on Screening
Data Science Intern Interview Questions are not about filtering out the unqualified. They are about identifying the teachable. Technical skills can be taught in three months. Judgment, curiosity, and honesty are harder to instill. When you find candidates who demonstrate all four, hire them immediately and give them real work. The internship will either make them indispensable or expose them quickly. Either outcome is better than pretending the process was fair. The companies that treat interns as temporary workers rather than potential full-time hires always lose in the long run. The best interns remember the experience and recommend the company to their peers. The worst interns recommend it too, but negatively. The difference comes down to whether you invest in their growth or just extract cheap labor. The economics favor investment, though the short-term temptation to exploit is real.

