The Reality of Getting Models Out of Notebooks and Into Production
Most people think model deployment is just saving a .pkl file and wrapping it in FastAPI. It is not. I have spent the last few years watching teams ship models that work perfectly in dev and break within 48 hours in production, and the reasons are almost always the same boring infrastructure issues rather than anything fancy. When I started doing this around 2018, I had no real deployment pipeline. I would train a model, pickle it, put it on a server, and pray. That approach worked for a proof of concept and then completely fell apart when we got our first real traffic spike. A single model serving request took 12 seconds because I had forgotten to enable batching, and the server memory climbed until everything crashed. I learned pretty quickly that deployment is not a final step. It is its own engineering discipline with its own failure modes.
What Data Science Model Deployment Actually Means
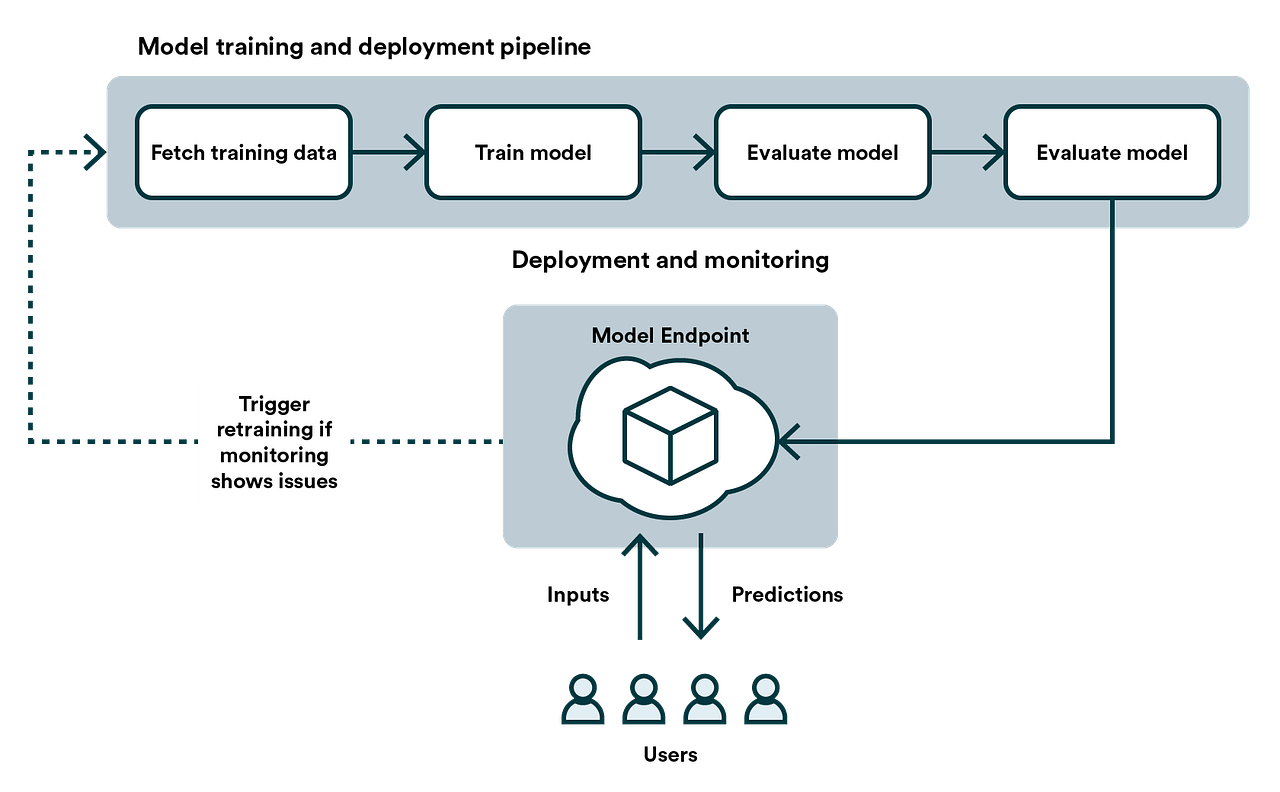
At its core, it is the process of taking a trained model artifact and making it accessible to consume data at scale with acceptable latency. That sounds simple because it is simple on paper. The hard part is everything between the model output layer and the person or system that needs the prediction. You need to handle input validation because garbage in will still produce garbage out, and it will do it quietly without raising any errors. You need to manage model versioning because you will inevitably need to roll back when a new version underperforms. You need monitoring because models degrade over time as the data distribution shifts away from what they were trained on. You need containerization or at least a consistent runtime environment because the Python version mismatch between your training machine and your server is the most common single point of failure I have seen, and it wastes an absurd amount of time debugging.
Step-by-Step: A Practical Deployment Pipeline
Here is how I actually structure deployments now. It took me about two years to get to this setup after trying several different approaches that each had their own problems. First, you serialize the model properly. I recommend ONNX or TorchScript over pickle for most production use cases. Pickle is convenient but it is a Python-specific format that introduces security risks when loading untrusted model files, and it couples you tightly to a specific Python version. ONNX gives you cross-framework compatibility and typically reduces inference overhead by about 20 to 30 percent compared to raw Python inference loops. Second, you build a thin inference service. FastAPI is the standard tool here and for good reason. It handles async requests well, does automatic request validation with Pydantic models, and generates OpenAPI documentation for free. I usually set up a simple endpoint structure with a /predict route and a /health route. The health check is critical because load balancers and orchestrators rely on it to determine whether your service is actually alive and accepting traffic.
Get the Full Details
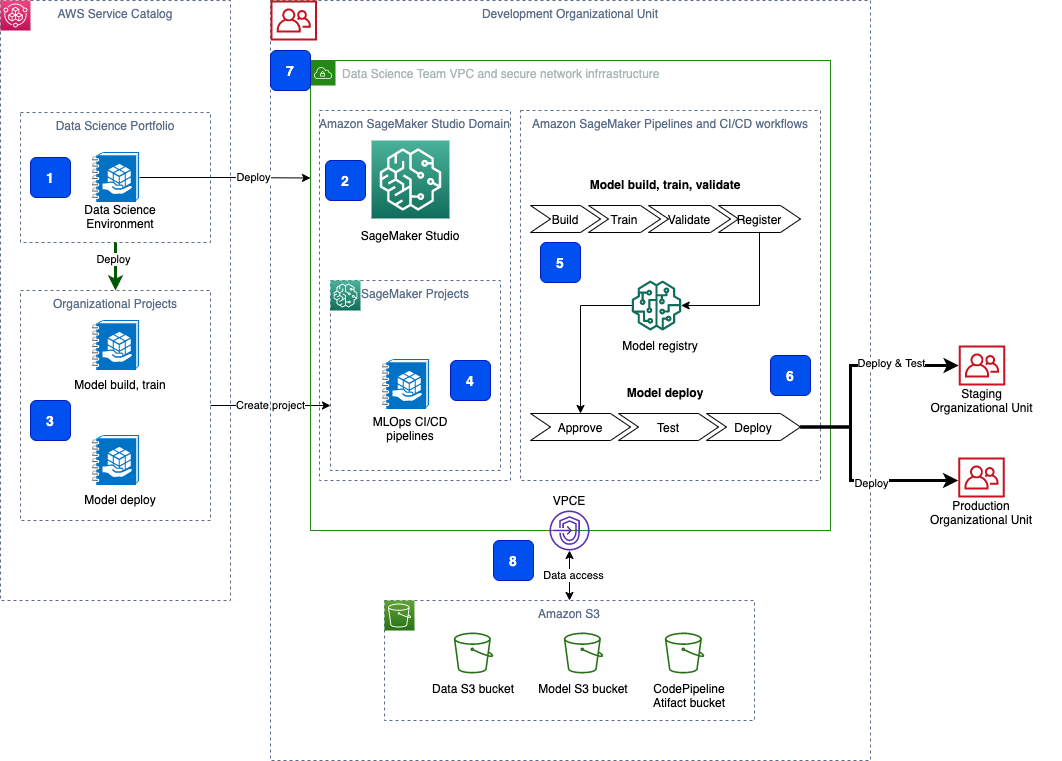
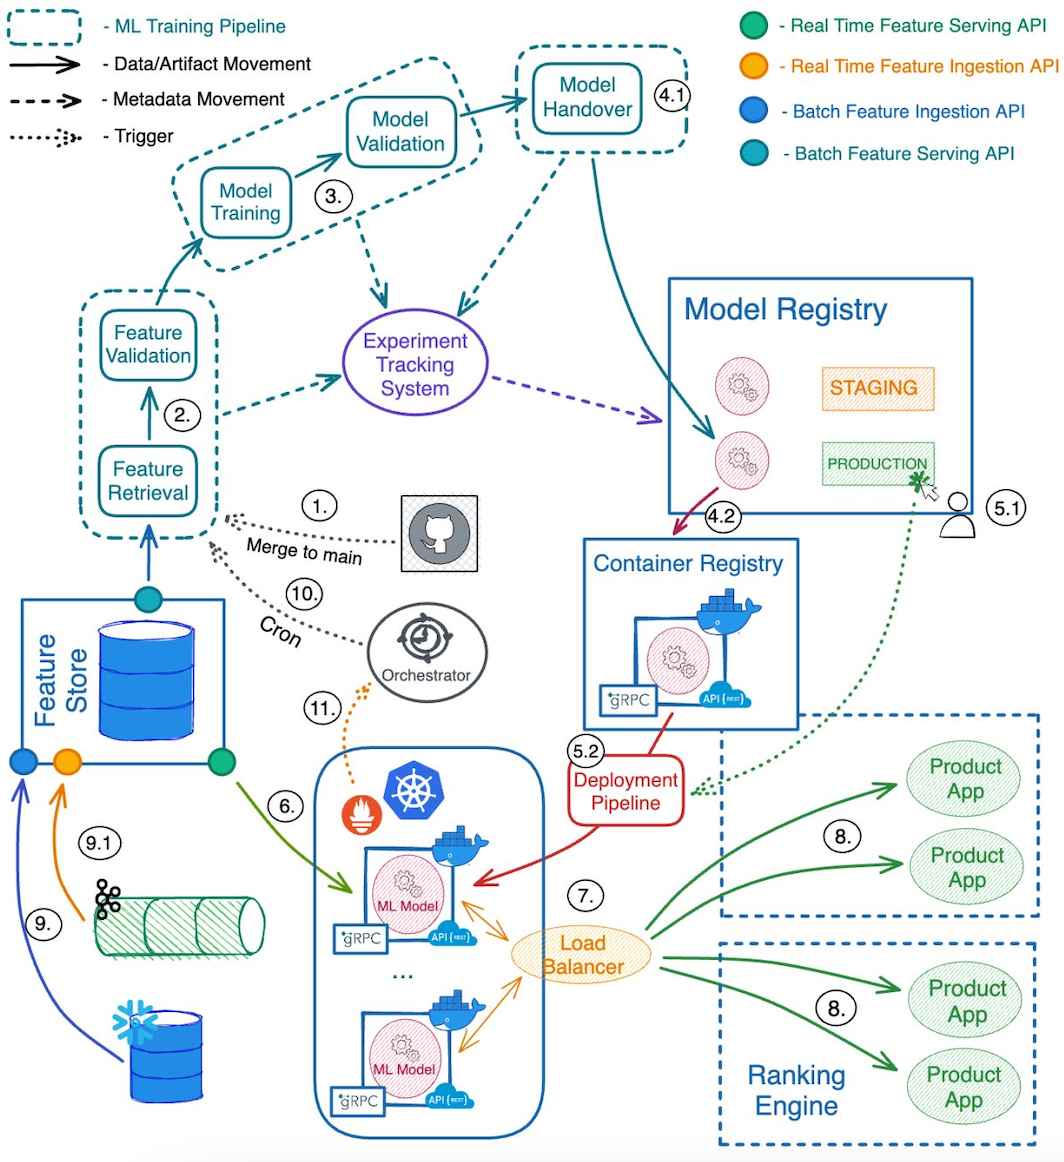
Third, you containerize it. Docker is the default at this point. The key thing that most beginners miss is the base image size. Using python:3.11-slim instead of the full python:3.11 image reduced our deployment artifact from 2.4 gigabytes to about 800 megabytes, which cuts down pull times and startup significantly during scaling events. If you are using GPU inference, switch to nvidia/cuda base images instead and be aware that image sizes jump back up to 4 or 5 gigabytes. Fourth, you set up orchestration. Kubernetes is the enterprise standard but it is also overkill for small teams. For anything under 10 concurrent models, a managed service like AWS SageMaker, GCP Vertex AI, or even a single well-configured EC2 instance with a reverse proxy works fine. When we were deploying a handful of models internally, we used ECS with Fargate and it handled our traffic without any manual intervention. The cost was roughly $120 per month for the compute versus maybe $400 if we had gone fully Kubernetes. Fifth, you add monitoring. Prometheus and Grafana give you visibility into request latency, error rates, and throughput. Model-specific monitoring should track input feature drift and prediction distribution changes. We use Evidently AI for this in production and it catches distribution shifts before they become business problems about 90 percent of the time. The remaining 10 percent is when you have a rare event model and the signal is too sparse for drift detection to trigger reliably.
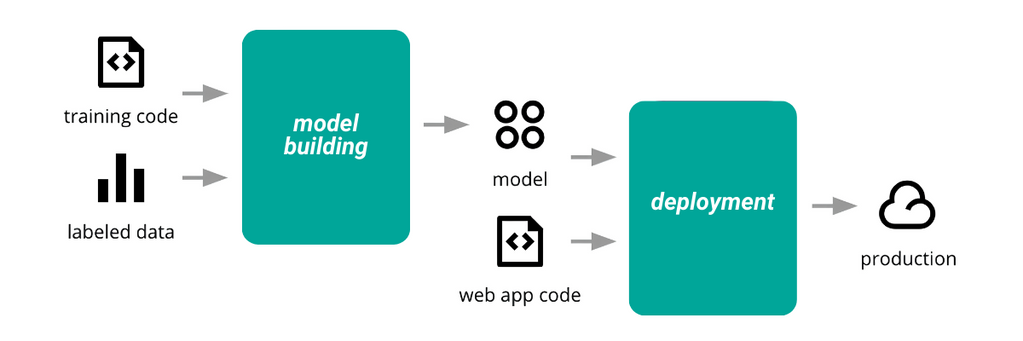
The actual sequence matters more than people realize. I used to train, containerize, and deploy all in one go because it felt efficient. It was not. Now I keep training and deployment as separate stages with a formal model registry in between. MLflow works well for this. It tracks experiments, stores model artifacts, and manages version transitions. The transition from staging to production should require an explicit approval step, even if it is just you approving your own work. Skipping that step is how bad models reach users.
A Specific Problem I Ran Into and How I Fixed It
About a year ago, we deployed a text classification model that processed user-generated content. The model performed well in testing with an F1 score around 0.91. Within three days of production, we started seeing latency spikes that went from an average of 45 milliseconds to over 2 seconds during peak hours. The GPU utilization was only at about 40 percent, so the hardware was not saturated. This was confusing because higher hardware usage usually explains latency. Aftering logs for several hours, I found the issue. The input data was coming through as raw JSON strings with inconsistent field ordering and occasional missing keys. The model preprocessing step was running synchronously inside the inference handler, which meant every request was blocked while the preprocessing completed. Under low traffic this was invisible. Under load it created a queue that grew without bound. The fix was to separate preprocessing into an async stage before the model call. I added a lightweight FastAPI middleware that parsed and validated the incoming payload, filled in missing fields with defaults, and normalized the text before passing it to the inference function. This reduced p99 latency from 2.1 seconds to about 180 milliseconds. The preprocessing code itself added roughly 8 milliseconds per request, but because it ran outside the model inference lock, it did not compound under load.

Another related issue I encountered was model warmup. When containers scaled from zero to multiple instances, the first batch of requests to each new instance was significantly slower because the model weights had to be loaded into GPU memory. I solved this with a startup probe that sent dummy requests until the model was ready, combined with a minimum replica count that kept at least two instances always running. This eliminated the cold-start problem entirely for our use case.
Counter-Intuitive Things Beginners Miss
The biggest thing people underestimate is the cost of data serialization. When you pass request and response objects as JSON, the encoding and decoding overhead becomes non-trivial at scale. Switching our internal service from JSON to MessagePack for high-throughput endpoints reduced serialization time by roughly 60 percent and cut our CPU usage on the inference servers by about 15 percent. This is not a model improvement. It is a plumbing improvement that most teams never think about. Another thing that surprises people is that larger models are not always better in production. A smaller model deployed with lower latency and higher throughput often produces better business outcomes than a larger model that is too slow to serve in real time. We replaced a 1.3 billion parameter model with a 250 million parameter distilled version on a recommendation task. The accuracy dropped by 1.2 percent in offline evaluation, but the p95 latency dropped from 340 milliseconds to 45 milliseconds, and user engagement actually increased because the feature could be used in a real-time context rather than being cached and served stale. Batching is another area where intuition fails. More batching sounds better because it increases GPU utilization. But too much batching increases latency for individual requests. We found that a batch size of 32 was the sweet spot for our text model on A10G GPUs. Going to 64 improved throughput by only 8 percent while increasing p99 latency by 40 percent. The optimal batch size depends entirely on your latency requirements and your hardware, so you should measure both metrics when tuning this parameter rather than assuming larger batches are always better.
Where This Approach Breaks Down
The pipeline I described works well for standard REST-based inference at moderate scale. It breaks down in a few specific scenarios. If you need sub-10 millisecond latency for every request, HTTP-based serving is too slow and you should look into gRPC with custom serving frameworks like Triton Inference Server configured for continuous batching. If you are deploying to edge devices or embedded systems, Docker is too heavy and you need to convert models to formats like TensorRT, CoreML, or TFLite depending on the target hardware. The conversion process itself introduces precision loss that you need to validate carefully. We once converted a BERT-based model to ONNX for an edge deployment and saw a 4 percent accuracy drop that we did not catch in testing because our test set was too small and not diverse enough to surface the regression. For very large-scale serving with millions of requests per second, managed services become expensive quickly. At that point the economics shift toward self-hosted infrastructure with auto-scaling and reserved instances, but that requires genuine platform engineering capability that most data science teams do not have. This is not a criticism of the teams. It is just a factual constraint that determines whether a managed or self-hosted approach makes sense for your situation.
The model registry approach with MLflow works for most teams up to maybe 50 active model versions. Beyond that you start hitting limitations with the UI and the metadata storage, and you might need to supplement it with a dedicated MLOps platform or build custom tooling. This is a scalability boundary that most people do not encounter until they are already past it. I have found that the most sustainable deployments are the ones where the data scientists and the infrastructure engineers share ownership from the beginning rather than handing off a model and walking away. The deployment process changes how you should design models in the first place, and that feedback loop is the part that actually matters in the long run.