Getting Started With Data Science On The Google Cloud Platform
Most people overcomplicate this. You don't need a PhD in cloud architecture to build a working ML pipeline on GCP. What you actually need is a clearer map of which tools talk to each other and which ones just sit there collecting quota errors while you debug permission issues at 11 PM. Let me walk through how I actually set up Data Science On The Google Cloud Platform for production work, the stuff that doesn't show up in the official documentation because it's not exactly glamorous.
Data Science On The Google Cloud Platform
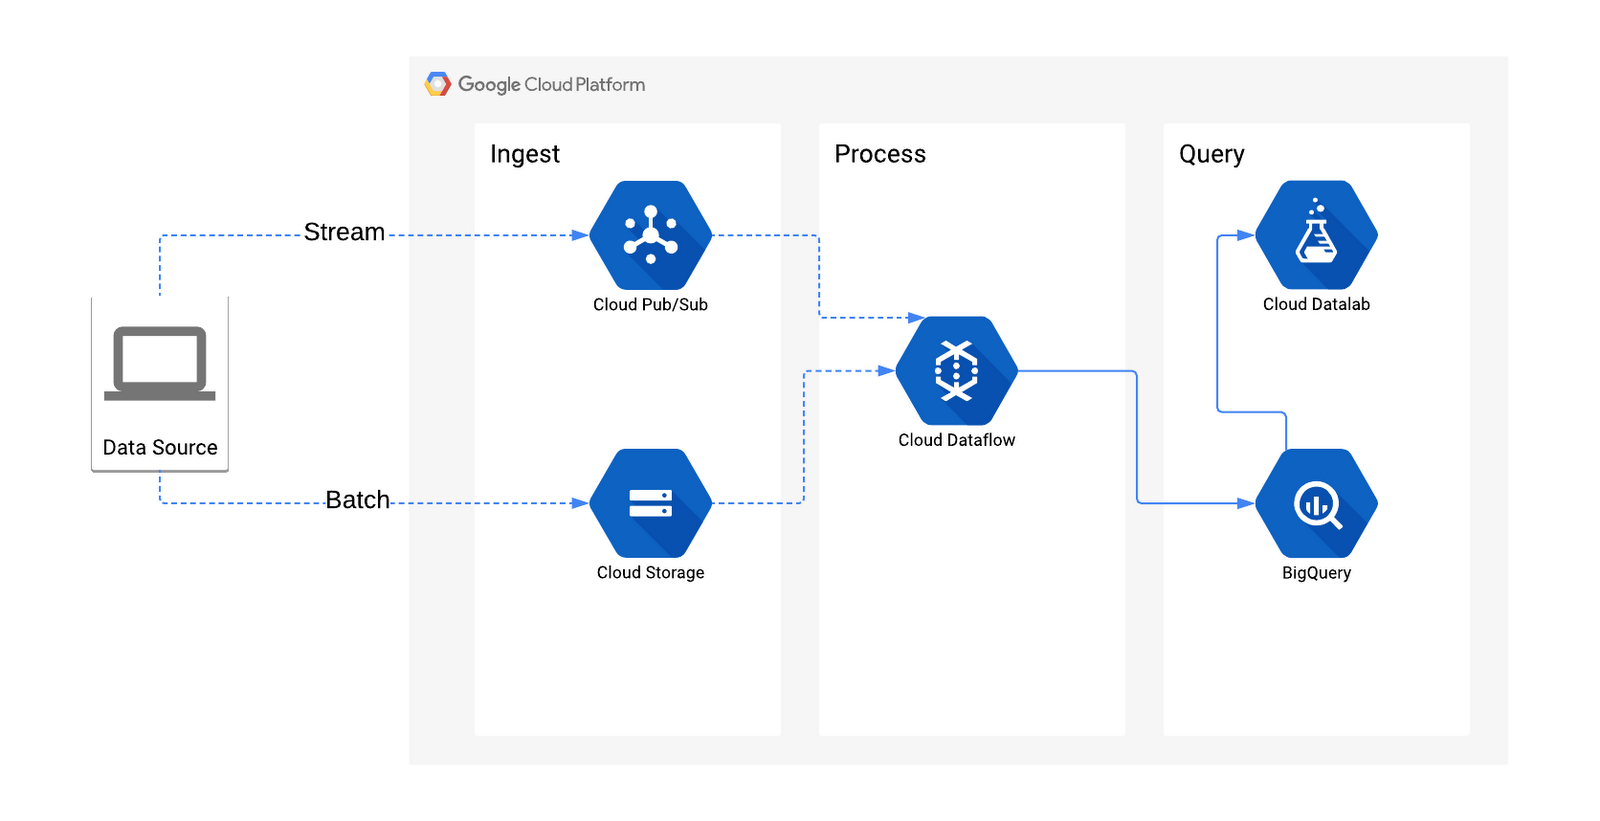
The core stack breaks into three pieces: storage (Cloud Storage buckets), compute (Vertex AI workspaces or Compute Engine instances), and the actual modeling layer (BigQuery ML, AutoML, or custom training jobs). That's the surface. The part nobody tells you is that your data shape determines your tool choice far more than you'd expect. If you're working with structured tabular data under a few hundred gigabytes, BigQuery ML will handle everything without spinning up a single GPU. It's surprisingly fast for what it is, and you're paying per query, not per hour of idle instance time. I ran a logistic regression on about 40GB of clickstream data last year and the BigQuery ML job finished in eight minutes. Running the same thing on a Vertex AI notebook with a GPU instance would have cost roughly $3 an hour and taken maybe twelve minutes once you factored in load time and environment setup. The difference isn't huge for a single job but it compounds fast when you're doing hyperparameter sweeps or cross-validation loops.
Setting Up Your Environment
Start by creating a single project in the Google Cloud Console. Don't spread your work across multiple projects unless you have a good reason, and you probably don't. Enable the Vertex AI API, Cloud Storage API, and BigQuery API. That's it. Three APIs. The docs list seven or eight additional ones and you'll spend an afternoon wondering why your Python scripts keep failing until you realize none of them actually matter for a basic workflow. Create a Cloud Storage bucket in the same region as your intended compute. This matters more than people admit because egress fees between regions are real, and moving terabytes of training data across zones will quietly eat your budget. Name the bucket something descriptive like project-name-data and set the location to us-central1 or europe-west4 depending on where your team is. Consistency here saves debugging time later. For notebooks, Vertex AI Workspaces is the default recommendation and it works fine for prototyping. Spin up a JupyterLab instance with a NVIDIA T4 if you need GPU access. The standard CPU option is perfectly adequate for data exploration and light model training. I usually keep a T4 instance running for when I hit the edge cases where pandas dataframes get too large for memory and I need CUDA-accelerated operations. The hourly rate is about eighty cents on demand, which is tolerable if you remember to shut it down.
Get the Full Details
The Pipeline That Actually Works
Here's the practical flow I use. Upload raw data to your Cloud Storage bucket using gsutil or the storage client library. Preprocess within a Vertex AI notebook or BigQuery depending on data size. Export the clean dataset back to Cloud Storage in Apache Parquet format, not CSV. Parquet compression typically reduces storage costs by sixty to eighty percent and cuts read times in half during training. Then schedule your training jobs using Vertex AI Pipelines or simple Cloud Scheduler triggers feeding into custom containers. The container approach is where most people fumble. Build a minimal Docker image with only the packages you actually use. A standard tensorflow or pytorch base image is around ten gigabytes. Strip it down to five. Every extra megabyte in your container multiplies pull time across every training job, every deployment, every autoscaling event. I use distroless images as a starting point and layer on only what's needed. My typical image runs about three gigabytes with Python, numpy, scikit-learn, and XGBoost installed.
A Real Problem I Ran Into
Last year I was training a gradient boosting model on roughly two hundred thousand rows with about four hundred features. Everything was going fine until the validation loss started spiking randomly every third epoch. No pattern in the data, no outlier I could identify. Turned out to be a floating point precision issue specific to how Vertex AI's built-in TensorFlow Runtime handles mixed precision on certain GPU configurations. The same code ran perfectly on CPU instances and on my local machine with identical random seeds. The workaround was ugly but effective. I disabled mixed precision explicitly by setting the Keras backend to float32 across the board, then disabled the cuDNN benchmark mode with a single environment variable before training. It added maybe four percent to training time but eliminated the instability completely. The official docs mention both flags individually. They don't mention you might need both simultaneously when your feature count exceeds a certain threshold and your batch size is below sixteen. I also hit a quieter issue where Vertex AI's managed notebook environment would silently drop numpy array dtypes during file saves. Int64 columns would become float64, which then caused type mismatches downstream in my preprocessing code. The fix was wrapping every numpy.save call with an explicit dtype specification. Six lines of code that prevented three days of debugging.
Common Pitfalls
The biggest mistake I see is treating GCP as if it were AWS or Azure with different names. The IAM system works differently, the CLI tools have different conventions, and the pricing model rewards steady usage while punishing bursty patterns in ways that catch people off guard. If you're coming from another cloud provider, budget two weeks of friction before you feel comfortable. The mental models are close enough that you'll function faster than that, but comfortable is a different metric. Another trap is over-relying on AutoML Tables. It's genuinely useful for quick baselines on structured data, but the black-box nature means you get almost no visibility into feature importance beyond the surface-level export. When your model starts degrading in production and you need to understand why, AutoML gives you nothing to work with. I use it for initial validation then immediately rebuild in either BigQuery ML or custom Vertex AI training where I have full control over the pipeline and can log everything.
Monitoring After Deployment
Vertex AI Model Monitoring is functional but sparse. It catches basic prediction drift and feature skew within twenty-four hour windows, which is better than nothing. The monitoring reports aren't particularly actionable though. They'll tell you that your input feature distributions have shifted statistically but won't tell you which feature or what business action to take. Pair it with a simple Cloud Logging dashboard tracking prediction count and latency percentiles. Those metrics catch degradation before the statistical drift alerts fire. Cost monitoring deserves more attention than it gets. Set up budget alerts at fifty percent and ninety percent of your monthly forecast. GCP doesn't stop spending when you hit your cap, it just sends emails. I've seen teams lose four thousand dollars in a single weekend from a misconfigured autoscaling policy on a training cluster. The autoscaling defaults on Vertex AI are conservative but not paranoid. Adjust the max worker count and idle timeout based on your actual workload patterns rather than trusting the recommendations.
When GCP Isn't the Right Call
BigQuery ML stops being competitive when your data doesn't fit in BigQuery's columnar storage model, which happens more often than the documentation suggests. Geospatial data, time series with irregular intervals, and text-heavy datasets all struggle in BigQuery. In those cases, Vertex AI with custom containers or even a straightforward Compute Engine setup becomes the better path. The managed infrastructure of Vertex AI doesn't scale gracefully past about fifty concurrent training jobs before you start hitting quota limits that require support tickets to resolve. If you're running an organization with heavy ML workloads, talk to a Google rep about increasing your quotas before you hit the wall. The process takes two to three weeks. For extremely small teams doing occasional analysis, the overhead of managing GCP resources might outweigh the benefits. A well-tuned local setup with DVC for version control and a single cloud instance for batch jobs can handle most one-person data science workflows without the operational burden. GCP shines when you need collaborative environments, automated retraining pipelines, or serving hundreds of predictions per second through a managed endpoint. Before committing to the full platform, be honest about which of those you actually need. The platform is solid once you stop fighting it and start working within its actual constraints. The learning curve is steeper than AWS SageMaker for pure beginners but the resulting infrastructure tends to be more maintainable long-term. Most of the frustration comes from trying to apply patterns from other clouds or local setups without adjusting for how GCP specifically structures identity, storage, and compute. Document your decisions, keep your containers lean, and monitor your costs weekly instead of monthly. Those three habits alone prevent most of the problems I've encountered over the last few years.