What Actually Works When You Are Stuck on a Problem
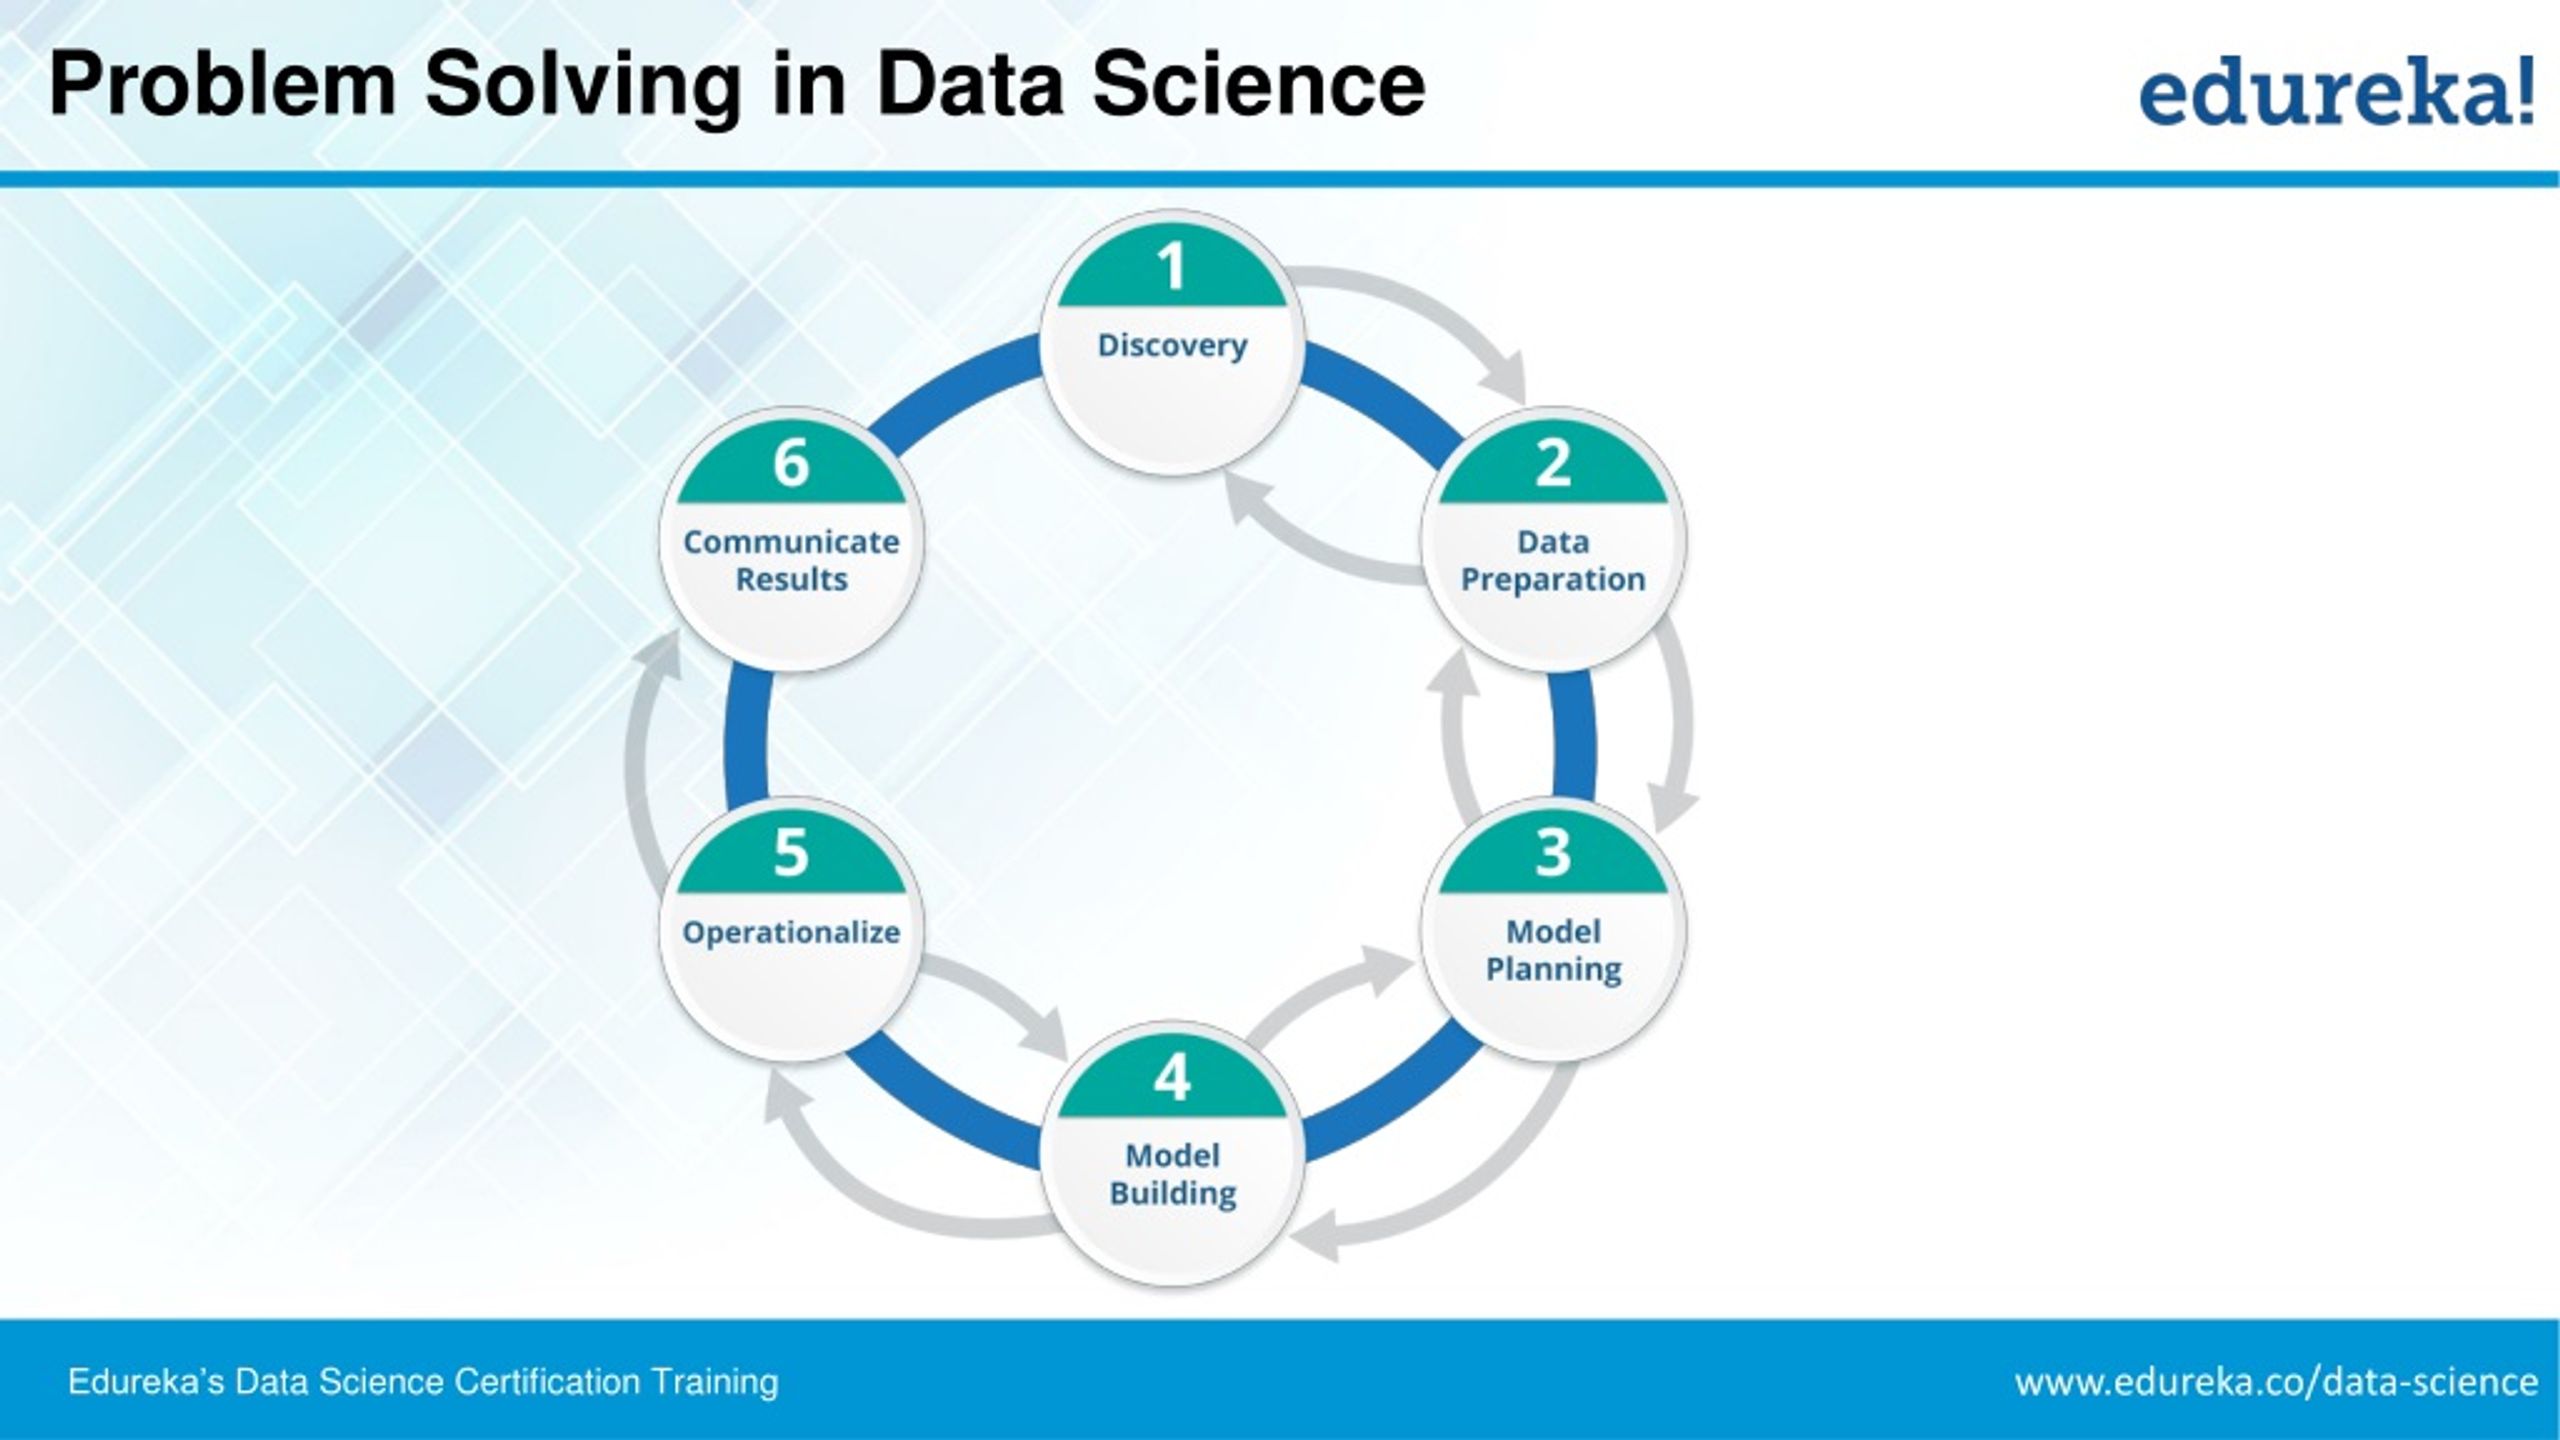
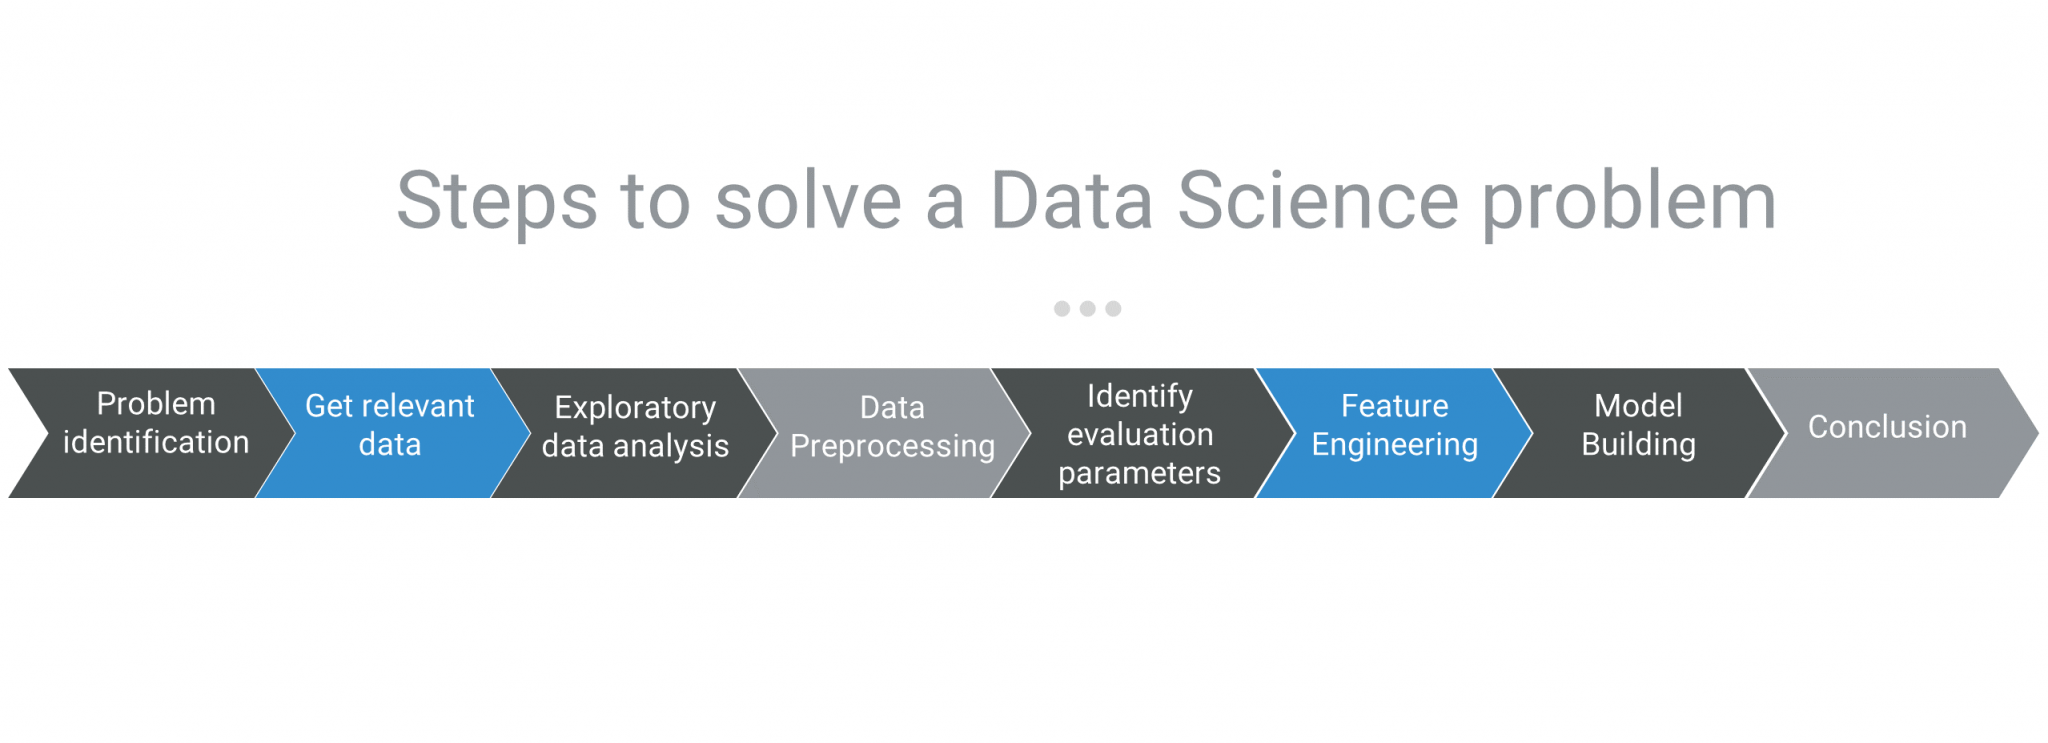
I spent about three years working in data science before I stopped treating every problem like a machine learning challenge. Most people I work with now, or used to work with, immediately reach for a neural network when the issue is something much simpler. The problem is not that advanced models are bad. They are just the wrong tool for most real-world situations you encounter on a Tuesday afternoon. Here is the practical framework I use when a new problem lands on my desk. The first step is always figuring out what the business actually needs, not what they asked for. People say they want a prediction model when what they need is a better filtering system. I had a client who wanted a churn model built with random forests. The actual problem was that their customer support team was not following up with at-risk accounts. The model would have been accurate but useless because nobody was going to act on the output anyway. We ended up building a simple alert system instead. It took two days instead of six weeks. Once you understand the real problem, the next step is data assessment. Look at what you actually have before you do anything else. Check for missing values, inconsistent formats, duplicate records, and basic quality issues. Most projects I see get delayed because someone assumed their data was clean. It almost never is. I recently worked with a dataset where the timestamps were stored in three different time zones without any consistent labeling. This meant sorting by date produced completely wrong results for about forty percent of the records. The fix was straightforward but it required manual mapping of each source to its correct zone, not just a quick pandas to_timestamp call.
Feature engineering is where most of the actual work happens. This is the part that rarely gets discussed in tutorials because it is tedious. You spend hours transforming variables, creating interactions, handling outliers, and deciding what to drop. A common mistake beginners make is keeping every feature available and hoping the model figures out what matters. Tree-based models handle this reasonably well, but linear models will punish you for it. Regularization helps but it is not a magic fix for garbage input data. When it comes to model selection, start simple. Fit a baseline logistic regression or a decision tree first. Then move to more complex options only if the baseline is insufficient. I have seen teams skip this step entirely and start with gradient boosting or neural networks, then spend weeks tuning hyperparameters on a problem that a simple model could have solved with higher interpretability. The extra accuracy you gain from complex models is often less than two percentage points, and you lose the ability to explain anything to stakeholders. Cross-validation is non-negotiable if you want results that generalize. Time series data requires time-based splitting, not random k-fold. I learned this the hard way when a model showed ninety-four percent accuracy in validation but performed at sixty-one percent in production. The data had a clear temporal pattern, and random splitting had allowed future information to leak into the training set. Switching to a proper time-based split immediately dropped the validation score to a realistic sixty-eight percent, which was still better than the production result but at least honest.
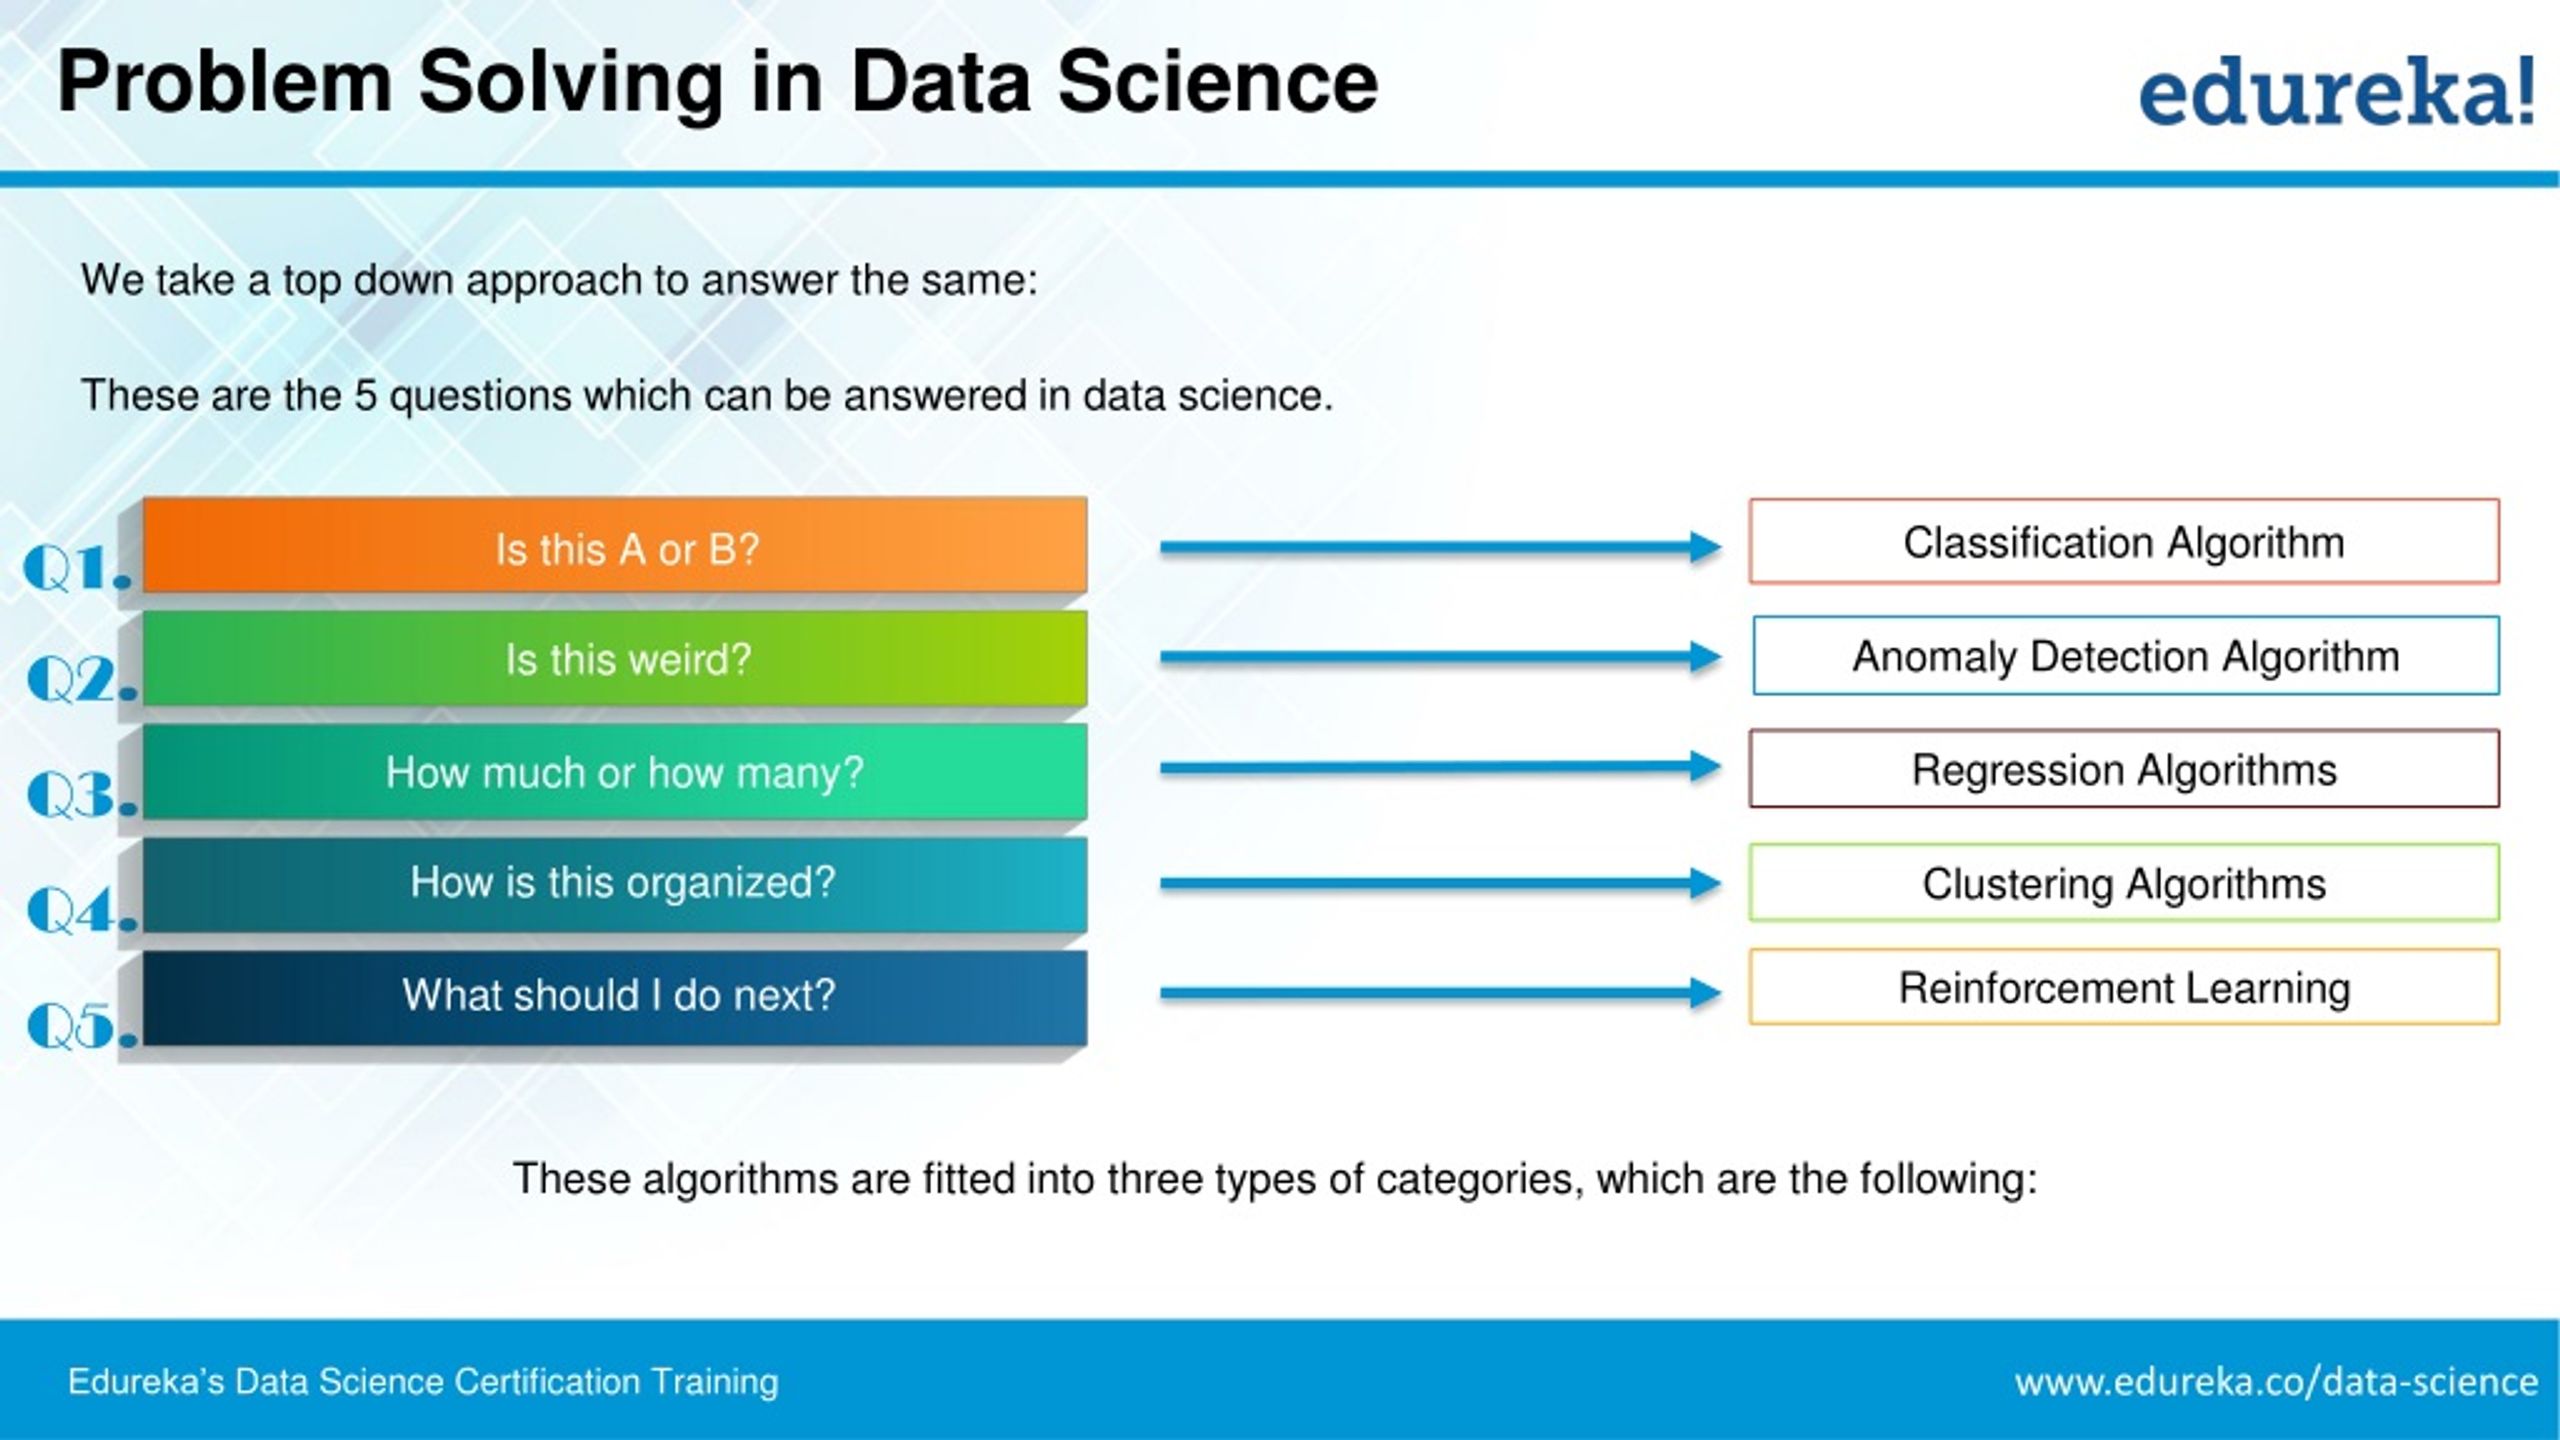
Evaluation metrics matter more than people admit. Accuracy is almost never the right metric unless your classes are perfectly balanced. Use precision, recall, F1, ROC-AUC, or business-specific metrics depending on what actually costs money when you get it wrong. A fraud detection model that catches all fraud but flags half of normal transactions is worse than a model that misses some fraud but rarely disrupts legitimate customers. The cost asymmetry determines everything. Deployment is where most projects die. A model sitting in a Jupyter notebook has zero value. You need to think about how the output will actually be consumed. Will it be an API endpoint? A scheduled report? A dashboard widget? I once built a model that predicted inventory needs with good accuracy, but nobody knew how to use the daily predictions because there was no integration with the procurement system. The model was technically correct and completely abandoned within a month. Building the pipeline and handoff process alongside the model, not after it, prevents this entirely. Monitoring and maintenance are also essential but frequently ignored. Data drift happens constantly. Your model will degrade whether you notice it or not. Set up basic performance tracking from day one. If you are not measuring prediction drift, distribution shifts, and business metric changes after deployment, you are flying blind. I typically set up simple logging that tracks input distributions weekly and compares them to the training baseline. When the divergence exceeds a threshold, you get an alert instead of discovering the problem after accuracy has already tanked.
Get the Full Details

The hardest part of data science is not the math. It is knowing when to stop, when a simple solution is good enough, and how to communicate clearly with people who do not think in statistics. The models are the easy part. Everything around them is where the real work lives.