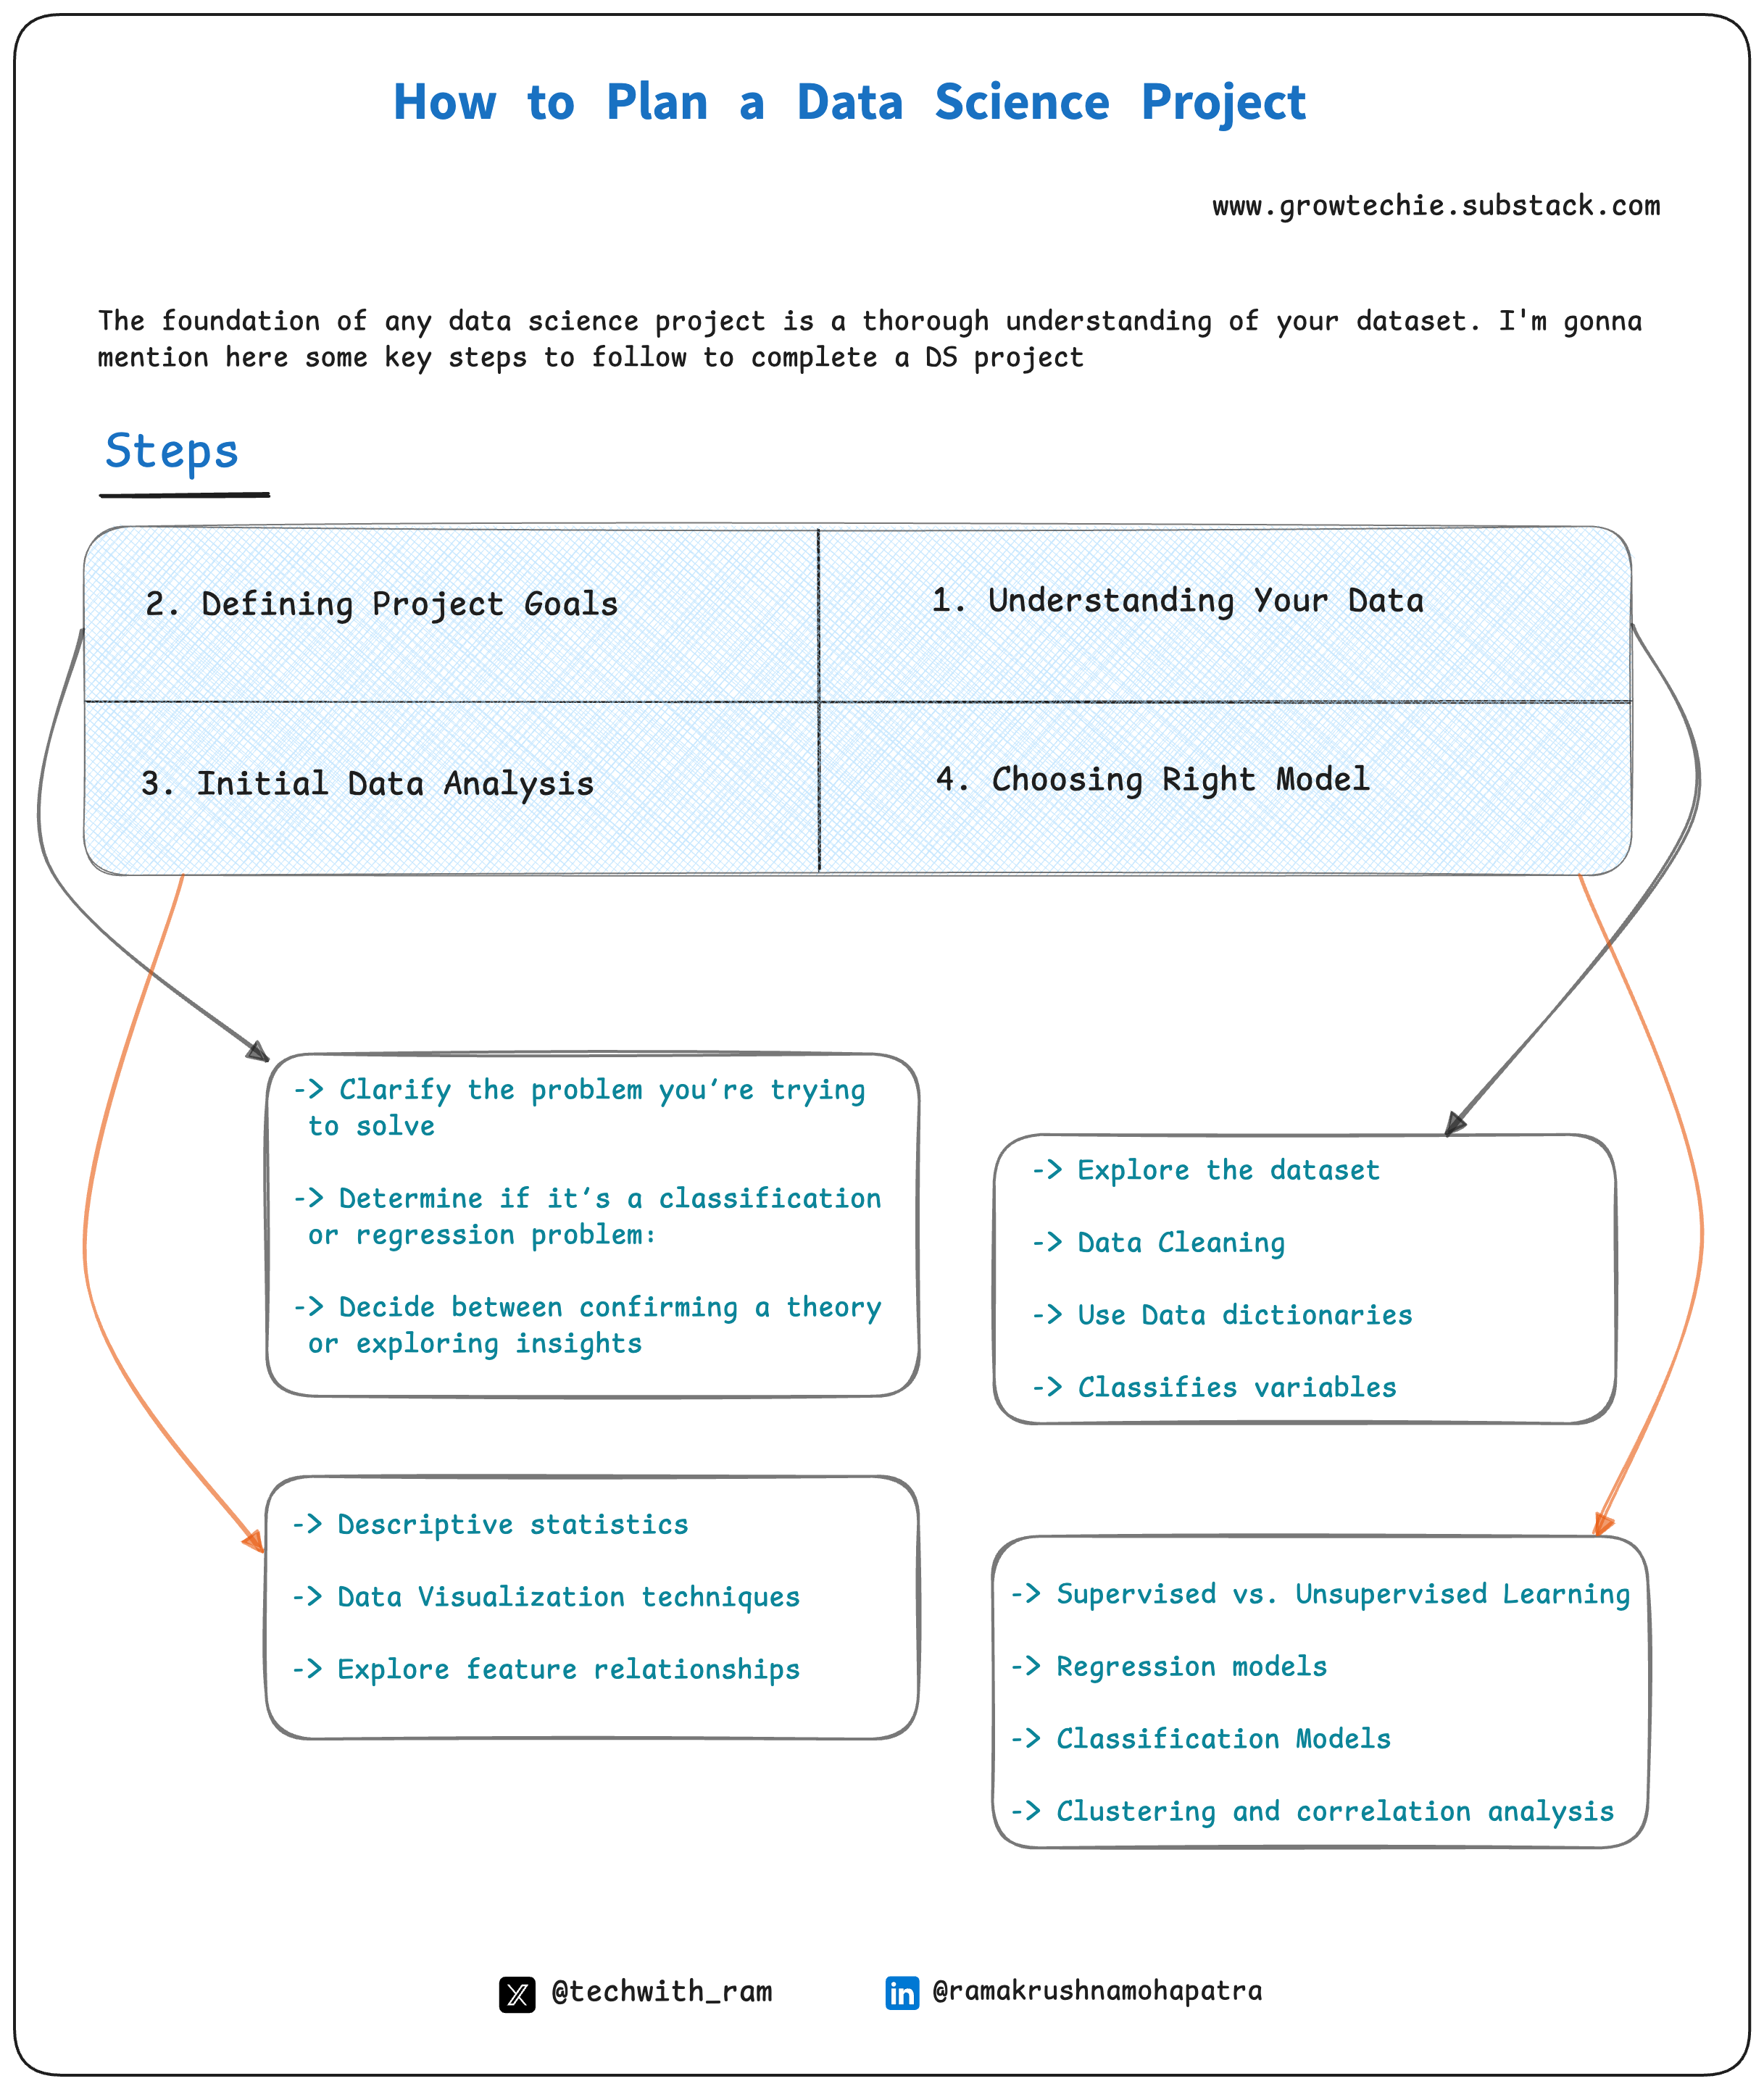
Why Most Data Science Project Plans Die Before They Start
I spent three years building project plans that looked perfect on paper and fell apart within the first two weeks of execution. The problem wasn't the planning itself. It was that most people treat a Data Science Project Plan like a contract you sign once and then follow religiously. That's not how any of this works. Here's what I actually do now, and why it takes me about half the time compared to the old way while producing something people actually use.
Data Science Project Plan
The first thing you need to understand is that a project plan in data science isn't a schedule. It's a living document that maps your unknowns. Every phase has assumptions attached to it, and those assumptions are where things break. My plan always starts by listing what I don't know yet, not what I do. A standard template usually asks for phases like data collection, exploration, modeling, deployment. Those are real steps. But here's the thing nobody puts in the template: data access delays. I had a project where the entire timeline shifted by six weeks because the compliance team needed to approve our data handling procedures. The model was ready in two weeks. We sat on it for four because we couldn't move past the permission review stage. My plan now has a dedicated dependency section that lists every external gate before you touch a single dataset. Another counter-intuitive insight: scope reduction is usually faster than scope expansion mid-project. When stakeholders keep adding features to a model, the plan becomes useless within days. I learned this the hard way on a churn prediction project where we started with three features and ended up with seventeen. The model performance didn't improve meaningfully, but the deployment timeline tripled. After that, I build a strict feature freeze point into the plan, usually right after the EDA phase, and anything past that needs explicit approval from both the business owner and the technical lead.
Here's how I structure the actual document now. It's not complicated, and it's shorter than what most people turn in. Section one is the problem statement, written in one paragraph. Not two. One. If you can't describe what you're solving in a single paragraph, you don't understand the problem well enough to plan for it. I've seen plans built around problems that turned out to be symptoms of a different issue entirely. That costs months of work. Section two is the success criteria. This is where most plans fail. "Improved prediction accuracy" is not a success criterion. You need a specific metric, a baseline, and a threshold. "Reduce false positive rate from 12 percent to under 8 percent while maintaining recall above 70 percent on the validation set." That's measurable. That's what you plan around. Without it, you'll never know when the project is actually done.
Get the Full Details
Section three is the data inventory. List every source, its format, its refresh cadence, and its ownership. I once worked on a project where we assumed the transactional database was updated in real time. It wasn't. It was a daily batch job that ran at 3 AM and had a four-hour window where the data was incomplete. We built the entire pipeline around real-time assumptions and spent two weeks debugging what turned out to be a scheduling issue. Every data source in my plan now has a verified freshness attribute before we commit to using it. Section four is the methodology. Don't write a novel. Link to your approach document if it's detailed, but in the plan itself, state the algorithm family, the why behind it, and the fallback. Machine learning projects rarely go exactly as planned. Your primary approach might underperform because of class imbalance, distribution shift, or some other issue that only appears during training. Having a pre-identified fallback method saves you from the panic that comes with a second attempt. Section five is the timeline, but not the way you might think. I don't Gantt-chart every single task. I mark the critical path items and estimate ranges, not fixed dates. Data science work has high variance. An EDA phase that should take three days might take three because you discover a major data quality issue. Or it might take six hours because the data is cleaner than expected. Fixed dates create false certainty. Ranges around critical items give you actual visibility.
The critical path in almost every data science project includes the same three bottlenecks: data access approval, stakeholder review cycles, and model validation against business logic. Plan for these explicitly. Don't bury them inside other tasks. Section six is the communication plan. This is the part everyone skips. Who needs to see what, and when? Technical leads need architecture decisions documented weekly. Business stakeholders need progress summaries every two weeks, not daily updates about model convergence rates. I usually include a simple matrix showing roles, information type, and frequency. It takes ten minutes to write and prevents about twenty hours of miscommunication over a typical project. One more thing that matters but rarely gets mentioned: the rollback plan. If the model performs well in testing but fails in production, what happens? I've seen teams ship a bad model and spend two weeks scrambling to revert while stakeholders are asking why the predictions changed. Your plan should include a rollback strategy, even if it's as simple as keeping the previous version deployed alongside the new one until you're confident. Canary deployments, A/B comparisons, shadow mode testing — pick one and document it.
There are honest limitations to this approach. A lightweight plan doesn't work well for highly regulated industries where auditors require extensive documentation. In those cases, you'll need more formal scaffolding. But even then, keeping the core plan lean and attaching the regulatory detail as separate appendices tends to work better than trying to merge everything into one massive document. Nobody reads a hundred-page plan. They read the executive summary and hope for the best. If you need a starting template, I keep a version in a shared drive that covers the sections I described. It's designed to be filled out in a single working session, not a week of meetings. The key is treating it as a planning tool, not a deliverable. The best project plans I've seen were the ones that got updated weekly and were referenced during actual standups, not the ones that sat in a shared folder and were never opened again.