Getting Data Science Right Without Losing Your Mind
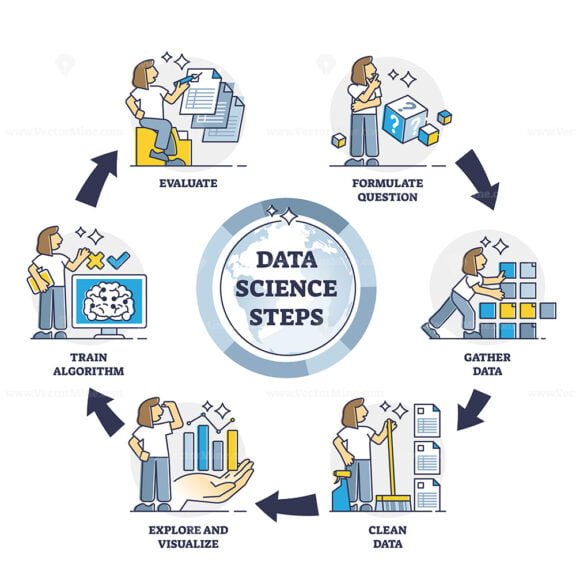
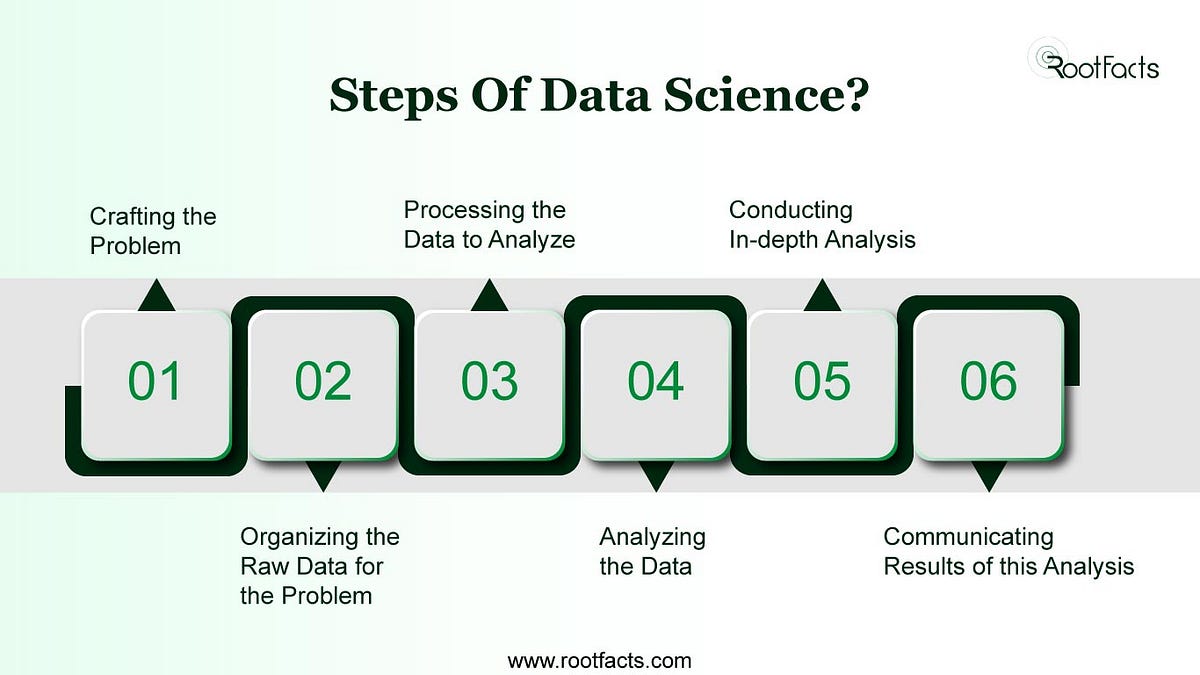
Most people jump into data science tutorials and hit the same wall within three weeks. They download a dataset from Kaggle, run a random forest model, and call it a project. That is not data science. It is a template exercise that looks impressive on paper and fails immediately when you try to apply it to real business data. The gap between what you learn online and what actually works in production is massive, and it comes down to process discipline, not fancy algorithms. Here is what the workflow actually looks like when someone is trying to solve a real problem, not complete a bootcamp assignment. It starts with understanding the question before touching a single line of code. I spent six months working on a churn prediction model for a telecom company. The client wanted 90% accuracy. The actual business problem was identifying which customers to call with a retention offer before they left. Those are two completely different objectives, and treating them the same cost the project an extra fourteen weeks of wasted iteration. Once you have the actual question pinned down, you move to data acquisition and inventory. This is where most projects stall. You need to know what data exists, where it lives, how fresh it is, and whether it is even relevant. I once inherited a project where the engineering team had built a pipeline to collect clickstream data, but the schema had changed three times in four months and nobody had updated the documentation. The feature set in the training data did not match what the model was receiving in production. We caught it two weeks after launch when the model started predicting uniformly. I ended up writing a validation script that compared schema versions every night and flagged drift before it became a production incident.
The Exploration Phase Most People Rush Through
Exploratory data analysis is not a checkbox. It is where you learn what your data is actually telling you, and skipping it is the fastest way to build a model that looks good on a test set and breaks in the field. I use basic statistics first. Means, medians, standard deviations, correlation matrices, missing value counts. Then I visualize distributions and look for outliers. A boxplot can tell you in thirty seconds what a thousand rows of a dataframe will obscure. I remember working with a healthcare dataset where the target variable had a tiny fraction of extreme values. The standard deviation was massive because of a few hundred patients with unusual readings. If I had normalized that data without investigating, the model would have learned the wrong relationships. I logged those outliers, reviewed them with the domain team, and discovered they were legitimate cases. We kept them but created a separate flag feature so the model knew they were edge cases rather than noise. Feature engineering is where the actual work happens. Raw data rarely comes in a form that models can use effectively. You need to create features that capture the signal you are looking for. Time-based features are almost always worth the effort. Hour of day, day of week, month, whether it is a holiday. For a retail demand forecasting project I worked on, adding a rolling 7-day and 30-day average as features improved the model's performance more than any algorithm tuning ever did. Feature selection matters too. Too many irrelevant features introduce noise and increase the chance of overfitting. Recursive feature elimination and permutation importance are practical tools for this, not the most glamorous parts of the workflow but the ones that make the biggest difference.
Model Building Without the Hype
You do not need a deep neural network to solve most business problems. Gradient boosting models like XGBoost, LightGBM, or CatBoost consistently outperform simpler approaches on tabular data and they train in a reasonable timeframe. I trained a CatBoost model on a dataset with over 200 features and mixed data types. It converged in about twenty minutes on a single CPU, and the cross-validated score beat a randomly tuned neural network by three percentage points. The neural network also took four hours and required GPU infrastructure that the team did not have access to. Cross-validation is non-negotiable. Training and testing on the same data is not a mistake you make once. It is a mistake you make regularly until something expensive forces you to stop. Time-series data requires time-based splitting, not random k-fold splits. If your data has a temporal component, shuffling it randomly leaks future information into your training set and gives you inflated performance numbers that mean nothing in production. I learned this the hard way on a fraud detection project. We got 97% accuracy on our validation set and felt proud about it. When we deployed it, the precision on new transactions dropped to 41%. The model had learned patterns from future data points that would never be available at prediction time. Switching to a time-based split and recalibrating the evaluation metrics fixed the problem in a day.
Get the Full Details
Validation, Deployment, and the Part Nobody Talks About
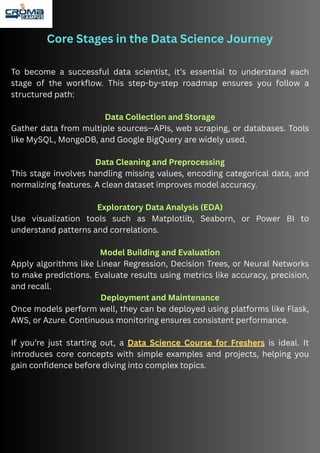
Model evaluation goes beyond accuracy. Precision, recall, F1 score, ROC AUC, and lift charts each tell you something different about how your model performs. A fraud detection model with 99% accuracy might still miss the majority of actual fraud cases if fraud represents only one percent of transactions. You need to pick the right metric for the right business outcome and optimize for that metric during training. Deployment is where theory meets reality. A model living in a Jupyter notebook is not a deployed model. It needs to be packaged, versioned, and integrated into a pipeline that can handle incoming data, generate predictions, and log results. I worked with a team that spent three weeks building an excellent churn model and then two weeks figuring out how to serve predictions through an API endpoint. The model itself was the easy part. Getting it into production reliably took longer because of dependency management, containerization issues, and inadequate monitoring setup. We ended up using Docker for packaging, FastAPI for the service layer, and Prometheus for tracking prediction latency and error rates. This setup cost about forty hours of initial work but saved us from repeated debugging sessions whenever we needed to retrain and redeploy.
Common Pitfalls in Data Science Step By Step Best Approaches
Overfitting is the most common technical failure mode. It happens when a model learns the training data too well and fails to generalize to new data. Regularization, dropout, early stopping, and simpler models are the standard countermeasures. But the more insidious version of overfitting is target leakage, where your features inadvertently contain information about the target variable that would not be available at prediction time. I caught this once in a loan default prediction project. One of the engineered features was the number of payment reminders sent in the past thirty days. The model latched onto it because reminders correlated strongly with defaults. But in production, you cannot know how many reminders a customer will receive before you decide whether to approve their loan. The feature was circular logic disguised as useful signal. Removing it dropped our training accuracy by four points but increased real-world performance by eight. Data quality issues are another persistent problem that receives insufficient attention in tutorials. Missing values, inconsistent formatting, duplicate records, and encoding errors accumulate over time and degrade model performance silently. A simple data quality check at the beginning of every project saves more headaches than any advanced technique. I maintain a checklist that takes about ten minutes to run on any new dataset. Null ratios per column, unique value counts, range validation against known business constraints, and basic consistency checks across related fields. It catches about eighty percent of data problems before they reach the modeling stage.
Tools and Environment Setup
The Python ecosystem for data science is mature. Pandas handles data manipulation, NumPy provides numerical operations, Scikit-learn covers most machine learning needs, and Matplotlib plus Seaborn handle visualization. For deeper learning work, PyTorch is more flexible than TensorFlow for research-oriented projects, though both are production-ready. Jupyter notebooks are fine for exploration, but production code should live in regular Python scripts or packages with proper structure, tests, and documentation. Version control is essential even for solo projects. Git tracks changes to your code, and DVC or similar tools can version your datasets and models alongside the code. I started using DVC on a personal project and it took about three hours to set up. Six months later it saved me from recreating a data processing pipeline from memory after a hard drive failure. The time investment is small relative to the risk you are managing. Cloud platforms like AWS SageMaker, Google Vertex AI, and Azure ML provide managed environments for training and deployment. They reduce infrastructure overhead but introduce vendor lock-in and cost unpredictability. A model that trains comfortably in a cloud notebook instance might cost significantly more to serve at scale than an equivalent on-premises solution. Budget roughly five to ten dollars per training run for medium-sized datasets on cloud GPUs, and factor in monthly serving costs that scale with traffic. For small teams and startups, starting with local development and moving to cloud only when you need distributed training or automated pipelines is usually the most cost-effective path.
When Data Science Processes Break Down
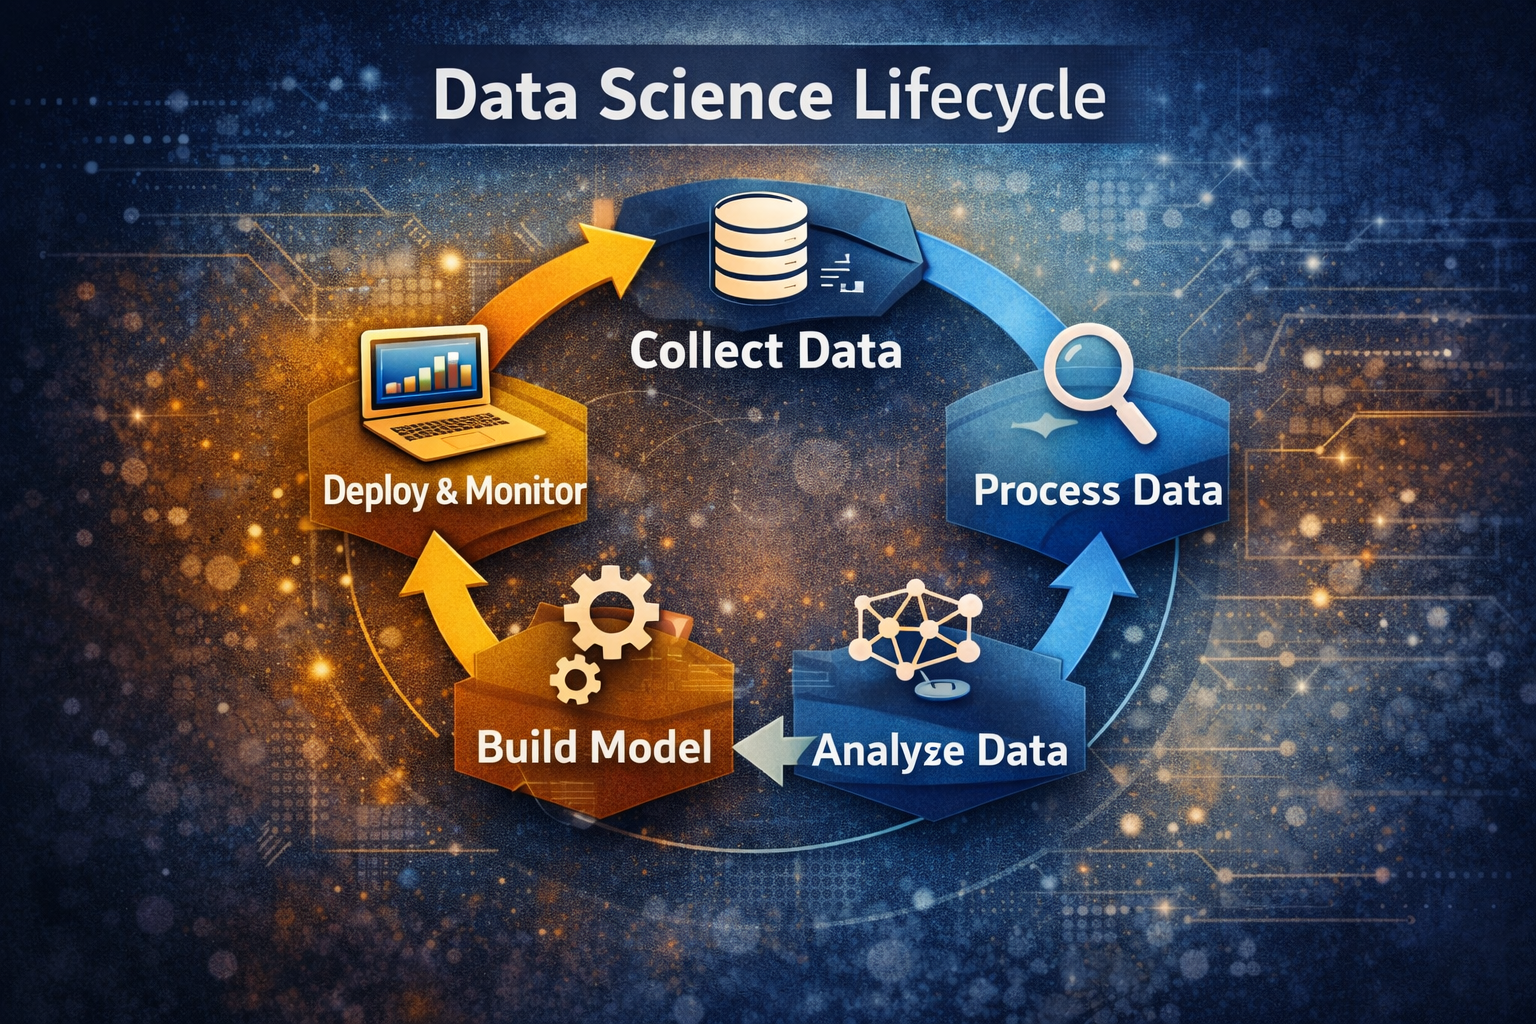
No workflow survives contact with messy data completely intact. Some projects will fail regardless of how well you follow the steps. Datasets with insufficient samples, unclear problem definitions, or data that simply does not contain a predictive signal will waste time no matter what technique you apply. I encountered this on a project to predict equipment failure from sensor data. We had twelve months of telemetry from fifty machines. After three weeks of feature engineering and model tuning, the best achievable accuracy was marginally better than random guessing. The sensors did not capture the failure modes. The actual causes were mechanical wear patterns that the sensors simply did not measure. We recommended a different sensor configuration and a redesigned data collection strategy instead of continuing to force a solution. Shutting down a failing project early is a skill that pays off more than pushing through to a mediocre result. Another limitation is that data science workflows assume stable data generating processes. When the underlying patterns change, models degrade. Customer behavior shifts, market conditions evolve, and systems get updated. Retrain frequently, monitor performance continuously, and have a rollback plan ready. A model that loses fifteen percent of its predictive power over six months is not a failure of methodology. It is a normal lifecycle event that requires a scheduled retraining cycle, not a panic response. The practical reality is that data science is less about clever algorithms and more about disciplined process, clear problem definition, and honest evaluation. The steps are straightforward. Understand the problem, get the data, explore it thoroughly, engineer features carefully, build and validate models properly, deploy with monitoring, and iterate based on real performance. Following that sequence will produce better results than jumping straight into modeling with incomplete data and undefined objectives. The work is iterative and often frustrating, but it is predictable enough that you can plan around the hard parts instead of being surprised by them.