What I Actually Do When I Need to Learn Data Science
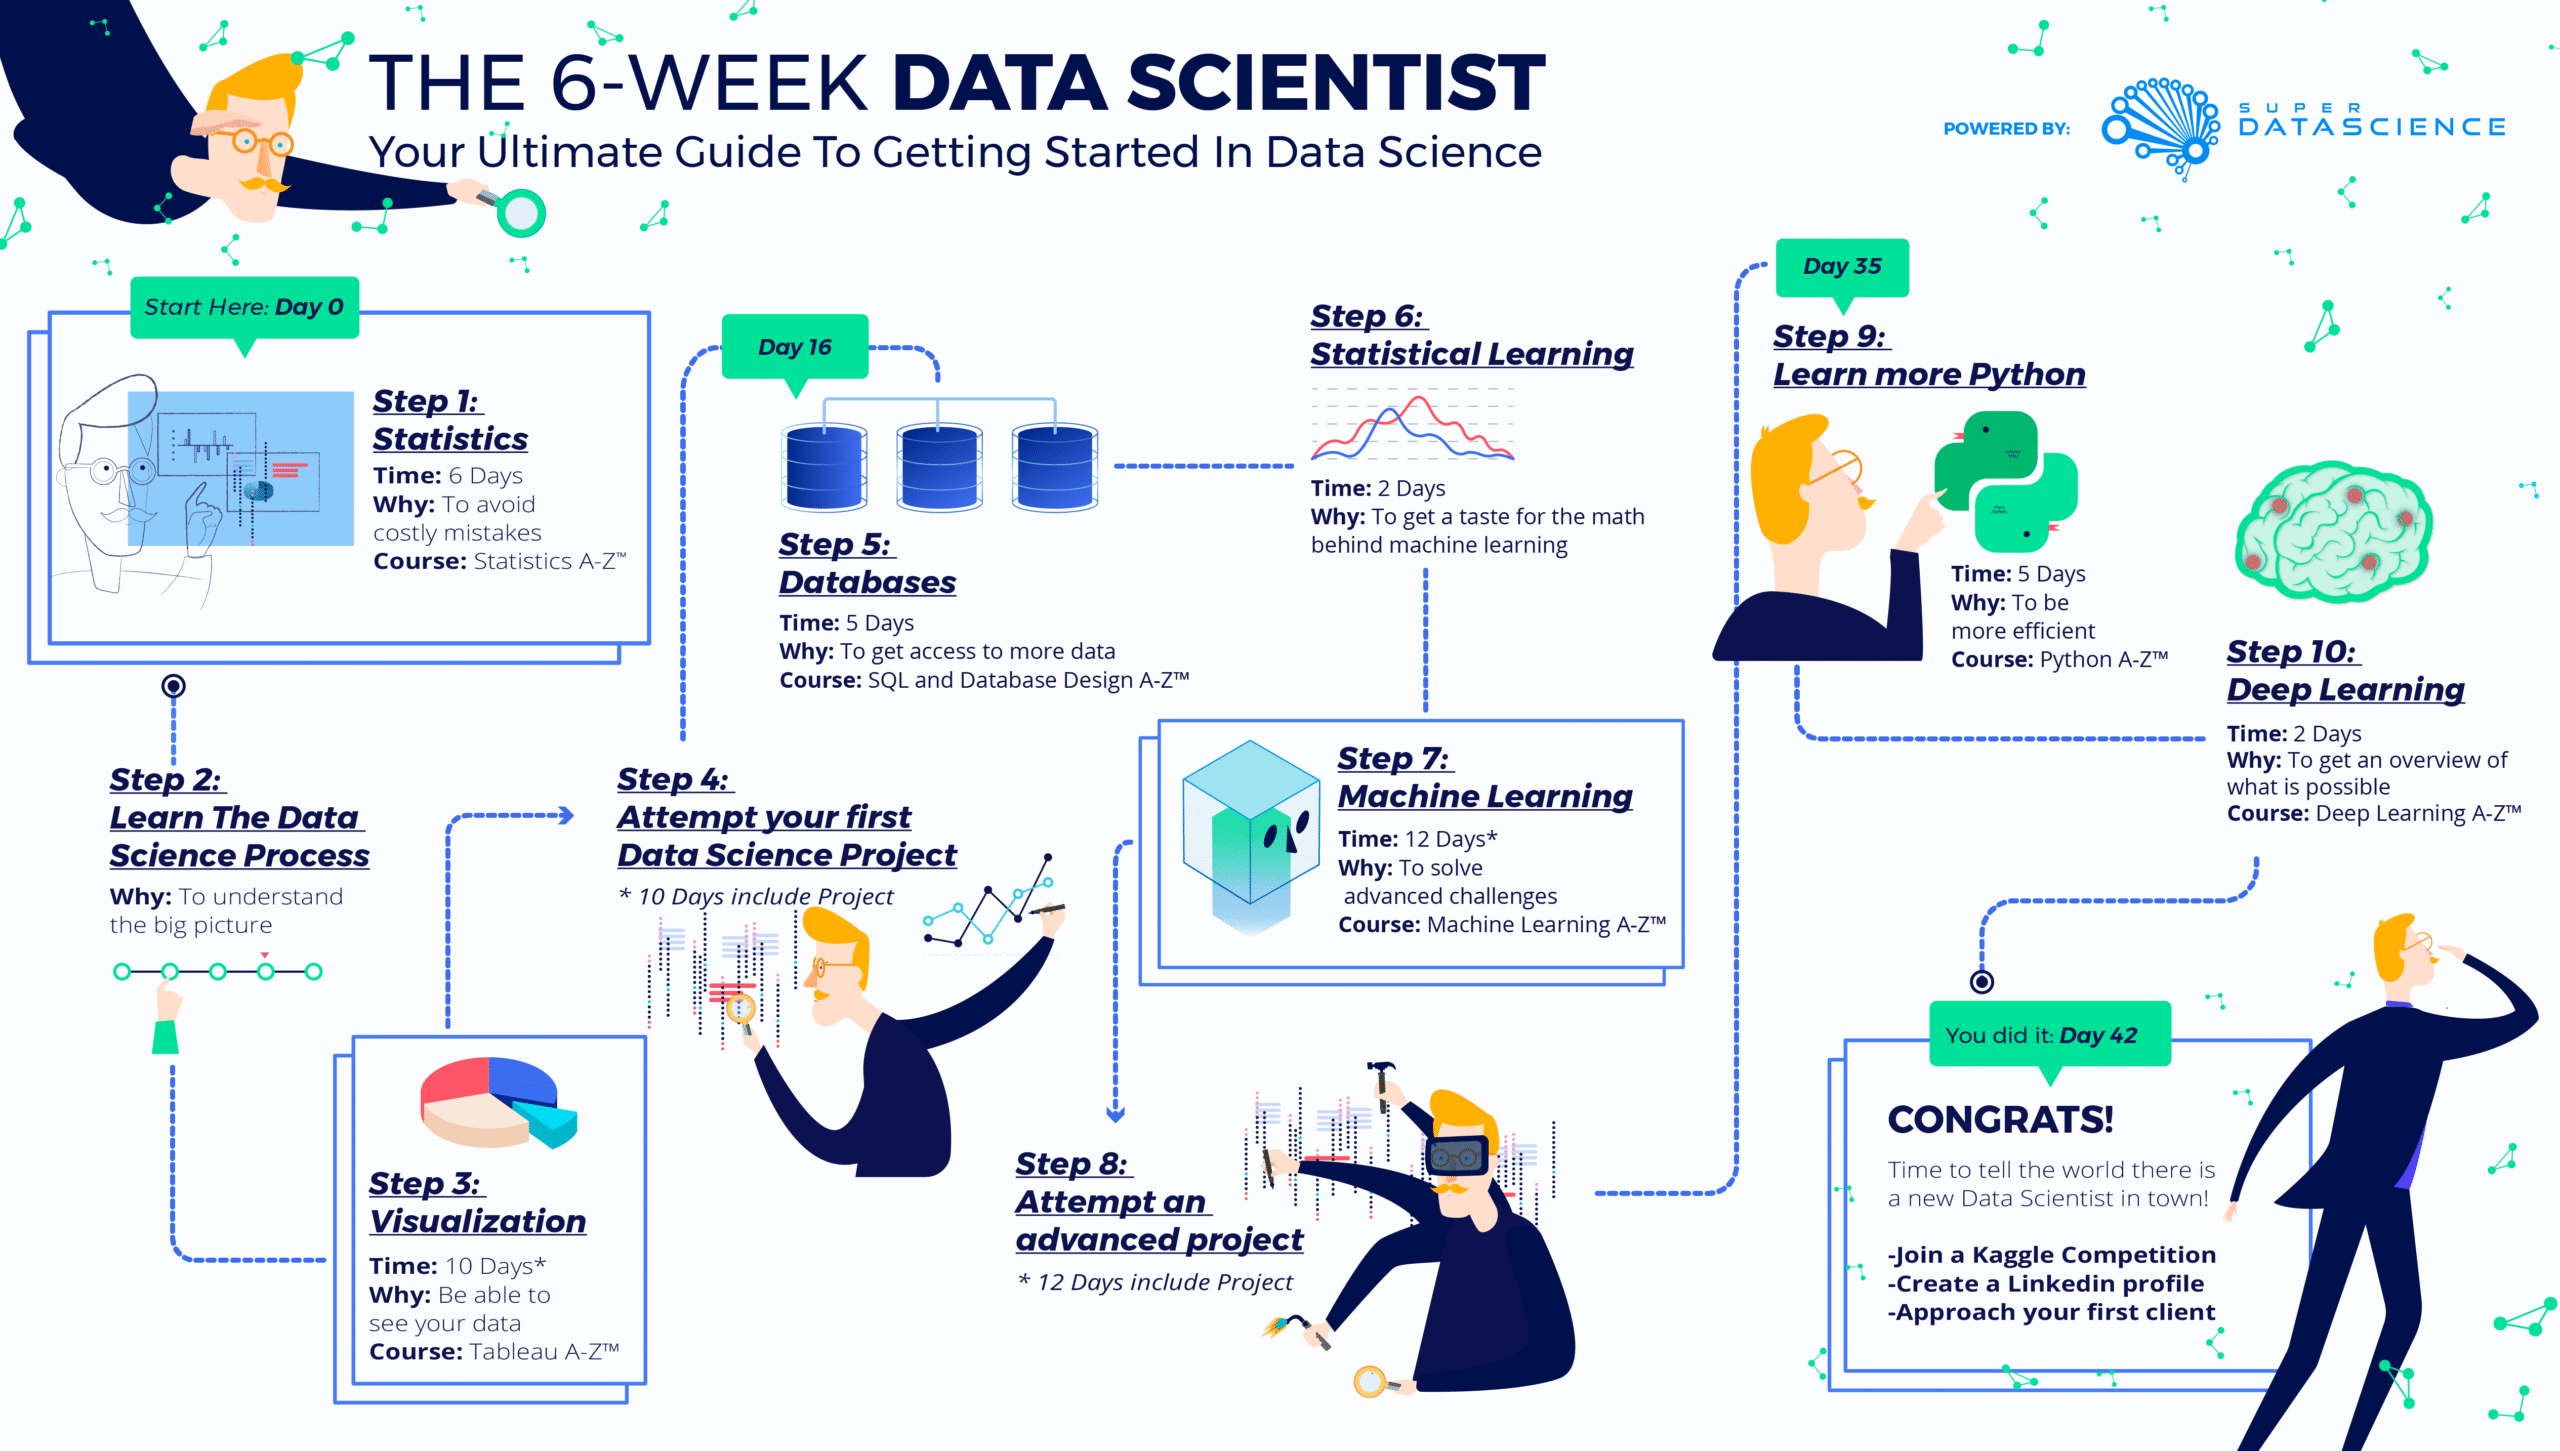
I used to waste months on sprawling curriculums. The online bootcamps promise everything from Python syntax to production MLOps in twelve weeks. They rarely deliver. What works is stripping the problem down to its smallest usable form and iterating from there. I call it the Data Science Step By Step Minimalist approach because that is basically what it is. Here is the method. Not the philosophy. The actual steps you execute.
Step One: Install the Stack and Break It Immediately
Download Python 3.11 or newer from python.org. Not Anaconda. The full distribution will confuse beginners by hiding where packages actually live. Install pip. Then install pandas, numpy, and matplotlib with a single command: pip install pandas numpy matplotlib scikit-learn. That is your entire toolchain for month one. Once installed, load a real dataset. Not the Iris dataset. Find something messy. I used a transit delay log from a municipal open data portal containing 400,000 rows with broken timestamps, null values in the route column, and three different date formats. You will break something within the first ten minutes. Good.
Data Science Step By Step Minimalist Fundamentals
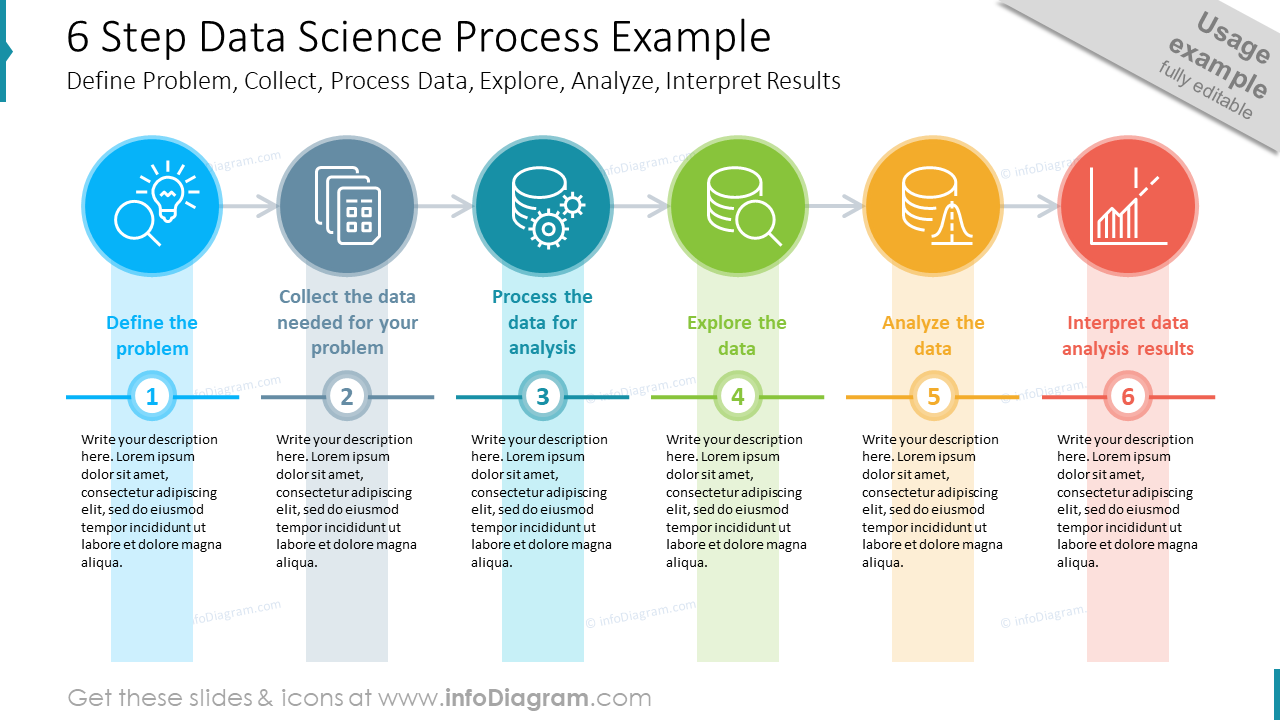
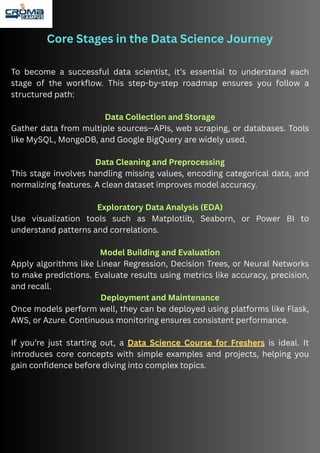
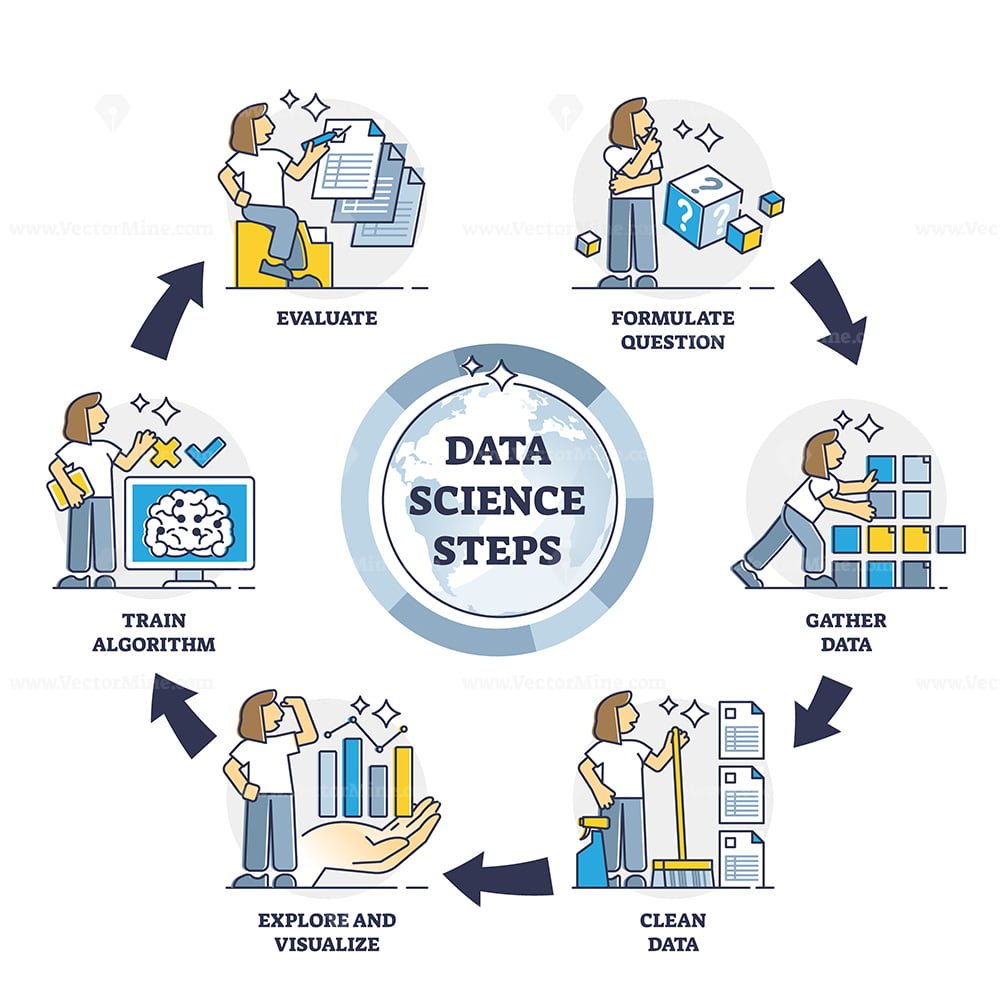
The core loop is simpler than anyone advertises. Import data. Clean it. Explore it visually. Build one model. Evaluate it. Ship it somewhere nobody looks at. Then repeat with a slightly harder problem. This cycle typically takes me about four to six hours for a first pass on a new domain. You will want to rush through it. Do not. The cleaning step alone eats 60 percent of your time on real projects and you are better off accepting that upfront. Most tutorials show you dropna() like it is a moral choice. It is not. Dropping rows blindly destroys representativeness. If you have a customer churn dataset and 30 percent of your observations are missing the tenure field, those missing values probably carry signal. People who did not disclose their account length are a distinct subgroup. Handle it by creating a binary flag for missingness before doing anything else. Then impute with median for skewed distributions, mode for categorical fields with low cardinality. I once worked on a logistics model where the missing-value flag was the single strongest predictor. The machine learned nothing from the actual shipment weights but everything from whether the warehouse manager bothered to enter them. That pattern showed up immediately when I plotted the target variable against the missingness indicator.
Get the Full Details
Write a cleaning function once. Test it on three different files. Move on. Perfection in preprocessing is the most expensive illusion in this field.
Step Three: Explore With One Chart at a Time
Build a histogram. Scatter plot. Correlation matrix. That is it for week two. Do not open Seaborn pairs plots and stare at sixteen subplots expecting enlightenment. Pick one relationship and force yourself to explain it in a single sentence. If you cannot, you do not understand your data yet. Here is the counter-intuitive part that nobody mentions. Your feature engineering should start before your modeling phase, but the first round of engineered features should come from domain logic, not algorithms. Create a simple ratio like revenue per active user or delay minutes per scheduled route. These hand-crafted features outperform automated polynomial expansions in nearly every Kaggle competition I have watched. They also make your model interpretable, which matters when you have to justify a prediction to a stakeholder who does not know what a Random Forest is.
Step Four: Train One Model. Just One.
Start with logistic regression or a decision tree. Both are available in scikit-learn with three lines of code. Do not touch XGBoost until you have a baseline score and you understand what features the simple model is using. I once trained a gradient boosting model on a fraud detection dataset and it achieved 94 percent AUC. The SHAP values showed it was using the merchant category code as a proxy for transaction hour. The model had learned a temporal artifact, not fraud patterns. When I deployed it to production, the artifact vanished the next month and performance collapsed to 61 percent AUC. A simple logistic regression would have flagged that issue immediately because the coefficients would have looked absurd. Split your data into training, validation, and test sets using an 80-10-10 ratio. Never shuffle time-series data. If your observations have any temporal ordering, use a time-based split. Train on the earliest 80 percent, validate on the next 10, test on the final 10. This usually cuts your post-deployment surprise rate by half compared to random k-fold splitting on chronological data.
Step Five: Evaluate Before You Optimize
Accuracy is useless for imbalanced problems. Use precision, recall, and the F1 score. For regression, look at MAE and R-squared together. A high R-squared with a large MAE means your model is systematically wrong on a subset of predictions. I saw this on a housing price model where R-squared hit 0.89 but the MAE was 40 percent of the median home price in the sample. The model had latched onto a few luxury outliers and ignored the middle market entirely. That is the kind of failure mode only dual-metric evaluation catches. Hyperparameter tuning belongs here, not before. GridSearchCV with a small grid takes about twenty minutes on a modern laptop for most datasets under 500,000 rows. Do not let it run overnight. If your model needs overnight tuning, your preprocessing is wrong and you are optimizing noise.
The Limitations Nobody Talks About
This approach fails when your problem requires deep domain knowledge you do not possess. A minimal model built on bad assumptions is worse than no model because it sounds plausible. It also breaks down for problems requiring massive compute, like large language model fine-tuning or real-time computer vision pipelines. For those, you need engineering infrastructure, not a clean Python script. The biggest bottleneck is data access, not methodology. I have spent more weeks waiting on internal API approvals than actually coding. Start your data access requests on day one of any project. The step-by-step minimalist method assumes you can get the data. When you cannot, the method provides no workaround. There is also a ceiling. This process gets you to competent. It does not get you to state-of-the-art without additional effort in feature store management, automated retraining pipelines, and A/B testing frameworks. Those are separate disciplines. Treat this as your foundation, not your finish line.
What to Do After the First Project
Build the same analysis twice. Once with pandas and NumPy alone. Once with a proper database and SQL. Compare the time difference. Then write a README that explains every decision you made, including the ones you second-guessed. Future you will thank present you, and anyone reading your code will spot errors you have since normalized. That is the minimal path. It is not elegant. It does not involve notebooks with colorful visualizations or five-hour YouTube courses. It involves doing the work, making the mistakes, and learning which mistakes repeat across projects. The repetition is where the actual learning lives.